
行业动态NEW
昨天
Kling AI has released version 4.0 of its video generator with support for clips up to 30 seconds, ten keyframe images as input, and prompt comprehension expanded to 8,000 tokens. I…
共 115 条相关资讯 · 来自历史归档
Kling AI has released version 4.0 of its video generator with support for clips up to 30 seconds, ten keyframe images as input, and prompt comprehension expanded to 8,000 tokens. I…
We introduce Gen4P, a unified framework for recovering 4D geometry and motion from monocular video. We show that a pretrained video generator can be repurposed into a feed-forward 4D perceiver without…
As joint audio-video generation models become more capable, they can generate audio-visual scenes exhibiting three forms of complexity: multi-event composition, multi-layer audio mixture, and asymmetr…
Interactive video generation commonly relies on small bidirectional chunks to reduce response latency. Yet our preliminary experiments show that larger chunks improve video quality and better utilize…
For video generation in dynamic world modeling, observed static and dynamic content should be efficiently reused to provide conditions for repeated generation at different times and viewpoints. We int…
Generalist robot manipulation can benefit from pretrained vision-language models (VLMs) for semantic reasoning and video generation models (VGMs) for world modeling. However, existing unified models t…

IT之家 10 月 10 日消息,生数科技现已发布全新一代视频生成旗舰模型预览版本 Vidu Q4 Preview,最多支持 3 段参考音频、15 张参考图与 2K、4K 输出。 IT之家获悉,Vidu Q4 目前支持图生视频和参考生视频。图生视频可根据图片和文字描述生成视频;参考生视频可结合多张参考图片和音频生成视频。 Vidu Q4 Preview 最多…
AI 点评 · 国产视频模型冲上4K画质,多模态参考能力或成新竞争分水岭。
Latent diffusion models enable high-quality video generation, but video VAE encoding and decoding remain computationally expensive. Existing methods use stage-specific lightweight operators, yet eithe…
Distributed image and video generation in ComfyUI for two NVIDIA DGX Sparks.
Video generators and video-based world models can synthesize plausible visual trajectories, but long-horizon procedural tasks require generation to adapt to what has actually been produced. A model mu…
Autoregressive video diffusion models have become a leading approach to real-time interactive video generation and video world modeling. However, existing methods typically allocate computation unifor…
Language-guided panoramic video generation benefits various downstream applications, such as interactive 3D scene exploration, virtual reality experiences, and embodied agent training. Existing panora…
Official implementation of "GRACE: Generation-Aware Latent Compression for Efficient Video Generation" (arXiv 2610.10524)
Bidirectional video diffusion models denoise entire videos in parallel, yet when trained on effectively unlimited in-distribution data from procedural generators, continue to violate physical laws and…
Modern autoregressive (AR) video diffusion models excel at short-horizon video generation, yet generating long videos remains challenging due to drifting, where colors and textures shift, and motion d…
Current controllable video generation systems often rely on 2D motion trajectories or sparse drag signals for object motion. These controls are ambiguous because the same 2D trajectory can correspond…
AI 点评 · 用3D相机与物体运动联合控制生成视频,破解2D轨迹歧义,让AI真正理解空间关系。
Recent video generation models can produce highly realistic videos from natural language instructions, with visual quality approaching cinematic standards. Existing evaluation benchmarks, however, pre…
Video generation models are increasingly being explored as world simulators for embodied planning and learning. To do so effectively, these models must not only generate visually appealing frames, but…
Long-video generation and world models have shown strong potential for interactive entertainment and embodied simulation by predicting future observations conditioned on user actions and historical me…
Recent video generation is increasingly realistic and controllable, yet video editing remains less developed, particularly for precise local edits that must preserve the original scene dynamics. Video…
AI 点评 · 视频场景文字编辑长期被忽视,这项基准填补了高保真局部修改的评测空白。
Video generation has rapidly progressed from short, low-quality clips to high-resolution, long-duration sequences with complex spatiotemporal dynamics. Despite strong generative priors learned through…
Video world models require persistent scene memory to maintain consistency during long-horizon video generation. Existing spatial memories accumulate RGB observations or latent features, increasing st…
Recent video-based world models pair the scalability of autoregressive (AR) prediction with the visual quality of diffusion models. The choice of scene tokenizer is paramount for the optimal performan…
Video generation models (VGMs) offer strong spatiotemporal priors for embodied observation--action modeling. However, joint-space action vectors lack explicit image-space structure and vary in dimensi…
Human image animation aims to transfer motion from a driving video to subjects in a reference image. Despite remarkable progress in video generation, achieving high-fidelity animation of multiple inte…
Real-world robot learning is constrained by the cost of collecting experience and evaluating candidate behaviors. Video generation models offer a scalable foundation for visual simulators that predict…
We introduce LIFT, a unified image-to-video generation framework that complements camera control with Layout-In-FuTure control, enabling users to specify what should appear in a future view and where…
Video diffusion models are increasingly developed into specialized models for diverse downstream tasks, and this development often includes a distillation stage, for example to accelerate sampling or…
High-resolution video generation is expensive, as its cost grows rapidly with the number of spatiotemporal tokens. A practical alternative first generates a lower-resolution video and then applies a r…
Teaching humanoids loco-manipulation skills, such as carrying diverse objects, via visual imitation is a promising path toward generalist robots. However, collecting diverse, high-quality interaction…
We introduce LIFT, a unified image-to-video generation framework that complements camera control with Layout-In-FuTure control, enabling users to specify what should appear in a future view and where…
Autoregressive (AR) video diffusion enables low-latency, streamable video generation, but prediction errors often accumulate over long rollouts. Training the generator on its own rollouts exposes it t…
World models, game simulators, and long-take video creation require coherent scene evolution and sustained dynamics over extended durations. Autoregressive (AR) video diffusion provides a natural fram…
Few-step streaming audio--video generation requires both causal modeling and step distillation, yet standard training recipes face two context-related challenges. Teacher forcing pairs clean history w…
Self-driving laboratories (SDLs) aim to automate the full experimental loop, from scientific decision-making to physical execution. Ideally, AI-generated plans could be carried out directly by robotic…
Long-horizon camera-controlled video generation requires recovering previously observed content from an ever-growing visual history. Existing approaches either search historical context implicitly or…
Despite recent progress in agentic multi-shot video generation, producing coherent and consistent long-form stories remains challenging. Existing agentic pipelines typically rely on textual shot plans…
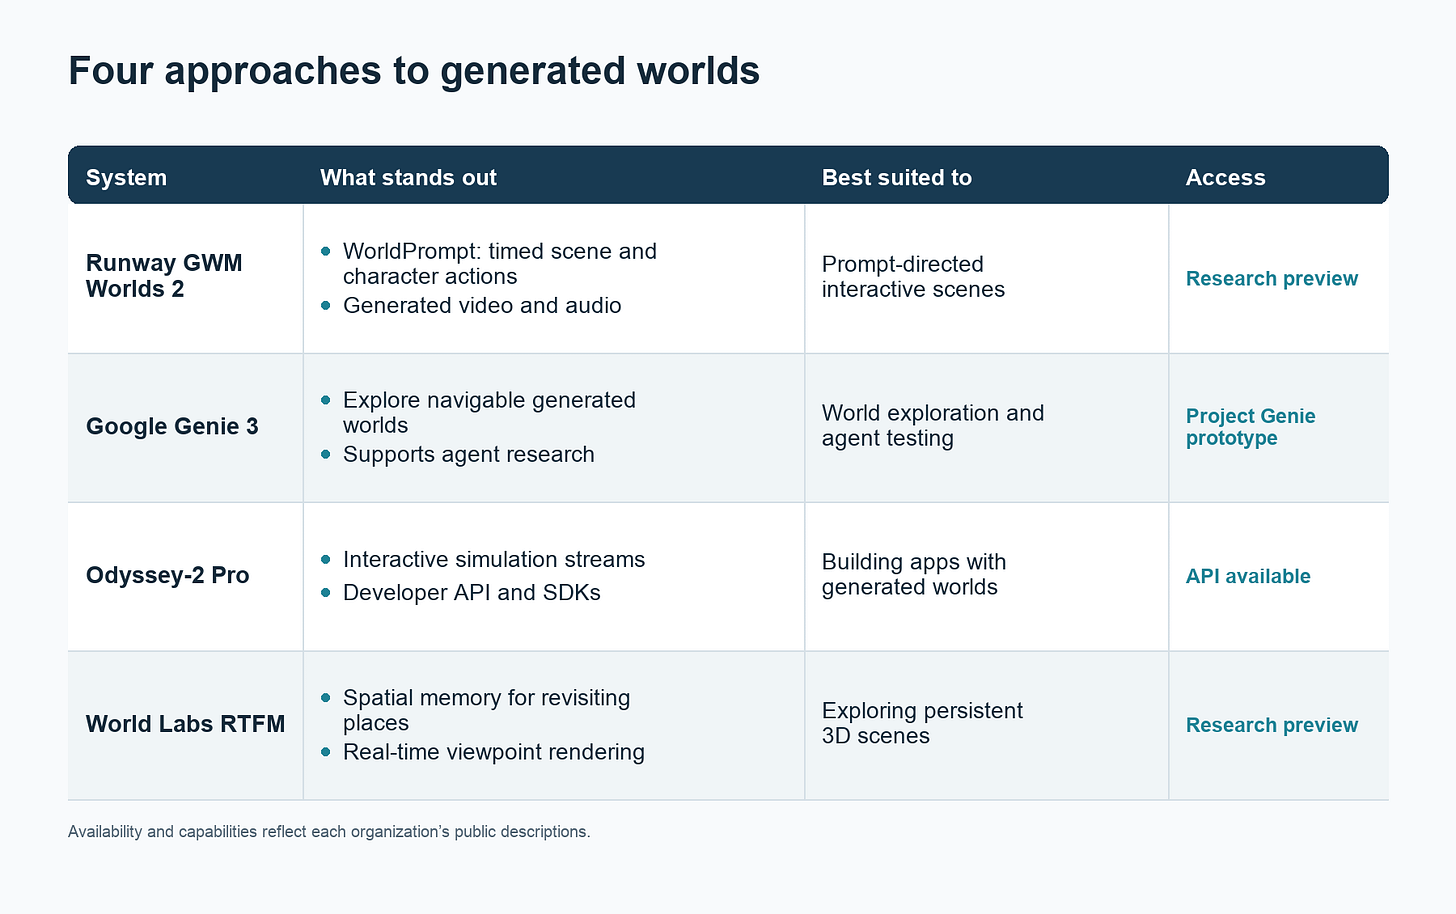
GWM Worlds 2 uses persistent context and timed actions to steer a world model generating video and audio in real time.

Generative AI
AI 点评 · 长视频生成从片段拼凑迈向连贯叙事,自动化突破将重塑影视与内容创作门槛。
Recent years have witnessed major progress in joint audio-video generation. Existing models still suffer from limited per-modality fidelity, insufficient text-modality alignment and weak cross-modal s…
Few-step autoregressive (AR) video diffusion enables low-latency streaming generation, but existing post-training methods predominantly rely on Distribution Matching Distillation (DMD), requiring both…
Video generation begins in text space by authoring a cinematic screenplay, then materializes into pixels. As contemporary video generators scale to 30 seconds and faithfully follow complex conditions,…
Video is a rich representation of a physical event, capturing appearance, geometry, motion, and temporal evolution. Other modalities, such as 3D body motion or audio, encode narrower aspects of the sa…
Advances in generative models have improved video fidelity, enabling long-horizon generation, interactive world modeling, and evolving visual environments. Autoregressive (AR) video generation extends…
World-action models (WAMs) transfer visual and motion priors from pretrained video generators to robot control by jointly modeling visual dynamics and actions. Existing WAMs, however, predict dense fu…
Object permanence and solidity are hallmarks of human cognitive priors. Recent studies show that video generation models, a paradigmatic class of current world models, have begun to show emerged reaso…
Pretrained generative Diffusion Transformers (DiTs) capture rich pixel-level visual and language-conditioned structure through large-scale image and video generation training. A growing line of robot…
Recent advances in video generative models have enabled high-fidelity, temporally coherent video generation. However, these models often struggle to satisfy prompts requiring specialized knowledge, sp…
AI video prompt cheat sheet & Claude Skill: cinematic camera angles, camera movement, lighting, composition, color grading for Veo 3, Kling, Sora, Runway, Midjo…
Runway wants to stream AI video as users prompt it, rather than make them wait for finished clips. The approach builds on GWM-1, its world model that generates video frame by frame…
Reinforcement learning (RL) is vital for optimizing video generation models, with a robust reward model (RM) serving as the cornerstone. However, existing video reward models often produce unstable sc…
SparkDiffusion: Accelerating DiT video generation by 265× via joint Sparsity, Distillation, Quantization, etc.
Reference-to-video (R2V) generation is evolving toward increasingly general and versatile reference control, giving rise to the emerging paradigm of omni R2V generation. However, existing benchmarks f…
Video diffusion models repeatedly process long spatiotemporal token sequences during denoising, making attention a major computational bottleneck. Linear attention offers an appealing alternative and…
Recent advances in video generation allow robots to learn manipulation trajectories from generated videos. However, these approaches produce purely kinematic trajectories that lack force information,…
智象未来(HiDream.ai)正式发布首个原生全模态视频生成模型 HiDream-O1-Video-1.0
Interactive control for video generation is moving from coarse prompts toward fine-grained, physically meaningful manipulation of dynamic scenes. Yet existing controllable methods either require the f…
Video diffusion models are stochastic and hard to control: precise content often requires repeated sampling without guaranteed success, and long-horizon scenes drift in appearance, interactions, and t…
Diffusion Transformers deliver state-of-the-art video generation, but their long spatiotemporal sequences make attention the dominant deployment cost, and a deployable low-bit kernel must be accurate…
We present Vidu S2, which comprises Vidu S2-Avatar, a real-time interactive digital-character model, and Vidu S2-Editing, a real-time video editing model. Moreover, we explore the feasibility of real-…
Autoregressive (AR) video diffusion models have shown great potential in real-time video generation. Recent methods distill pretrained bidirectional video diffusion models into causal AR students thro…
Generating long-form multi-shot videos requires coherent within-shot motion and visually consistent narratives across shots. Existing video generators favor continuous motion and struggle to present c…
DELE-w0.5 重新定义了世界模型在机器人操作中的作用。
World-action models (WAM) predict future states to guide robot actions, enabling learning from both action-free video and action-labeled interaction. Most inherit pretrained video generators, leaving…
Joint audio-video generation models have made substantial progress in visual quality and audio-visual synchronization. However, they still provide limited control over when shot transitions occur and…
AI company Runway has unveiled Solaris, the first model in a new category it calls "Interface World Models." Instead of running code, the system generates the user interface frame…
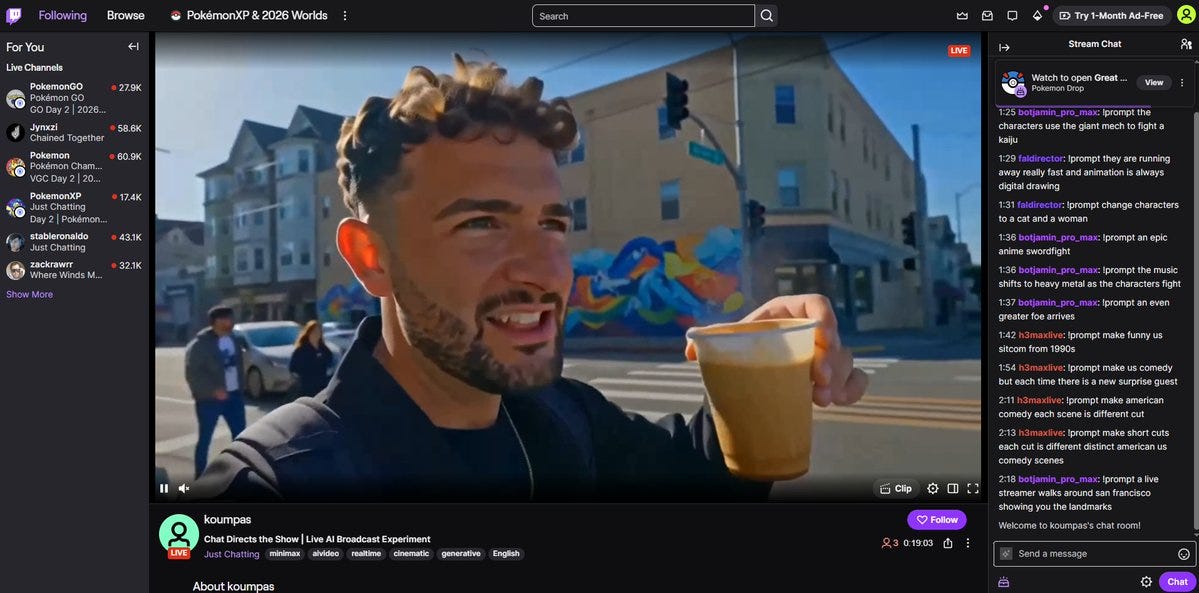
You can now create decent video faster than you watch it. This is the start of... something. We’re not sure what.
We present H3-World, an efficient framework that turns the 33B MiniMax-H3 video generator into an interactive world model. Our key finding is that, as large video generators become more capable, langu…
Recent video generators often omit audio or synthesize it in a separate stage, limiting reciprocal modeling of visual dynamics and acoustic events. We present DreamX-Creator 1.0, a compact native join…
Advertising video generation is not only a video synthesis task, but also a product-conditioned reasoning problem whose success is measured by online business metrics. Recent video foundation models c…
Interactive world models extend video generation from offline clip synthesis toward persistent simulation of interactive virtual worlds, enabling applications in games, robotics, embodied agents, and…
We look at Gemini Omni 1.1 Flash, Google's production update to its native multimodal video generation and editing model. We break down what changed: scene extension now reads up t…
AI 点评 · 原生多模态视频编辑升级,场景延长与4K增强直击创作痛点,实用价值显著。
Official implementation of "LayerRecall: A State-Conditioned Memory Router for Long-Horizon Consistency in Video Generation."
国产算力跑通视频生成规模化应用
AI 点评 · 国产算力突破视频生成瓶颈,规模化落地价值凸显。
Autoregressive video diffusion enables scalable long-video generation by producing chunks from a bounded recent context. While recency-based caching preserves local continuity, it evicts historical cu…
Recent generative approaches to geometry estimation adapt pretrained image diffusion models and treat the task as image-conditioned generation. Leveraging off-the-shelf image diffusion models, they ei…
Google's Gemini Omni 1.1 Flash video model now analyzes up to ten seconds of existing footage instead of just the last second for more consistent scene extensions. Scenes can be ex…
Recent video generation models are increasingly framed as world models. Many physical processes can unfold in more than one valid way. Therefore, a world model should reproduce not only a plausible tr…
Scaling video generation to long durations reveals a critical bottleneck: current models lack robust long-term memory. This deficiency can be studied along two critical aspects: object permanence, the…
Long autoregressive video generation faces a fundamental memory challenge: with a finite attention window, a model must decide which information from an ever-expanding history to retain. Existing meth…
Recent studies suggest that video generation models can exhibit certain forms of zero-shot visual reasoning through generated frames. Yet reliable evaluation remains challenging: benchmarks should ado…
少数派的近期动态新一季少数派会员启航,更新权益,更多惊喜,还有实体纪念卡。点击了解能让AI助手通过自然语言指令直接与您的Quote/0摘录墨水屏交互的DotSkill已上线。点击了解你可能错过的文章快 ... 查看全文
Alibaba's video generation model Wan3.0 creates clips up to 30 seconds long from text, PDFs, and PowerPoint files. A 30-second 1080p clip costs $6. Alibaba's quarterly profit dropp…
AI 点评 · 多模态输入直出30秒视频,定价透明,国产大模型商业化提速信号明确。
8月24日,阿里巴巴视频生成大模型Wan3.0正式上线。
With the rapid progress of diffusion models and large-scale video generation, generative world models are increasingly expected to replace traditional simulators, including physics engines, game engin…
Video generation is progressing beyond isolated clips toward long-form narratives and interactive worlds, requiring models to preserve identities, follow user controls, and remain stable over extended…
AI image and video generation skill for Claude Code and other coding agents — Gemini, OpenAI and Kie AI behind one CLI and MCP server, with EU AI Act content ma…

Current world models like Sora or Genie only simulate physics and ignore what people think, want, or feel. The new "Mental World Modeling" framework adds mental variables like beli…
AI 点评 · 忽视人类信念的世界模型,预测行为必失准,新框架补足心智维度。
AI 点评 · 视频生成跨界设计工具,直击Adobe与Canva的护城河,行业格局或将生变。
Streaming autoregressive diffusion models enable real-time, long-horizon video generation, but their training objectives optimize local frame prediction rather than the geometry and dynamics of a cohe…
Training-free block-sparse attention can accelerate video transformers, but row-wise attention concentration does not by itself specify an executable sparse operator. Queries sharing a block route may…
Official RMD implementation for cross-resolution diffusion distillation and accelerated video generation.
We introduce Semantic Task Completion Video Generation, an outcome-oriented video generation task. Under this formulation, success requires both achievement of the intended outcome and semantic ground…
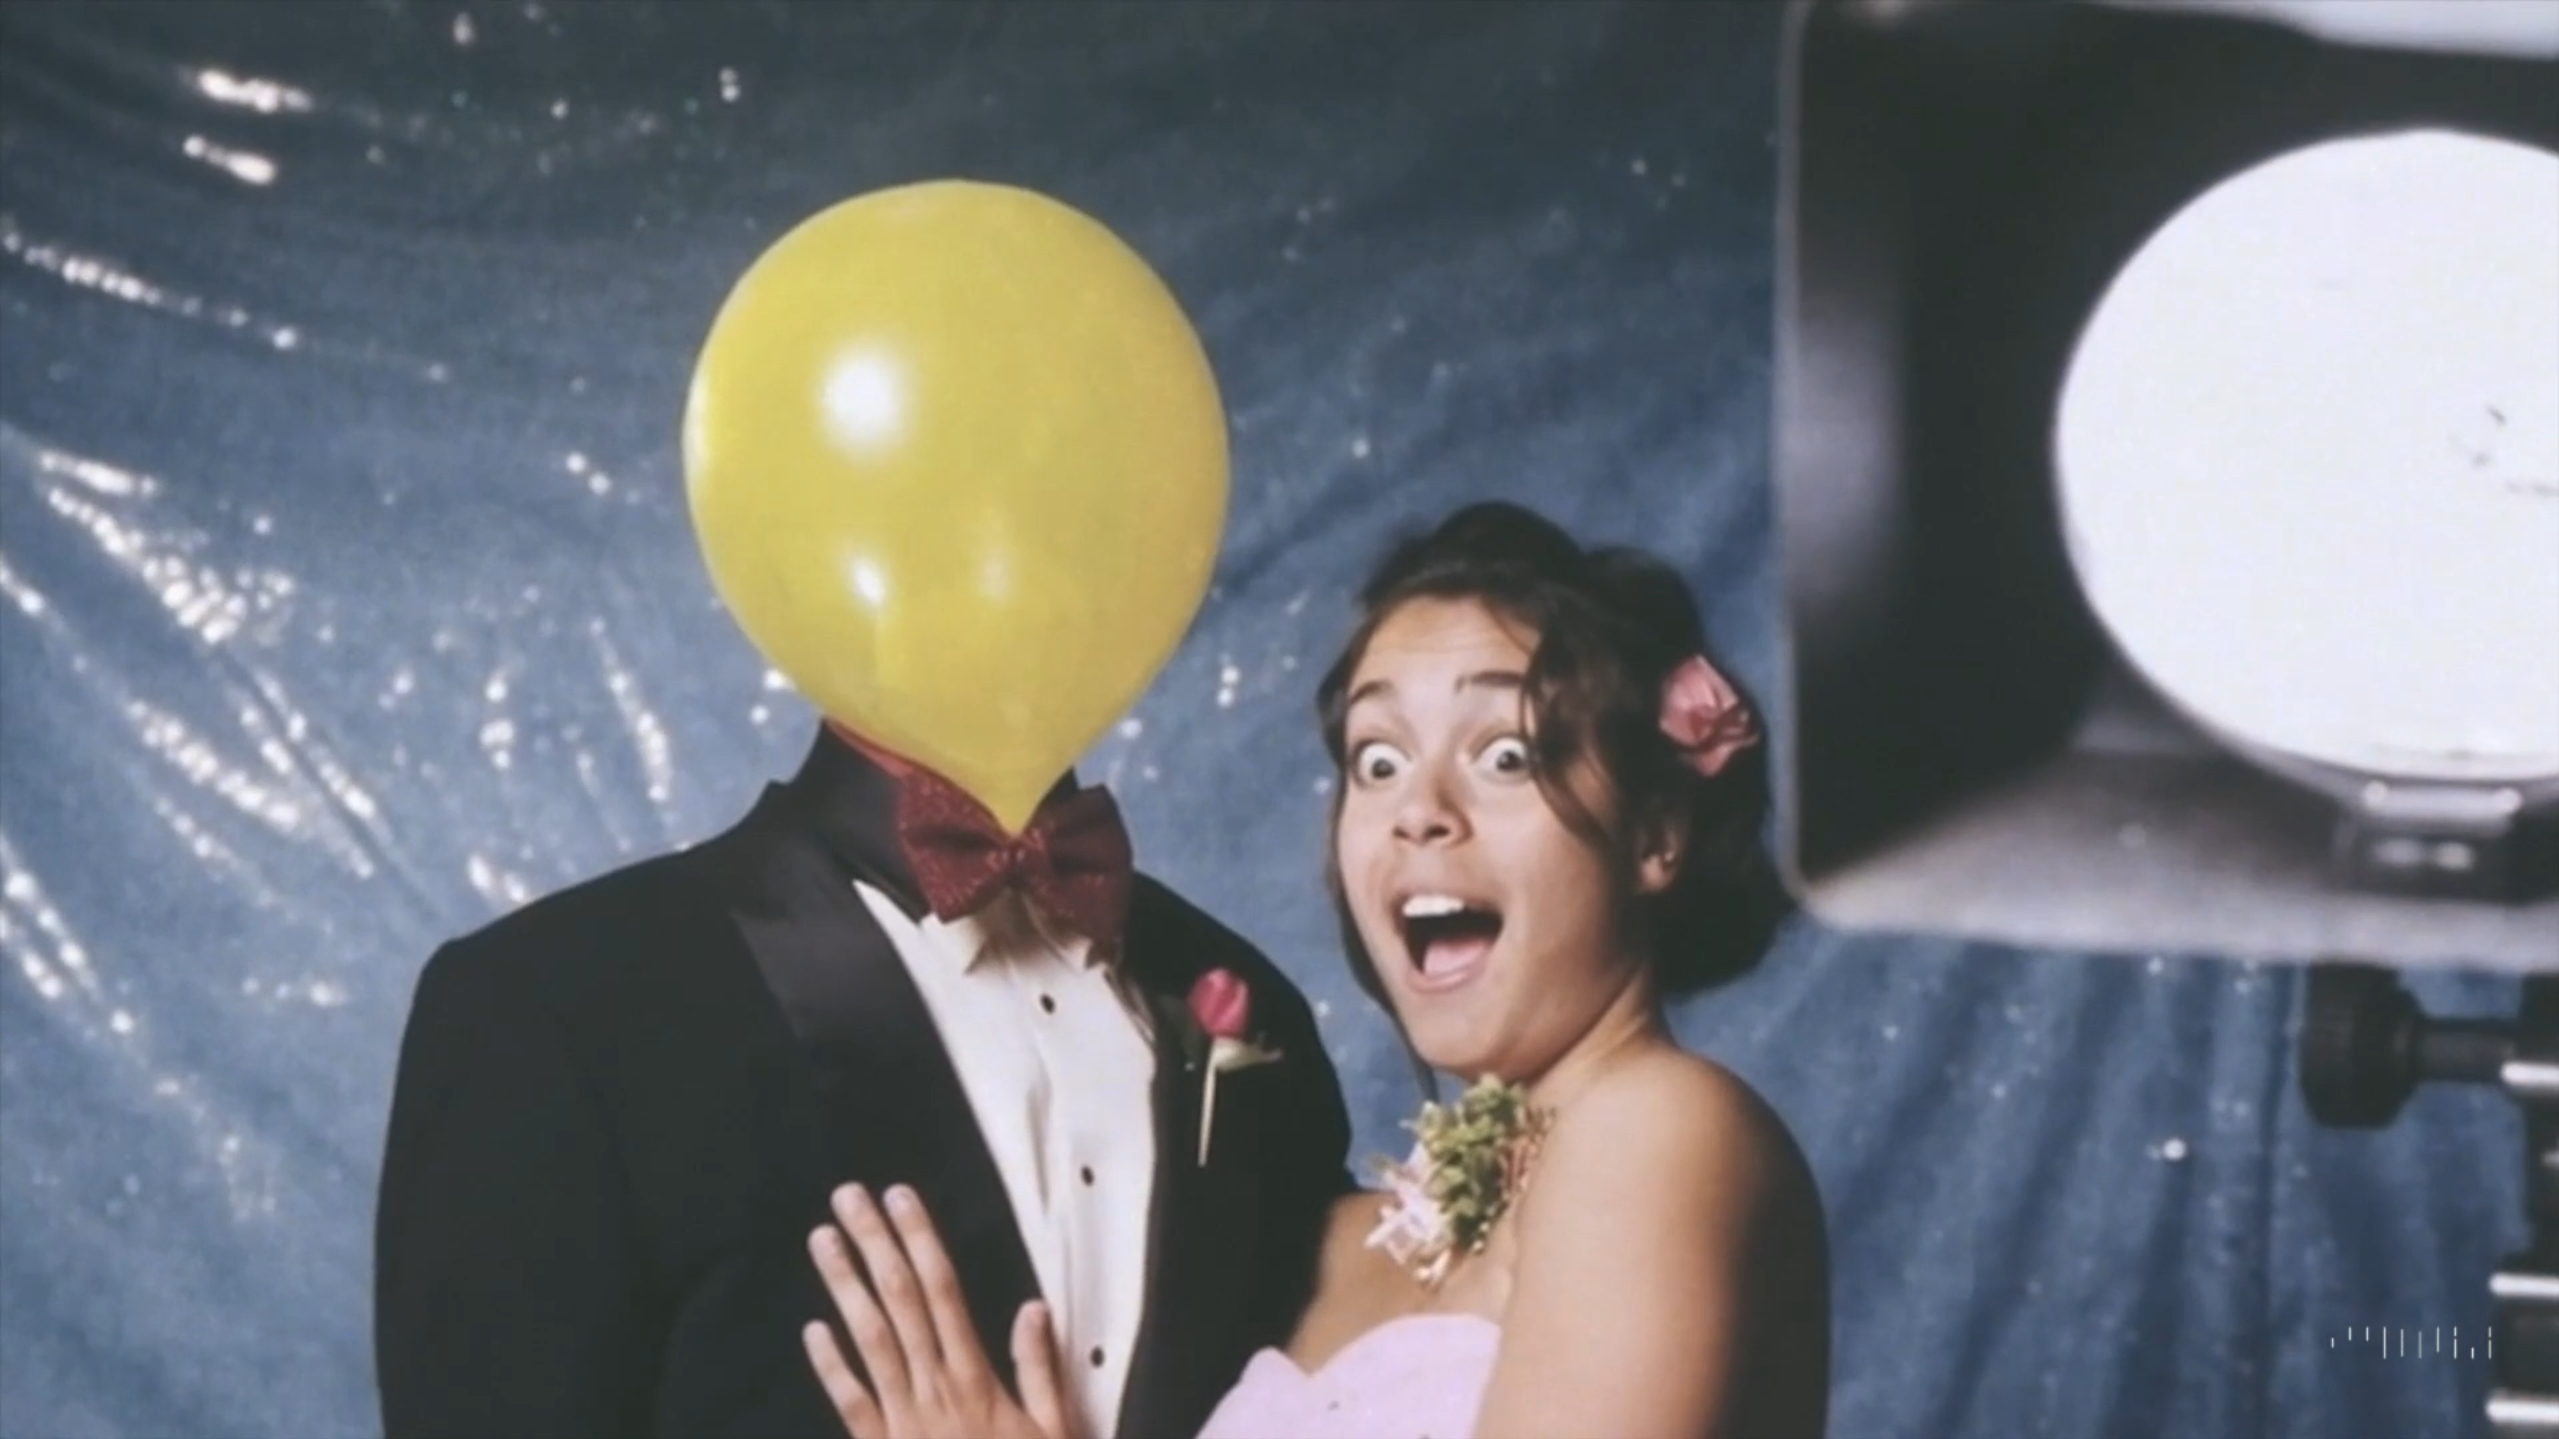
AI production companies like Promise are setting up shop around Hollywood's historic studios, using real-time backgrounds and other AI tools to cut film costs. Netflix already uses…
We present AnyTalk, a novel method for generating 3D speech animations for arbitrary characters without requiring any animation data. While existing audio-driven 3D speech animation methods rely on ch…
Multi-GPU acceleration for MiniMax H3 video generation on NVIDIA V100 (sm_70). Ulysses sequence parallelism as a drop-in ComfyUI custom node — ~19 min to ~7 min…
Recent video generators can fabricate realistic depictions of wars, disasters, public emergencies, and other real-world crises, creating substantial risks of misinformation. Existing benchmarks, howev…
Interactive autoregressive video generation demands both low-latency rollouts and precise online control. Few-step distillation accelerates generation by reducing denoising steps, while online control…
Large-scale manipulation data is essential for robot learning, yet collecting robot demonstrations remains expensive and difficult to scale. Meanwhile, abundant egocentric human manipulation videos pr…
Latent video generation relies on autoencoders to define a compact space in which generative models operate. Although video autoencoder architectures have evolved substantially, their latent spaces ar…
LTX-2.5 brings frontier video generation to local NVIDIA hardware: 6.8-second clips, native multishot, day-one ComfyUI, open weights. The post The Video Production Stack Now Fits o…
AI 点评 · 本地开源视频生成首次媲美前沿水平,多镜头与ComfyUI支持将大幅降低创作门槛。
4D generation synthesizes dynamic 3D scenes from conditions such as text or images. Existing methods either reconstruct generated RGB videos with a separate 4D model or adapt a particular video genera…
We introduce Sci-VBench, a comprehensive benchmark for evaluating knowledge- and reasoning-intensive video generation across scientific domains. It contains 1,253 expert-annotated examples spanning 60…
8月6日,阿里巴巴视频生成大模型Wan 3.0开启公测
Black Forest Labs 正式推出 FLUX 3 视频生成模型,研究人员发现 iCloud Private Relay 存在 IP 泄露风险等。 查看全文

Black Forest Labs has launched FLUX 3 Video, which generates Full HD clips up to 20 seconds long with native audio and lip-synced dialogue in more than 14 languages. It can also re…
10秒1080P,成本只要5毛钱
Open agentic prompt-expansion harness for image and video generation, bridging polished demos, public APIs, and deployable workflows.
Controllable video generation models are increasingly being developed as world models. Accordingly, evaluating them in this role extends beyond the apparent appearance of generated videos to the inher…
狂刷3小时!
AI 点评 · AI巨头沉迷短视频,揭示人性与算法共谋的荒诞现实。
🎬 Curated MiniMax H3 video generation prompts — cinematic, ads, anime, UGC, product videos, and more. Includes playable examples and creator attribution.
Kandinsky WM 1.0 — a family of models for Physical AI. Image-to-video generation for autonomous driving, robotics & general physics.
A curated list of reinforcement learning, preference optimization, and reward-driven post-training and alignment methods for video generation.


