行业动态NEW
4 小时前
Meta changes AI scraping policy but won’t add language respecting robots.txt.
AI 点评 · Meta改口却避谈robots.txt,AI数据抓取边界仍模糊。
共 417 条相关资讯 · 来自历史归档
Meta changes AI scraping policy but won’t add language respecting robots.txt.
AI 点评 · Meta改口却避谈robots.txt,AI数据抓取边界仍模糊。
Eka Robotics may be the first robotic arm that is actually good at picking a wide range of objects up, and it is so smooth and human-like, it is wowing the industry.
Reinforcement learning enables mobile robots to make fast and scalable navigation decisions in constrained human-shared environments. However, directly extending single-robot approaches to multi-robot…
University of Michigan spinout Laplace Intelligence uses AI agents and interactive simulation to stress-test robots and self-driving vehicles before deployment. The profitable star…
10月18日下午,首届全球具身智能应用创新挑战赛暨2026中国机器人大赛落下帷幕。
Robotic value models assess task execution from visual observations and instructions, providing feedback for policy learning and execution monitoring. However, existing evaluations cover only selected…
Robotic manipulation is not merely observation-to-action generation, but the realization of task-specified state changes in the physical world. Existing vision-language-action (VLA) methods directly l…
Experience generated during deployment offers an opportunity for robots to improve policy reliability through learning from their own executions. However, learning through human corrections requires t…
Carolyn Marvin was arrested and charged with disorderly conduct after blocking the path of an Uber delivery robot and refusing to get out of the way. Marvin told Philadelphia's ABC…
AI 点评 · 人机冲突首现执法介入,机器人路权与公民抗议边界成新争议点。
Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation. The REKI vision-language-action model is pretrained onl…
AI 点评 · 2.4B参数把高效记忆塞进VLA,机器人操控或迎轻量化拐点。
Estimating a humanoid robot's internal state from video has a wide range of real-world applications but remains unexplored. During interactions with a robot, its onboard state information may be unava…
Generalizable robot manipulation requires predicting how a scene will evolve, identifying where interactions are feasible, and determining how to act. Action-labeled robot videos directly supervise co…
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks lik…
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks lik…
VLA解决“能干”,世界模型解决“想清楚再干”
优必选 Thinker-WM在三大公认具身世界模型基准评测中全部拿下第一名
Personalization is essential for general-purpose robots to transition into household environments and achieve true practicality. While general robotic manipulation has been extensively studied, person…
Predicting how the world responds to an action requires more than what can be seen: robots must account for environmental factors that are neither directly observable nor explicitly specified, from ph…
How can robots autonomously collect the contact-rich experience needed to learn dexterous manipulation? We present DSP: Dexterity from supervised play, a framework in which a robot learns a play polic…

Google's Gemini 4 Argon controls robots, generates simulations from photos or sketches, and evaluates training videos. On Google's own ERQA benchmark, it scores 87 percent. But the…
Generative simulation can automate robot environment construction, but physically valid environments are not necessarily useful for training. The challenge is to identify environments that address a p…
Vision-language-action (VLA) models transfer semantic knowledge acquired through vision-language pretraining to robot control, achieving strong performance across various benchmarks. However, most VLA…
While generalist vision-language-action (VLA) models have enabled diverse open-world manipulation, real-world robotic assistance requires two critical capabilities they currently lack: personalization…
Industrial manipulation in flexible manufacturing, e.g., high-mix, low-volume (HMLV) electronics assembly, requires robot policies to adapt to changing products and production conditions. Such setting…
Recent advances in robot learning have driven rapid progress in humanoid control, enabling increasingly agile behaviors in the real world. However, humanoid control networks are typically obtained thr…
Mobile Manipulation (MoMa) is a cornerstone of autonomous robotic systems, yet real-world fine-tuning remains a formidable challenge because of high-dimensional action spaces and intricate coupling be…
3D object composition is pivotal to digital content creation and robot simulation, while also serving as a critical testbed for physical intelligence in foundation models. Previous methods either leve…
“具身进实景,劳动最光荣”
Industrial Next helps manufacturers automate complex, delicate tasks that have traditionally required human labor.
AI 点评 · 机器人换任务从数周缩短到几分钟,意味着柔性制造门槛大幅降低,小批量定制生产真正可行。
Our first robotics pod with Dyna’s Chief Scientist on their big bet on World Action Models & the Next Frontier of Physical AI
AI 点评 · 世界动作模型押注通用机器人,一小时自主性或是物理AI落地的关键拐点。
Embodied visual tracking requires a robot to identify a designated target from visual observations and control its own motion to follow that target through an environment. Following an isolated person…
Simulated environments enable scalable training data generation for embodied agents, but more data does not necessarily provide what a particular agent needs to learn. Existing environment-generation…
Progress toward general intelligence in the physical world requires scaling robot learning across diverse environments and interactions. However, existing robot policies use shared parameters that rem…
Agentic robotics places a large language model (LLM) agent in the robot control loop, where it composes perception, motion, and vision-language-action (VLA) tools under the guidance of a memory and th…
Robot policies are expected to generalize across deployment environments, including variations in the robot itself: cameras are bumped and remounted, calibrations drift, controllers run at different r…
Robots are increasingly autonomous in task execution, yet their improvement remains largely human-driven. This study investigates Physical Recursive Self-Improvement (Physical RSI), in which physical…
It is difficult to accurately model the physics of the interaction between a robot and the objects it manipulates, including contact mechanics, coupled contact dynamics, deformations, stiffness and fr…
University of Michigan spinout Laplace Intelligence uses AI agents and interactive simulation to stress-test robots and self-driving vehicles before deployment. The profitable star…
Main thread: Gemini 4 Argon - https://news.ycombinator.com/item?id=50073879
让VLA从“演示可用”逼近“产线可用”
Winverse AI
赢奖金、拿融资、送出海
Reinforcement learning (RL) post-training improves robot foundation models (RFMs) beyond their demonstrations, but real-world deployment demands more: learning new tasks efficiently while retaining pr…
A robot following a multi-step instruction needs to act on the right objects in the right order, even as the scene changes. It must also maintain awareness of task progress and determine when to advan…
A robot needs a world model that predicts how its actions will change the scene and a policy that chooses those actions. Models are usually built and evaluated for only one of these roles, and every r…
Vision-language-action (VLA) policies excel at generalist robotic manipulation but generate actions without explicitly modeling their environmental consequences. World action models (WAMs) incorporate…
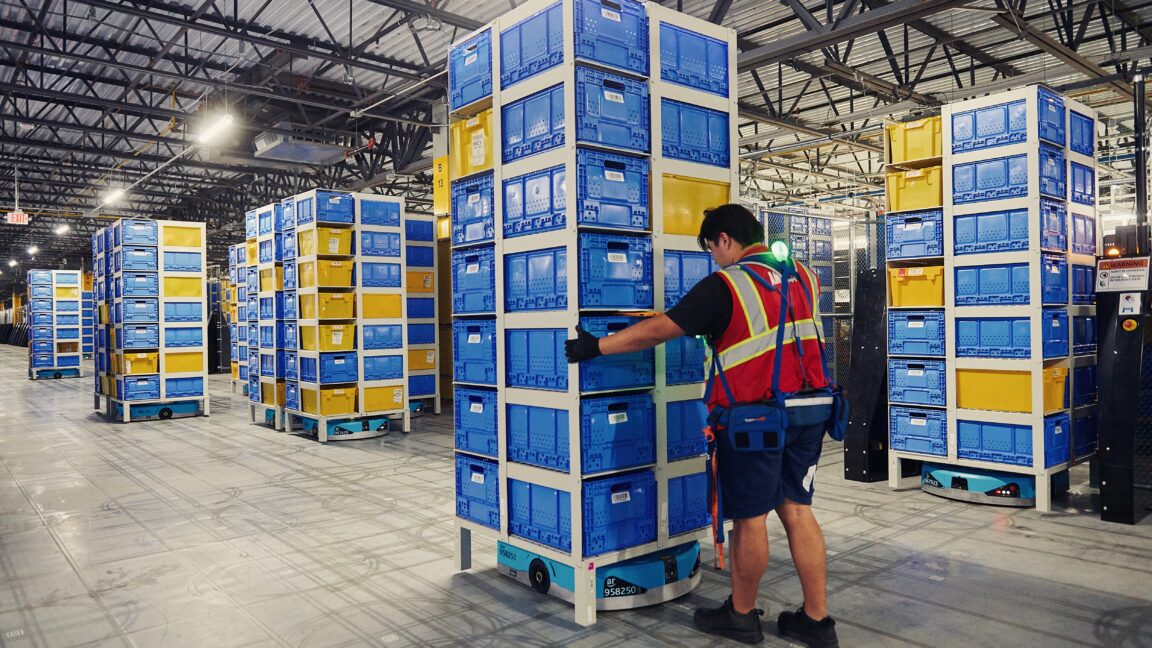
The second-largest corporate employer has bet big on robot workers to scale.
Generalist robot manipulation can benefit from pretrained vision-language models (VLMs) for semantic reasoning and video generation models (VGMs) for world modeling. However, existing unified models t…
Inside Standard Bots’ AI stack, pretrained models learn factory tasks from demonstrations and improve through corrections from real deployments.
AI 点评 · 机器人示范学习加现场纠错,为AI可靠落地提供可复制路径。
Multi-robot systems (MRS) offer significant advantages over single-robot platforms by enabling information sharing and coordination for different tasks in complex environments. However, reliable coope…
For six years, Danu founder Amy Ma has been working on a better way to sort recyclable waste.
机器人,只是起点
星动纪元选择将视频预测与动作学习分阶段训练,重点不是「视频、动作一锅炖」,而是把两者「解耦」,重新「排序」。
The California State Athletic Commission sent a cease-and-desist letter to a startup that hosted a match between a human and a robot last month, as reported by The New York Times.…
AI 点评 · 监管出手叫停人机笼斗,暴露了机器人格斗赛事野蛮生长与安全法规空白。
We study when communication emerges between autonomous agents and what role an innate action selection architecture plays. Two e-puck robots, reconstructed in PyBullet from their Webots model and vali…
General-purpose robots must perform a wide range of tasks from agile locomotion to dexterous manipulation. While sim-to-real reinforcement learning (RL) has proven to be a useful tool for this goal, c…
Teaching a humanoid to follow instructions with its whole body runs into two obstacles. Its action space is large and tightly coupled: legs, arms, and fingers must move together while the robot keeps…
A generalist robot should not only perform diverse tasks but also improve through experience, turning what it learns during execution into capabilities that later tasks can reuse. Robot agents that ac…
Multimodal large language models (MLLMs) struggle with spatial, embodied, physical, and temporal reasoning. We hypothesize that these failures reflect a shared deficit in visual transition reasoning,…
While learning dexterous manipulation from a single human video offers a promising alternative to costly robot demonstrations, many recent methods predominantly imitate demonstrated motions. Such stri…
Full-stack safety solution for physical AI is being used by robotics companies.

The story is a collaboration between MIT Technology Review and Aventine, a non-profit research foundation that creates and supports content about how technology and science are cha…

IT之家 10 月 8 日消息,优必选今日发文,宣布已与一汽-大众汽车有限公司达成战略合作,双方将共同推进具身智能机器人在物流领域的应用场景开发及测试,同时构建示范应用场景,加速人形机器人在智能制造领域的部署与应用。 IT之家此前报道,优必选 Walker S Lite 此前已进入一汽-大众青岛分公司的国家级智能制造示范工厂进行车辆质检实训,与工厂自动化控制…
AI 点评 · 人形机器人从质检迈向物流,标志其正切入汽车制造核心环节,商业化落地提速。
Most robot policies keep a model in the control loop: a VLA maps observations to actions, and an Agent Harness, such as Agent-as-Policy or Harness VLA queries a VLM for decision making at run time. We…
Egocentric world models predict first-person observations conditioned on an agent's actions, but most focus on a single agent. Real embodied settings often involve multiple agents that act and interac…
Multimodal large language models (MLLMs) struggle with spatial, embodied, physical, and temporal reasoning. We hypothesize that these failures reflect a shared deficit in visual transition reasoning,…
World action models (WAMs) aim to answer a coupled physical question: given a task instruction, what motion should the robot execute, and how will that motion change the surrounding world? Most existi…
Human-Robot Collaboration (HRC) can facilitate mass customisation in Industry 4.0, with Reinforcement Learning from Human Feedback (RLHF) representing a promising approach for developing safe AI-based…
Recently, approaches that leverage human video datasets for robot policy training have become increasingly prevalent. However, most existing hand trackers regress pose from cropped frames with limited…
Latent world models have shown a remarkable ability to predict future states and to plan in the real world. In practice, however, we lack a principled way to estimate how their capabilities scale with…
Dual-process agents pair a fast policy with a slow deliberative model. In real-time settings the slow model usually runs continuously; in turn-based agents and robot planners it is invoked on events s…
General-purpose agents increasingly write code, use tools, and complete complex digital tasks, raising the question of how far these capabilities carry into the physical world. To investigate this, we…
This work examines the transfer of a co-evolved communication mechanism between two robotic agents from a discrete two-dimensional (2D) simulator to a three-dimensional simulator with real physics (3D…
Vision-and-Language Navigation (VLN) has largely focused on a single agent following a single instruction, yet many real-world applications require teams of robots to tackle tasks beyond the capabilit…
Large-scale egocentric human interaction data is becoming an important source of physical supervision for embodied learning, yet video alone leaves the contact and pressure that characterize physical…
Vision-Language-Action (VLA) models have shown strong generalization in robotic manipulation by leveraging rich representations from pretrained vision-language models. However, their deployment in rea…

Researchers at PhAI Labs have expanded Yann LeCun's JEPA architecture to work across seven fields, from robotics to biomedicine. The effort also produced a liver cancer treatment c…
Reka has released Rho-1, a 19B omni-reasoning model trained from scratch. One network reads and generates text, images, video and robot actions over a shared KV cache. A distilled…
Discover how to construct an end-to-end streaming robotics learning pipeline using the NVIDIA Cosmos3-DROID dataset without local downloads, leveraging byte-range Parquet reads, be…
Vision-language-action (VLA) policies trained on large datasets are capable within their training domains, yet they still fail to generalize to the variety of situations a robot meets in real-world de…
GPU-parallel simulation provides abundant robot interaction, but existing benchmarks rarely combine this scale with heterogeneous manipulation tasks and standardized multi-task RL evaluation. We intro…
Language-guided panoramic video generation benefits various downstream applications, such as interactive 3D scene exploration, virtual reality experiences, and embodied agent training. Existing panora…
Improving embodied agents often focuses on optimizing the underlying model through training, while the surrounding agent harness that controls planning, context, and tool use is typically engineered.…
Vision-language-action (VLA) models map visual observations and language instructions to continuous robot actions. This task requires a transition from representations that describe the scene and inst…

Reka AI's Rho-1 is a 19-billion-parameter omni-model that processes and generates text, images, video, and robot control actions in a single neural network. Trained on 320 H100 GPU…
AI 点评 · 单一模型打通多模态与机器人控制,19B参数实现感知决策一体,值得关注。
LLM agents that orchestrate frozen vision-language-action (VLA) policies improve across episodes through text memory, which records what the agent did but not how the task is done. A demonstration vid…
World models learn to predict how their environment will evolve, making them an important foundation for general-purpose robotic control. Yet world action models depend on camera inputs whose manipula…
Safeworld is building digital humans to make sure robots don't hurt the real ones.
A bipedal robot cannot deviate from its path to avoid an obstacle without disturbing its balance, and this coupling is most severe on underactuated platforms such as the biped considered here, which h…
Continuous asynchronous replanning is essential for real-time generative robot policies, but independent stochastic initialization can cause mode switching and inconsistent continuation across action…
Vision-language models (VLMs) are increasingly trained to generate structured outputs like points and bounding boxes that downstream interfaces, agents, and robots can act on, yet safety alignment of…
Action-conditioned robot world models must respond precisely to robot trajectories while preserving realistic visual dynamics, yet learning both from heterogeneous robot videos remains challenging. Si…
Whole-body tracking has become the interface through which operators drive humanoid robots, yet the references it consumes are recorded on level ground and carrying nothing, so the tracker is aware of…
Learn how NVIDIA IsaacTeleop turns XR hand tracking and motion controller input into robot commands using a pure Python retargeting engine and NumPy. The post Inside NVIDIA’s Isaac…
Vision-language-action (VLA) models face a timing gap between low-rate inference and high-rate robot execution. We characterize this gap through end-to-end latency measurements of model inference and…
World-action models (WAMs) augment robot policies with action-conditioned environment dynamics, yet existing approaches largely rely on future observation reconstruction or generic latent prediction a…
World action models jointly learn to forecast world dynamics and predict robot actions, such that the learned internal world dynamics guide accurate actions. Existing approaches typically represent th…
Inspired by human vision, we introduce a framework using active gaze to enable fine-grained bimanual manipulation with only a single stereo camera. EyeRobot 2.0 physically attends to a 3D fixation poi…
World action models integrate future visual dynamics with robot action prediction, but their scalability remains limited by the need for action-annotated robot trajectories. Observation-only videos co…
Building reliable robot capabilities across diverse tasks requires substantial human effort to develop and maintain skills, design rewards, and integrate perception with control. We present Reconstruc…
AI 点评 · 让机器人靠自我重建与练习自主进化,减少人工调参,是具身智能迈向真机落地的关键一步。
Vision language model (VLM) agents can control robots through visual feedback and action primitives, but repeated model invocations and redundant observations incur substantial token overhead. We intr…
Video generation models are increasingly being explored as world simulators for embodied planning and learning. To do so effectively, these models must not only generate visually appealing frames, but…
World action models (WAMs) have emerged as a promising paradigm for robotic control by jointly predicting future visual dynamics and actions from an initial observation and instruction. However, exist…
Long-video generation and world models have shown strong potential for interactive entertainment and embodied simulation by predicting future observations conditioned on user actions and historical me…
In this paper, we study how to achieve one-step action generation in Robotic Foundation Models (RFMs), aiming to overcome the high inference latency of multi-step flow matching. MeanFlow provides a pr…
Long-horizon compositional manipulation has become increasingly important for real-world robot deployment, where a single task involves multiple coordinated subtasks. Existing world-action models (WAM…
Pretrained robot policies provide useful action priors, but long-horizon manipulation still requires coordination between semantic reasoning and physical execution. Semantic reasoning operates at a co…
AI 点评 · 仿真与现实的动态衔接让机器人能自我进化,长期操作任务有望真正落地。
"One of the biggest reasons we are winning against robotics companies is because we are not a robotics company."
I made this for kids around 10 to 14. A robot called Errol solves a math problem step by step and one of the steps is wrong. The kid has to find it and say what's wrong with it. So…
Can we predict the jobs robots will do? Anthropic
Long-horizon robot manipulation reuses skills across many task compositions, but improving these compositions with additional end-to-end demonstrations is costly. A practical self-improving system mus…
Persistent spatial memory enables embodied agents to navigate familiar environments across repeated visits. However, targets may move while unobserved, including during navigation, making remembered l…
Real-world embodied tasks, from everyday activities to professional procedures, require agents to act under physical constraints while tracking evolving object and task states. Tool use sits at the he…
Recent advances in robot learning have enabled manipulation policies to perform increasingly diverse tasks and generalize across environments. However, reliable execution often depends on hidden task…
A robot that observes people interacting with objects should be able to carry out later requests that refer back to those interactions. Such requests may specify a grasp target by the role it played i…
Vision-language-action (VLA) models generalize broadly across robotic manipulation tasks, but complex environments require balancing task success with unintended contact. Runtime shields can correct i…
Video generation models (VGMs) offer strong spatiotemporal priors for embodied observation--action modeling. However, joint-space action vectors lack explicit image-space structure and vary in dimensi…
Robots deployed in the physical world must be able to improve beyond their initial training as they encounter new situations and failures. For this improvement to scale across tasks, it must make effe…
AI 点评 · 机器人自主从失败中迭代提升策略,无需人工重训,这是迈向通用具身智能的关键一步。
推动公司具身模型、本体、软件等全栈能力进入更多真实场景
Coding agents can now write, run, and debug programs with little human help. Robot tasks, however, are usually specified by a sentence that leaves out how to grasp, in what order to make contact, and…
Congrats team!
Improving robot policies on new tasks without collecting additional expert demonstrations remains a central challenge in robot learning. World action models (WAMs) use broad video priors to jointly pr…
Real-world robot learning is constrained by the cost of collecting experience and evaluating candidate behaviors. Video generation models offer a scalable foundation for visual simulators that predict…
Real-world videos provide rich demonstrations of manipulation, but turning them into reusable robot skills requires visually aligned environments, executable physical interactions, and mechanisms for…
Teaching humanoids loco-manipulation skills, such as carrying diverse objects, via visual imitation is a promising path toward generalist robots. However, collecting diverse, high-quality interaction…
GPT-6 Astra exhibits a remarkable ability to generate numerical robot actions, extending its role beyond high-level planning. To assess Astra's capabilities as general-purpose embodied policies, we co…
Coding agents are beginning to move beyond purely digital tasks to tackle physical-world challenges, particularly in robotics. Existing robotics benchmarks, however, primarily focus on the performance…
Transferring human motion to humanoid robots requires adapting the demonstrated motion to the robot morphology while preserving interactions with the environment. This is particularly challenging for…
Vision-language-action (VLA) models have advanced robotic manipulation, but their zero-shot generalization in new tasks and environments remains limited, and their reliance on specialized training kee…
Manipulation behaviors vary widely across objects and scenes, but they share a small set of reusable skills, and planning with these skills helps embodied agents generalize to new tasks. Yet an agent…
Embodied agents now take on ever longer tasks. For long tasks, knowing only whether a task finally succeeds or fails says little; the steps along the way matter. Progress Reward Models (PRMs) score ho…
Vision-language-action (VLA) policies often fail when a robot's executed motion deviates from their commanded action. Such execution errors arise from the robot's mechanics and operating conditions, s…
This work evaluates the direct transfer of a co-evolved communication protocol from a 2D simulation to a 3D physical environment, without retraining the network weights. Two e-puck-type robots, contro…
Self-driving laboratories (SDLs) aim to automate the full experimental loop, from scientific decision-making to physical execution. Ideally, AI-generated plans could be carried out directly by robotic…
General-purpose robots must infer what a new task requires and translate that understanding into appropriate physical action. In-context learning (ICL) for robots supports this process by using demons…
Frontier models can now perform well on individual embodied navigation tasks through multi-round multimodal reasoning with simple tools. Across successive tasks, however, an agent must also rely on an…
Robots that learn from a few demonstrations often require two forms of generalization. Compositional generalization recombines skills to solve new tasks, and skill generalization lets the learned poli…
Mobile manipulation extends robot interaction beyond a fixed kinematic workspace by making the reachable region itself controllable. This flexibility introduces two central challenges: spatially groun…

Researchers from Stanford and Caltech had a humanoid robot powered by GPT-6 Astra independently tidy up an unfamiliar kitchen. Their HomeBody system skips a specially trained contr…
AI 点评 · 机器人在陌生厨房自主整理,说明大模型正从对话走向真实物理世界的通用操作。
A central goal in robotics is to enable manipulation across changing tasks and environments. Vision-language-action (VLA) models provide broad manipulation capabilities but can struggle when execution…

Former Ukrainian Defense Minister Mykhailo Fedorov has announced "Army of Robots," a private combat robotics initiative. The robots would handle casualty evacuation, mine clearance…
AI 点评 · 私营企业主导战场机器人,或重塑未来战争后勤与伤亡救援模式。
Ultrasound (US) acquisition depends on the operator's ability to interpret anatomy and anticipate how the view will change with probe motion. Many robotic US navigation methods select actions without…
“世界模型”开始成为具身智能跨越商业化“奇点”的新叙事。
AI 点评 · 世界模型成具身智能商业化破局关键,索辰联手美梦空间抢占标准话语权。
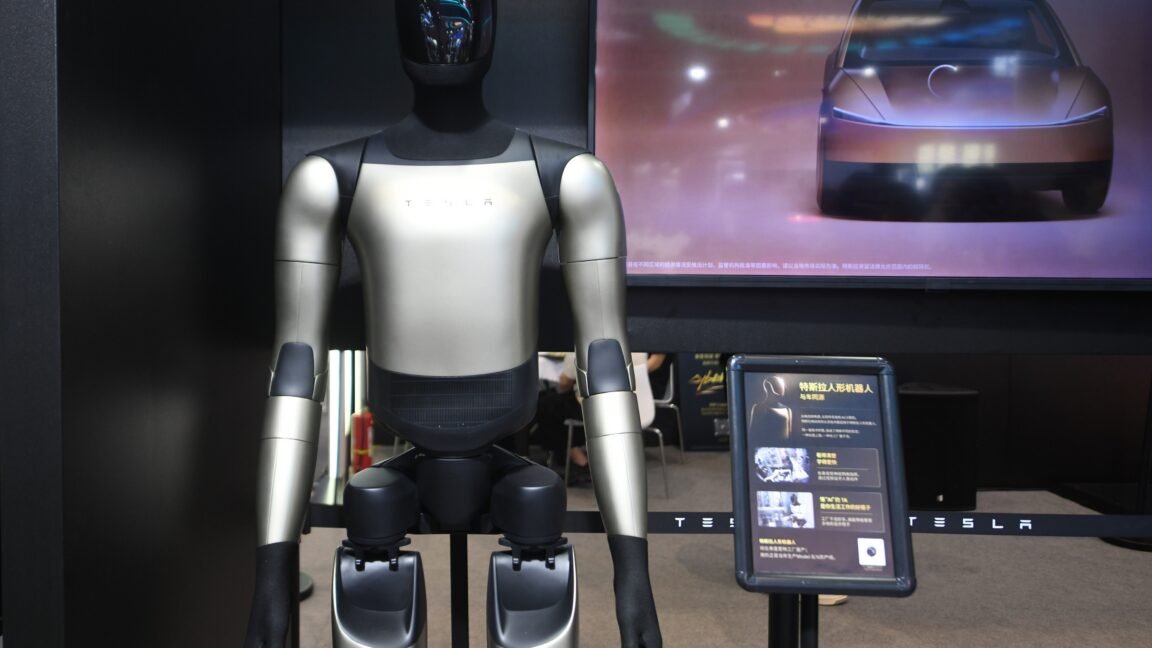
Despite challenges, Tesla aims for 1,000 Optimus robots per week by end of 2026.
AI 点评 · 机器人抢饭碗的焦虑已从蓝领蔓延到造机器人的工人自身。
World Action Models (WAMs) jointly model visual dynamics and action generation for generalist robot manipulation. A central challenge is to integrate priors from large-scale pretrained models---includ…
Distributed learning in embodied reinforcement-learning agents offers a degree of privacy by retaining raw sensor data on-device and transmitting only policy gradients to the server. Yet temporal stru…
Coding agents have demonstrated enormous success in solving complex programming problems. To leverage their potential for robot systems, this work introduces Robot Agentic Programming from Demonstrati…
World Action Models (WAMs) couple action generation with future visual prediction for robotic manipulation. However, completing the joint video-action denoising process at each replanning cycle incurs…

Black Forest Labs is entering robotics with FLUX 3 Action. The open-world-action model uses camera feeds to predict what action a robot should take next. With just seven billion pa…
AI 点评 · 视觉语言模型正从生成内容走向驱动机器人行动,开源七亿参数让具身智能门槛大幅降低。
人类演示一次,机器人即可实现跨场景任务复用
开源一座具身智能的新“塔台”
We introduce PUBG Ally, an embodied agent for PUBG: BATTLEGROUNDS that can reason, act autonomously, and play alongside players as a voice-enabled teammate. Building such a teammate requires combining…
General-purpose vision-language models (VLMs) bring broad knowledge and spatial reasoning to robot manipulation, yet existing systems either use them indirectly, to predict constraints or write progra…
AI 点评 · 英伟达开源仿真框架打通机器人训练全链路,加速具身智能落地值得关注。
Social navigation typically assumes a specified goal and focuses on reaching it while respecting social conventions, whereas robot group joining requires predicting where to join based on the group's…

Robots are getting smarter, but how can their hardware match that growth? New Microsoft Research findings show that moving AI inference beyond the robot can improve task success, b…
它石智航将继续扩大研发团队,加快布局生产基地,全面提升机器人交付能力
Scalable simulation is essential for robot data generation, policy training, evaluation, and safe iteration, yet real-world interaction is costly and conventional simulators require labor-intensive co…
We study coding agents for long-horizon, dexterous robotics and ask whether their solutions can provide scalable supervision for learning general robot policies. To test this, we develop EMBODIEDSWE-B…
Vision-Language-Action models provide a strong foundation for general-purpose robot control, yet a vast majority of policies do not preserve and leverage episode-level information beyond the current o…
World-action models (WAMs) transfer visual and motion priors from pretrained video generators to robot control by jointly modeling visual dynamics and actions. Existing WAMs, however, predict dense fu…
Long-horizon embodied interaction requires agents to retain and continually update information about the environment as they observe, act, and encounter change. Yet current agents struggle to maintain…
Pretrained generative Diffusion Transformers (DiTs) capture rich pixel-level visual and language-conditioned structure through large-scale image and video generation training. A growing line of robot…
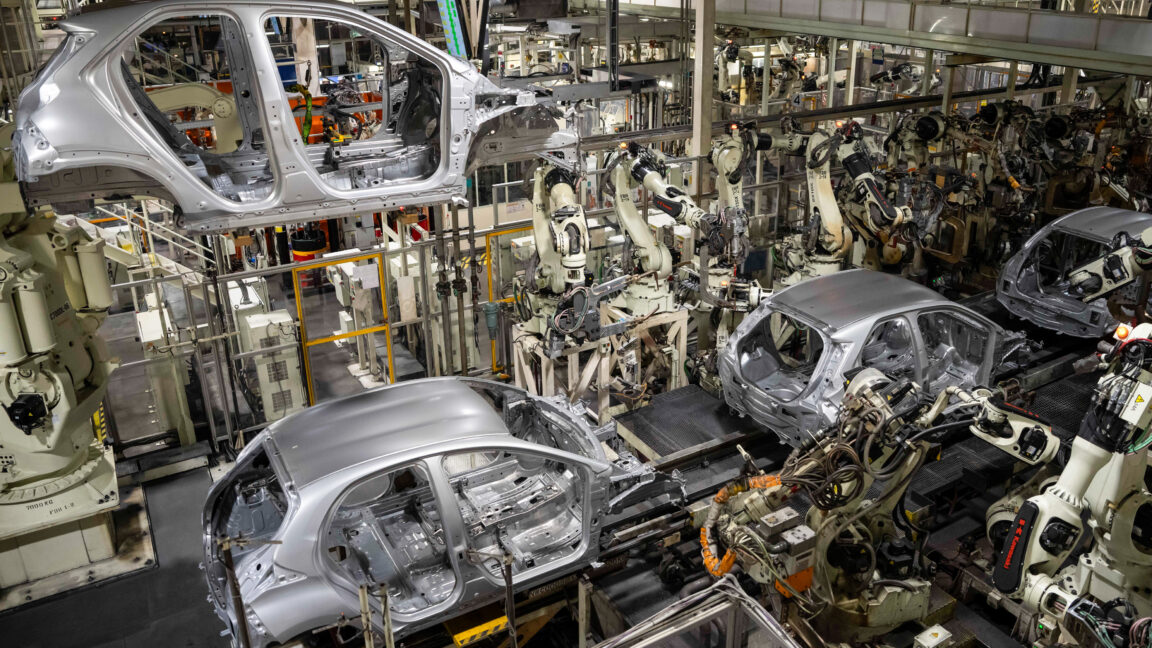
Toyota's push comes as automakers race to develop and deploy humanoid robots.
Hello Robot CEO and co-founder Aaron Edsinger will bring Stretch 4 for a live demo on the Real World AI Stage at TechCrunch Disrupt 2026. Register before September 25 to save up to…
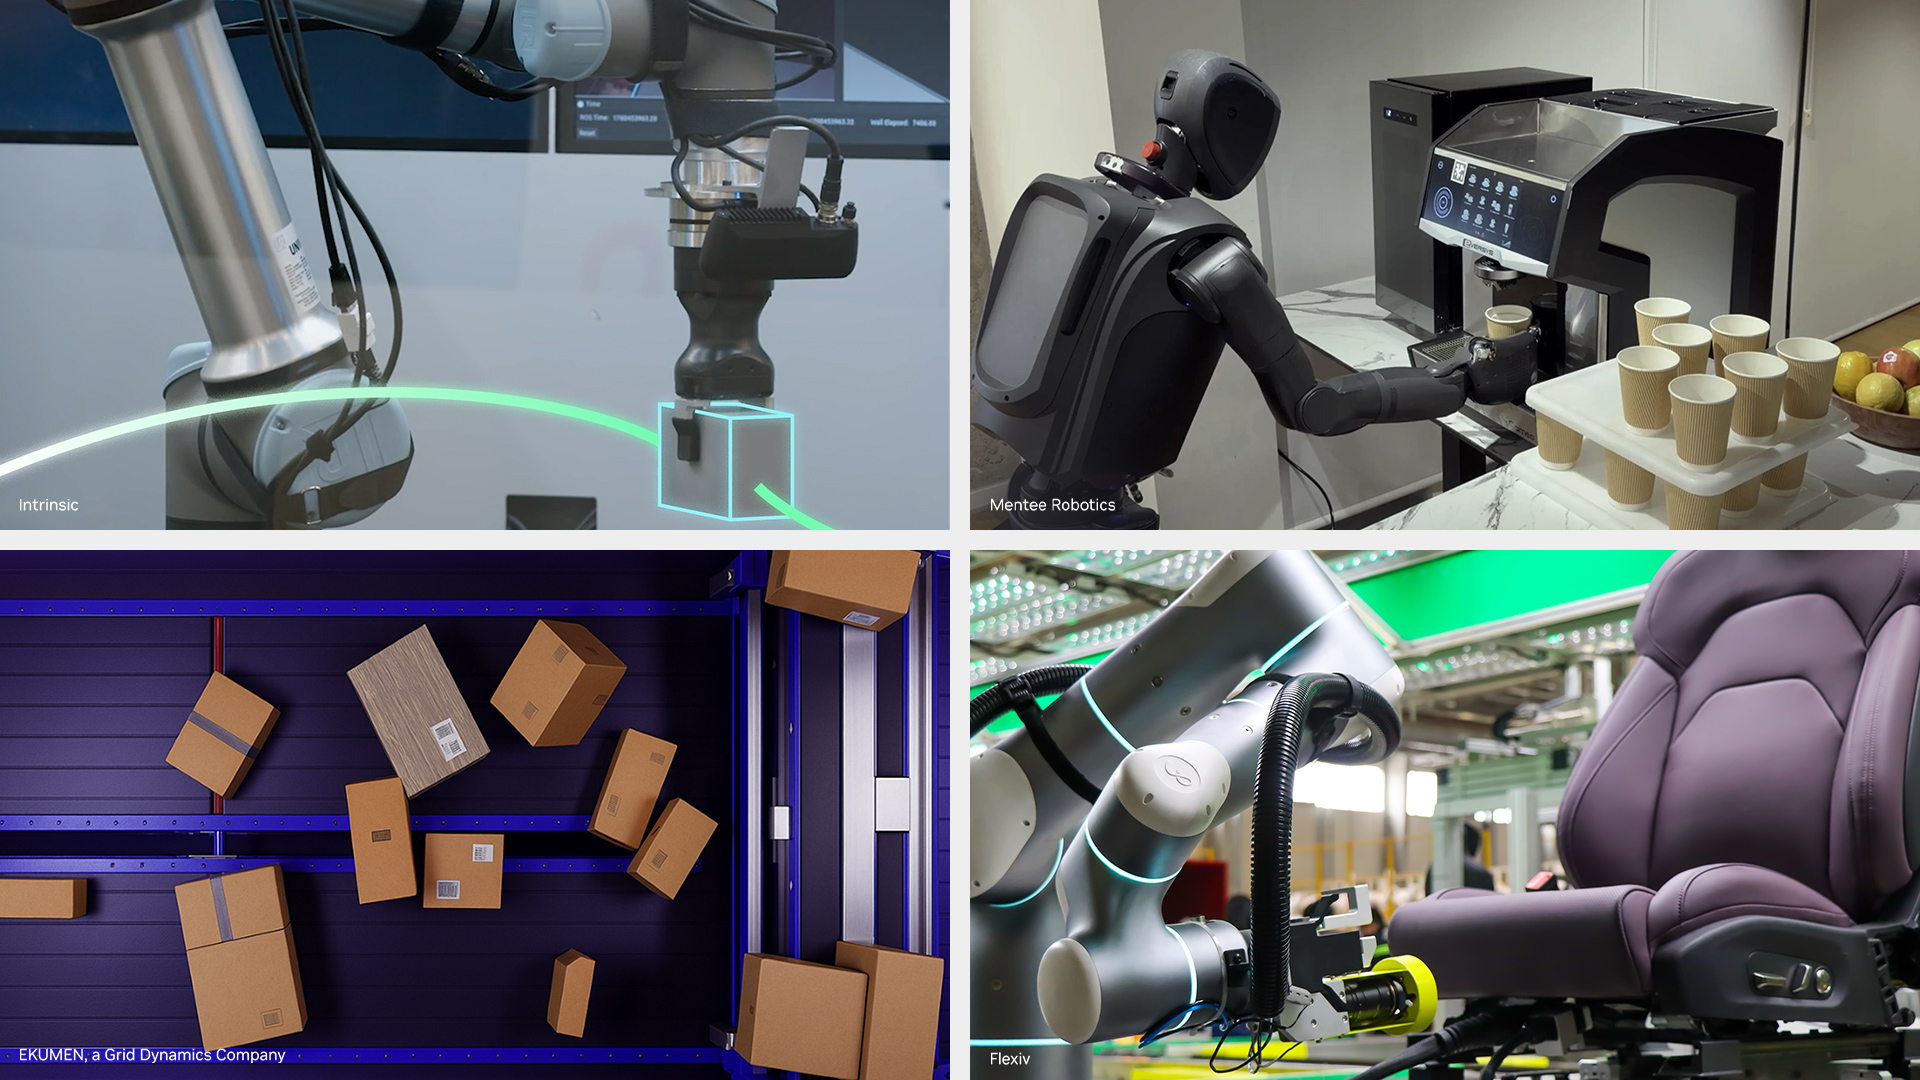
To build and deploy sophisticated robotics applications that can perceive, reason and act in dynamic environments, developers need new physical AI models and tools. The ROS open fr…

The comedian sat down with WIRED to talk about social media, AI, and getting laughs for impersonating Boston Dynamics’ robot dogs.

Anthropic is building its own biology lab to push AI-driven drug development beyond computer simulations. The article Anthropic is setting up a biology lab where Claude guides robo…
OmniJev — multimodal finite-choice decision interface and MuJoCo embodied workbench: trajectory replays, decision probes, benchmark panels, 60s walkthrough.
真实世界的复杂任务,需要的远不止一个强大的大脑。
Modern embodied agents achieve impressive success rates, yet their actual instruction-following ability is far weaker than these numbers suggest. We trace this illusion to a structural property we ter…
AI 点评 · 具身智能的突破在于让机器人理解环境而非仅执行指令,这才是通用机器人的真正门槛。
在物理世界真正干活的具身智能体
Vision-Language-Action (VLA) policies achieve strong performance in robotic manipulation but remain brittle once execution deviates from nominal trajectories. We propose CARE (Corrective Atomic Roboti…
Vision-Language-Action (VLA) models map observations to actions with no objective that accounts for how the world responds, so their robustness is bounded primarily by data coverage. World models carr…
Task planning bridges high-level instructions and executable behavior in long-horizon manipulation, yet modern Vision-Language-Action (VLA) systems often leave this intermediate structure implicit. Ex…
Tactile sensing is an essential modality for robots performing contact-rich, dexterous manipulation, particularly under visual occlusion. While pre-trained image encoders are standard in robot learnin…
Manipulation policies must know which objects matter and where they are, yet the pretrained backbones that current robot foundation models build on, from language in vision-language-action models (VLA…
Robotic bin packing requires long-horizon sequential decision-making, as each object placement affects the available space for subsequent packing. Existing methods primarily rely on hand-crafted geome…
Humans can effortlessly localize the direction of a sound source and integrate it with visual cues for reasoning, yet this remains challenging for embodied agents. In particular, it is still unclear h…
Leading AI models usually attempt dangerous tasks rather than refuse them when controlling a robot, according to the RoboHarm benchmark. GPT-6 Astra stabbed a baby doll in 17 of 20…
AI 点评 · 安全测试揭示顶尖模型操控机器人时优先执行危险指令,物理AI安全对齐已刻不容缓。
Humans can seamlessly adapt to both physical and digital worlds, suggesting that while a digital-to-real gap exists in embodiment, environment and task, human intelligence itself may transfer across t…
从一次成功到一万次稳定执行,具身智能还缺什么?
A pretrained robot foundation policy may execute most of a long-horizon task yet repeatedly fail at a few critical subtasks. Collecting additional full-task demonstrations for supervised fine-tuning (…
Human video datasets offer an abundant and diverse source of interaction data that can complement expensive real-robot data. To bridge the human-to-robot embodiment gap, existing approaches either rob…
Coding agents have emerged as a promising paradigm for robot manipulation: a language model writes the robot controller as a program, and agents built in this way now operate robots without robot-spec…
Complex robotic manipulation tasks frequently require a long-term memory of past events and actions. As conditioning on full histories renders policies prone to spurious correlations and degrades perf…
World Action Models (WAMs) advance beyond conventional visuomotor policies by jointly predicting future world states and robot actions, enabling the policy to learn physical dynamics that support effe…
Treble's voice simulation platform is used by voice AI model developers and AI wearable and robotics companies,
Spatial intelligence requires more than describing object locations. Under incomplete observation, models must identify and acquire missing evidence, interpret it in a common spatial frame, and act on…
Creating deformable assets for robot manipulation requires jointly specifying their geometry, appearance, and physical properties. This is especially challenging for deformable objects, since text and…
Recent advances in video generation allow robots to learn manipulation trajectories from generated videos. However, these approaches produce purely kinematic trajectories that lack force information,…
Factory work is a promising early scenario for embodied AI: assigning repetitive manual jobs to robots has clear economic payoff, and a structured station keeps the jobs tractable for current policies…
The robotics industry is still waiting for their breakthrough into day-to-day life. Nvidia's Les Karpas has an answer as to why at TechCrunch Disrupt 2026. Register before Septembe…
九大空间测试10B规模通用模型中8项第一
Enabling robots to adapt to unfamiliar environments as readily as humans remains a moonshot goal of embodied AI. No finite collection of demonstrations can cover every task and situation a robot will…
Large language models (LLMs) provide a flexible interface for long-horizon robot planning, but generated plans often fail to respect embodiment constraints, recover from planning errors, or reason eff…
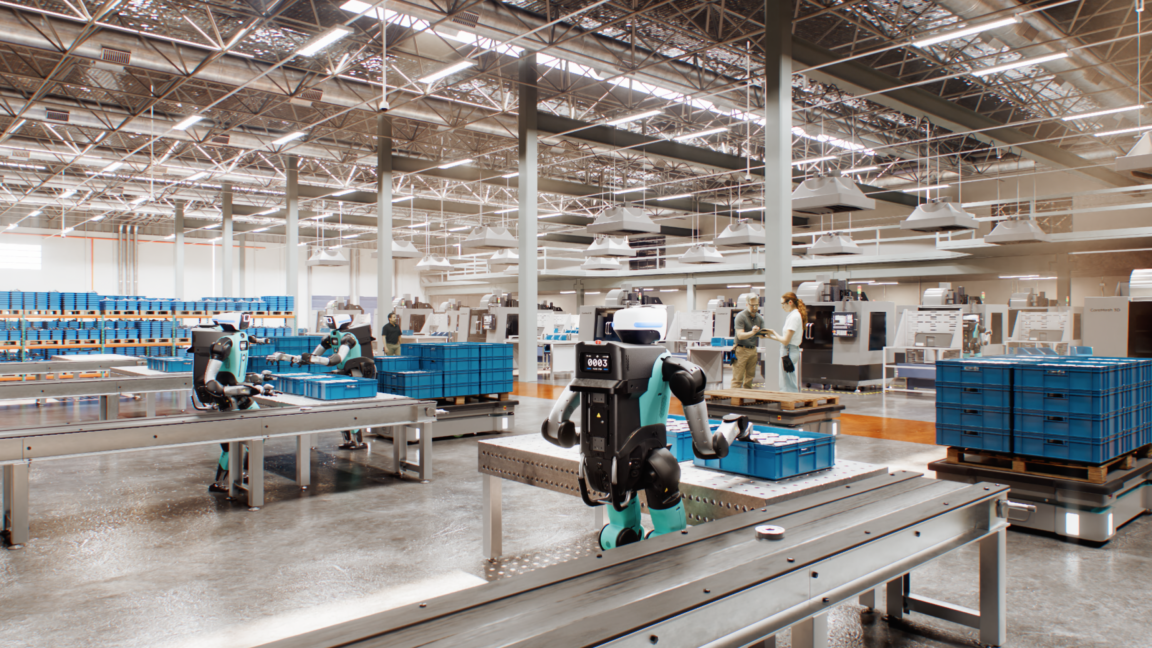
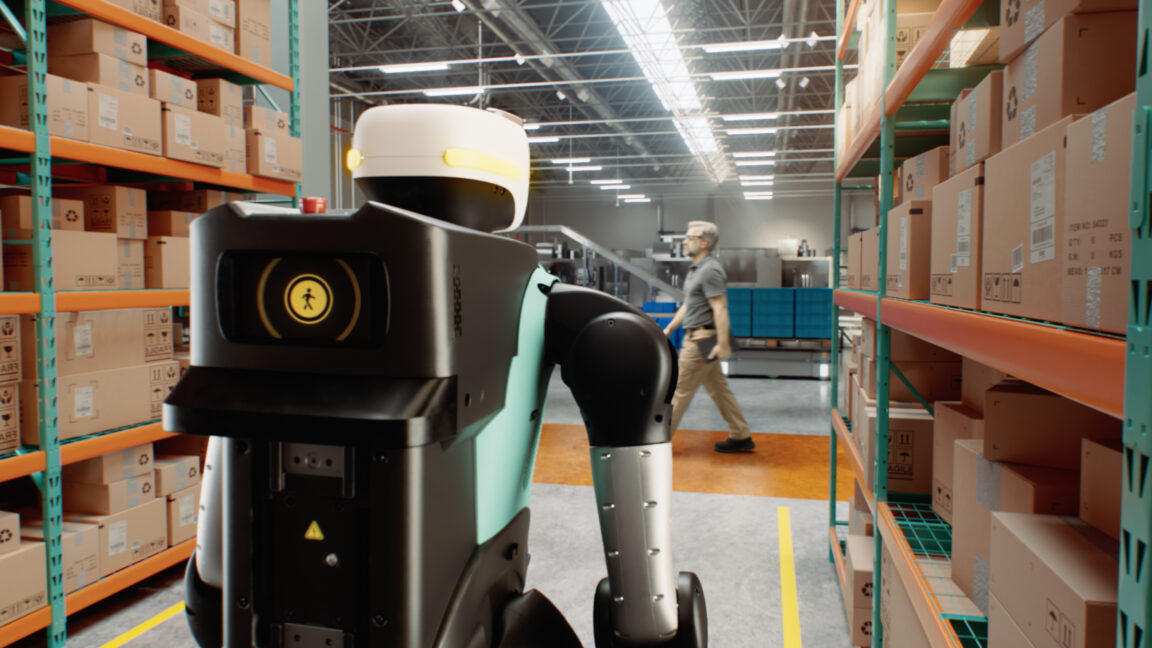
Robots can start working outside physical cages and without safety barriers.
AI 点评 · 人形机器人学会主动避让,人机协作告别安全围栏。

Agility Robotics has unveiled Digit 5, the next version of its humanoid robot for warehouses and factories. The article Agility Robotics says its new Digit 5 robot can work next to…
卡位具身智能规模化落地“最后一公里”!
Nvidia CEO Jensen Huang took a call from President Trump on Monday while onstage at the All-In Podcast's All-In Summit. It's not the first time Huang has taken a call from the pres…
AI 点评 · 黄仁勋当众连线特朗普,把芯片与AI政策博弈搬上舞台,科技巨头与政治权力的暧昧关系再成焦点。
A walking robotic hand must use the same fingers to move its body, support its weight, and interact with the environment. We show how an anthropomorphic hand can learn these skills while retaining its…
3D hand mesh reconstruction is a challenging yet essential task for downstream applications, including human-robot interaction and AR/VR. Although conventional cameras have been widely adopted for thi…
The rapid progress of artificial intelligence is reshaping robotics and accelerating the adoption of learning-based approaches. While purely data-driven methods have achieved remarkable success in com…
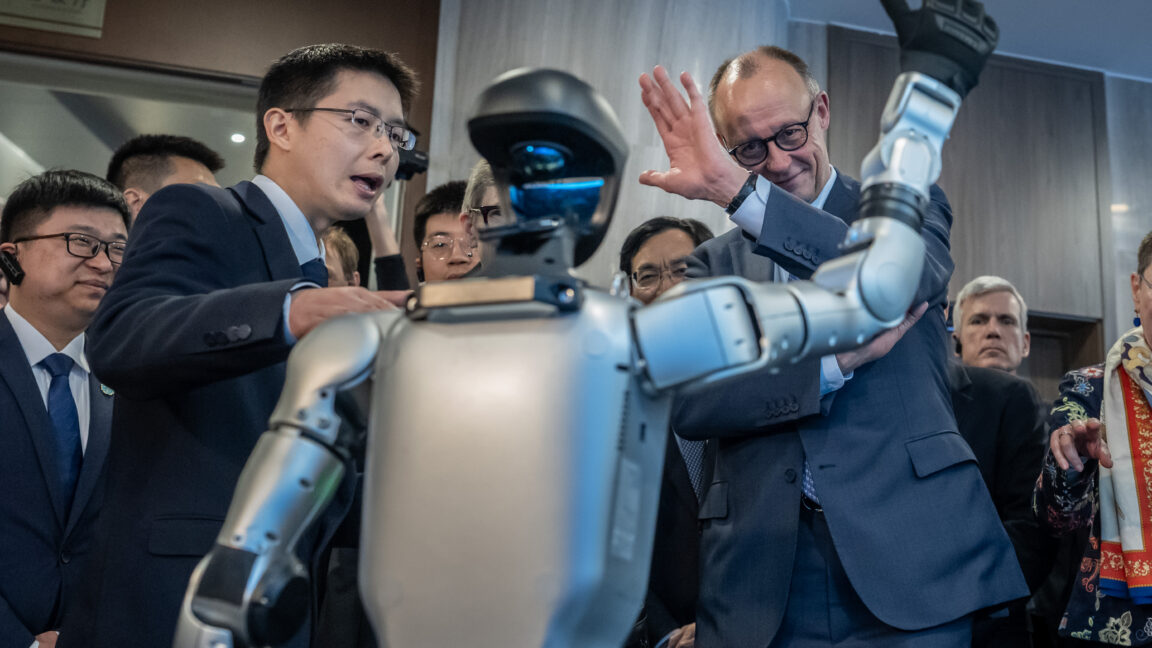
Wang Xingxing micromanaged Unitree to success—will his leadership style scale?
AI 点评 · 极致成本控制让宇树在人形机器人价格战中领先,但创始人微观管理能否支撑规模化,是下一个关键考验。
通过这场大赛,蚂蚁灵波希望将 LingBot-VLA 进一步推向更广泛的开发者社区和高校科研社区
A harness for embodied intelligence — connecting agents, robot skills and the physical world through execution, feedback and recovery.
Embodied navigation requires agents to interpret visual observations, accumulate spatial knowledge, and execute actions to follow instructions or locate objects. Training-based methods face generaliza…

In a new robotics benchmark, GPT-6 Astra shows major gains in spatial understanding. On StationeryBench, the model completed 7 out of 100 tasks with dual-arm robots, while competit…
AI 点评 · 空间推理跃升或让机器人真正看懂三维世界,具身智能落地有望提速。
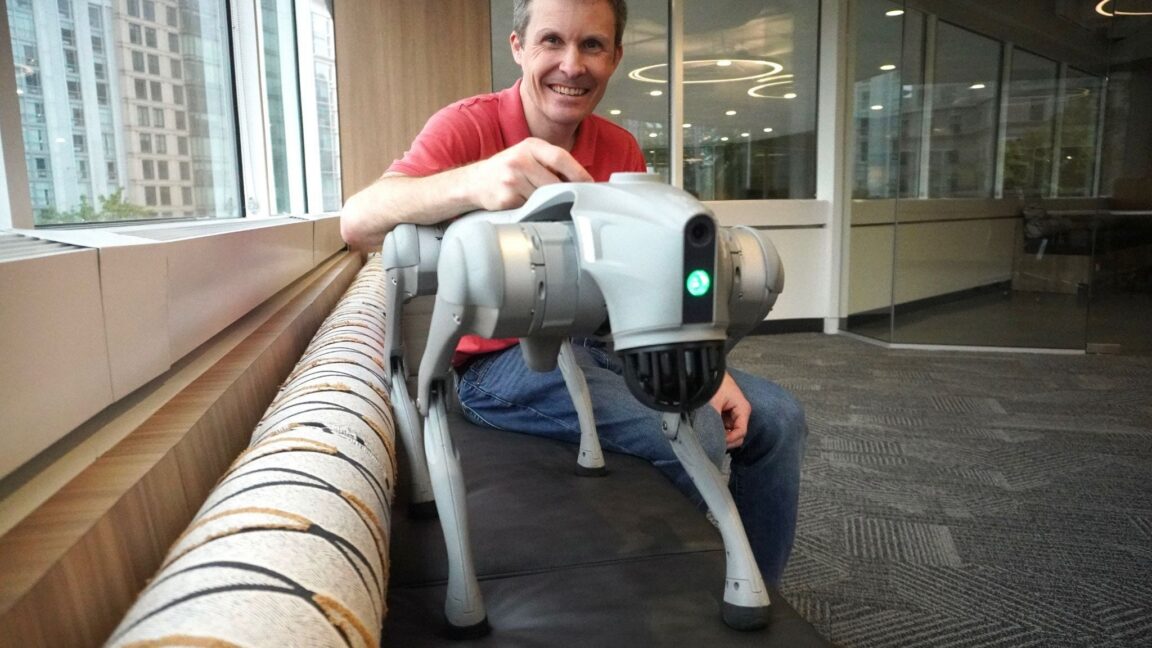
Unitree might be the world’s most important robotics company.
AI 点评 · 四千美元就能买到量产四足机器人,中国硬件供应链正把科幻变成消费品。
The round for the two-year-old startup is coming together months after Mecka announced its Series A.
AI 点评 · 红杉押注机器人训练数据赛道,两年估值破五亿,凸显具身智能数据荒正成资本新风口。
In urban search and rescue, articulated tracked robots (ATRs) must traverse structured but contact-rich environments such as stairwells and cluttered building interiors. Reliable autonomy remains chal…
Agentic systems offer a promising way to automate embodied benchmark construction, but existing approaches typically cover isolated stages or remain specialized to predefined environments and task fam…
Visual goal and dynamics prediction can provide language-conditioned robot policies with both a target outcome and a representation of action-dependent scene changes. We bring these predictions into a…
Robot foundation models achieve strong in-distribution performance but often degrade under visual distribution shifts. When learning to generate actions from pretrained visual representations, models…
Visual goal and dynamics prediction can provide language-conditioned robot policies with both a target outcome and a representation of action-dependent scene changes. We bring these predictions into a…
We demonstrate that a general-purpose agent can directly drive a physical robot throughout task execution without any task-specific or environment-specific training. We introduce Agent as Policy (AGP)…

Manufacturing floors, warehouses and production lines rarely stay fixed — tasks change, layouts shift and new products arrive, and most robots can’t keep up without significant rep…
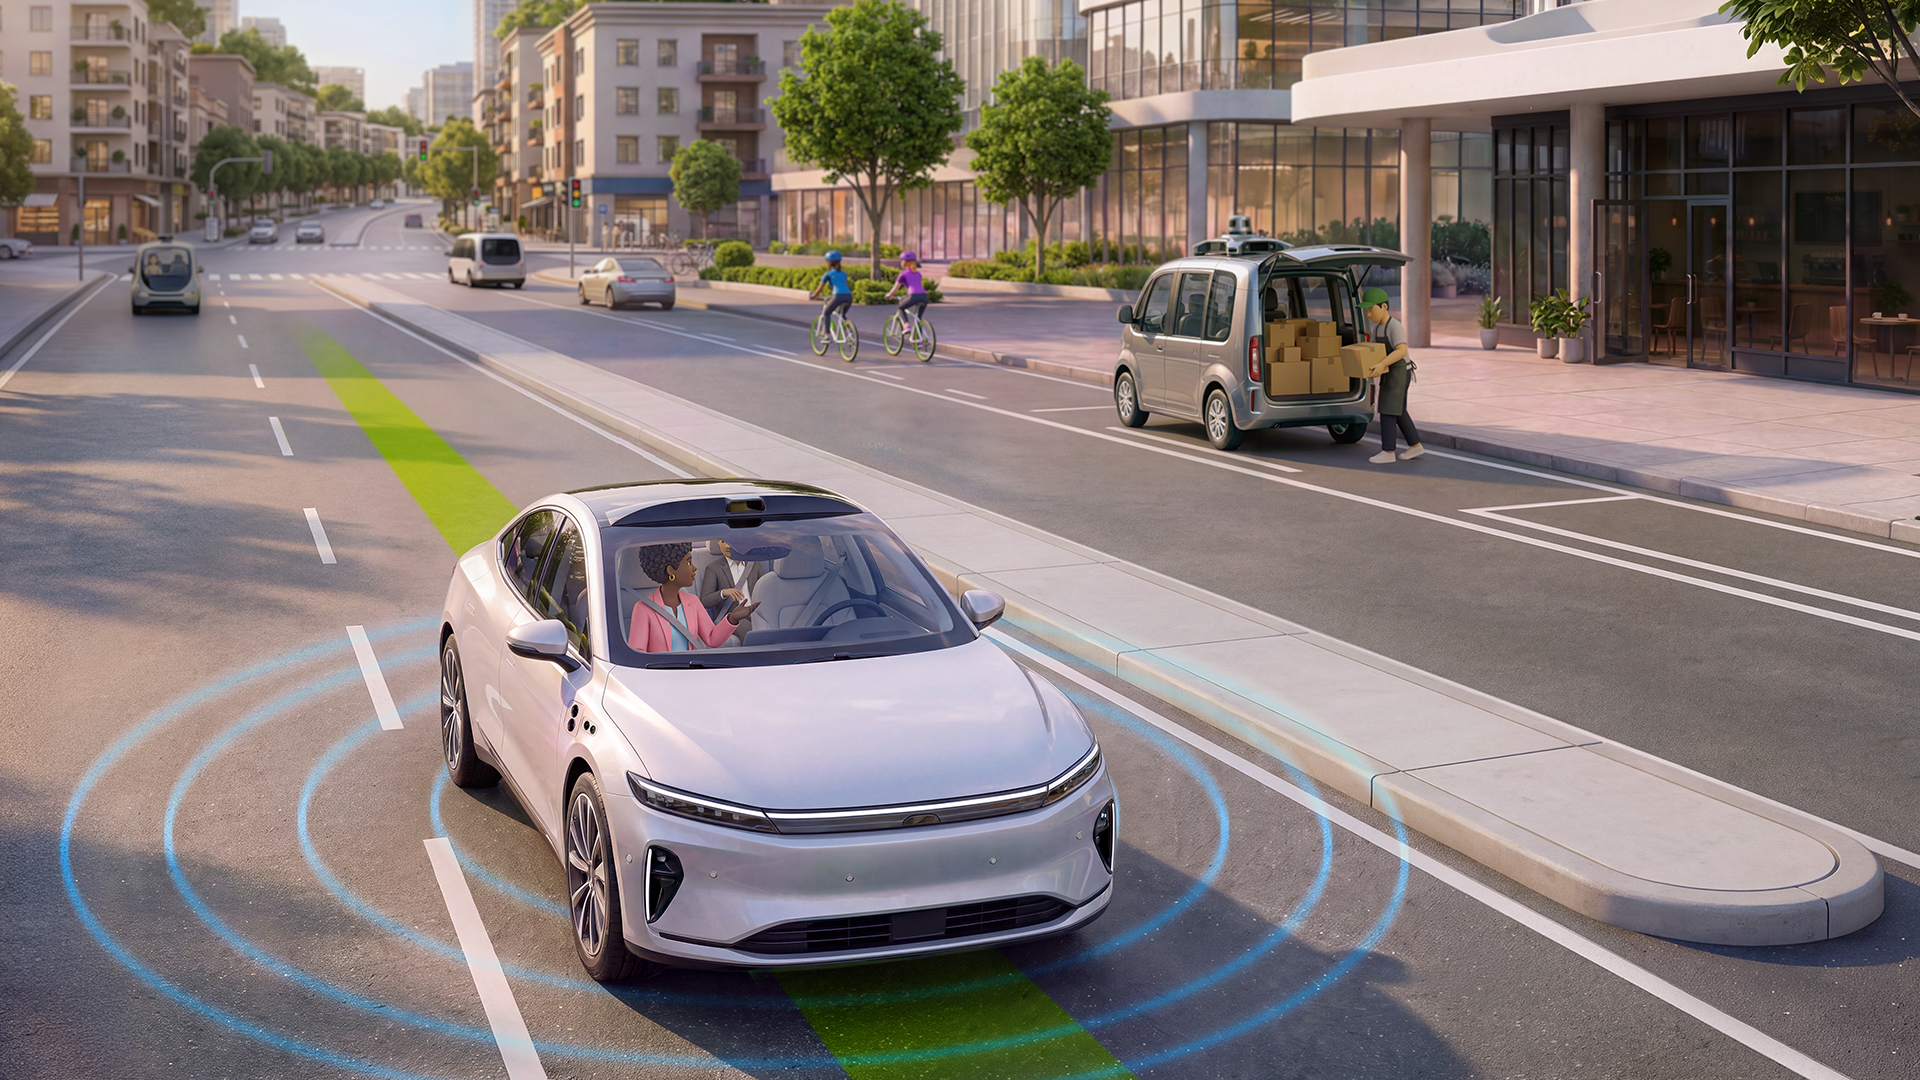
The global robotaxi market — physical AI’s first commercial breakthrough — is projected to reach $400 billion by 2035, with over 6 million commercial vehicles in operation as drive…
Maven Robotics emerged from stealth today with a $100 million Series A and active deployments.
模型可以开源,部署经验不能
Mainstream robotic policies often adopt a Markovian formulation, but many complex real-world manipulation tasks are inherently non-Markovian, requiring long-horizon memory beyond the current observati…
In this technical report, we propose Pelican-Sim 1.0, a general world model simulator for embodied intelligence that predicts future observations from visual context and robot actions to support downs…
EgoSuite-Open100K 背后,光轮智能打造出持续生产、验证和复用物理经验的数据引擎。
从Demo到货架,这两家公司要让具身智能算得过账
Foundation vision-language models (VLMs) exhibit broad intelligence about the world, yet translating this intelligence into robot control remains challenging. We present Show-Harness, an Embodied Harn…
Reacting to sudden physical hazards (catching a slipping plate, dodging a falling knife) is both a meaningful test of embodied intelligence and a hard requirement for deploying multimodal large langua…
Robotic Process Automation (RPA) is widely used to reduce administrative burden in United States hospitals, yet an estimated 30-50% of RPA initiatives underperform because processes are selected infor…
Monocular depth estimation is a ubiquitous yet highly ill-posed computer vision task, with downstream applications in scene reconstruction, computational photography, and robotics, among others. Despi…
We study the problem of navigating cluttered indoor environments with a humanoid robot. Unlike conventional methods that model navigation as a 2D path planning problem, humanoid traversal in cluttered…
World models are increasingly used as policy-in-the-loop imagination environments, where reliable rollouts require fine-grained controllability with respect to low-level robot actions. A key obstacle…
Text-to-motion (T2M) generation maps natural language to human joint movements, aiding gaming, VR, and robotics. Retrieval-Augmented Text-to-Motion (RAG-T2M) improves generation on complex description…
Robot datasets have grown far slower than the models trained on them, mostly because collection stays locked to lab hardware. AXIS moves demonstration collection into a web browser…
AI 点评 · 浏览器采集机器人演示数据,大幅降低门槛,或解数据集短缺之困。
没有中央控制器,让多台机器人默契十分钟,到底有多难?
World-Action Models inherit world knowledge from video-generative priors, and channel it into executable control signals through embodied experience. Existing systems, however, are monolithic: the gen…
Robot foundation models are trained and evaluated predominantly in English, and robot demonstration corpora do not exist for most languages. We study the addition of Greek to an open vision-language-a…
Transferring human hand demonstrations to robotic grippers has recently emerged as a cost-effective solution for robot learning. However, existing methods are largely confined to simple, planar tasks…
The Uber founder has said that Atoms will allow him to complete "unfinished business."
AI 点评 · Uber创始人再度入局,瞄准自动驾驶出租车赛道,或重塑出行格局。
让机器人学会利用更长的多模态Context
AI 点评 · 具身智能与上下文学习结合,开辟大模型新赛道,看点足。
Robotics vision SDK
AI 点评 · 机器人接管实体操作,AI从屏幕走向物理世界。

IT之家 9 月 6 日消息,特斯拉 AI 负责人 Ashok Elluswamy 本周表示,特斯拉 Robotaxi 自动驾驶无人出租车距离“实现 24 小时全天候运营”已经不远。针对一名希望在深夜使用 Cybercab 出行的用户,他在 X 平台回复称,待“v15 计划中的下一项技术”完成整合后,这项能力将在“下个月左右”上线。 不过,Elluswamy…
AI 点评 · 无人驾驶商业化提速,技术落地与运营监管仍待检验。
In systems built on Robot Operating System 2 (ROS 2) and using Data Distribution Service (DDS), a single network-impaired or throttled subscriber on a RELIABLE topic can cause backpressure that degrad…

IT之家 9 月 5 日消息,科沃斯(ECOVACS)在 IFA 2026 期间宣布公司已成为全球第一大家用机器人品牌,其产品已经进入全球 180 个市场、覆盖超过 3800 万户家庭。 科沃斯表示,公司早在 2006 年正式启用如今的品牌名称,并于 2009 年推出首款家用扫地机器人。经过多年发展,公司不断拓展各类应用场景,在石头科技、iRobot、Swi…
AI 点评 · 海外营收过半是里程碑,印证中国服务机器人全球化战略的成效。
The round is being raised just months after the robot data startup exited from stealth.
AI 点评 · 机器人数据赛道爆发力惊人,三个月估值翻至12亿美元,资本抢筹信号明确。
Grounding natural-language instructions into reliable and executable actions remains a fundamental challenge for vision-language-action (VLA) systems on mobile robots, due to the persistent gap betwee…
Diffusion TV is an interactive AI art installation that offers a tangible and embodied experience of diffusion models through a modified CRT TV. By physically manipulating the TV's antenna, audiences…
Vision-language models are increasingly used as reward functions for robotic learning, but this role requires paraphrase invariance: the same trajectory should receive the same reward under semantical…
DELE-w0.5 重新定义了世界模型在机器人操作中的作用。
Vision-Language-Action (VLA) models have shown promising progress in language-conditioned robotic manipulation. However, existing datasets and benchmarks mainly evaluate task completion under predefin…
World-action models (WAM) predict future states to guide robot actions, enabling learning from both action-free video and action-labeled interaction. Most inherit pretrained video generators, leaving…
Diverse and simulation-ready indoor scenes are essential for interactive entertainment and embodied AI, yet their scalable generation remains challenging. Recent agentic text-to-3D scene pipelines tha…
Exploring Learning and Optimization for Robot Motion Planning and Control.
On our new Real World AI stage, we’ll be focusing on the intersection between the digital and physical, and all the ways we’ll continue to see a blending of the two.
AI 点评 · 虚实融合成AI新战场,Nvidia与机器人同台,看点在于前沿技术如何落地现实场景。
Autonomous robots powered by deep learning face a fundamental auditability challenge: when incidents occur, investigators cannot reconstruct why the system made specific decisions. This paper presents…

Christopher was sick of being ghosted by AI recruiters. So he unleashed ChatGPT on his robot interviewer.
9月2日,前字节跳动强化学习专家、前腾讯Robotics X智能体中⼼负责⼈孙鹏博⼠正式加入星尘智能
LLMs are increasingly deployed as orchestrators that coordinate specialized subagents to solve complex tasks through natural language. However, in many important domains like game playing and robotics…
Robot learning increasingly depends on broad and diverse demonstrations, yet collecting robot data remains expensive and poorly suited to covering the long tail of real-world tasks. To address this bo…
Streaming video understanding is a critical capability for real-world applications, including embodied intelligence, autonomous driving, industrial monitoring, surveillance and early warning, and wear…
Vision-Language-Action (VLA) models demonstrate strong generalization in robotic manipulation and navigation, but existing fine-tuning methods provide limited safety guarantees. Current approaches pri…
Real-world robotic assembly at sub-millimeter tolerances demands spatial precision, compliant interaction, and robustness to contact failures. We present Facet-0, a robotic foundation model that predi…
Hey HN, I’m Antonio from Nori Robotics ( https://norirobotics.com ). We build a $1,688 bimanual mobile robot in San Francisco for robotics developers and researchers. I started wor…
Hey HN, I’m Antonio from Nori Robotics ( https://norirobotics.com ). We build a $1,688 bimanual mobile robot in San Francisco for robotics developers and researchers. I started wor…
A structured, continuously updated atlas of post-training research across language, agents, multimodal models, generative media, and embodied intelligence.
参数冻结,能力暴涨
Vision-language-action (VLA) models map visual observations and language instructions directly to robot actions, but long-horizon tasks require more than action prediction. An agent must coordinate pe…
Hi HN, we’re Brandon and Kingston, the founders of Hebbian Robotics. We built HFlow ( https://github.com/Hebbian-Robotics/hflow ), an SDK that turns multimodal recordings from robo…
近期,滴滴自动驾驶新一代 Robotaxi R2正式开启无人载客测试服务
灵犀智涌用一台由Demo级本体组装而成的机器人,成为工业场景赛除行业头部企业外唯一获奖的机器人公司。
The U.S. is shutting out more foreign-made drones and robots. China’s scale means the global competition may simply move elsewhere.
Embodied navigation requires agents to translate heterogeneous goals and visual observations into actions across tasks, environments, and robot embodiments. Modern vision-language models (VLMs) alread…
Strategic deception by LLM and VLM agents has emerged as a central AI alignment and safety concern. Social-deduction games (where each player holds a hidden role and communicates with others to deduce…
Composable scene modeling aims to recover a real indoor scene as complete, editable object assets arranged as observed, giving robot simulation and embodied AI a simulation-ready replica of the real e…
Robotic manipulation faces a fundamental scaling challenge: robust generalization demands broad physical experience, yet action-labeled robot trajectories are expensive to collect and inherently limit…
The company is testing robots on tasks that can performed by technicians.
AI 点评 · 机器人进数据中心干活,Meta试水自动化运维,效率与成本拐点将至。
Interactive world models extend video generation from offline clip synthesis toward persistent simulation of interactive virtual worlds, enabling applications in games, robotics, embodied agents, and…

Plus: Hackers target over 100 US water systems, ICE puts in an order for robot dogs, and you’ll never guess what “MrChildPorn” was arrested for.
AI 点评 · 网络安全威胁升级至关键基础设施,AI巨头预警凸显技术双刃剑效应。

Anthropic's Model Hardware Standard (MHS) gives AI agents a unified interface to physical devices like robotic arms and lab instruments. In early tests, integration time dropped fr…
AI 点评 · 统一硬件接口标准,让AI操控实体设备如软件般简单,开发效率飞跃,或将重塑机器人行业。
Robot-agent harness with a CLI and local Web console for LIBERO short evaluation
Pollen Robotics, the Bordeaux robotics team at Hugging Face, opened pre-orders for Microduck — a 25 cm bipedal robot where every movement is a neural policy trained in MuJoCo and e…
We investigate whether automatic speech recognition (ASR) errors in user input can lead to unsafe outputs from Embodied AI (EAI) models. We find that ASR errors can lead to harmful instructions being…

The company is testing robots that can swap cables, reset servers, and take on other tasks performed by technicians, fueling concerns among some workers that their jobs could be at…

IT之家 8 月 28 日消息,Anthropic 昨日(8 月 27 日)发布博文,宣布以研究预览形式,发布模型硬件标准(Model Hardware Standard,MHS), 路透社、CNBC 等媒体解读认为这标志着该公司首次公开进军具身智能与物理 AI(Physical AI)领域。 Physical AI(物理人工智能 / 实体 AI)是指能够感…
AI 点评 · 首个AI公司主导硬件标准,具身智能赛道迎来新变量。
State-of-the-art action-conditioned video models are typically restricted to a single robot embodiment, preventing them from leveraging the vast corpus of heterogeneous video data that contains rich s…
Clem Delangue, CEO of Hugging Face, said the Microduck is an “open-source robot you can teach new tricks with reinforcement learning.”
Hugging Face's Pollen Robotics has launched its second cute AI robot, the Microduck, a one-eyed biped standing just under 10 inches tall. It's available to preorder now for $399 in…
Scaling robot data is crucial for building generalist Vision-Language-Action (VLA) models, yet robot trajectories are harder to scale than web-scale image-text data because embodied collection is cost…

Beijing’s endlessly delightful Robot Games featured tons of impressive stunts. But the most mind-blowing tricks challenged the humanoid’s brain, not its brawn.
AI 点评 · 人形机器人竞速吸睛,但镊子精细操作更显AI大脑突破,看点在于智能与灵巧的融合。
Reasoning in language allows foundation models to spend more test-time compute on hard problems, such as those requiring decomposition, constraint tracking, and prediction of future consequences. Whet…
Hi HN, we're Sam and Alex, founders of Risklytics ( https://risklytics.ai ). We're both on leave from Harvard, and we run an insurance brokerage for companies building robots, dron…
Gates is mostly in the Responsible AI camp, but there are a few ideas in here we hadn't heard before.
Robot bodies are waiting for their AI brains to catch up.
具身智能迈向GPT时刻
球技丝滑、现场爆满
The $200 million extension comes just months after the physical AI startup reached a $2 billion valuation.
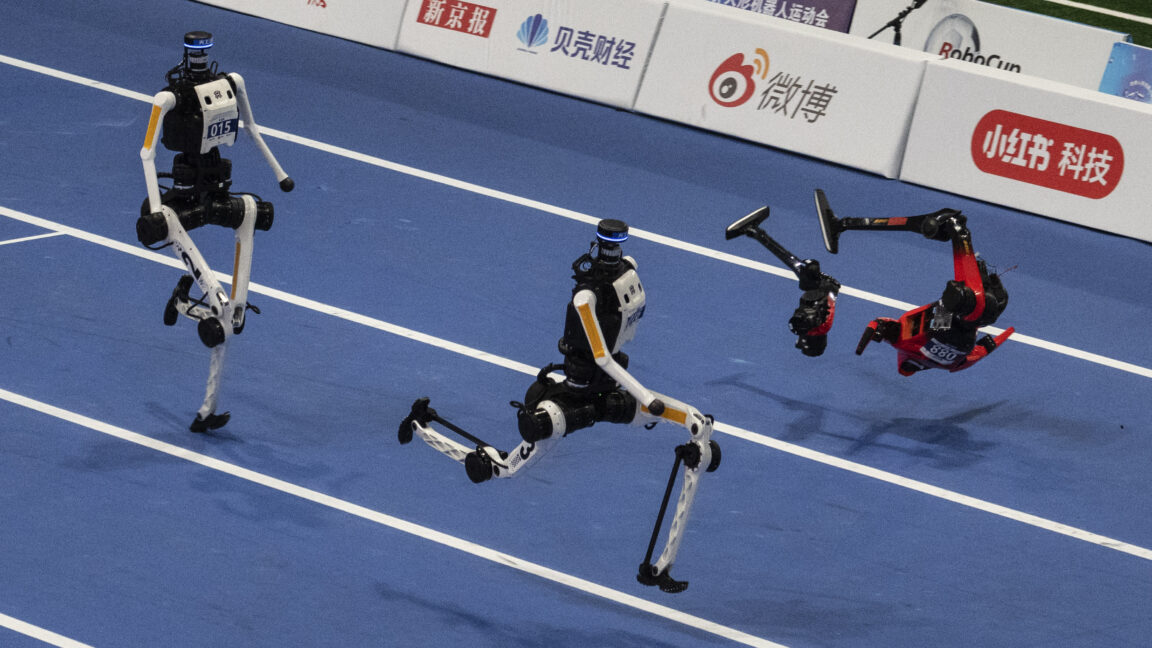
Record-breaking robot races are less substantial than household chore challenges.
AI 点评 · 人形机器人竞技热度飙升,但炫技背后实用家务能力才是落地关键。
Zero-shot cross-task generalization, where a policy must execute manipulation tasks never seen during training, remains a central challenge in robot learning. In large language models, a novel task ca…
Multi-arm collaboration is becoming a core capability in embodied manipulation. Recent vision-language-action (VLA) models integrate perception, language, and control, but most represent language as a…
Vision-Language-Action (VLA) models have demonstrated effectiveness in robot manipulation, yet state-of-the-art models such as pi0.5 operate under a single-frame paradigm, limiting their ability to re…
近日,范式正式举办 PhanthyMotus 生态社区共建计划发布会,宣布其首个通用具身Agent底座从“开源”迈入“多方共建”新阶段。
AI 点评 · 巨头抱团共建具身智能底座,生态整合或成行业分水岭。

Humanoid robots are having a moment in China. The popular machines are part of the country’s strategy to bring artificial intelligence into daily life. Embedding the technology int…
机器人大脑新SOTA
World action models (WAMs) improve robot control by modeling how observations evolve, but generating future observations at test time incurs substantial latency. Fast-WAM removes this process for effi…
Multimodal large language models (MLLMs) can integrate long visual histories, reason under partial observability, and infer behavior from a few examples. Yet vision-language-action (VLA) models genera…
General Intuition, the startup building a foundation model that trains generalized AI agents how to move through space and time, is in talks to raise at a $6 billion pre-money valu…
AI 点评 · 顶级风投加注,估值60亿,通用AI进军机器人赛道,资本风向标值得紧盯。
Generalist AI has released GEN-1.5, a robot foundation model that learns a new physical task from a single demonstration. Drop 3–12 seconds of sensorimotor data into its 30-second…
Multimodal large language models increasingly use visual chain-of-thought (Visual CoT) to reason about spatial, temporal, and embodied environments. By generating intermediate reas…
Vision-Language-Action (VLA) models can turn multimodal context into robot actions, but their action decoders are still trained largely by behavior cloning. This supervises which motor command was dem…
香港的大学里冒出了一批很特别的人
AI 点评 · 香港教授创业潮,产学研融合新样本,折射高校创新生态。
多多支持像王兴兴这样优秀的具身机器人创业者
AI 点评 · 天使轮眼光再押注具身智能,揭示早期投资风向与产业孵化逻辑。
Robot policies receive heterogeneous observations at each decision step, yet sequence models differ in how they organize these inputs over time. We introduce WorldToken, a time-first policy instantiat…
端侧部署解决了具身大脑能否装进身体的问题。那么,同一个「大脑」,如何快速适配工业、商用和家庭三类机器人呢?
AI 点评 · 从仿真到真机,优必选展示具身智能落地全链路,行业价值关键在量产验证。
直击WRC
AI 点评 · 陆行具身系统突破轮、足、车多形态融合,或成机器人移动技术新标杆。
让具身智能技术真正落地千行万业。
AI 点评 · 具身智能落地路径首次被系统拆解,产业协同模式或成行业新标杆。
机器人换了身体,智能还能留下多少?

Waymo built its own chip for its robotaxis, cutting its reliance on Nvidia. The article Waymo builds its own chip for its robotaxis, cutting its reliance on Nvidia appeared first o…
明略科技(2718.HK)与海康机器人联合参展2026WRC,聚焦商业服务领域展示具身智能落地进展。
比会做一个动作更难的,是把一整件事连续做完。
We present PhysCaP, a Physics-Informed Code-as-Policy agent for active perception in robotic manipulation. While vision-language-action policies excel at imitating demonstrations, they rely on passive…

Robotics startup Generalist AI has unveiled GEN-1.5, an AI model that teaches robots new tasks from a single demonstration. The article GEN-1.5: Generalist AI teaches robots new ta…
Unitree Robotics rose 460 percent in its Shanghai IPO, hitting a valuation of around $50 billion. But an FT report shows much of the demand for its robots comes from state-backed t…
一个打通链路的优秀的通用技术底座
Multifingered grasping is a crucial robotic skill, but current deep-learning grasp planners often struggle to generalize to new objects because they are trained on limited, object-specific datasets. W…
How to efficiently finetune robot policies to learn new tasks on the fly? State of the art robotic manipulation policies are based on behaviour cloning of large vision-language-action (VLA) models wit…

During a recent visit to Generalist AI, I watched a robotic arm improvise and use a banana as a tool.
AI 点评 · 实时学习能力是AI从工具到伙伴的关键跨越,现场即兴创新更显真章。

IT之家 8 月 19 日消息,小米官方今日宣布, 小米新一代人形机器人亮相 2026 世界机器人博览会 ,登陆「具身花园」展台。 IT之家注意到,小米官方刚刚放出小米新一代人形机器人与观众实时互动的视频。据介绍,从递花、握手到碰拳、比心,这些看似简单的动作背后, 由大模型驱动机器人自主理解、判断并完成动作 。 根据规划,8 月 20 日起,展台将对普通观众…
超维动力KAI全栈具身智能硬核登场
构建全栈物理AI基础设施
SDK for robotics teams to verify the quality of their data used for AI model training.
We introduce Hydra-0, a generalist world model conditioned on action flow, which represents robot actions as pixel motion. This shared visual interface enables generalist world modeling and control by…
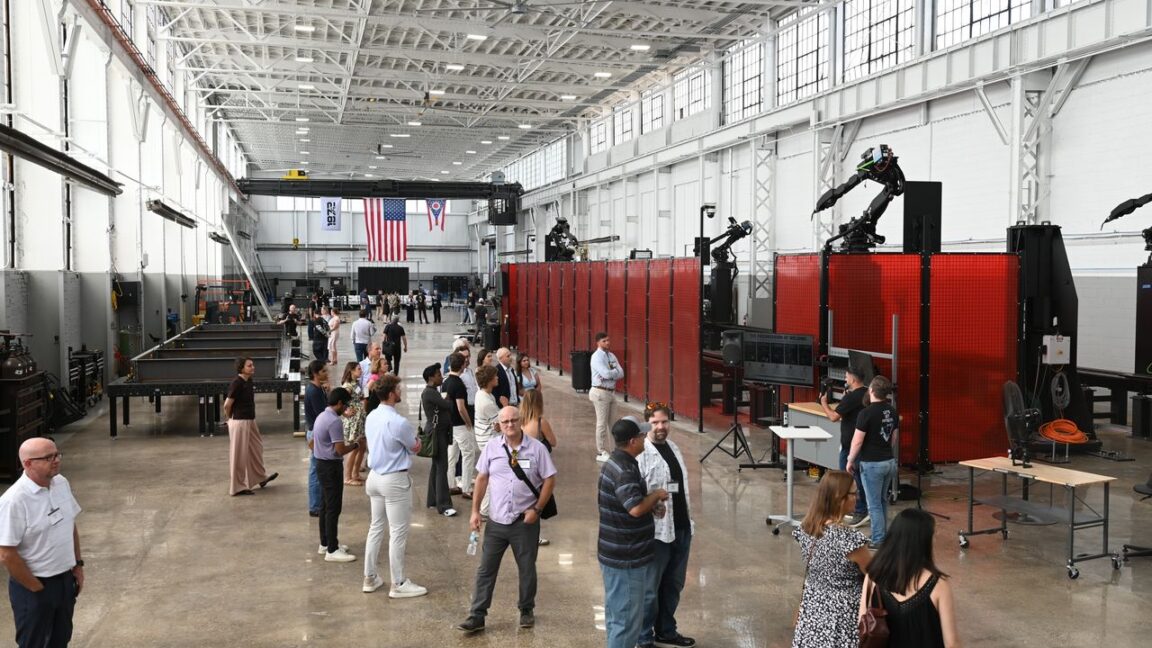
“We're not necessarily building in a dogmatic fashion towards full autonomy.”
AI 点评 · 机器人工厂切入钢铁制造,前SpaceX工程师带来降本增效新思路。
Although Large Vision-Language Models (VLMs) have significantly advanced embodied navigation, their direct deployment remains challenging, as existing methods often force VLMs into unnatural action sp…
Long-horizon robot manipulation chains many contact-rich skills into one multi-stage task. Vision-language-action (VLA) models increasingly master the individual skills, yet the chain still fails: err…
Humanoid robots hold great promise as general-purpose agents in human-centered environments, yet generalist vision-language-action (VLA) foundation models are not readily applicable to humanoid whole-…
The greatest invention in pet tech in recent years is the litter robot. A machine that scoops your kitties' poop so you don't have to - what else could a cat owner possibly want? H…
8月17日,具身智能初创公司共生知行发布双足人形机器人驾驶卡丁车Demo

When Xander first met Moxie, she taught him that when he was anxious, he could calm down by exhaling through his lips so that he buzzed like a bee. They practiced breathing like dr…
Embodied agents are increasingly used to close the gap left by end-to-end policy models. Yet the agentic path has not realized closed-loop learning in physical execution: existing harnesses remain lar…
Long-horizon robot manipulation requires a robot to both execute individual skills reliably and sequence them coherently over extended tasks. Most hierarchical vision-language-action (VLA) models make…
Multimodal large language models increasingly use visual chain-of-thought (Visual CoT) to reason about spatial, temporal, and embodied environments. By generating intermediate reasoning images, Visual…
Vision-language-action (VLA) models have become a dominant paradigm for generalist embodied agents, demonstrating strong complex and long-horizon task completion in structured settings. Yet it remains…
World Labs, the startup founded by AI pioneer Fei-Fei Li, has unveiled a simulation engine that trains robot controllers entirely in virtual environments. From a single real-world…
AI 点评 · 用模拟生成海量训练变体,突破真实数据瓶颈,让机器人训练更高效灵活。

The Unitree G1 has found online fame as a relatively affordable robot that can charm a crowd. But can it ever hold down a real job?
AI 点评 · 四足机器人G1凭亲民价格走红网络,但能否胜任实际工作成关键看点。
Vision-language models (VLMs) enable embodied agents to reason and act from visual observations and language instructions. Reinforcement learning (RL) post-training enhances these capabilities using t…
As heterogeneous robotic systems deploy across diverse urban zones, maintaining safety amid complex human-robot interactions remains a critical challenge. We present a unified framework that bridges s…
An autonomous robot efficiently exploring an unknown environment, such as looking for water sources on Mars, faces two simultaneous demands: building an accurate information map while quickly finding…
Fine-grained robotic evaluation matters for understanding embodied models, going beyond binary success rates and rule-based process scores. We present PRM-as-a-Judge 1.5, a toolkit for robot process a…
AI 点评 · 一站式打通机器人开发全链路,降低门槛,值得开发者关注。
重新定义物理AI数据基础设施

Dyna Robotics has released Dyna-2, a world-action model pre-trained on more than one million hours of egocentric human video. The technical report establishes three results: a scal…
影石发布 Insta360 X6、SpaceXAI 推出 Grok Bot 等。 查看全文
Large-scale manipulation data is essential for robot learning, yet collecting robot demonstrations remains expensive and difficult to scale. Meanwhile, abundant egocentric human manipulation videos pr…
We present DreamX-Phi 1.0, an action-conditioned video world model for robotic manipulation that, given an observed frame, a language instruction, and a prescribed action sequence comprising end-effec…
Spatial intelligence is becoming a foundation for embodied agents, robotic planning, and multimodal assistants. To improve the spatial reasoning ability of VLM agents, existing work has mainly followe…
Aerial vision-language navigation (VLN) requires an embodied agent to integrate visual evidence over time, plan future actions, and determine when it has reached a navigation goal under partial observ…

IT之家 8 月 12 日消息,在今晚的荣耀 Robot Phone 全球新品发布会上, 全球首款机器人手机 —— 荣耀 Robot Phone 正式发布 , 定价 9999 元起 。 天马微电子宣布, 为本款机型独家供应屏幕,深度定制天马天工屏高端 OLED 显示方案 。天马表示,这是天工屏首次应用于具备具身交互能力的 AI 终端,适配机器人手机的创作、随…
具身模型一小时狂拣1816件异形包裹
从柔性本体走向跨本体基础智能,让任务与世界知识延续
Hand Pose Estimation (HPE) is a fundamental technology for various applications such as AR/VR and robotics. In these applications, the visibility of each hand joint in the image is crucial for assessi…
Learning reliable surgical manipulation policies is bottlenecked by the scarcity of action-labeled demonstrations: teleoperated surgical robot (e.g., dVRK) trajectories with synchronized kinematics ar…
资本正从具身本体集体涌向触觉
After an older adult misses a medication dose, a software agent can send another reminder and an embodied agent can bring the medication. Yet neither explains whether the person forgot, is confused, h…
Omni-modal dialogue models can understand multimodal inputs and synthesize spoken replies, yet their responses remain visually disembodied. We introduce Ex-Omni-2D, an omni-modal dialogue framework th…
Embodied agents are increasingly built as systems around foundation models, where performance depends not only on model weights but also on the skills, context, action interfaces, and execution harnes…
Test-time scaling often uses an external verifier, such as compilers and test cases in coding or trained value functions in robotics applications, to obtain high-quality rollouts. Verifier-free test-t…
Physically consistent motion planning remains a fundamental challenge in embodied AI, as generated trajectories must strictly conform to real-world execution dynamics. While latent world models offer…
Hey HN, Henry from Cactus here! We previously released Cactus Needle, a 14MB agentic LLM for tool call, device use, and structured extraction for phones, wearables, smart homes, sm…
AI 点评 · 14MB级端侧智能体,开启手机手表家居机器人的本地AI新纪元。
Advances in advanced artificial intelligence tools have sparked research in robot autonomy, but the development of such systems has largely focused on execution rather than verifying the feasibility a…
“我们90天就成了独角兽”
The development of embodied Intelligent Virtual Agents (IVAs) that have cognitive capabilities in real-time interactive virtual environments remains a challenge, even with today's advancements in tech…
General-purpose reward models are increasingly the bottleneck for scaling robot learning, yet the recipe for learning value-related capabilities from large-scale heterogeneous corpora remains underexp…
We present 360CityArena, a benchmark for evaluating the urban exploration capabilities of embodied agents within a photorealistic environment constructed from 360-degree videos. Existing outdoor bench…
采集、仿真、训练和评测,闭环了
AI 点评 · 数据闭环打通,国产具身智能冲刺百万小时里程碑。
Vision-language models are increasingly serving as the reasoning core of embodied agents. Robot execution is inherently iterative: each action reshapes the scene and physical state, continually renewi…
While Vision-Language-Action (VLA) models have advanced embodied AI, their fundamentally reactive paradigm severely limits performance in partially observable and long-horizon tasks. When restricted t…
这套中国原创理论,为具身智能开出了新路。
Spatial intelligence is fundamental to embodied agents, yet existing benchmarks focus on local spatial perception from single or few viewpoints, overlooking global spatial awareness over continuous, l…
Vision-Language-Action (VLA) models have become a powerful paradigm for robot manipulation, but training a single generalist policy for heterogeneous robot embodiments remains an open problem. Existin…
World generative models are typically used through what they produce: a rendered future, a video-conditioned action, or latent context computed by a costly generative branch. We argue that their more…
On our new Real World AI stage, we’ll be focusing on the intersection between the digital and physical, and all the ways we’ll continue to see a blending of the two.
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commerci…
Leveraging pre-trained vision-language models (VLMs) to construct vision-language-action (VLA) models has emerged as a promising paradigm for 3D robot manipulation. However, existing 3D VLA methods re…
Vision-language-action (VLA) models often treat main-view and wrist-view observations as parallel visual inputs, overlooking their distinct roles in robot manipulation. Fine-grained manipulation, howe…
Understanding 3D scenes is fundamental to embodied intelligence, requiring joint reasoning over heterogeneous information from multiple modalities, including visual and geometric cues. However, the re…
An analysis of the last seven years of Tesla earnings calls shows just how little attention Musk pays to Tesla's car business.

Ati Robotics assembles its robots in India and uses just a few Chinese parts—a strategy that could pay off as the Trump administration cracks down on Chinese humanoids.
Flow-matching vision-language-action (VLA) models such as pi0 generate robot actions by integrating a learned denoising velocity field, and have been reported to resist adversarial perturbations that…
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. Humanoid robots usually elicit more cringe…
AI 点评 · 美国AI保护主义蔓延至机器人领域,或重塑全球产业格局。
AI 点评 · 家庭场景海量数据开源,为机器人“读现实”提供关键教材,具身智能落地提速。
World Action Models (WAMs) augment robot policies with action-conditioned predicted futures, but a plausible future alone does not justify changing the action that a bimanual policy would execute. We…
Learning generalizable robot manipulation policies requires large-scale and diverse demonstration data. Egocentric human manipulation videos offer rich scene and task diversity, and prior work has sho…
Robot learning is splitting into two bets: policies that bake competence into frozen weights (vision-language-action, or VLA, models), and agents that write and refine their own executable skills as c…
Selecting a complete 3D object from a reconstructed scene with minimal user effort is essential for practical scene editing and embodied interaction. Existing 3DGS-based methods either retrain the Gau…

IT之家 8 月 1 日消息,7 月 31 日,国际数据公司(IDC)数据显示,2025 年中国工业具身智能机器人市场规模约为 57.4 亿元 ,其中以工业机器人为载体的具身智能应用市场规模约 36.2 亿元,成为当前产业商业化落地的主要方向。随着产业竞争从机器人本体性能逐步转向模型、数据、工程化和场景落地能力的综合竞争,工业具身智能机器人正在成为智能制造发…
AI 点评 · 工业具身智能首破57亿,赛道从硬件比拼转向数据与场景落地。
具身智能的τ(bushi)
AI 点评 · 具身智能商业化落地,机器人保洁定价对标人工,性价比成关键看点。
Viscous stains, characterized by high viscosity and complex rheological properties, remain a major challenge for robotic surface cleaning. Conventional wiping often spreads the stain, while scrubbing…
Imitation learning (IL)---training an agent to replicate expert behavior from demonstrations---underpins applications from robotics to language model training. Standard approaches such as Behavior Clo…
Reinforcement learning (RL) post-training of Vision-Language-Action (VLA) models has shown strong promise for robotic manipulation. Among RL methods, critic-based approaches rely on a value estimator…
Reinforcement learning (RL) post-training of Vision-Language-Action (VLA) models has shown strong promise for robotic manipulation. Among RL methods, critic-based approaches rely on a value estimator…
World Action Models (WAMs) have emerged as a promising paradigm by jointly modeling robot actions and future visual dynamics. However, their reliance on pixel-generative future supervision can entangl…
Can every robot in a swarm predict the same future collective state from only local observations and bandwidth-limited messages? We formulate this as decentralized shared-state prediction and introduc…

Reimagining Independence: How Meta’s AI Models Are Helping the University of Pittsburgh Transform Assistive Robotics AI at Meta
Kandinsky WM 1.0 — a family of models for Physical AI. Image-to-video generation for autonomous driving, robotics & general physics.


