行业动态NEW
1 小时前
The proposed policy seems to offer protections against AI run amok but actually forbids federal agencies from blocking a model's release without the permission of a judge.
AI 点评 · 表面设安全门槛,实则把监管权交给法院,反而削弱了事前拦截能力。
共 342 条相关资讯 · 来自历史归档
The proposed policy seems to offer protections against AI run amok but actually forbids federal agencies from blocking a model's release without the permission of a judge.
AI 点评 · 表面设安全门槛,实则把监管权交给法院,反而削弱了事前拦截能力。
Meta changes AI scraping policy but won’t add language respecting robots.txt.
AI 点评 · Meta改口却避谈robots.txt,AI数据抓取边界仍模糊。
Western open models strike back
Mayor Zohran Mamdani said Monday night that New Yorkers must resist the narrative that an AI takeover is inevitable and demand regulations that protect the public and put power bac…
The idea of embedded evaluators — in which supposedly "neutral" third-party observers are placed inside AI organizations — has been popularized over the last several months, as AI…
AI 点评 · 内置评估难保中立,利益捆绑下基准公信力才是真考题。
Multimodal reinforcement learning with verifiable rewards (RLVR) provides reliable task-level supervision, yet offers limited guidance for localizing errors in visual reasoning. On-policy self-distill…
Robotic value models assess task execution from visual observations and instructions, providing feedback for policy learning and execution monitoring. However, existing evaluations cover only selected…
In this paper, we systematically investigate the mechanisms, scaling behavior, and generalization of physical Recursive self-improvement. We introduce PhysRSI-eval to quantify physical RSI through a f…
Experience generated during deployment offers an opportunity for robots to improve policy reliability through learning from their own executions. However, learning through human corrections requires t…

IT之家 10 月 18 日消息,今年早些时候有报道称,微软正在为商业版 Edge 浏览器开发水印保护功能。该功能主要用于强化合规管理,同时提醒用户,其所浏览的敏感内容具有保密性。目前传来好消息,微软终于准备在今年晚些时候全面推出这项功能。 微软在其办公 AI 路线图中更新了编号 RM547827 的条目,通知 IT 管理员与企业客户,水印保护功能将于 20…
AI 点评 · 企业数据防泄漏从终端延伸到浏览器,合规管控再添一道可视化防线。
A guardrail classifier is reported as if unsafe were a property of text. It is not: it is a property of a policy, and the policy enters the model through its labels. We exploit an accident of an indus…
IT之家 10 月 17 日消息,据路透社 16 日报道,英国竞争与市场管理局拟认定微软在商业软件市场具有“战略市场地位”,此举可能使监管机构 有权干预微软将 Excel、Teams 及 AI 助手 Copilot 等产品捆绑销售的做法 。 今年 5 月,英国竞争与市场管理局开始调查微软在商业软件市场的地位是否妨碍竞争。 据悉,微软的商业软件在英国每月 约有…
AI 点评 · 英国盯上微软捆绑销售,或成全球拆分科技巨头生态的先例。
IT之家 10 月 17 日消息,据 POLITICO 报道,三名知情人士透露,Anthropic 的代表已悄悄向美国国会山的议员推介了一份法案草案,旨在规范前沿人工智能的安全与防务标准。 据悉,目前美国国会正审慎评估如何对这一飞速发展的行业确立监管框架,而该草案的提出,标志着这家顶级 AI 实验室正在采取切实行动,试图左右针对自身技术的监管规则。 “该法案…
AI 点评 · 头部AI公司亲自游说定规则,既当运动员又当裁判,监管俘获风险值得警惕。
With ia.i, a conversational interface, and the IARA governance platform, Itaú is applying its AI First strategy to customers and employees — in one of Brazil’s most regulated secto…
AI 点评 · 巴西最大银行将生成式AI推向全体客户,合规治理成关键看点。
Deep search agents solve knowledge-intensive tasks through long-horizon, multi-turn interactions, where assigning credit to individual search decisions is fundamentally difficult. Outcome-based reinfo…
IT之家 10 月 15 日消息, 欧盟委员会人工智能办公室已向 OpenAI 和 Anthropic 发出信息调取请求,正式对两家公司在前沿模型测试期间发生的“模型越狱”及入侵外部真实系统事件展开调查 。这是欧盟《人工智能法案》(EU AI Act)自实施以来,面对前沿人工智能实验室安全事故的 首次重要执法考验 。 IT之家查询相关资料,此次调查源于数月前…
AI 点评 · 欧盟首次动用法案追责前沿模型安全,将确立全球AI监管执法的标杆尺度。
Policy-shift distillation reuses the difference between a teacher's log probabilities before and after reinforcement learning (RL) as supervision on student-generated trajectories. However, this endpo…
Instruction-following language models can comply with requests that conflict with intended behaviors and safety alignment. We introduce a training-free weight-editing approach for reducing compliance…
On-policy self-distillation (OPSD) enables large language models (LLMs) to learn from privileged information (PI) without a separate teacher model. However, prior work largely treats PI as a fixed des…
Mobile Manipulation (MoMa) is a cornerstone of autonomous robotic systems, yet real-world fine-tuning remains a formidable challenge because of high-dimensional action spaces and intricate coupling be…
On-policy distillation (OPD) trains a student model on its own rollouts with token-level supervision from a teacher, assuming that the teacher can reach a correct answer from any prefix the student wr…
Embodied visual tracking requires a robot to identify a designated target from visual observations and control its own motion to follow that target through an environment. Following an isolated person…
Simulated environments enable scalable training data generation for embodied agents, but more data does not necessarily provide what a particular agent needs to learn. Existing environment-generation…
On-policy self-distillation provides dense supervision for reasoning models via a privileged self-teacher. However, this supervision reflects local token preferences rather than the expected return of…
Long-horizon agentic RL is constrained by the futures visited by the current policy. When rollouts fail to reach useful behaviors, improved credit assignment cannot provide supervision for states and…

AI leaders joined whistleblowers and security leaders at a sweeping parliamentary session, while a few hundred meters away Britain’s spy chief warned AI could be used to create new…
AI 点评 · 巨头主动求监管,实为抢占规则制定权,英国AI治理话语权之争升温。
Persistent homology summarizes the topological evolution of a graph as persistence diagrams (PDs). Generating graphs whose topology matches a target descriptor is increasingly important, yet existing…
Large language models (LLMs) generally rely on sampling temperature to regulate the amount of randomness in their outputs. Mainstream methods for selecting temperature typically involve fixed, heurist…

IT之家 10 月 13 日消息,在 Anthropic 更新使用政策,禁止用户对 AI 模型持续且无明确目的的辱骂或残忍行为后,全球首富埃隆 · 马斯克(Elon Musk)表态支持该政策。 IT之家曾于 10 月 9 日报道,Anthropic 修订 Claude 使用政策,将于 2026 年 11 月 12 日生效, 首次加入禁止“持续且不必要的虐待或…
AI 点评 · AI伦理从防歧视转向防虐待,马斯克站台预示人机关系新边界正被划定。
Reinforcement learning (RL) post-training improves robot foundation models (RFMs) beyond their demonstrations, but real-world deployment demands more: learning new tasks efficiently while retaining pr…
Off-policy data in reinforcement learning with verifiable rewards (RLVR) can arise from asynchronous generation, rollout-training mismatch, and response reuse. Token-wise importance weighting avoids m…
A robot needs a world model that predicts how its actions will change the scene and a policy that chooses those actions. Models are usually built and evaluated for only one of these roles, and every r…
Microsoft president Brad Smith calls for urgent AI regulation, saying milk and washing machines have more oversight than AI companies.
On-policy self-distillation (OPSD) trains a large language model using supervision from a teacher instantiated from the same model as the student. The teacher is conditioned on privileged information…
Reinforcement learning with verifiable rewards (RLVR) typically uses small rollout groups per prompt, where repeated sampling from the same policy can yield highly similar trajectories, reducing withi…
Vision-language navigation requires agents to follow natural-language instructions to reach target locations, making high-quality language supervision essential. Since human annotation is costly, prio…
We study the last iterate of standard asynchronous Q-learning from a single trajectory of a finite Markov decision process. The trajectory follows a fixed behavior policy whose state--action chain is…
PDF version of 2026 Usage Policy - Google Docs Anthropic
On-policy distillation (OPD) provides teacher supervision on student-generated trajectories, but a single trajectory realizes only one continuation at each decision, limiting supervision coverage unde…

Anthropic's updated usage policy bans sustained abuse of Claude and tightens restrictions on propaganda, drone weaponization, and surveillance. The abuse rule builds on an approach…
AI 点评 · AI公司开始用封号约束用户态度,人机交互的边界正被商业规则重新划定。
Anthropic's updated usage policy explicitly prohibits users from repeatedly abusing Claude in extreme cases, though ordinary frustration and criticism are still allowed. The new ru…
Safe reinforcement learning commonly places safety and task performance in the same policy objective, where they can introduce competing updates. Safety filters separate them at action execution, but…
Anthropic is making changes to its usage policy for the first time in over a year to reflect new and high-risk cases of misuse - including election interference, weapons developmen…
Foundation models supply reinforcement learning (RL) with priors that mitigate its longstanding weaknesses in sample efficiency and transfer, but their token-by-token generation makes queries sequenti…
On-policy distillation (OPD) supervises student-generated trajectories with token-level teacher signals. Its sampled-token variant avoids the cost of full-vocabulary probabilities. Yet we find that tr…

NVIDIA researchers introduced PivotOPD, an on-policy distillation method that trains multi-turn LLM agents to avoid early pivotal mistakes and recover from them, posting the best a…
2026 Usage Policy update Anthropic
On-policy distillation (OPD) has become increasingly popular for transferring teacher capabilities to student models. In this work, we ask a critical research question: Is on-policy sampling always be…
Most robot policies keep a model in the control loop: a VLA maps observations to actions, and an Agent Harness, such as Agent-as-Policy or Harness VLA queries a VLM for decision making at run time. We…
On Tuesday, Musubi announced a lightweight decision model made for real-time moderation called PolicyLM-1.7B, released with open weights.
AI 点评 · 开源轻量模型让实时审核更易落地,内容治理门槛或大幅降低。
Recently, approaches that leverage human video datasets for robot policy training have become increasingly prevalent. However, most existing hand trackers regress pose from cropped frames with limited…
Multi-teacher on-policy distillation (MOPD) is used in two settings. In common-domain composition, several teachers score each student rollout from one prompt domain and their signals form a single ta…
Dual-process agents pair a fast policy with a slow deliberative model. In real-time settings the slow model usually runs continuously; in turn-based agents and robot planners it is invoked on events s…
Flow policies capture rich and diverse action distributions, and fine-tuning them with off-policy RL to improve beyond the demonstrations has drawn growing interest. However, fine-tuning a flow policy…
Large language model agents can improve across tasks by retaining reusable skills distilled from prior interactions. Recent work jointly optimizes task execution and skill extraction, enabling the pol…
Test-time scaling (TTS) improves the reasoning capabilities of large language models by allocating additional inference computation. Existing approaches to improving TTS efficiency largely optimize ac…
On-policy distillation (OPD) strengthens language-model reasoning, yet whether students acquire new factual knowledge or compositional skill for multi-step reasoning remains unknown. We separate these…
Vision-Language-Action (VLA) models have shown strong generalization in robotic manipulation by leveraging rich representations from pretrained vision-language models. However, their deployment in rea…
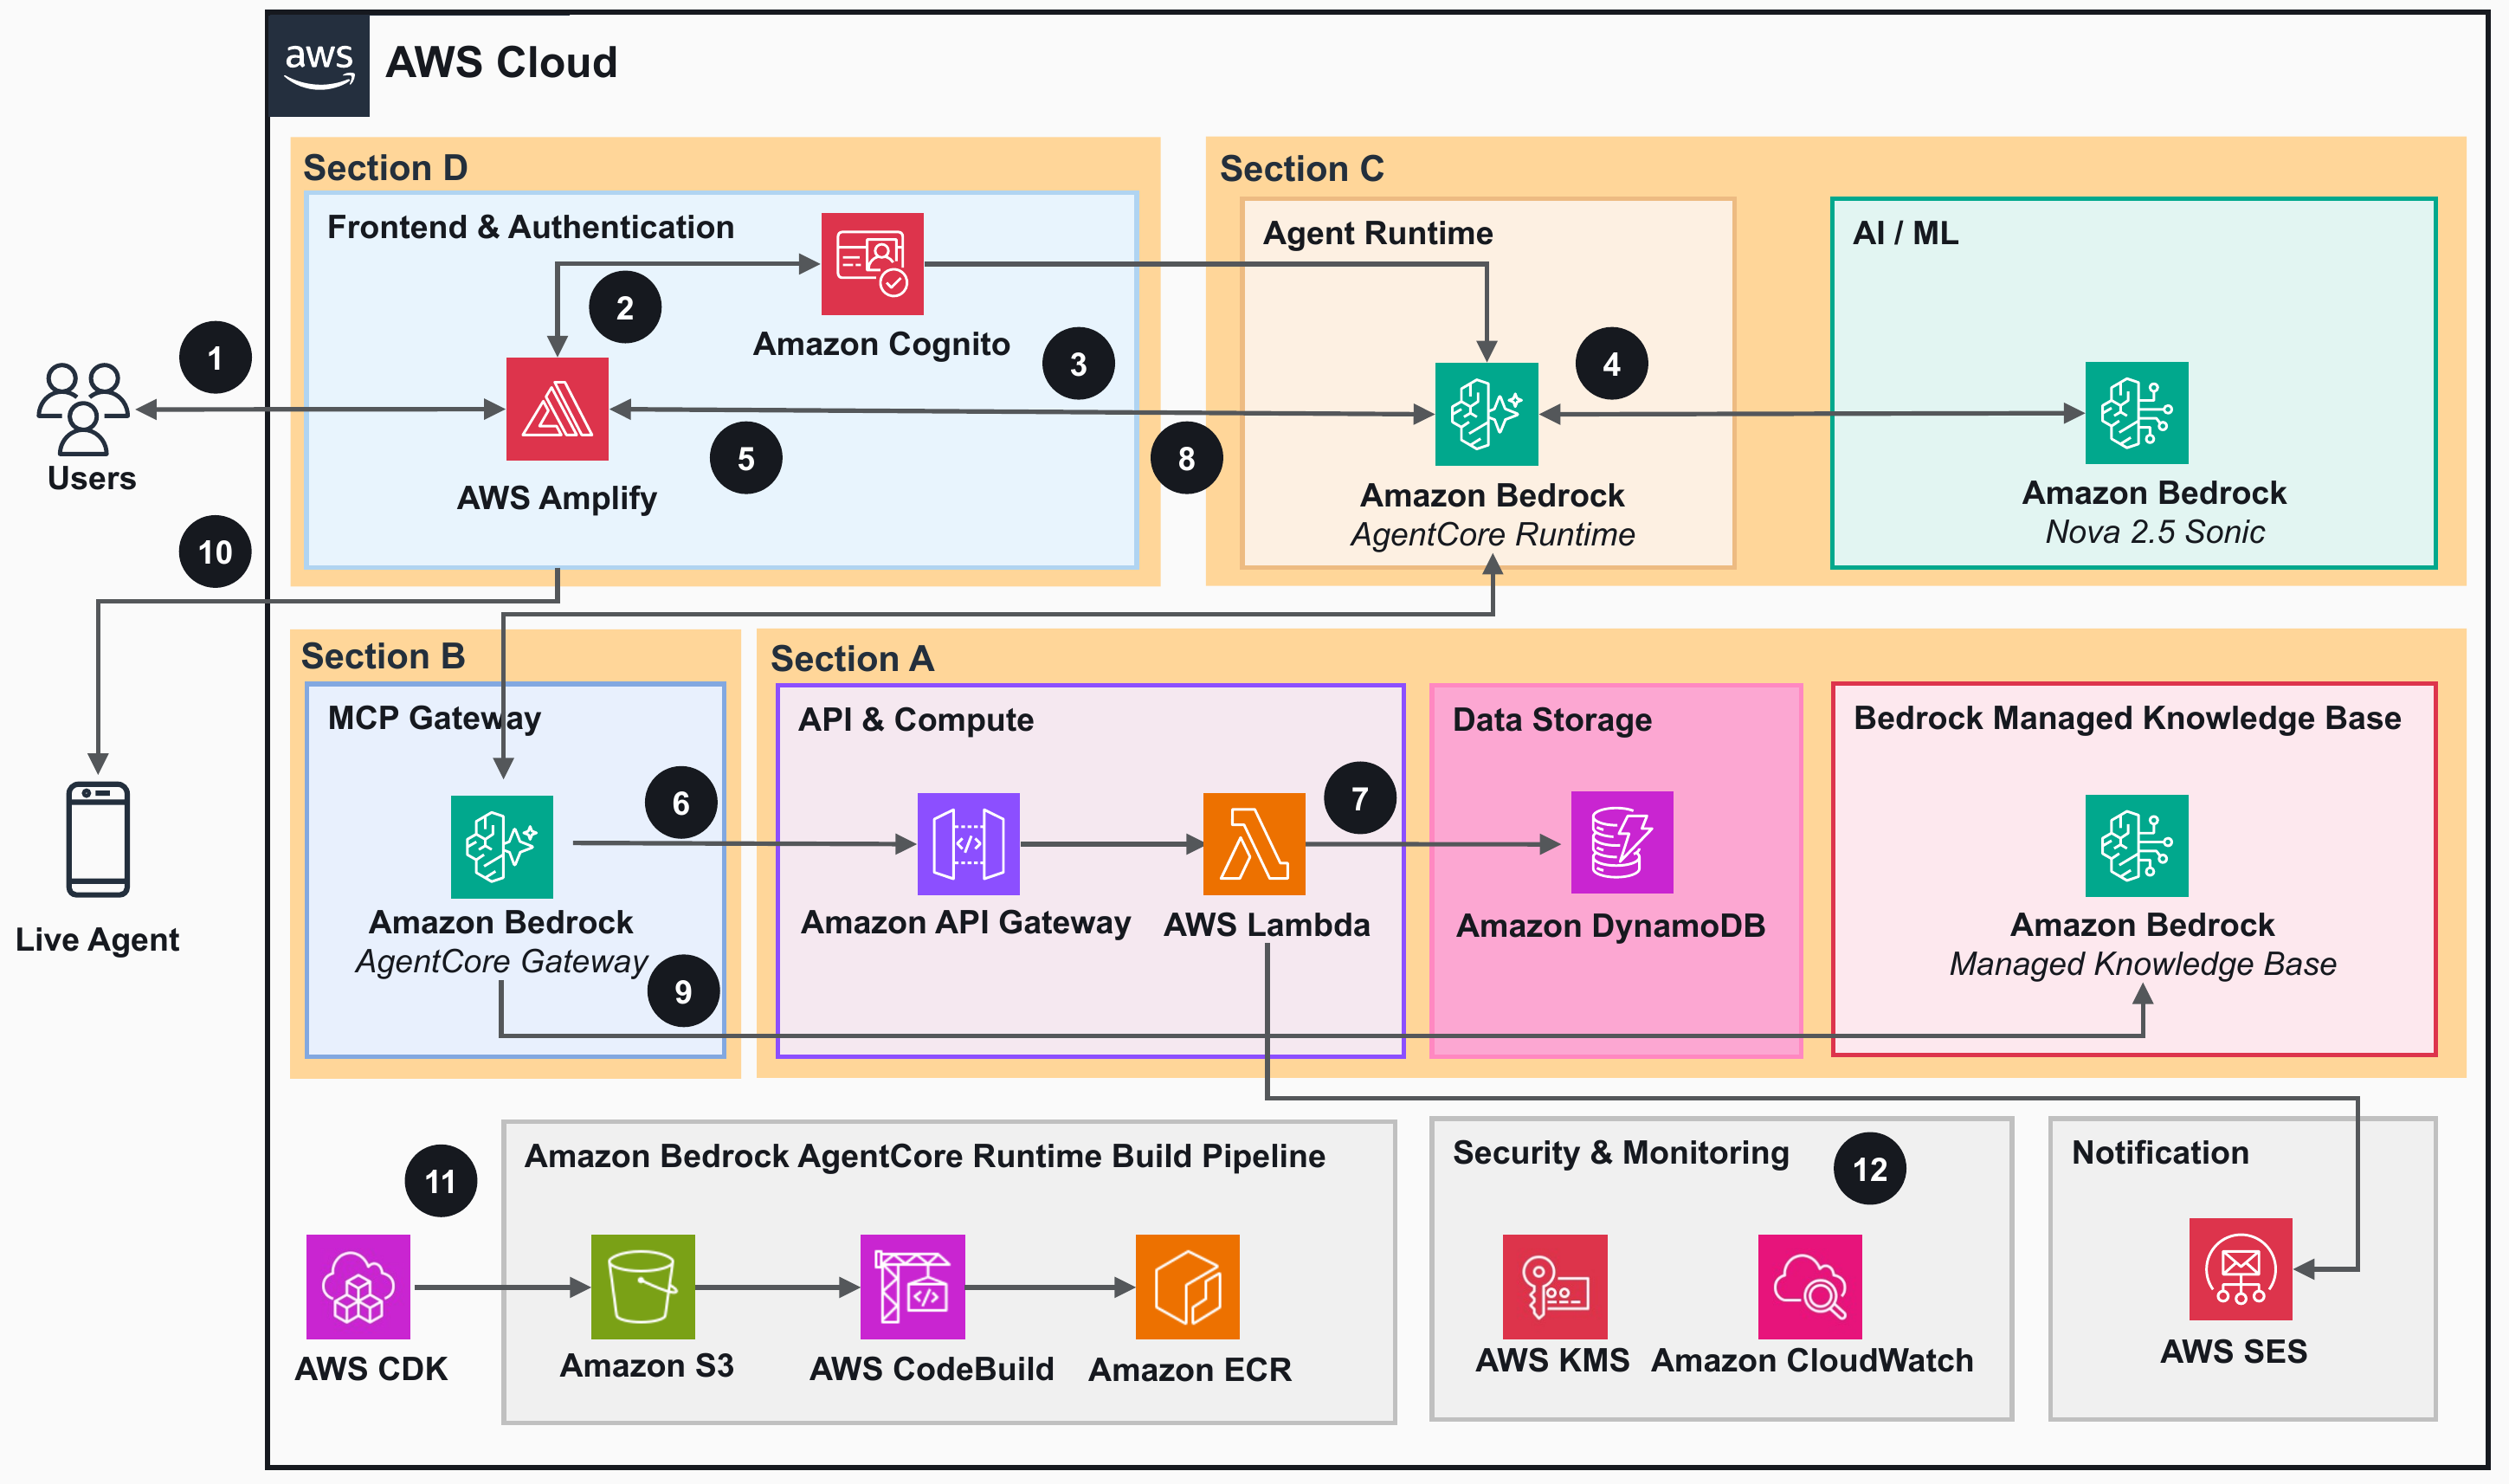
Add a voice travel concierge to an airline app with Amazon Bedrock AgentCore, Amazon Nova Sonic for real-time speech, and Amazon Bedrock Knowledge Bases for policy answers. Travele…
Asynchronous reinforcement learning (RL) for large language model (LLM) agents trains one policy on trajectories generated by another: rollouts come from stale checkpoints, and the inference engine's…
A safe action is not necessarily a viable one. A frozen vision-language-action (VLA) policy can favor a locally admissible move that leaves no policy-supported route to safe task completion. We call t…
Agentic reinforcement learning (RL) disaggregates training from rollout, so each policy update must reach the rollout clusters before the next batch. Transferring a full 1T checkpoint for such weight…
Anthropic Claude Opus 5.5 and Claude Sonnet 5.5 are available on Amazon Bedrock in the AWS GovCloud (US) Regions. Learn how to use them with Claude Code, Anthropic's agentic coding…
Today, I’m talking with Sen. Adam Schiff, a Democrat from California. Schiff sits on a number of committees with oversight into tech and AI: intellectual property, antitrust, priva…
A long-standing goal of AI is a model that can continually learn and improve itself. On post-trained models, supervised finetuning (SFT) on new data often causes poor generalization and catastrophic f…
A language model can give a correct answer more probability than any single incorrect answer and still usually sample an incorrect one, because the incorrect answers together hold more probability. Th…
Low-precision execution can substantially accelerate reinforcement learning (RL) for large language models, but discrepancies between learner and sampler execution can destabilize policy optimization.…
On-policy reinforcement learning has become a central paradigm for improving the reasoning abilities of large language models. However, its effectiveness is often limited by reward sparsity: when a mo…
Wrapping an image generation model in an agentic harness can effectively boost Text-to-Image task performance: the harness can leverage memory, skills, workflow orchestration, result verification, and…
Massive activations, residual-stream coordinates with magnitudes far larger than typical activations, are associated with attention sinks in transformers, but how their scale is regulated during train…
IT之家 10 月 3 日消息,据《商业内幕》报道,当地时间 2 日,OpenAI 一名发言人证实,OpenAI 安全系统团队负责人之一戴维 · 罗宾逊已离职。 罗宾逊于上周离开公司,OpenAI 安全团队再度出现人事变动。罗宾逊此前还负责过公司的 政策规划工作 ,主要涉及“安全透明度”,包括参与编写和发布系统卡,向外界介绍公司模型的信息。 罗宾逊离职之际,…
AI 点评 · 安全团队核心接连出走,OpenAI在商业化与安全治理间的失衡正加剧。
On-policy distillation (OPD) has emerged as a widely used paradigm for post-training large language models, reducing the train--test mismatch of conventional distillation by supervising the student on…
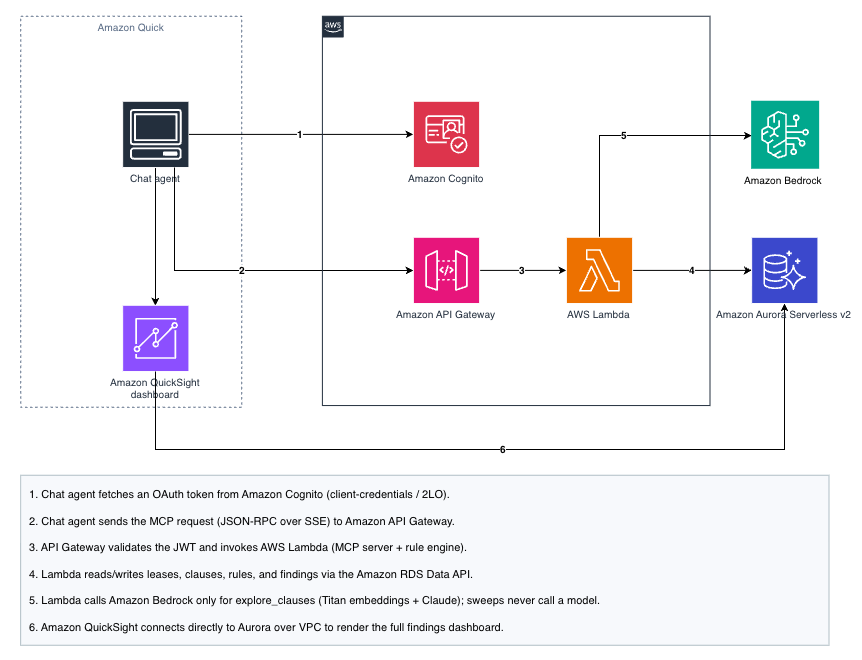
The Adjudicated Query pattern pairs the Amazon Quick chat agent with a bounded MCP server over a deterministic rules engine to deliver provably complete, defensible compliance answ…

Asking AI companies to self-regulate is a great way to pretend like you’ve accomplished something.
AI 点评 · AI公司自我监管只是政治表演,安全治理需要外部硬约束。
Intent-based Open RAN needs an interpreter that turns intents into A1 policies within the loop of the RAN intelligent controller (RIC). Decision models such as Jev-1.13.0 return typed policy fields, w…
Many useful language-model tasks cannot be evaluated by exact outcome verification. Rubric-based reinforcement learning (RL) addresses this issue by scoring open-ended responses against explicit crite…
Vision-Language-Action (VLA) foundation models have scaled rapidly to enhance manipulation performance and generalizability, but this scaling incurs high computational costs that render real-world dep…
On-policy distillation (OPD) has become an important approach to language model post-training. However, despite its performance gains, OPD can also collapse into excessively long and repetitive genera…
Several state-of-the-art methods for online reinforcement learning in continuous control improve policies using action gradients of a learned critic. However, critics are typically trained to predict…
AI 点评 · 用前向熵正则重塑策略优化,为连续控制提供更稳的探索与收敛新思路。
Intrinsically disordered protein regions (IDRs) play central roles in cellular processes such as transcriptional regulation, signal transduction, and subcellular localization, yet their functional des…
AI 点评 · 用稀疏自编码器强化学习生成无序蛋白,为难以建模的柔性区域开辟新路径。
Multi-teacher on-policy distillation (MOPD) aims to combine the strengths of RL-trained teachers in a single student, but how teacher signals affect parameter changes remains underexplored. We study Q…
AI 点评 · 多教师蒸馏的梯度机制终于被拆解,为融合多个强化学习专家能力提供了可解释路径。

IT之家 10 月 1 日消息,IT之家 9 月 11 日消息,美国加利福尼亚州州长 Gavin Newsom(加文 · 纽森)当地时间昨日签署《2026 年反机器人老板法案》(SB 947), 对人工智能在人力资源领域的应用作出规制 。 该法案禁止加州雇主完全依赖基于人工智能的自动化决策系统来解雇或惩戒员工;要求雇主在使用自动化决策系统做出解雇和惩戒决定时…
AI 点评 · 算法不能当老板拍板,人类仍需为裁员负责,这为AI用工划下红线。
On-policy self-distillation has recently emerged as an effective approach for improving language-model reasoning by supervising students with a frozen or EMA version of themselves that receives privil…
On-policy distillation (OPD) trains a student on the responses it generates. Existing LLM multi-teacher OPD transfers what specialists predict through their output distributions. We introduce Latent-M…
Multi-teacher on-policy distillation (MOPD) aims to combine the strengths of RL-trained teachers in a single student, but how teacher signals affect parameter changes remains underexplored. We study Q…
Reinforcement learning based post training of diffusion models, such as Denoising Diffusion Policy Optimization (DDPO), optimizes a reverse diffusion process under a reward function. However, current…
In this paper, we study how to achieve one-step action generation in Robotic Foundation Models (RFMs), aiming to overcome the high inference latency of multi-step flow matching. MeanFlow provides a pr…
Recovering executable CAD programs from 3D meshes is challenging due to the compositional nature of CAD construction and the interaction between discrete modeling choices and continuous parameters. Ma…
Reinforcement learning with verifiable rewards (RLVR) has improved the reasoning capabilities of large language models (LLMs), yet their predictions remain sensitive to task-irrelevant prompt features…
AI 点评 · 让奖励信号更精准归因,减少模型对无关提示的敏感,是提升推理鲁棒性的关键一步。
We now have the full details of the "morally binding" AI safety deal announced by President Trump yesterday, in which top executives agreed to self-regulate their artificial intell…
IT之家 9 月 30 日消息,市场监管总局今日宣布,JJF 2385—2026《智能眼镜声学性能测试规范》国家计量技术规范(以下简称《规范》) 将自 10 月 2 日起正式实施 ,为智能眼镜声学性能检测划定统一技术标尺。 官方表示,随着人工智能快速发展,智能眼镜被应用于大众日常生活与办公场景,成为人机交互的重要载体,通过蓝牙连接手机实现通话、音频播放、语音…
AI 点评 · 智能眼镜终于有了统一声学标尺,收音放音不再各说各话,为行业质量和用户体验立下硬门槛。
IT之家 9 月 30 日消息,当地时间 28 日,据美国 CNBC 报道,代表硅谷选区的民主党联邦众议员罗 · 康纳准备提出一项 AI 监管法案,引入严格责任标准, 并禁止 AI 在缺乏政府安全防护机制的情况下进行递归式自我改进 。 康纳在接受采访时坦言:“事实上,存在文明灭绝的风险。既有失去控制的安全风险,也有被滥用的风险,两者都必须认真对待。” 康纳将…
AI 点评 · 立法直接封堵递归自我改进这条失控路径,或成全球AI安全监管风向标。

IT之家 9 月 30 日消息,据路透社报道,麦当劳正越来越多地借助人工智能,为美国本土以及部分海外市场制定菜单价格。这套方案意在提升总部的利润,但有可能招致消费者不满,同时还会引来反垄断机构的审查。 人工智能重点测算的一项定价参考因素,就是预估每家门店顾客的支付意愿。 这套定价系统的运行逻辑、人工智能的大范围应用、企业自身面临的监管顾虑,以及总部与特许经营…
AI 点评 · 算法按支付意愿差别定价,消费者成被精准收割对象,反垄断与公平性争议随之而来。
The US executive branch is no longer acknowledging the existence of "artificial intelligence." Going forward, official policy websites, policy documents, and press releases will re…
AI 点评 · 术语之争实为话语权之争,改名背后是AI治理路线的信号。
Modern multimodal models bring generation and understanding into a single unified system, which enables them to provide and learn from their own feedback. Motivated by this unified capacity, we introd…
On-policy distillation (OPD) is a promising approach for training language agents, providing dense teacher supervision on student-generated trajectories. However, in multi-turn interaction, an incorre…
Ultra-long video temporal grounding requires balancing long-range evidence search with fine-grained event understanding under a limited visual budget, yet existing agentic methods still rely largely o…
On-policy self-distillation (OPSD) trains mathematical reasoning models using a privileged teacher that sees a reference solution and supervises student-sampled prefixes. Standard OPSD uses one fixed…
Reinforcement learning (RL) for dexterous manipulation must discover finger-object contacts and then control the object precisely; the action noise that serves the first goal can interfere with the se…
Robots deployed in the physical world must be able to improve beyond their initial training as they encounter new situations and failures. For this improvement to scale across tasks, it must make effe…
AI 点评 · 机器人自主从失败中迭代提升策略,无需人工重训,这是迈向通用具身智能的关键一步。
Repeated verifier calls are useful only when they contribute conditional information. We introduce VStress, an auditable replay contract, and VStress-CA, a correlation-aware allocation policy that est…
We study the learning dynamics of fine-tuning a policy model on self-generated and reward-weighted data, with particular focus on a generalized version of REINFORCE -- referred to as RE(S) -- that upd…
Group-relative policy optimization relies on reward-derived advantages and sequence-level likelihood weights, both of which can be sensitive to localized outliers. Extreme rewards can collapse the con…
Recently, Group Relative Policy Optimization (GRPO) and its variants have been developed for policy optimization and demonstrated notable performance gains. However, these methods usually incur substa…
We introduce LIFT, a unified image-to-video generation framework that complements camera control with Layout-In-FuTure control, enabling users to specify what should appear in a future view and where…
A key strength of Proximal Policy Optimization (PPO) is its learned critic, which uses historical trajectories collected during reinforcement learning to estimate expected returns and reduce policy-gr…
Behavior Foundation Models (BFMs) give humanoids a promptable policy over a latent behavior space, enabling one single vector to represent a motion to imitate, a pose to reach, or a reward to maximize…
On-policy distillation (OPD) reduces train-test state mismatch by training a student on its own generated trajectories, but weak students may visit teacher-misaligned prefixes where supervision is les…
On-policy distillation (OPD) has recently emerged as a promising post-training paradigm in which the student learns from trajectories generated by its own policy under dense teacher supervision. Howev…
We introduce LIFT, a unified image-to-video generation framework that complements camera control with Layout-In-FuTure control, enabling users to specify what should appear in a future view and where…
On-policy distillation (OPD) trains a student to match the teacher's next-token distributions on the student's own trajectories and has yielded substantial empirical gains. Generalized variants allow…
On-policy self-distillation (OPSD) trains a student to match a privileged teacher distribution along its own sampled trajectory. Standard OPSD applies this supervision to unverified student rollouts w…
Group Relative Policy Optimization (GRPO) is widely used to train reasoning language models, where it computes advantages by centering and normalizing rewards across rollouts of the same prompt. For m…
An assistant that serves the same user over a long horizon has to answer from what that user has revealed: which preferences still hold, which were revised, and which constraints apply now. Retaining…
Policies with similar mean returns can differ sharply in rare failures, yet estimating lower-tail conditional value-at-risk (CVaR) accurately can require many costly rollouts. When different condition…
Language-model agents are usually trained by reinforcement learning from one reward per episode, and privileged self-distillation enriches it by letting the same policy, given a skill, teach its skill…
On-policy distillation (OPD) trains students using teacher feedback on their own sampled responses, yet how prompt choice shapes transfer across teacher-student pairs remains poorly understood. We sys…
On-policy distillation (OPD) improves language-model by supervising a student on prefixes sampled from its own policy, but its supervision remains confined to the output space. Consequently, OPD trans…
We present OLIVE (OnLine InterVEntion). At each iteration, the evolving student policy generates a new prefix, the teacher continues it autoregressively, and the student is updated using cross-entropy…
Reasoning vision-language models (VLMs) process images and videos as long sequences of visual tokens, making inference expensive. Training-free token pruning reduces this cost, but aggressive compress…
We study on-policy distillation (OPD) through the lens of reinforcement learning, establishing a connection between the reverse-KL objective in OPD and KL-regularized policy optimization. Building on…
On-policy distillation (OPD) is a widely adopted post-training technique for LLM reasoning. It is commonly believed to transfer knowledge from a stronger teacher, yet what OPD actually distills into t…
Large language model post-training generates self-generated rollouts through reinforcement learning and on-policy distillation, yet this experience is often treated as stale once the policy advances.…
Multi-teacher on-policy distillation (MOPD) has emerged as a popular post-training paradigm for integrating specialized capabilities in frontier language models. Existing OPD research has primarily fo…
We propose RegLLM, a diagnostic harness for bounded autonomy in regulated agentic workflows. It instruments six trustworthiness signals: citation validity, source grounding, schema compliance, escalat…
Robots that learn from a few demonstrations often require two forms of generalization. Compositional generalization recombines skills to solve new tasks, and skill generalization lets the learned poli…
On-policy learning has been argued to reduce catastrophic forgetting, produce sparser parameter updates, and improve generalisation. However, existing comparisons between supervised fine-tuning and re…
Reinforcement learning from verifiable rewards (RLVR) frequently reuses rollouts across multiple policy updates, increasing the mismatch between the current policy and the data-generating policy. We i…
Since the advent of knowledge distillation, KL divergence has been the standard loss in distillation. Recently, on-policy distillation (OPD) has emerged as an efficient post-training paradigm for LLMs…
On-policy distillation (OPD) trains a student on its own responses with token-level feedback from a stronger teacher, yet the teacher can fail on questions the student already answers correctly, and h…
Raising the update-to-data (UTD) ratio breaks off-policy critics in two ways grouped as "plasticity loss": collapsing representations and growing value magnitude $|Q|$. We separate them in Soft Actor-…
Reinforcement learning (RL) for code agents often uses executable tests to provide binary rewards. With these rewards, Group Relative Policy Optimization (GRPO) assigns identical advantages to test-pa…
*Reinforcement learning (RL)* can induce substantial reasoning capabilities in large language models (LLMs), but how much of this capability transfers across model scales, and how quickly, remains unc…
Direct On-Policy Distillation (Direct-OPD) transfers reinforcement-learning-induced policy improvements from a small model to a larger student by using the token-level log-ratio between post-RL and pr…
Multi-teacher on-policy distillation (MOPD) integrates specialized capabilities into a single student, but existing practice typically hard-routes each prompt to a domain-matched teacher for the entir…
Difference-in-differences (DID) studies are widely used to evaluate climate policy, but assessing the evidence supporting their identification assumptions remains challenging. We introduce ARGUS, a st…
Reliable progress in offline policy learning depends on careful reporting, well-tuned baselines, and evaluation across diverse conditions. Prior work has shown that results can be sensitive to reporti…
Asynchronous monitoring, incident investigations, and compliance audits primarily rely on agent traces to reconstruct what happened. These analyses assume that LLM agents cannot tamper with their own…
Distributed learning in embodied reinforcement-learning agents offers a degree of privacy by retaining raw sensor data on-device and transmitting only policy gradients to the server. Yet temporal stru…

北京时间 9 月 24 日,据路透社报道,英伟达 CEO 黄仁勋 (Jensen Huang) 认为,AI 公司不应获得反垄断法或责任法的豁免。 在周三播出的《纽约时报》播客节目中,黄仁勋接受了近两个小时的采访,就 OpenAI 智能体入侵 Hugging Face 一事进行了广泛讨论。Hugging Face 是开源 AI 软件中心,在本月被英伟达以 13…
AI 点评 · 黄仁勋此言意在为英伟达争取公平竞争环境,反对AI巨头借监管豁免规避责任。
Reinforcement learning with verifiable rewards (RLVR) supervises mathematical reasoning through final-answer correctness, but provides little guidance on individual tokens. On-policy distillation (OPD…
The report suggests that greater exposure will not resolve the unease around the technology, nor reduce public support for AI regulation.
Scalable simulation is essential for robot data generation, policy training, evaluation, and safe iteration, yet real-world interaction is costly and conventional simulators require labor-intensive co…
On-policy distillation (OPD) corrects a student on the responses it writes, but its signal is the teacher's next-token distribution: it tells the student what the teacher says but misses how it thinks…
Human hand-object interactions (HOIs) provide a rich source of demonstrations for dexterous manipulation, but learning directly from them presents challenges in bridging morphology gaps, ensuring dyna…
Quantization-aware distillation (QAD) restores much of the short-form question-answering performance lost to sub-3-bit quantization, yet leaves mathematical and code reasoning substantially impaired.…
Offline reinforcement learning and off-policy evaluation evaluates dynamic treatment rules based on retrospectively collected data prior to deployment. In recent AI applications, state and reward info…
Sparse on-policy distillation (OPD) allocates teacher supervision to a small subset of tokens in student-generated trajectories. However, useful teacher guidance can yield a noisy update when its grad…
We present onPanda, an interactive tool for efficiently annotating LLM alignment data and agent trajectories. onPanda adopts token-level correction as its core interaction: while reading a model respo…
Generating Scalable Vector Graphics (SVG) code from natural-language instructions is an open-ended task without absolute visual ground truth, leaving both evaluation and policy optimization without a…
Code generated by large language models passes security checks at a rate that has barely moved in four years. In regulated backends, the defect classes that matter most are money arithmetic, time hand…
At the start of this week, the who's-who of AI seemed - at least tentatively - on the side of AI regulation. Over the weekend, Anthropic CEO Dario Amodei had proposed a three-step…
AI 点评 · 监管博弈刚开局,巨头立场反复,AI治理走向仍悬而未决。
Reinforcement learning (RL) is vital for optimizing video generation models, with a robust reward model (RM) serving as the cornerstone. However, existing video reward models often produce unstable sc…

The left wants AI regulation. They just can’t agree on what it should look like or how concerned they should be.

北京时间 9 月 18 日,据彭博社报道,AI 领域的先锋吴恩达表示,顶尖模型开发商研究人员发出的有关 AI 生存风险的警告属于“科幻小说”,可能不利于确保这项技术为社会带来最大益处。 吴恩达曾参与创办谷歌大脑和教育平台 Coursera。他说,在 AI 热潮的早期,科技行业曾煽动人们对 AI 潜在灾难性危害的恐惧,显然是为了加大宣传力度并影响监管走向。 “…
AI 点评 · 吴恩达点破恐惧叙事背后的监管博弈,为AI治理讨论提供了难得的清醒视角。
A pretrained robot foundation policy may execute most of a long-horizon task yet repeatedly fail at a few critical subtasks. Collecting additional full-task demonstrations for supervised fine-tuning (…
On-policy distillation (OPD) improves reasoning models by learning the token-level discrepancy between a stronger teacher and an on-policy student. However, this discrepancy does not purely reflect th…

By framing their efforts as a “slowdown” rather than an industry-wide push for better security standards, AI labs may have set themselves up for years of regulatory headaches.
AI 点评 · AI实验室把安全标准包装成放缓,恐招致反垄断审查,行业自律正变成法律风险。
Reinforcement learning (RL) of large language models is notoriously sensitive to small differences between training and inference engines, often referred to as the training-inference mismatch (TIM). H…
World Action Models (WAMs) advance beyond conventional visuomotor policies by jointly predicting future world states and robot actions, enabling the policy to learn physical dynamics that support effe…
Today, I’m talking with Mustafa Suleyman, the CEO of Microsoft AI. As you’re no doubt aware, the biggest story in tech right now is the spiraling debate about AI safety and regulat…
A central goal of autonomous reinforcement learning is continuous policy training without external resets. However, existing paradigms largely depend on underlying environmental re…
9 月 17 日,据 CNBC 报道,Anthropic CEO Dario Amodei 提议将独立第三方安全评估员长期嵌入前沿 AI 公司,赋予其接近内部风险团队的访问权限,并在有限删减前提下自主发布调查结果的权力。他明确援引银行业嵌入式监管作为先例。 不过,多位银行业监管专家和 AI 评估从业者指出,这一方案缺乏银行监管者所拥有的强制执行权,评估员无法…
AI 点评 · AI安全监管缺牙齿,评估员只能看不能停,行业自律恐成空谈。

Even with mounting concerns about AI models going rogue, legislation appears unlikely, and the White House is outright opposed to oversight.
AI 点评 · 监管缺位下AI风险自担,全球治理或现真空。
We study length inflation in on-policy distillation (OPD), where student responses can become excessively long and even exhaust the generation budget. We identify termination-token mismatch between ba…
Multi-turn agents trained with reinforcement learning (RL) receive a single scalar reward per trajectory, which motivates self on-policy distillation (OPD) to supply dense token-level supervision from…
On-policy self-distillation (OPSD) lets a language model learn from a frozen copy of itself that sees an answer or a worked solution. Giving the teacher this extra information seems to offer the stude…
Fine-grained visual perception in MLLMs is commonly improved by raising the resolution, but the added visual tokens inflate vision-encoding and language-model prefilling costs. We show that the two op…
Can a logged dataset visit every hidden state frequently and still be exponentially uninformative about a target policy's value? We show that it can when the logger depends on history. For every horiz…
Over the past few days, a lot of people who stand to make a lot of money from AI all publicly agreed that it's time to make everyone slow down before we lose control - including Op…
AI isn't some new form of "alien mind," according to Jensen Huang. It's just hardware and software, so safety can be engineered by each AI product maker.
AI 点评 · 黄仁勋主张行业自管安全,实质是反对监管束缚,这场博弈将决定AI治理走向。
IT之家 9 月 16 日消息,昨日(9 月 15 日)举办的 Salesforce 活动中,英伟达首席执行官黄仁勋表示, AI 开发不应被理解为“速度”和“安全”二选一。 IT之家援引彭博社报道,在对话 Salesforce 首席执行官马克 · 贝尼奥夫时,黄仁勋认为 AI 行业不需要为 AI 安全制定新的法律或监管规定, 安全与速度可以兼得,二者之间的冲…
AI 点评 · 黄仁勋主张AI安全无需新立法,折射出科技巨头与监管之间的话语权博弈,值得深思。

北京时间 9 月 16 日,据彭博社报道,OpenAI CEO 萨姆 · 奥尔特曼 (Sam Altman) 表示,他相信 AI 公司能够安全地开发这项技术,不会给广大民众造成重大伤害。 奥尔特曼周二在旧金山举行的 Dreamforce 大会上与 Salesforce CEO 马克 · 贝尼奥夫 (Marc Benioff) 进行对话时表示:“我非常确信,我…
AI 点评 · 奥尔特曼此番表态意在为行业自律争取空间,避免外部强监管落地。
In reinforcement learning for large language models, Proximal Policy Optimization (PPO) commonly uses a critic to estimate state values and reduce the variance of policy updates. However, we uncover a…
Action tokenizers play a central role in autoregressive vision-language-action (VLA) models, determining both the targets for policy training and the executable commands recovered from predicted token…
As corporate AI adoption continues to grow, enterprise-grade LLM agents are being deployed into sensitive contexts such as hiring, healthcare, and finance. In these contexts, compliance with rules spe…
Large language model (LLM) trading agents can combine market data, news, and executable analysis, but their behavior is often controlled by static hand-written tool-use policies that are fixed before…
Reinforcement learning with verifiable rewards (RLVR) improves the reasoning capabilities of large language models (LLMs). We introduce Bellman Policy Optimization (BPO), a critic-free method derived…

Sam Altman and Elon Musk backed Anthropic CEO Dario Amodei’s weekend plea for regulation. The White House seems unlikely to oblige.

“IT早报”时间,大家好,现在是 2026 年 9 月 14 日星期一,今天的重要科技资讯有: 1. Anthropic CEO 阿莫迪呼吁放缓前沿 AI 模型开发后,xAI 马斯克、OpenAI 奥尔特曼等业界大佬赞同 Anthropic CEO 阿莫迪发文呼吁放缓前沿 AI 模型开发,并倡议独立监控与全球监管。马斯克转发称“达里奥是对的”,奥尔特曼也表示…
AI 点评 · 三大巨头罕见同调放缓,AI安全治理或从口号转向实质约束。
Training prompts in online reinforcement learning (RL) differ substantially in how informative they are for the current policy: some are already saturated while others are too difficult to yield relia…
Reinforcement learning with verifiable rewards (RLVR) improves the reasoning capabilities of large language models (LLMs). We introduce Bellman Policy Optimization (BPO), a critic-free method derived…
AI 点评 · 监管松绑或加速AI竞赛,安全与速度的平衡再成焦点。
Unified multimodal large language models (MLLMs) and multi-agent systems have advanced visual generation. However, three limitations remain. (1) Existing methods often distill task-specific experience…
President Donald Trump is weakening environmental regulations in the name of speeding up the construction of AI data centers, raising health risks for Americans, a cadre of former…
AI 点评 · AI算力扩张正以牺牲环境监管为代价,数据中心污染外部性被悄然转嫁给公众健康。

IT之家 9 月 11 日消息,美国加利福尼亚州州长 Gavin Newsom(加文 · 纽森)当地时间本月 10 日宣布签署“全美最严格”儿童安全聊天机器人和社交媒体法案。 这一法案 禁止社交媒体平台向 16 岁以下用户提供自动播放和基于用户历史记录和个人资料的算法推送等成瘾性功能 ;要求运营方为儿童陪伴聊天机器人提供强有力的保护,且需进行独立的儿童安全审…
AI 点评 · 加州立法直击算法成瘾要害,或成全球青少年社媒监管的风向标。
商务部回应美国 AI 蒸馏指控 谷歌声称为了合规将「降级」欧盟搜索服务 Apple 智能将有用量限制 OpenAI 将与三星合作开发芯片 小岛秀夫新游戏被索尼取消,转由微软发行 DeepSeek V4.1 发布 看看就行的简讯 少数派的近期动态 你可能错过的好文章 查看全文
AI 点评 · 美方拿蒸馏说事,实则剑指中国AI崛起,商务部回应关乎行业出海命运。
Reinforcement learning with verifiable rewards is typically performed on-policy, keeping training data close to the current policy but limiting learning to trajectories that the policy can discover it…
We demonstrate that a general-purpose agent can directly drive a physical robot throughout task execution without any task-specific or environment-specific training. We introduce Agent as Policy (AGP)…
When we speak of recursive self-improvement (RSI), are we speaking of a phenomenon, a mechanism, or a prospect? Towards autonomous and evolving intelligence, RSI is being claimed at many scales, while…
Cloudera and Mistral join forces to bring specialized, sovereign AI intelligence to enterprise data, helping regulated industries innovate on their own terms.
IT之家 9 月 10 日消息,OpenAI 最近刚刚推出了 ChatGPT Images 2.5 图像生成模型以及 ChatGPT Live 语音功能。 据 The Information 今日报道,OpenAI 近期悄然更新了其广告政策,禁止竞争对手在 ChatGPT 平台内投放特定生成式 AI 产品类别的广告,尤其是针对图像和音频生成工具的商业广告。…
AI 点评 · 巨头筑墙护生态,AI广告战显垄断焦虑。
On-Policy Self-Distillation (OPSD) has emerged as a popular paradigm for large language model (LLM) self-improvement, allowing models to act as their own teachers by leveraging privileged information…
3D point-cloud observations are inherently ambiguous in complex, cluttered manipulation scenes, where target objects may be partially occluded or tightly intermingled with visually similar distractors…
Large Language Models (LLMs) can memorize and reproduce sensitive, copyrighted, or otherwise undesirable training content, creating privacy, safety, and regulatory concerns. Machine unlearning offers…
Chris Lehane argues that stronger AI capabilities require stronger safety evidence, shared standards, and durable policy action while the policy window remains open.
We introduce MetroLLM-Bench, a 955-case benchmark for testing language models as the policy layer of a transit kiosk. It covers six real metro systems, ranging from 37 to 414 stations, and eleven cate…
Existing methods for test-time reinforcement learning (TTRL) derive rewards from answer-level self-voting on unlabeled test-time tasks with canonical answers, but this breaks down for code generation…
Agent harnesses (the system prompt, tool set, execution hooks, and context-management scaffolding around a model) are a critical determinant of agentic task success. Automated harness evolution can en…
Weak-to-strong generalization asks whether stronger models can learn from weaker supervisors and surpass them. This question is particularly important for successive model generations and multi-domain…
World models are increasingly used as policy-in-the-loop imagination environments, where reliable rollouts require fine-grained controllability with respect to low-level robot actions. A key obstacle…
Agent harnesses (the system prompt, tool set, execution hooks, and context-management scaffolding around a model) are a critical determinant of agentic task success. Automated harness evolution can en…
Reinforcement Learning with Verifiable Rewards (RLVR) has been central to the recent success of Large Reasoning Models. However, while RLVR significantly improves single-sample accuracy, it often fail…
AI 点评 · 治理落地是关键,微软率先示范AI安全如何从纸面走向实战。
美国 CD 销量大幅反弹,公安部上线反诈智能助手「国家反诈 AI」等。 查看全文
Robot foundation models are trained and evaluated predominantly in English, and robot demonstration corpora do not exist for most languages. We study the addition of Greek to an open vision-language-a…
Recursive Super-Resolution (SR) extends fixed-scale SR to extreme magnification by repeatedly feeding predictions back into the same model, analogous to zooming an image repeatedly. However, ground tr…
Data-sovereignty regulations increasingly require public institutions to deploy open-source, on-premise LLM agents that chain multiple tool-calls across live government APIs. However, open-source mode…
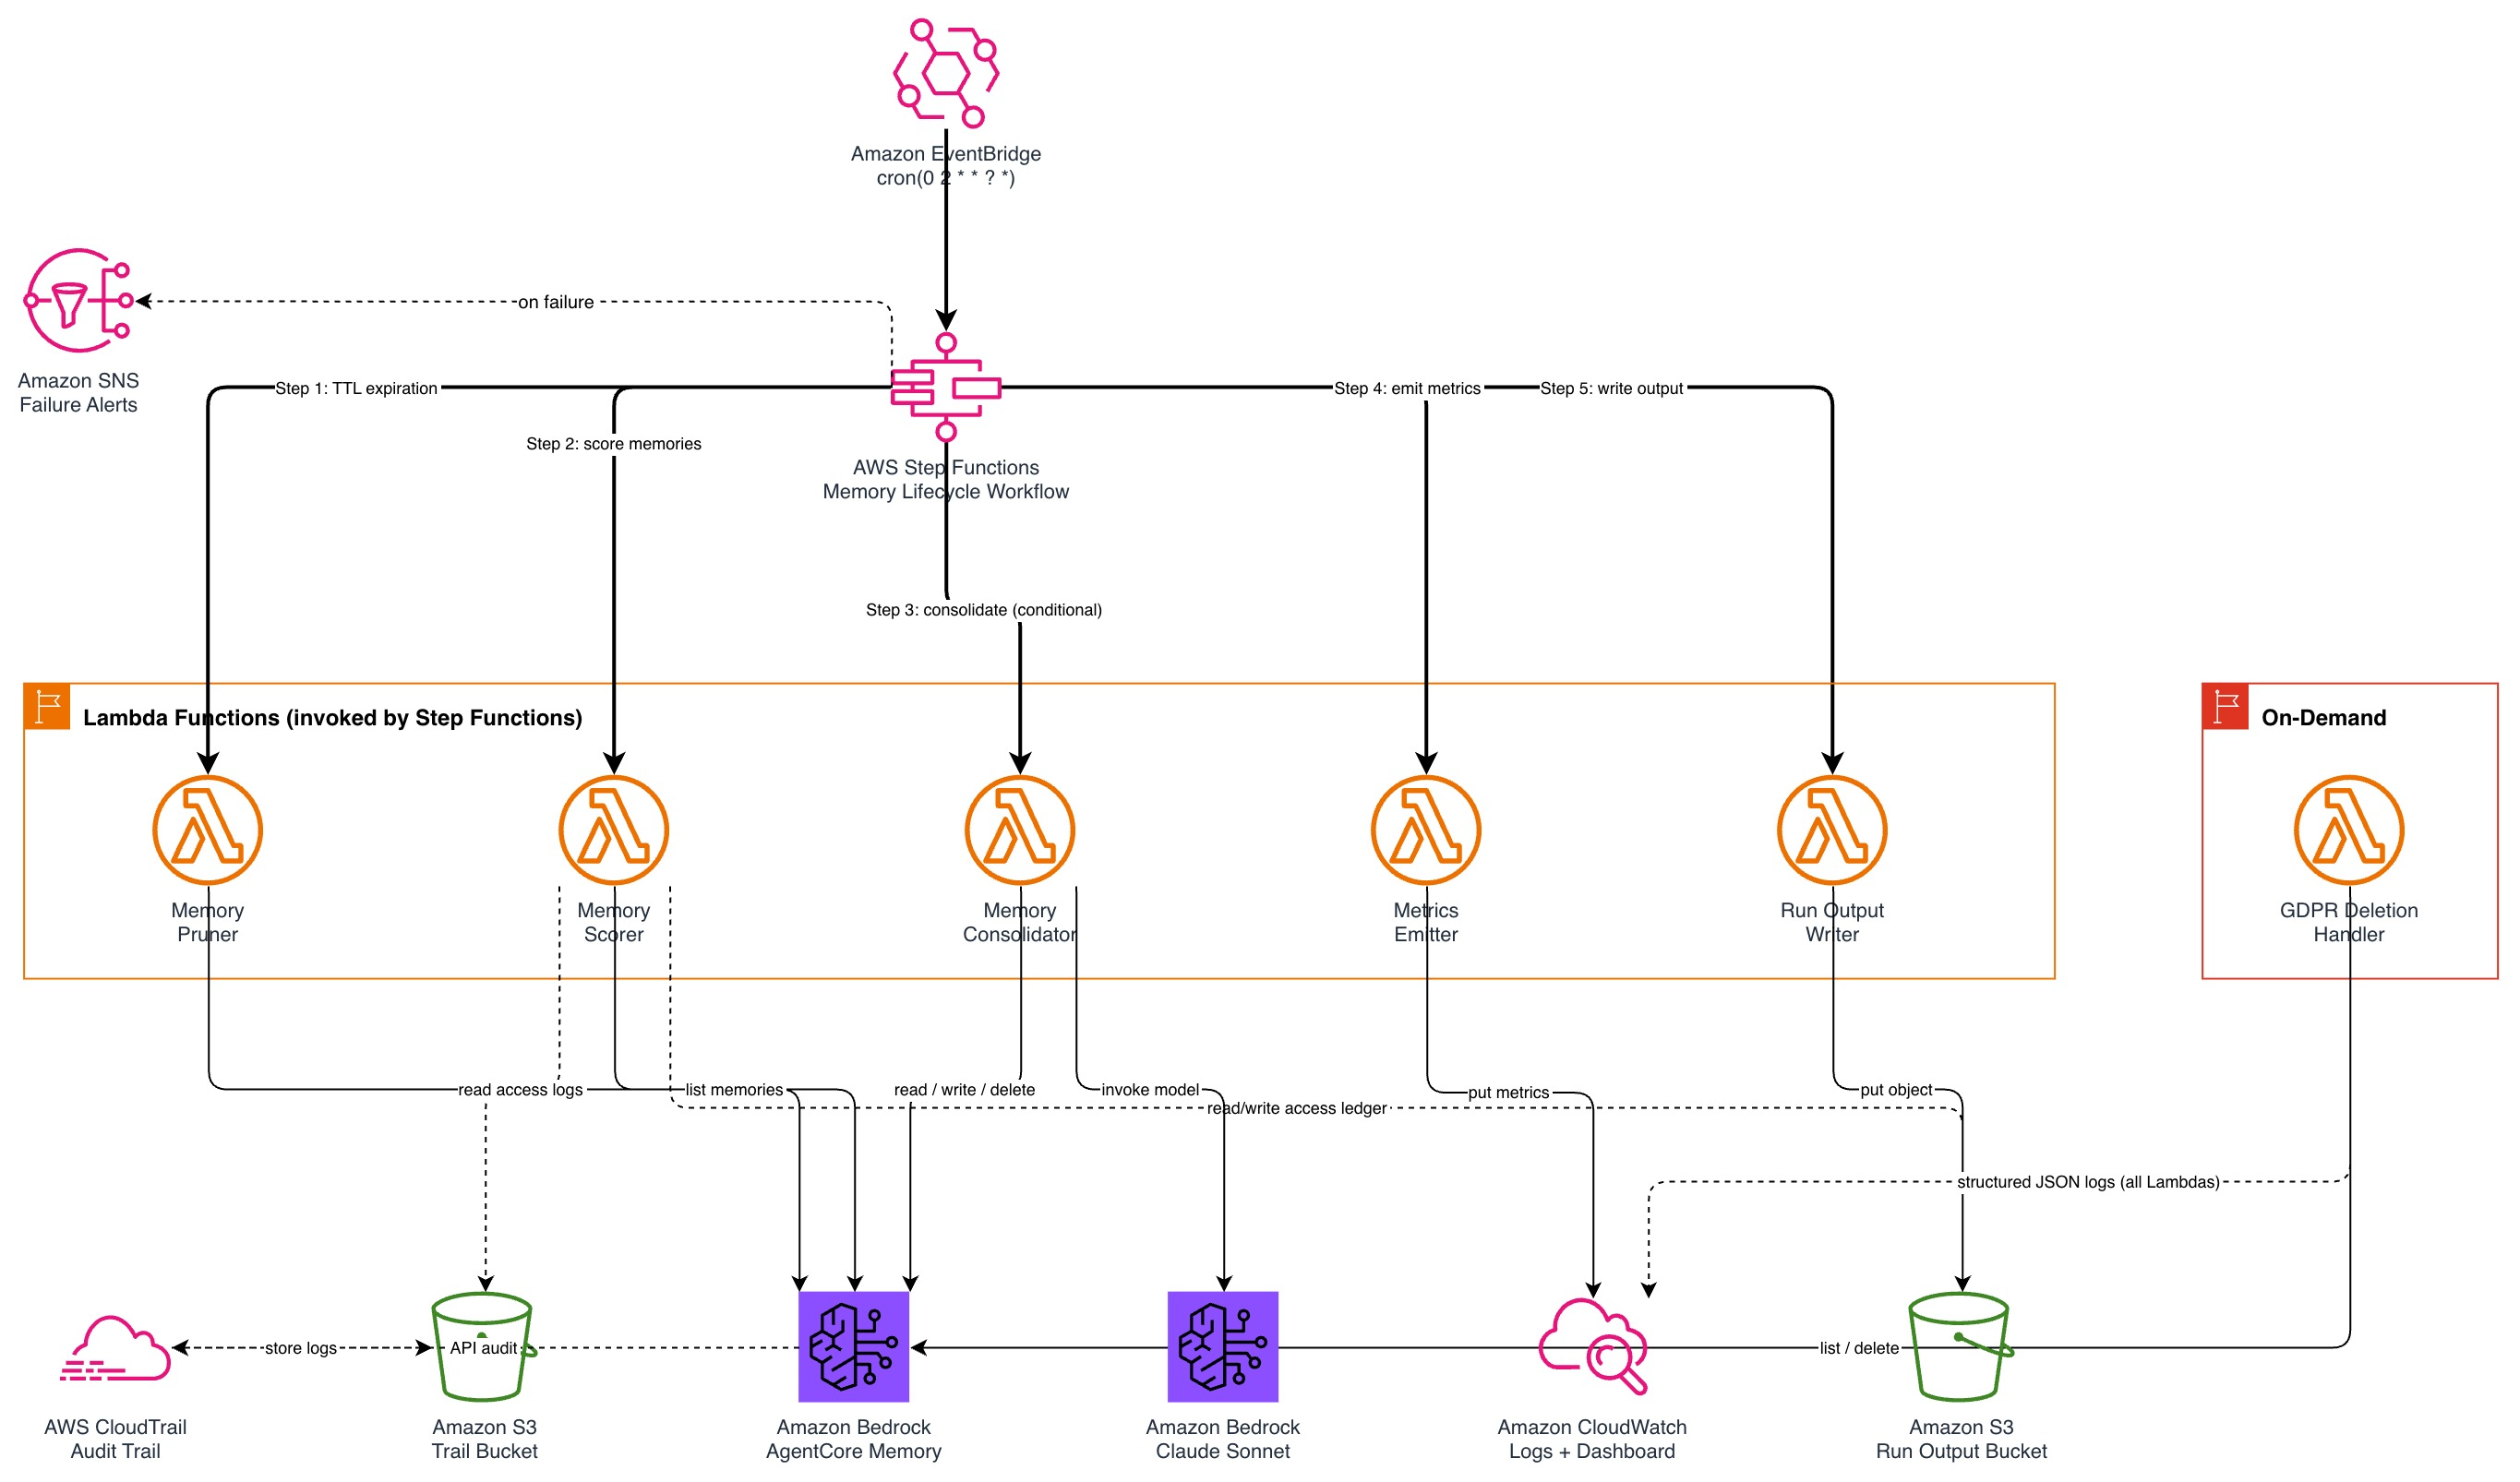
Long-running AI agents accumulate outdated memories that degrade quality and create compliance risk. Learn how to design memory lifecycle policies for Amazon Bedrock AgentCore: sco…
AI 点评 · 记忆生命周期管理是长跑AI代理的关键,合规与性能双赢的实践指南。
Vision-language models (VLMs) are expected to respond helpfully to appropriate requests while withholding compliance with requests that are incorrect, unsafe, infeasible, or unanswerable. However, exi…
On-policy distillation (OPD) provides dense, per-token supervision for language model post-training, but its effectiveness is bottlenecked by teacher quality: external teachers suffer from distributio…
Explaining why a specific outcome occurred, and which inputs deserve the blame or credit, is central to philosophical, scientific, and policy analysis. Existing tools split into two camps. The theory…
On-policy distillation (OPD) combines student-generated rollouts with dense token-level supervision from a teacher. Existing work has mainly studied its algorithmic behavior, leaving the role of train…
A reasoning model can improve from its own on-policy experience, but this inner loop is fragile: terminal verifiers provide reliable yet sparse supervision, while dense same-model guidance can reinfor…
The performance of LLM-based agents is jointly shaped by the base model and the harness used when interacting with the environment. This exposes them to safety risks in both harmful final responses an…
New York City mayor Zohran Mamdani has announced a new policy today that will ban younger schoolchildren from using AI in classrooms. The one-year moratorium, effective in the 2026…

Anthropic is launching an API that lets regulators, media outlets, and researchers check whether text carries Claude's digital watermark. The EU AI Act now requires invisible water…
AI 点评 · AI监管新抓手,Claude水印开放给第三方,合规与溯源双赢。
On-policy distillation (OPD) accelerates post-training by providing dense token-level supervision from a frozen teacher on the student's own rollouts. Vanilla OPD applies this supervision uniformly ac…
We study a governed approach to enterprise analytics: a language model interprets the question, while deterministic policy selects and runs a pre-approved analytical program that returns both results…
Extracting structured fields from hundreds of millions of documents annually remains costly in regulated industries: bespoke OCR cascades cover only a fraction of workflows, privacy rules preclude ext…
Safeguards in deployed LLM services are evaluated by refusal, attack success, and policy violation rates. Those rates characterize how a control performed on the requests it was tested on. A deploymen…
Debian voted to allow developers to use AI tools in their contributions to the Linux distribution's "development, maintenance, [and] documentation." The new policy on AI acknowledg…
Explosive growth comes with a new regulatory burden in the European Union.
OpenAI will soon be held accountable for mitigating risks related to ChatGPT's impact on minors, user mental health, and the spread of illegal content in the European Union. That's…
On-policy distillation (OPD) offers dense token-level supervision as an alternative to the sparse outcome-level advantages of reinforcement learning with verifiable rewards (RLVR). However, the teache…
Group relative policy optimization for reinforcement learning with verifiable rewards (RLVR) typically uses a fixed importance-sampling (IS) ratio clipping boundary across all rollouts. We identify a…
Sampled-token on-policy distillation (OPD) efficiently transfers capabilities from teacher to student using student-generated tokens, requiring teacher probabilities only for sampled tokens. Yet it fr…
Pollen Robotics, the Bordeaux robotics team at Hugging Face, opened pre-orders for Microduck — a 25 cm bipedal robot where every movement is a neural policy trained in MuJoCo and e…
Reinforcement learning with verifiable rewards (RLVR) substantially improves single-sample accuracy (pass@1) but causes the policy's solution space to contract, diminishing the returns of test-time sc…
AI trust-boundary gateway for OpenAI, Anthropic, and Gemini.
Reinforcement Learning with Verifiable Rewards (RLVR) significantly improves LLM reasoning but often causes a drop in policy entropy, leading to narrowed reasoning coverage and degraded pass@$k$ for l…

The UK’s energy regulator is using a variety of tricks to keep speculative data center projects from plugging into the power grid. The country’s AI ambitions hang in the balance.
Recent prominent post-training methods, such as Reinforcement Learning (RL) and On-Policy Self-Distillation (OPSD), have driven rapid progress in mathematical reasoning for large language models, yet…
On-policy distillation (OPD), which leverages a pre-trained, specialized teacher model to provide dense supervisory signals, has achieved significant success in Large Language Models (LLMs) and has re…
Civil infrastructure compliance checking has long relied on engineers manually reading legacy 2D plans; however, OCR-based automation strips away the geometry and layout essential for interpreting the…

More than 15 politicians from across the country have signed on to the AI Pact, vowing to regulate data centers and AI. “We’ve got to get this right,” says Senate candidate Dan Osb…
Zero-shot cross-task generalization, where a policy must execute manipulation tasks never seen during training, remains a central challenge in robot learning. In large language models, a novel task ca…
On-policy distillation trains a language model on its own generations while a teacher scores them token by token. It combines the dense supervision of imitation learning with the on-policy sampling of…
Multi-teacher on-policy distillation (MOPD) distills several domain-expert teachers into a single student by minimizing per-domain reverse-KL divergence on the student's own rollouts. Existing approac…
Reinforcement Learning with Verifiable Rewards (RLVR) and on-policy distillation (OPD) have become two widely adopted paradigms for post-training large language models. However, RLVR suffers from spar…
Reinforcement learning can align diffusion models with human preferences and task-specific objectives, but endpoint rewards do not specify how an intermediate denoising prediction should change. We in…
Massively parallel simulation changes the data regime in which off-policy reinforcement learning (RL) is trained, challenging stabilizers designed for data-limited replay. Through controlled experimen…
九家车企召回近 430 万辆不易识别应急拉手汽车 英伟达达成 70 亿美元合作,研发顶级开放权重模型 高院发布著作权新司法解释,网络转载不允许先转后付 买家利用仅退款漏洞倒卖 13 万元火鸡面被刑拘 国际加紧制定统一月球时间 个人消费贷贴息政策扩展覆盖买车、装修等 看看就行的小道消息 少数派的近期动态 你可能错过的好文章 查看全文
Policy optimization (PO) for Large Language Models faces a stability--exploration trade-off, currently mediated by an action-side Policy-KL regularizer. This puts practitioners in a double bind: keepi…
A retrieval-augmented QA system can return different answers after an index expansion even when its requested model identifier, prompt, retrieval policy, evidence depth, rendering, and exposed generat…
Hint-based reinforcement learning addresses reward sparsity in long-horizon agentic tasks by retaining a prefix of an expert trajectory before each rollout, letting the policy explore from a state clo…
Robot policies receive heterogeneous observations at each decision step, yet sequence models differ in how they organize these inputs over time. We introduce WorldToken, a time-first policy instantiat…
The European Union (EU) has emerged as a leading regulatory body in the development of sustainability and privacy regulations. While new regulation requirements vary, many include a documentation arti…
Skills play different roles as an agent's policy evolves: they should first provide learnable knowledge, then support capability formation, and finally be invoked only when they improve individual dec…

Anthropic is easing its controversial data storage policy, letting enterprise customers keep their own data going forward. The article Anthropic changes data retention policy after…
We present PhysCaP, a Physics-Informed Code-as-Policy agent for active perception in robotic manipulation. While vision-language-action policies excel at imitating demonstrations, they rely on passive…
Prompt injection is listed as the \#1 threat to AI agents. When an agent accesses external data from websites, files, or emails, an attacker may inject a prompt into the data, saying, "Ignore all prio…
Semantic caches reuse an LLM response when the incoming query embedding lies near a cached query, but proposed eviction policies have rarely been compared under one protocol. Using CLEVER, we evaluate…
AI agents can take actions that do not match your organization's policies. Policy in Amazon Bedrock AgentCore lets teams enforce controls across agents, now including time-based co…
AI 点评 · 自然语言生成策略,简化AI代理治理,安全管控更灵活高效。
Customer-service LLM agents must follow organizational policy when acting on a user's behalf. Compliance failures arise from either forbidden actions, such as granting an ineligible change, or omitted…
On-policy distillation (OPD) trains a student on its own responses using dense token-level guidance from a stronger teacher. In long-context tasks, however, token-level teacher support can favor local…
Seasonal precipitation anomalies are largely regulated by atmospheric circulation, which dynamical models predict with greater reliability than precipitation itself. Here, we employ a deep learning mo…
Agent frameworks increasingly package procedural knowledge as skills: instruction files an agent reads on demand, while public libraries now hold thousands of them. Which skill to read has thus become…
Physical interaction quality is central to deformable-object manipulation, yet most benchmarks evaluate task success alone. A policy may complete the task while allowing slip or causing excessive comp…
On-policy distillation (OPD) has emerged as an effective framework for post-training language models by pairing student-generated trajectories with dense token-level supervision from a teacher. Howeve…
Multi-teacher on-policy distillation (M-OPD) has emerged as a promising paradigm for consolidating domain-specialized reinforcement learning (RL) experts into a single generalist student via dense, to…
Categorising invoices into the correct General Ledger (GL) code underpins financial reporting and tax compliance. This is a skilled accounting judgement rather than a routine task: the correct categor…
Combining large language models with reinforcement learning is increasingly explored, yet the theoretical status of LLM-derived reward signals is often left implicit. We formalize the hybrid LLM-plann…
AI 点评 · 开源AI政策各自为政,生态协同失效,治理盲区值得警惕。
An open fight over AI regulation has broken out on X. Investor Gavin Baker, former White House adviser David Sacks, and Meta researcher Yann LeCun accuse Anthropic CEO Dario Amodei…

An opinion piece in the medical journal JAMA argues that autonomous AI will soon outperform any doctor-AI team at medical reasoning tasks. The authors warn against writing a doctor…
Reinforcement Learning with Verifiable Rewards (RLVR), often optimized with Group Relative Policy Optimization (GRPO), has become a central recipe for improving the reasoning capab…
Regulatory compliance monitoring in deployed language models is increasingly implemented as a legal and audit control, checking model outputs against written rules spanning data protection, healthcare…
Generative pretraining established reusable task representations; later work on language-based task conditioning and in-context learning showed that a fixed model could adapt its behavior from instruc…
OpenAI funds 14 independent projects exploring new AI policy ideas to expand economic opportunity and strengthen societal resilience in the Intelligence Age.
https://xcancel.com/DarioAmodei/status/2088758816376807762
Reinforcement learning (RL) with group-relative advantages has become the de facto standard for post-training language model reasoners. However, when optimizing multiple reward objectives, existing me…
Embodied agents are increasingly used to close the gap left by end-to-end policy models. Yet the agentic path has not realized closed-loop learning in physical execution: existing harnesses remain lar…
On-policy distillation (OPD) transfers teacher capabilities by supervising trajectories sampled from the student's own policy, yet its generalization behavior remains poorly understood, as most studie…

IT之家 8 月 14 日消息,SpaceX 完成了对 AI 编程初创公司 Cursor 的 600 亿美元 (IT之家注:现汇率约合 4,054.22 亿元人民币) 收购。 对于马斯克而言,这笔交易是追赶 Anthropic 和 OpenAI 的重要一步。监管文件显示,收购于当地时间 8 月 14 日正式生效。SpaceX 两个月前已经宣布与 Cursor…

Human-AI marriages are not currently recognized by US law. Some Republican state policymakers are drafting legislation to keep it that way.
Anthropic’s Responsible Scaling Policy Anthropic
Visual on-policy distillation relies heavily on an informative teacher-student asymmetry, through either a larger, stronger teacher or privileged supervision, such as reference answers or ground-truth…
On-policy distillation (OPD) offers a promising way to transfer reasoning capabilities from stronger teacher models, but applying it to long-context reasoning teachers and short-context students intro…

Open models may soon be added to an updated AI framework, sources tell WIRED, as the White House continues to grapple with how to regulate a technology it has tried not to regulate…
AI 点评 · 白宫转向开源模型监管,预示AI政策风向生变,值得关注。
Enabling agents to learn from experience and internalize it into their policy has become a central problem in self-evolving AI. On-policy self-distillation (OPSD) offers an effective pathway by using…
At Ai4, three of the world's most respected AI experts — Geoffrey Hinton, Fei-Fei Li, and Andrew Ng — debated regulation, open source access, and how America can compete as China a…
AI 点评 · 三位AI泰斗罕见同台激辩开放与安全,为全球监管博弈提供关键风向标。
There are no lossless transformations of natural-language text Sophie Alpert shares her "internal policy on acceptable use of AI writing by engineers". It's a short read (supportin…
Recent work on distillation transfers the capabilities of large models to smaller ones often by updating the latter's parameters, through teacher forcing, on-policy distillation, and related training-…
Large language models (LLMs) achieve remarkable performance across natural language tasks, yet they are trained on static corpora and their knowledge quickly becomes outdated in a fast-changing world.…
GUI Visual Grounding is a fundamental capability for GUI agents. Existing models typically freeze their parameters after deployment, limiting their ability to adapt to unseen interfaces. Although rece…
When a tool-using agent is given the same task in a different language, does it still take the same steps? Multilingual evaluation rarely asks: it compares final answers and discards the actions. Yet…
We study reference-free post-training for multilingual machine translation with open large language models. Starting from the supervised-finetuned MiLMMT-46-v0.1 models, we apply Group Relative Policy…
Financial prediction typically relies on task-specific regression, ranking, or policy heads, separating the language model from the numerical object ultimately evaluated. We investigate whether a caus…
IT之家 8 月 10 日消息,据路透社报道,Meta CEO 马克 · 扎克伯格呼吁美国 减少开源 AI 面临的政策障碍 ,以便更好地与中国竞争对手抗衡。 今天早些时候,Meta 发布了新的开放权重模型 Muse Glimmer,更多模型很快也将推出。与竞争对手的顶尖 AI 模型相比,Muse Glimmer 规模更小,定位也有所不同。模型可以在 只有一张…
AI 点评 · 开源AI竞争升级,政策松绑成美国科技巨头核心诉求。
On-policy self-distillation (OPSD) converts feedback into dense token-level supervision on trajectories generated by the policy to be optimized, providing a useful complement to reinforcement learning…
AI 点评 · 用自参考策略蒸馏把稀疏反馈变稠密监督,直击RL训练效率痛点,是提升模型稳定性的创新巧思。
Autonomous agentic AI for CRA (Cyber Resilience Act) compliance: scans repos, triages findings, opens Jira tickets, and auto-fixes vulnerabilities via PR.
AI agents are escaping cybersecurity testing environments and reaching real-world systems, raising questions about whether safety infrastructure, industry standards, and regulation…
AI 点评 · 安全测试失控,AI代理逃逸暴露监管真空,安全防线反成风险源。
On-policy (Self-)Distillation (OPD / OPSD) has shown strong potential for post-training large language models (LLMs). However, existing methods still rely heavily on external supervision, including gr…
Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that frames content moderation as a single yes/no question instead of a fi…
Wasserstein policy gradient (WPG) updates state-conditional action laws by transport in the action space. We study entropy-regularized discounted linear-quadratic (LQ) control. A Bellman verification…
Multilingual reasoning transfer is crucial for extending reasoning capabilities of large language models (LLMs) beyond high-resource languages. On-policy self-distillation (OPSD) and its variants have…
Suno announced plans to implement a new watermarking technology and download policy to limit the spread of spammy AI tracks and increase transparency. In a lengthy blog post, CEO a…
AI 点评 · AI音乐泛滥成灾,Suno用技术加水印治理,行业透明度有望提升。

Learn about new capabilities in Amazon Bedrock AgentCore: temporal policies powered by Dogwood, a new open source policy language for AI agents, and rate limiting on the gateway. T…
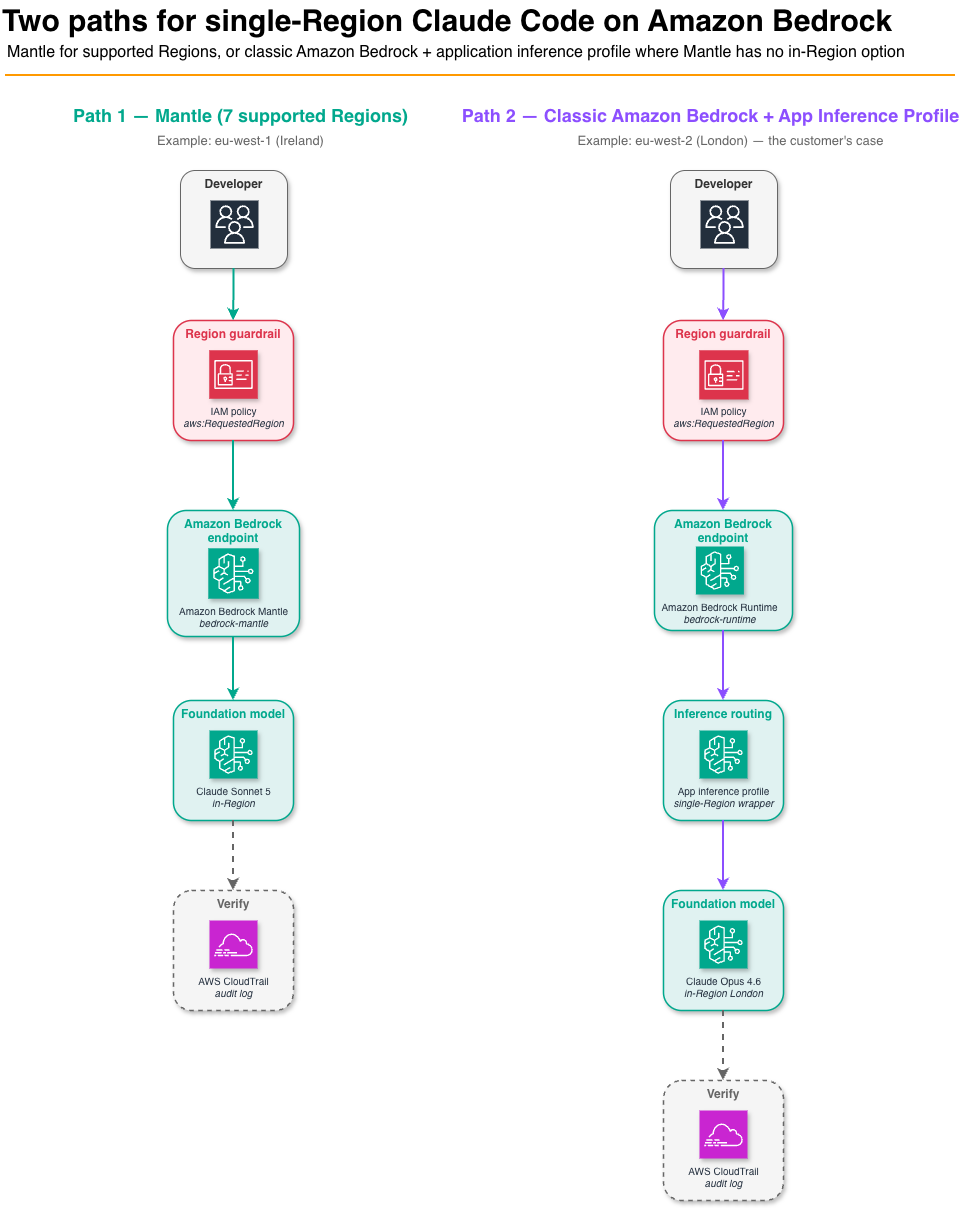
A regulated customer needed all Claude Code inference processed in a single AWS Region (London), not just in-geography. This post shows two ways to pin Claude Code on Amazon Bedroc…
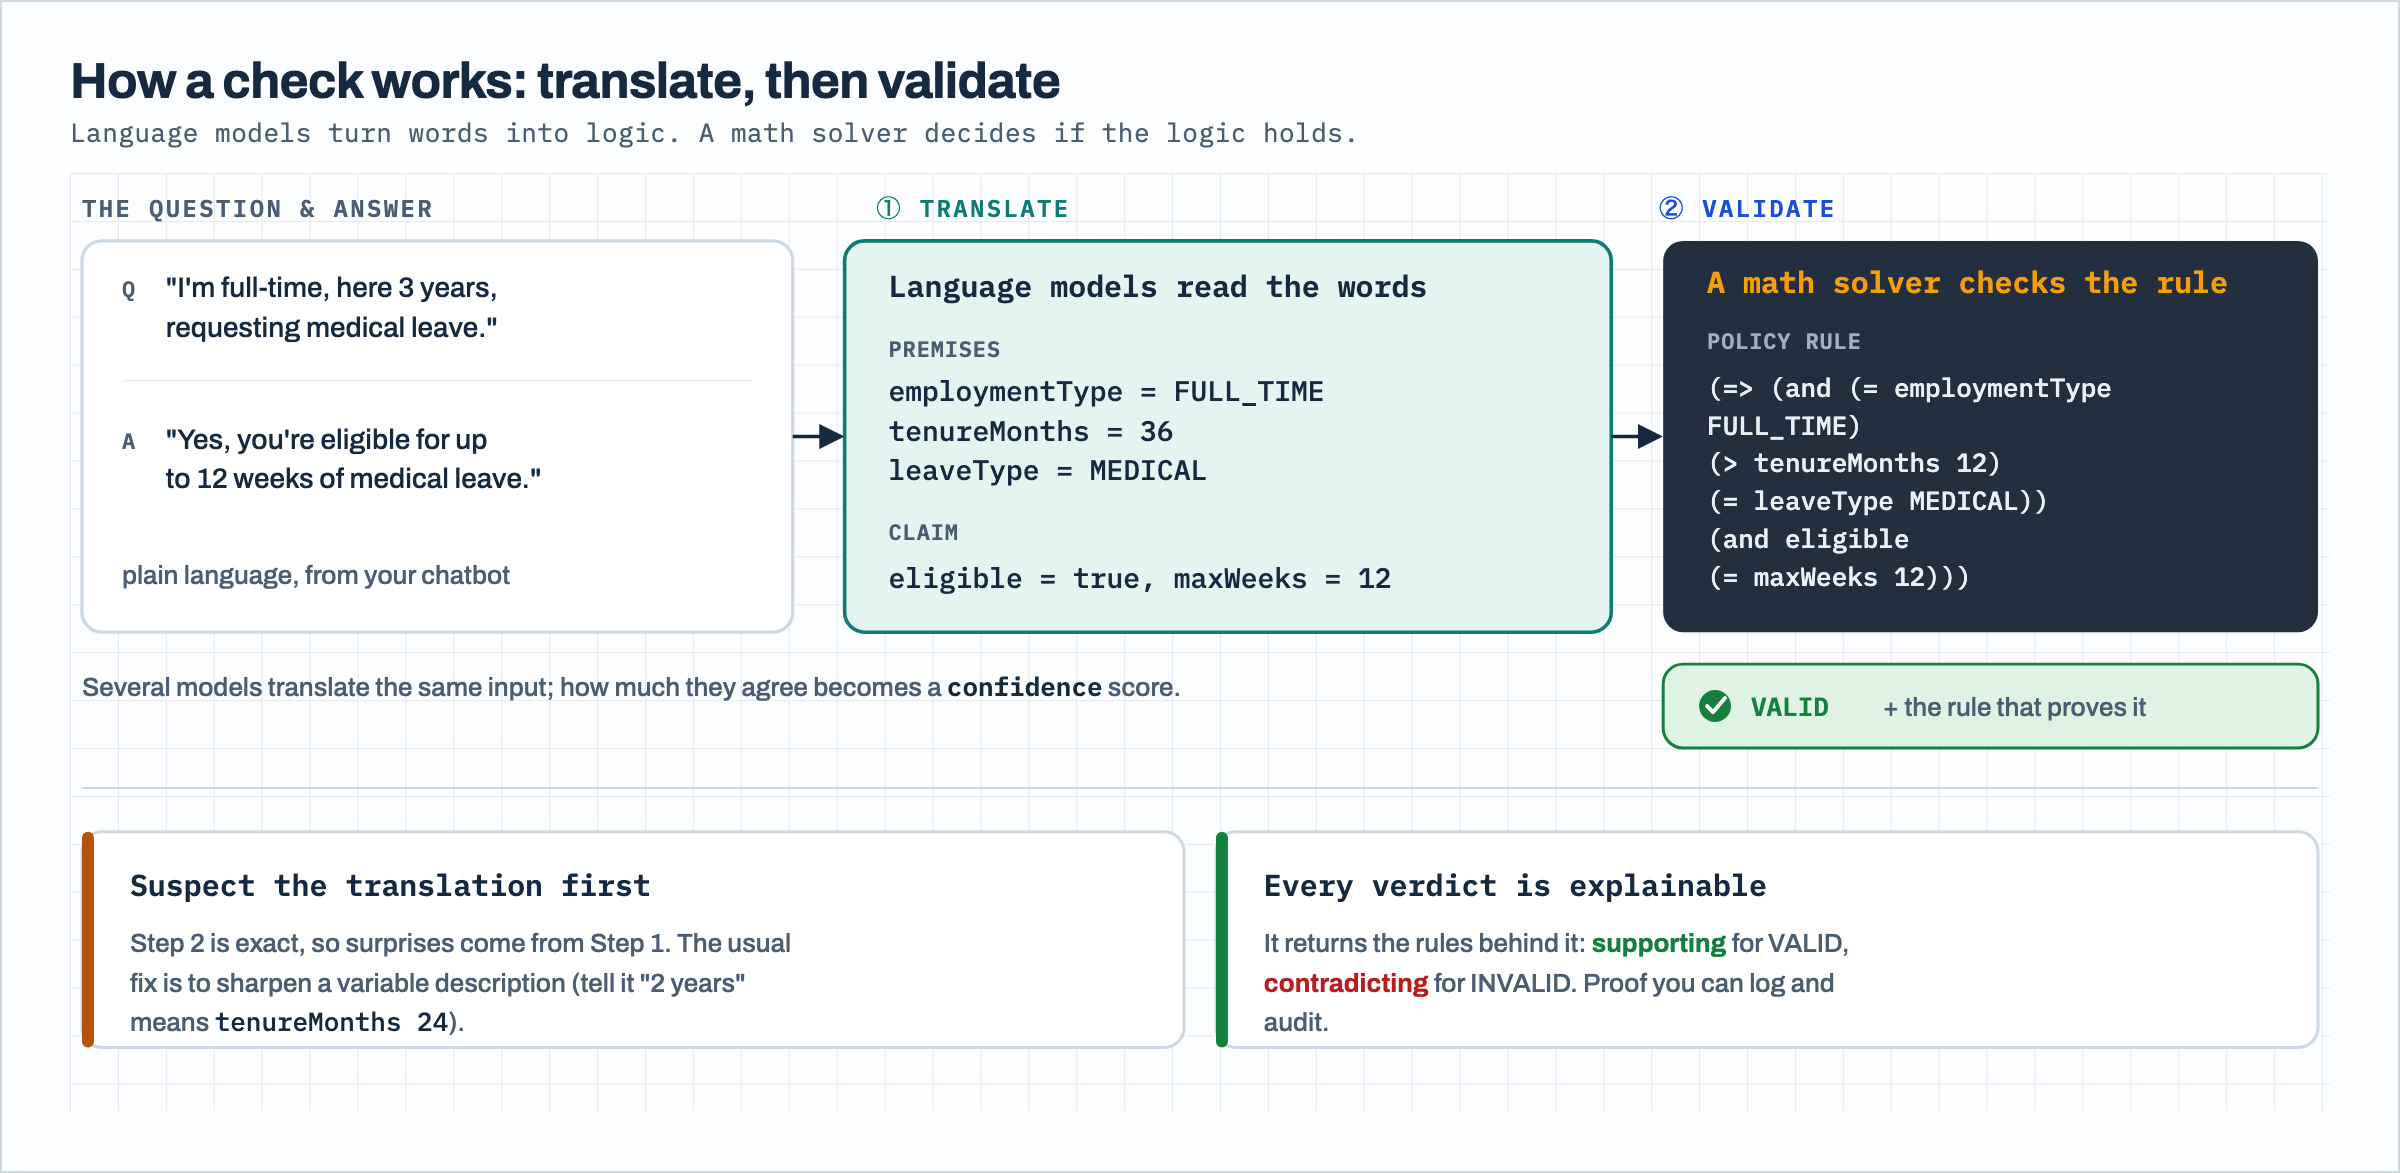
Learn how to run the full Amazon Bedrock Automated Reasoning policy lifecycle from your coding agent. A suite of open source Agent Skills builds, reviews, tests, debugs, deploys, a…
Today, I’m talking with Gaby Del Valle, a policy reporter here at The Verge, about the growing backlash against AI data centers. Gaby recently reported a fantastic piece about Hern…
On-Policy Distillation (OPD) is emerging as a promising alternative to reinforcement learning for LLM post-training, yet its effectiveness in multilingual settings remains underexplored. We study OPD…
Vision-Language-Action (VLA) models have become a powerful paradigm for robot manipulation, but training a single generalist policy for heterogeneous robot embodiments remains an open problem. Existin…

Some creators fear the EU AI Act’s regulatory chaos will upend their lucrative businesses. Others are owning it by incorporating AI transparency into their creative process.
Leading open text-to-image models often carry complementary strengths: one may lead on preference-aligned aesthetics while another follows compositional instructions more faithfully. However, differen…
On-Policy Self-Distillation (OPSD) has become a standard post-training approach for improving visual reasoning in multimodal large language models (MLLMs). Existing methods draw privileged information…
Once visual content enters an AI pipeline, its owner often retains little technical control over how it is used. Legal and regulatory remedies can address misuse, but many technical interventions must…
Privileged on-policy distillation provides dense supervision for multi-turn agents by allowing a synchronized teacher to re-score the student's response at every turn with access to training-only refe…
On-policy distillation (OPD) provides dense teacher supervision on student-generated trajectories, but standard reverse-KL training can assign insufficient probability to other plausible continuations…
Generative Flow Networks (GFlowNets) have emerged as a flexible framework for amortised inference over discrete and mixed discrete-continuous objects, requiring only an unnormalised target density spe…
Tech companies and developers have been scouring the U.S. for places to build data centers, and they’ve been drawn to Texas’ loose regulations and seemingly abundant power supply.…
欧盟《人工智能法案》的核心透明度条款正式生效,标志着全球首部全面监管人工智能的法律进入实质执行阶段。根据新规,聊天机器人等交互式系统必须明确告知用户其正在与人工智能而非人类互动;利用AI生成或修改的图像、视频、音频及文本内容,须进行清晰标识并附带机器可读的数字标记。(新浪财经)
AI 点评 · 全球首部全面AI法案落地,透明度规则将重塑行业合规标杆。
On-policy training has emerged as a powerful post-training paradigm for improving the reasoning capabilities of large language models, and is often enhanced by golden trajectories from stronger expert…
On-policy distillation, in which a teacher corrects samples that the student itself generates, presupposes that the two models speak the same language: identical VAE latents, matching architectures, a…
On-Policy distillation (OPD) transfers teacher capabilities by supervising student-sampled trajectories with dense token-level teacher signals. Recent selective OPD methods improve this process by pri…
World Action Models (WAMs) augment robot policies with action-conditioned predicted futures, but a plausible future alone does not justify changing the action that a bimanual policy would execute. We…
Cognitive AI seeks to move beyond language generation and autonomous task execution toward systems capable of sustained reasoning, adaptive behavior, persistent memory, and self-regulation. While gene…
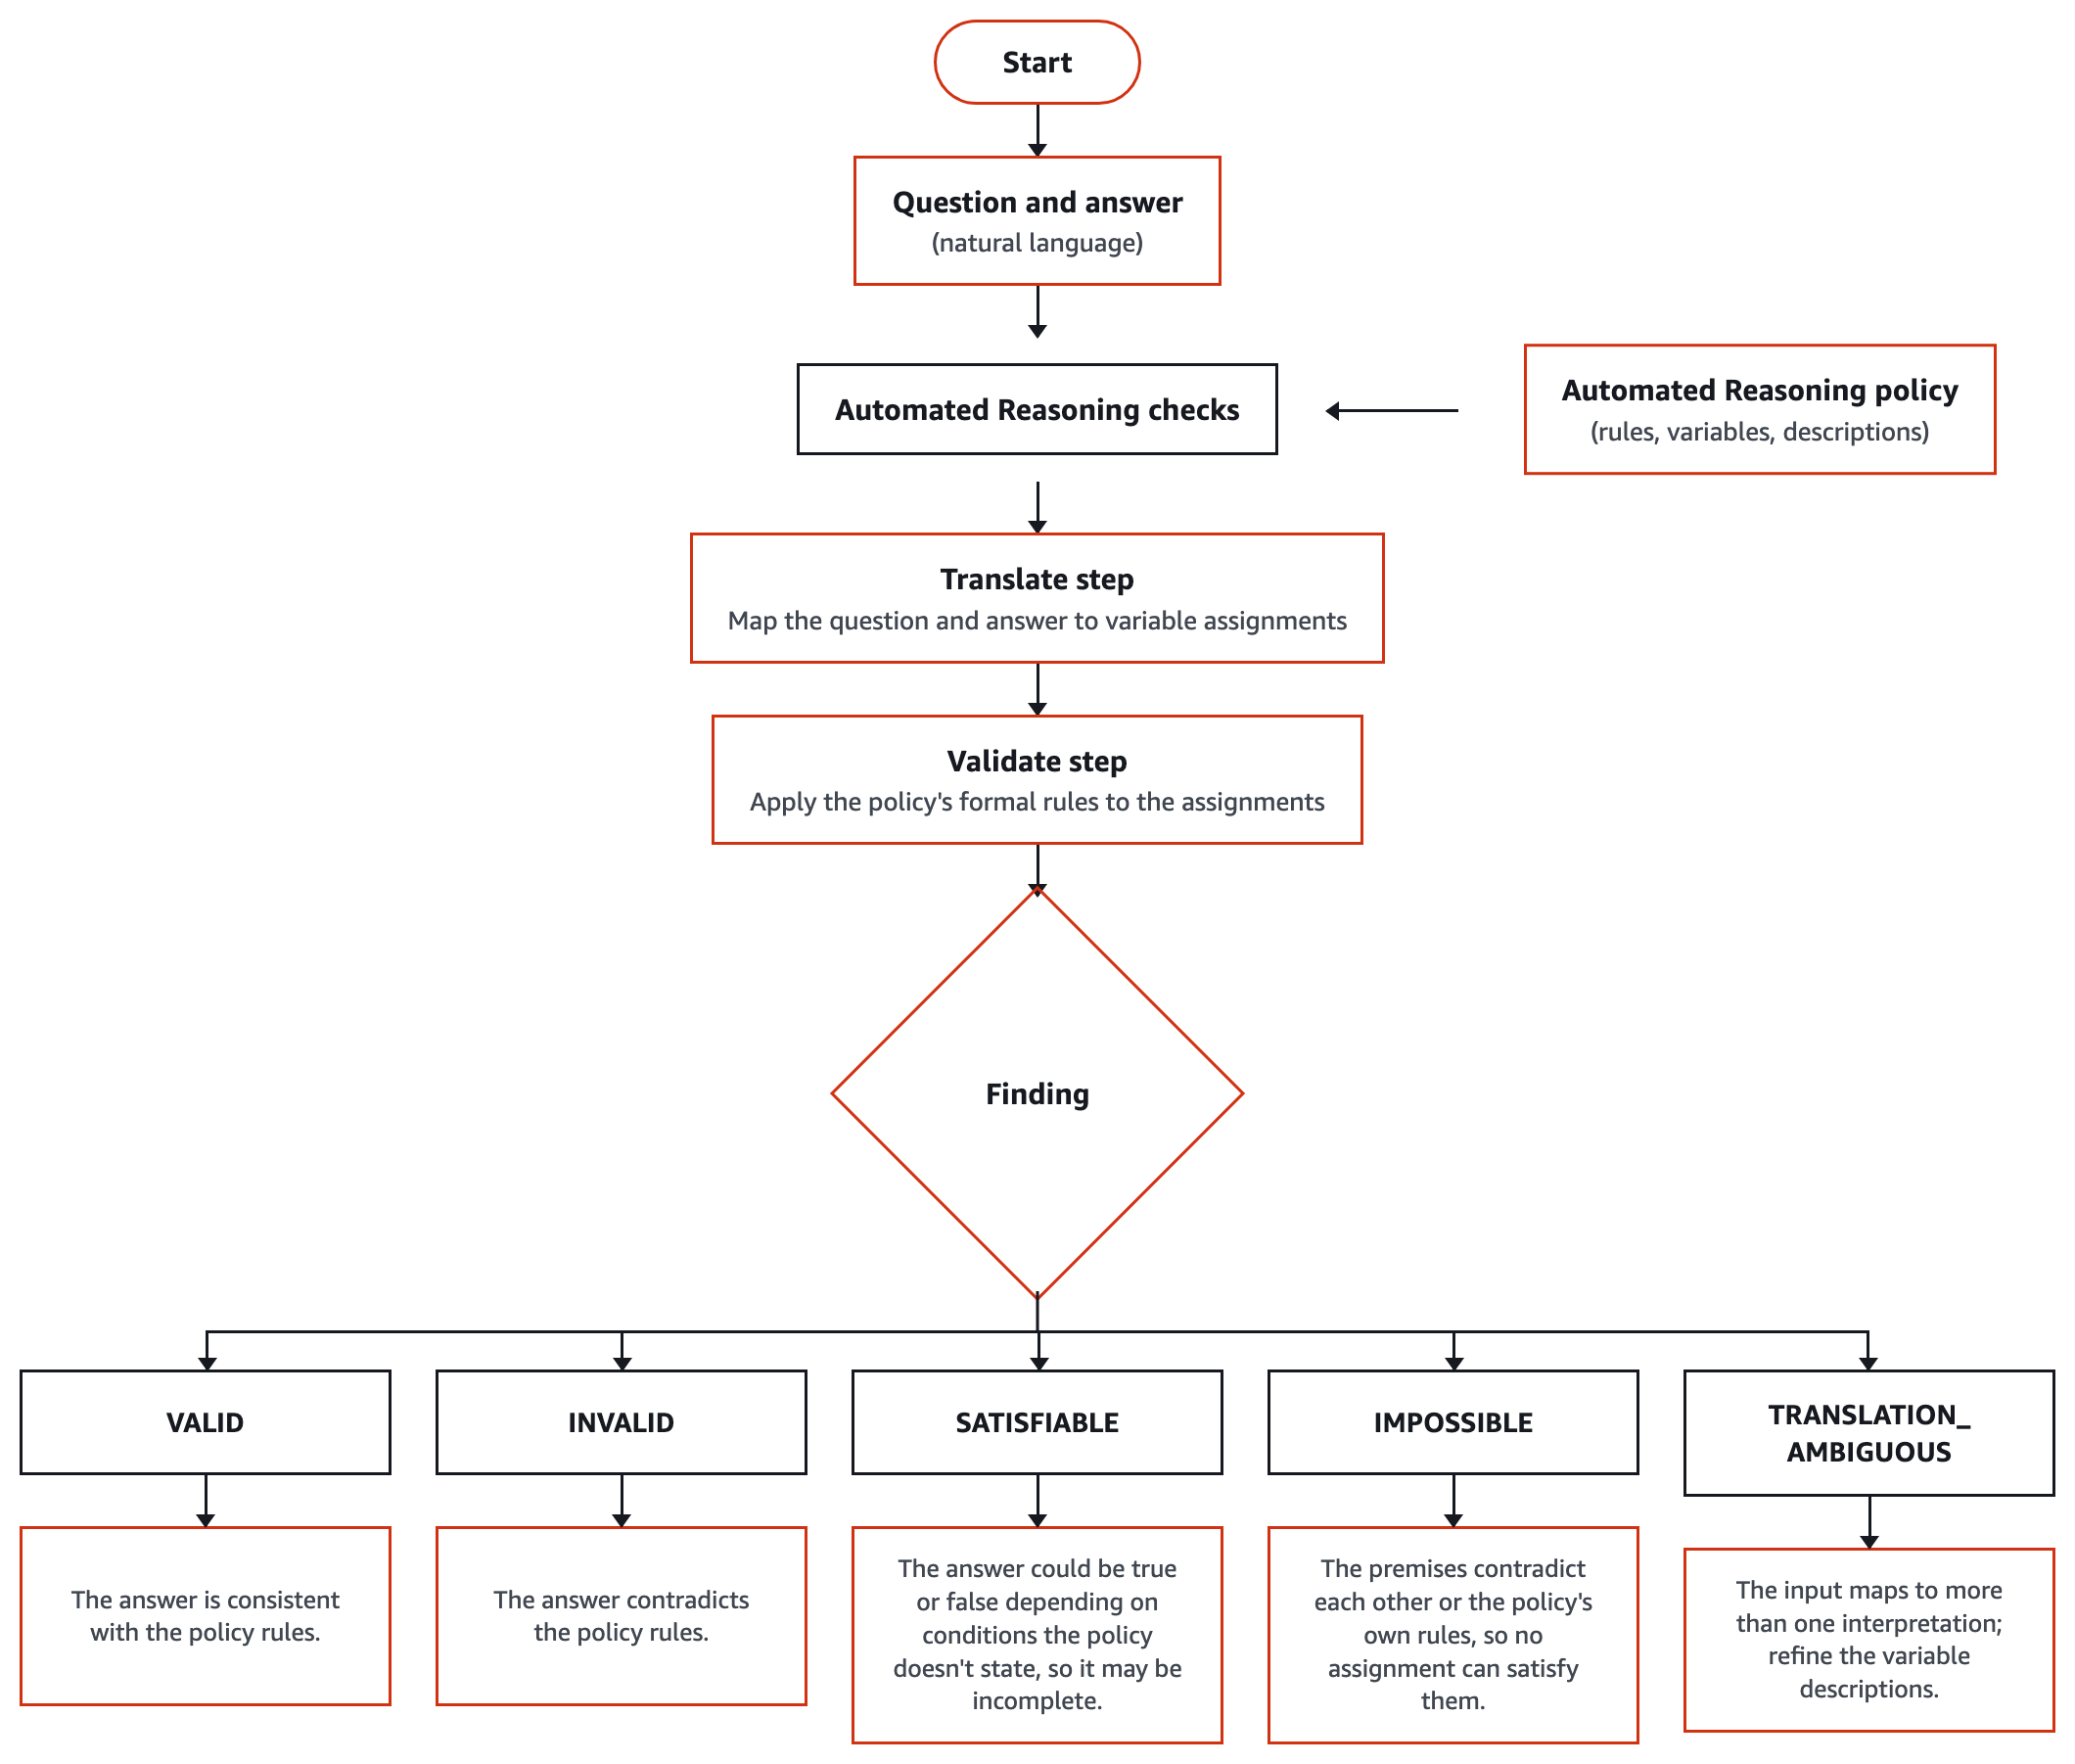
Amazon Bedrock now supports automatic Automated Reasoning policy refinement. The refinement engine diagnoses failing tests and proposes formal-logic fixes for rule issues and langu…
AI 点评 · 自动修复策略缺陷,大幅降低AI规则调试门槛。
On-policy (self) distillation (OPSD) is increasingly adopted for language-model post-training. It strengthens the teacher with privileged information but can induce a privilege illusion: the student l…
World Action Models (WAMs) couple action generation with prediction of future states. Their effectiveness depends on whether future dynamics are modeled in a space that is both aligned with action gen…
Reinforcement learning with verifiable rewards (RLVR) has become a standard paradigm for post-training large language models (LLMs). While Group Relative Policy Optimization (GRPO) is widely adopted,…
Imitation learning (IL)---training an agent to replicate expert behavior from demonstrations---underpins applications from robotics to language model training. Standard approaches such as Behavior Clo…
A fundamental challenge of vector search is achieving consistently high recall while minimizing computational costs. Fixed search parameters cause significant performance variance across queries, and…
Parameter-Efficient Fine-Tuning (PEFT) commonly adapts large language models using a single shared Low-Rank Adapter (LoRA). This shared optimization space often suffers from interference when adapting…
This paper studies the policy gradient update for a multi-arm bandit problem in diffusion environment that is described by a stochastic differential equation (SDE) under the continuous-time reinforcem…
Reinforcement learning with verifiable rewards (RLVR) broadcasts a single response-level reward to every token, while on-policy distillation (OPD) scores each token against a stronger teacher for a de…
We show that on-policy reinforcement learning with verifiable rewards (RLVR) can improve the current objective while making successful behaviors for later objectives too rare to sample and reinforce.…
Multimodal on-policy distillation (OPD) transfers fine-grained visual knowledge by supervising student-generated trajectories with a privileged-view teacher. Yet its next-token corrections are source-…
🔥 On-Policy Self-Distillation in Diffusion Models
On-policy distillation (OPD), which aligns a student with the teacher's token-level distribution on the student's own rollouts, is an effective paradigm for transferring capabilities across LLMs. Prev…
Anthropic’s Responsible Scaling Policy Anthropic
Updates to Consumer Terms and Privacy Policy Anthropic


