行业动态NEW
6 小时前
Google has joined Amazon in releasing a developer tool that makes it easy for PyTorch users to move their apps off Nvidia GPUs.
AI 点评 · 云厂商联手降低开发者迁移门槛,英伟达GPU生态壁垒正被逐步瓦解。
共 223 条相关资讯 · 来自历史归档
Google has joined Amazon in releasing a developer tool that makes it easy for PyTorch users to move their apps off Nvidia GPUs.
AI 点评 · 云厂商联手降低开发者迁移门槛,英伟达GPU生态壁垒正被逐步瓦解。
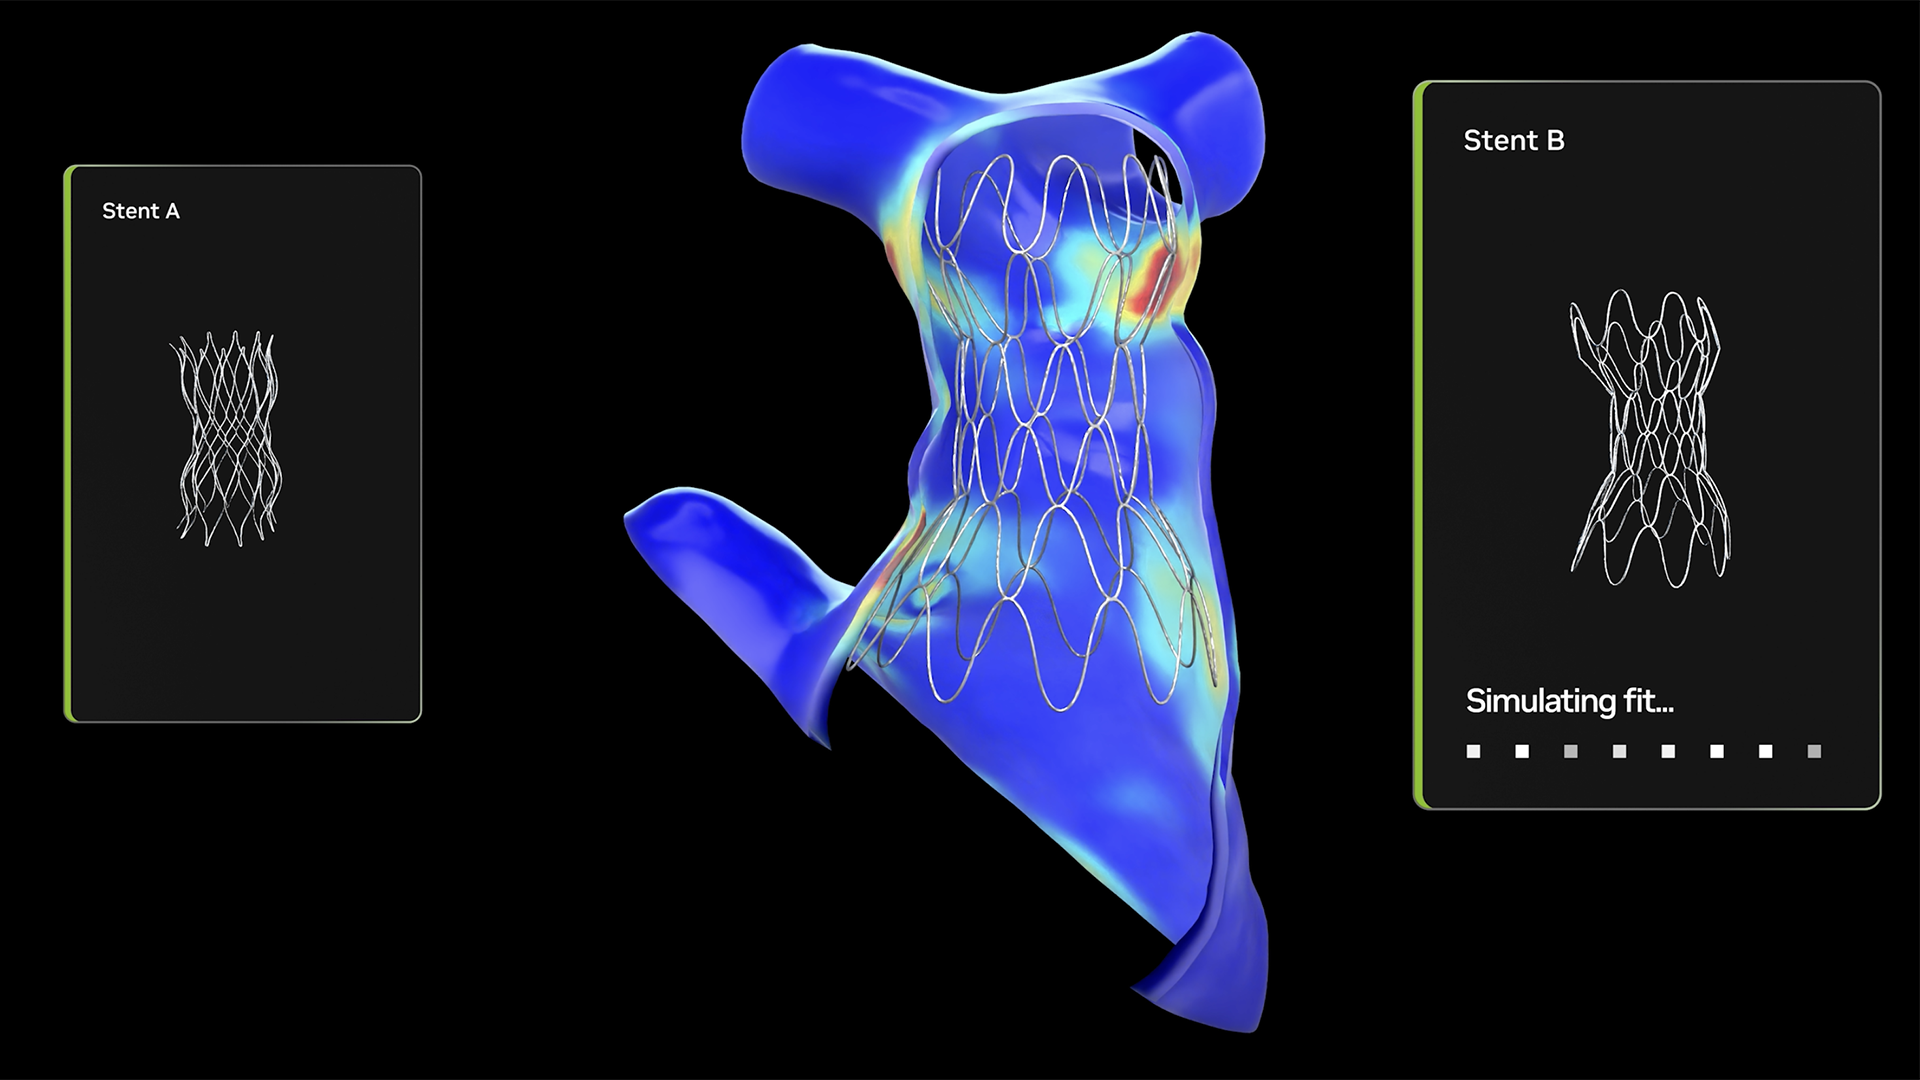
AI 点评 · 生成式仿真切入临床手术训练,医疗AI从诊断辅助迈向高保真操作模拟,值得关注。
DeepSeek has open-sourced DeepInfer, the Apache 2.0 inference framework that serves DeepSeek-V4.1-Flash in production. It targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, and…

IT之家 10 月 20 日消息,当地时间 10 月 19 日,亚马逊宣布推出开源工具 TorchNeuron,借助该工具,开发人员编写的 PyTorch 代码可以在亚马逊的自研 Trainium 芯片上本地运行, 只需更改一次配置,无需重写 。 IT之家获悉,TorchNeuron 将于当地时间 10 月 20 日在加州圣何塞举行的北美 PyTorch 大…
AI 点评 · 亚马逊用开源工具降低PyTorch迁移门槛,直击CUDA生态护城河,自研芯片竞争进入软件层。
Amazon wants to break Nvidia’s hold on PyTorch, the free toolkit used to build most AI apps, so that more developers run their apps on alternative chips like its own.
AI 点评 · 亚马逊借开源工具切入PyTorch生态,直指英伟达软件护城河,AI芯片竞争从硬件转向开发者入口。
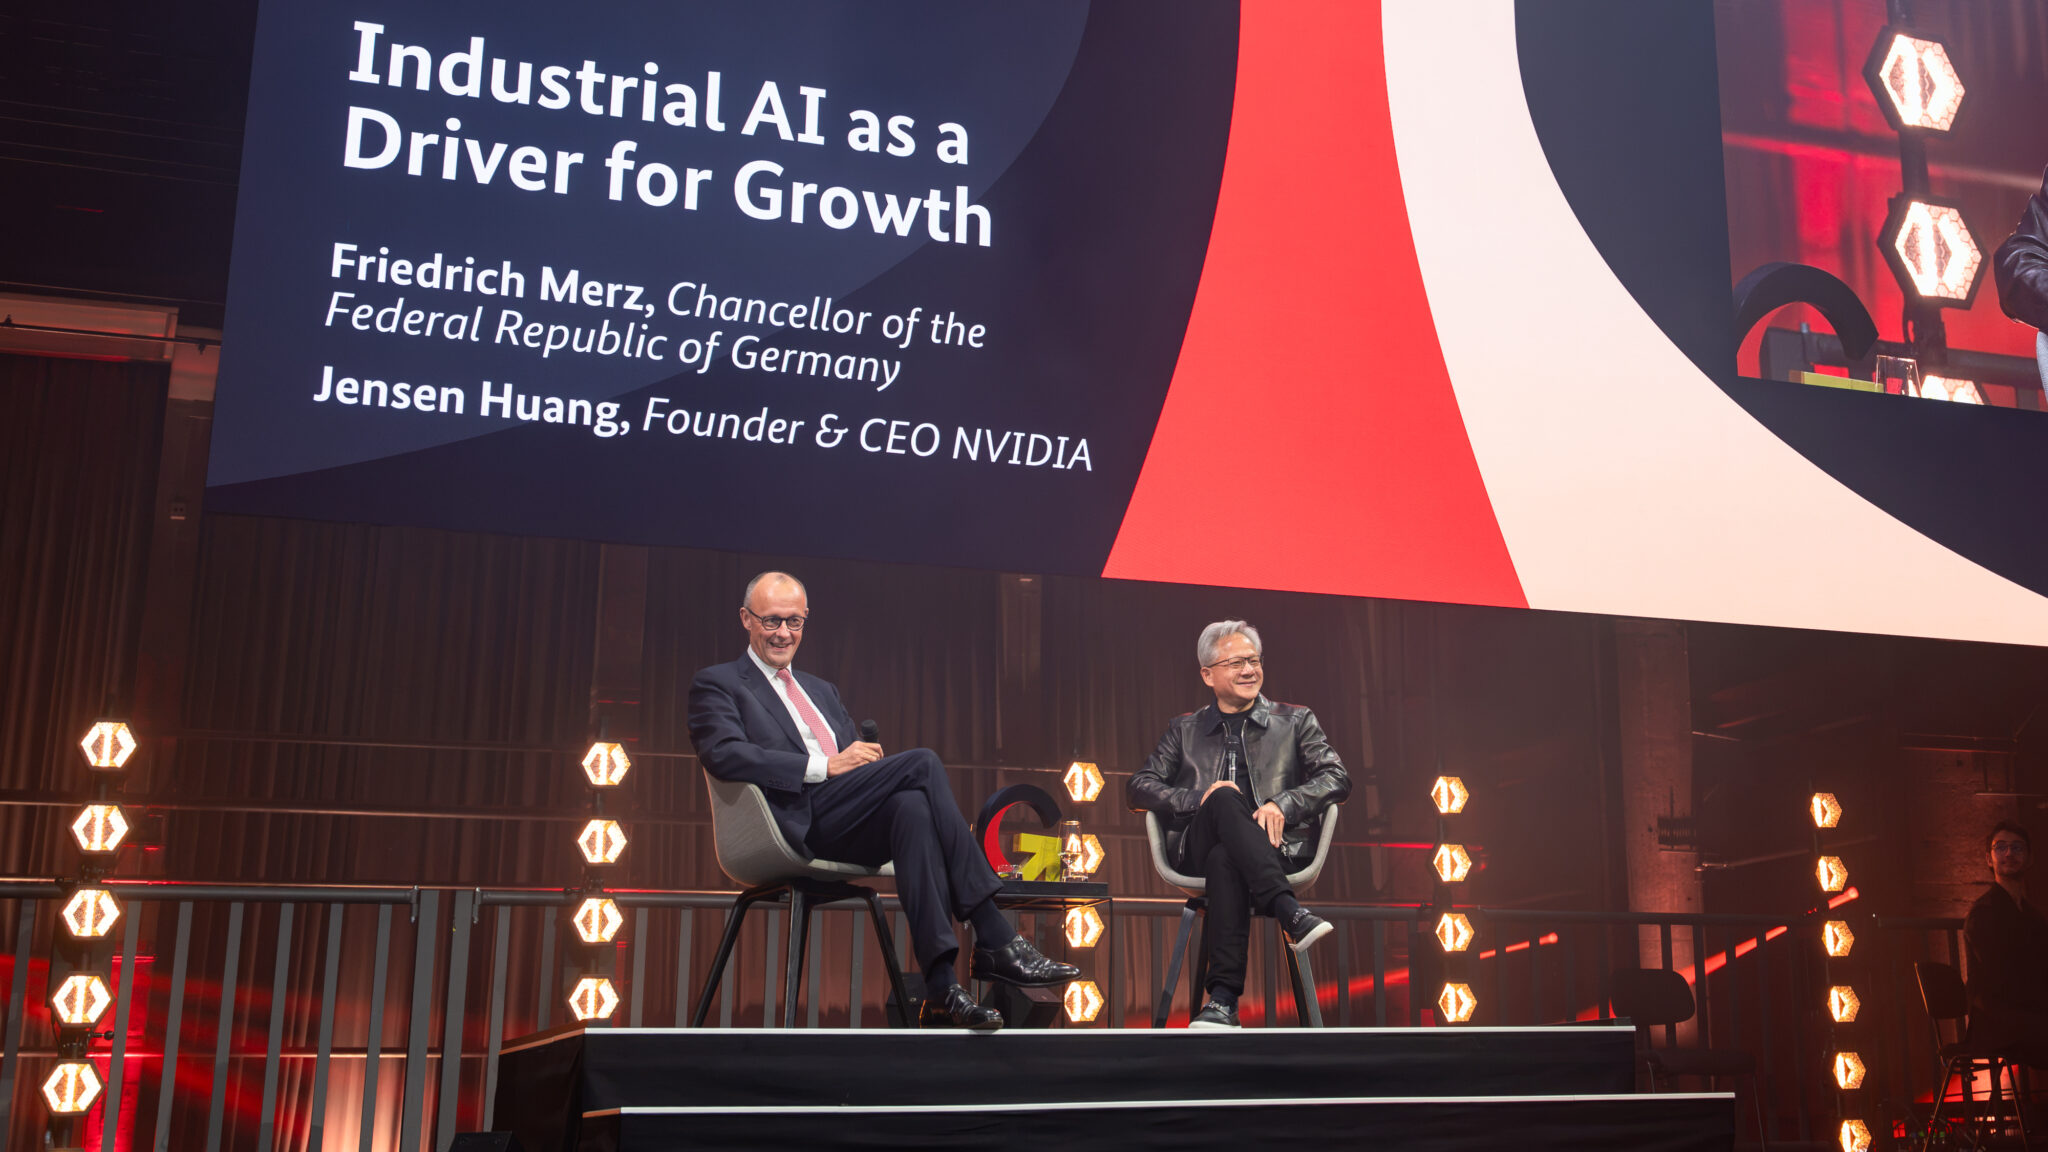
In the cavernous hall of Kraftwerk, a former power station in Berlin, German Chancellor Friedrich Merz and NVIDIA founder and CEO Jensen Huang sat down to discuss Germany’s AI road…
AI 点评 · 德国借英伟达算力押注工业AI,欧洲制造业智能化竞赛或就此提速。
After drawing acquisition interest earlier this year, the Nvidia challenger raised $1.5 billion to remain independent.
AI 点评 · 开源芯片挑战英伟达获巨额融资,估值飙升显示资本押注AI硬件多元化。
Nvidia is leaning hard into the trend of enterprise companies wanting to run their own open models in their own data centers and also trying to make on-device, private AI agents a…
After stock crashes and Firmus's scrapped IPO, industry executives expect only seven to ten of the hundreds of AI cloud providers to survive. CoreWeave lost a quarter of its market…
NVIDIA has released the full Run:ai GPU orchestration platform as open source under Apache 2.0. The release includes KAI Scheduler, CUDA 13.4 GPU fractioning, quota management, and…
In this tutorial, we implement Structured Data Models, NVIDIA’s new library that puts several pretrained foundation models for tables behind one PyTorch interface, and use it to ma…
NVIDIA RTX Spark laptops are now available, bringing NVIDIA Blackwell RTX graphics, up to 128GB of unified memory and the full NVIDIA AI platform to slim, premium Windows PCs. Star…
AI 点评 · 轻薄Windows本首次搭载Blackwell架构与128GB统一内存,AI算力下放至移动端,值得关
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks lik…
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks lik…
Nvidia's RTX Spark N1X processor is finally here, and we've been collectively testing a small fortune's worth of powerful laptops sporting this new "superchip." RTX Spark is design…

NVIDIA released Nemotron 3.5 Super VL, an open 120B-parameter multimodal MoE model with 12B active parameters, 1M-token context and NVFP4 weights that run on 1 DGX Spark, plus 2 Bo…
AI 点评 · 英伟达开源120B多模态智能体模型,稀疏激活仅12B,单机可跑,或将重塑开源多模态格局。
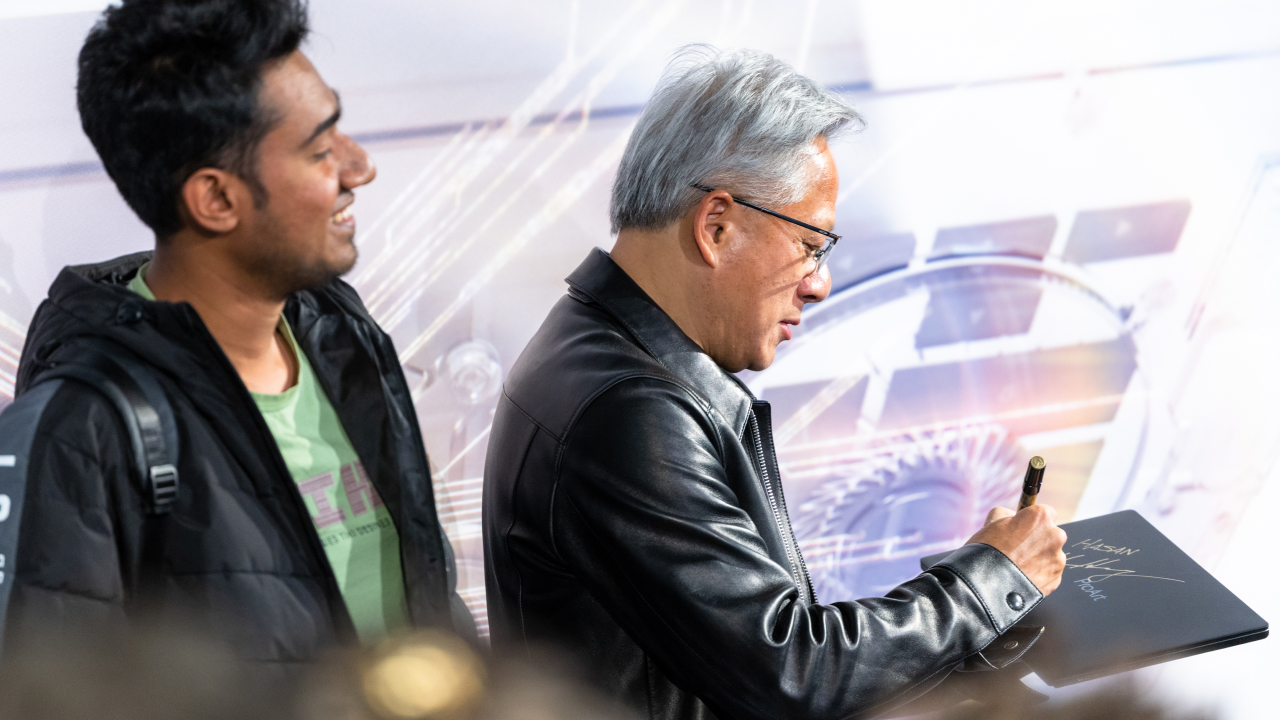
A new beginning for Windows PCs starts tomorrow with the launch of NVIDIA RTX Spark — one PC built for creators, gamers and AI agents. All are invited to celebrate with NVIDIA and…

With Nemotron 3.5 Super VL, Nvidia is releasing an open multimodal model with 120 billion parameters for enterprise agents. Two compact Bolt models bring agents to local machines.…
Microsoft and Nvidia held a launch party for the first wave of RTX Spark laptops last week in San Francisco, where a new wave of AI PCs took center stage amid a packed crowd and a…
Nvidia CEO Jensen Huang announced $2 billion in European investments and new stakes in French startups like Doctolib and Entalpic. The UK gets $250 million in compute for AI agent…

Keeping a city running means making decisions that affect residents every day — from when to repair a road to how to use energy more efficiently. Across the EMEA region, cities and…
When Nvidia originally showed off DLSS 5 earlier this year, the technology immediately got branded as gen AI for video games. To gamers, Nvidia had lost the plot. I personally coul…
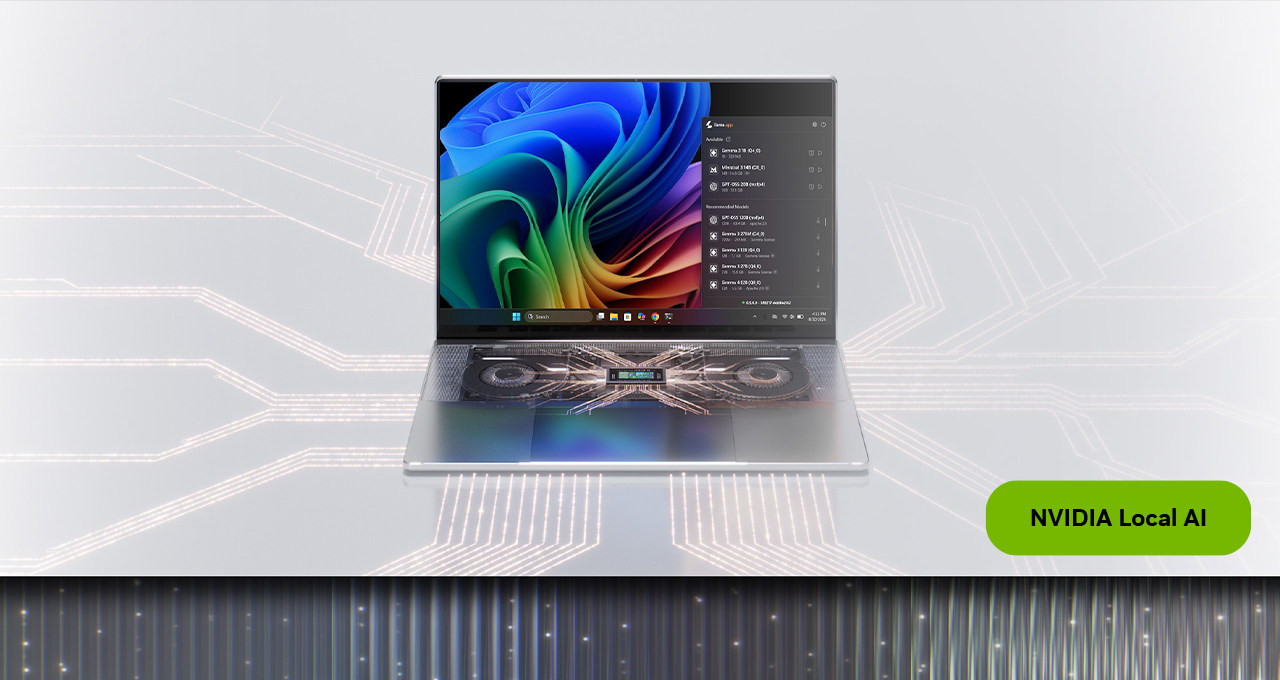
NVIDIA RTX Spark is a new beginning for the PC — a reinvention combining the capabilities of a gaming PC, a creative studio and a personal AI supercomputer into a single superchip.…

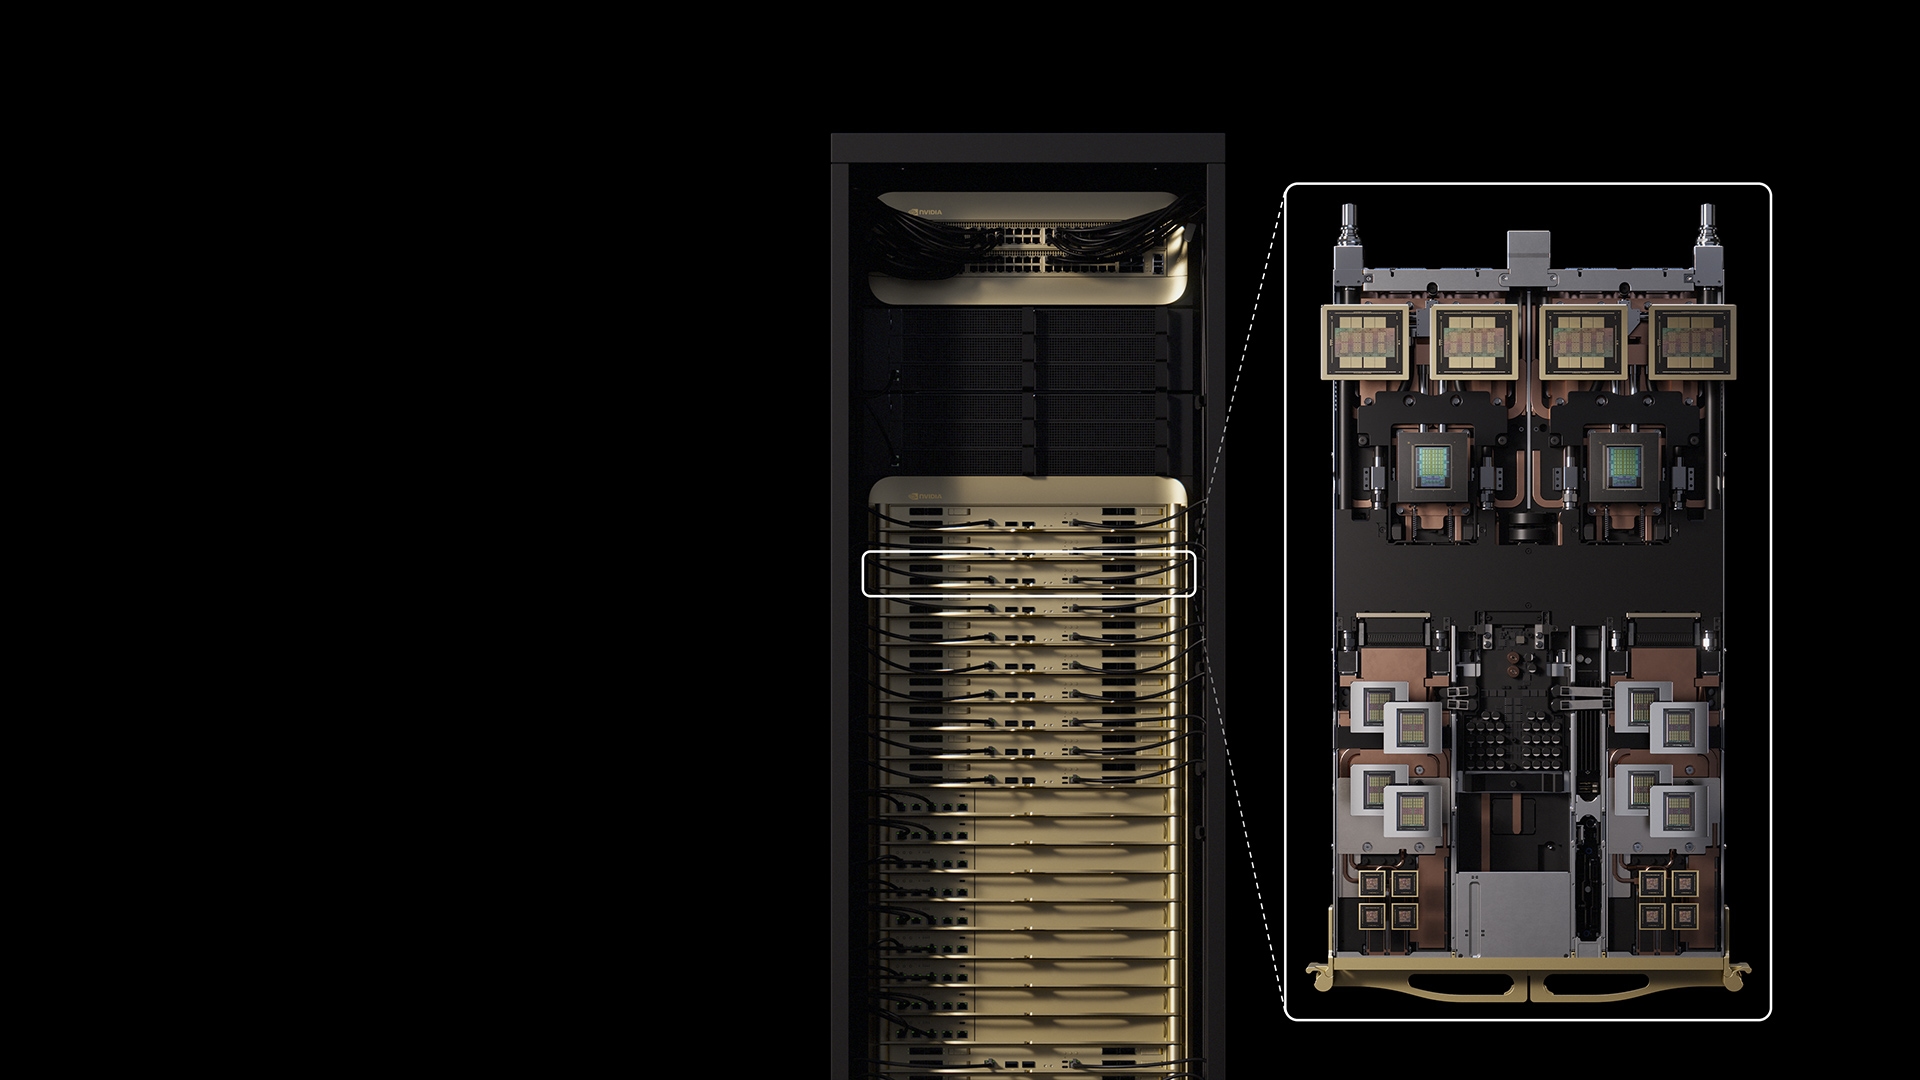
IT之家 10 月 12 日消息,英伟达昨日(10 月 12 日)发布公告,在开放计算项目(OCP)全球峰会上,英伟达宣布开放 Vera Rubin 机架与计算托架设计, 并与 Cisco、Google、Meta、Microsoft、Visionbay 等发布多项 AI 基础设施开放标准。 在本次 OPC 全球峰会上,英伟达宣布通过开放 NVIDIA MGX…
AI 点评 · 英伟达开放机架设计,意在让AI工厂像服务器一样标准化,降低自建门槛。
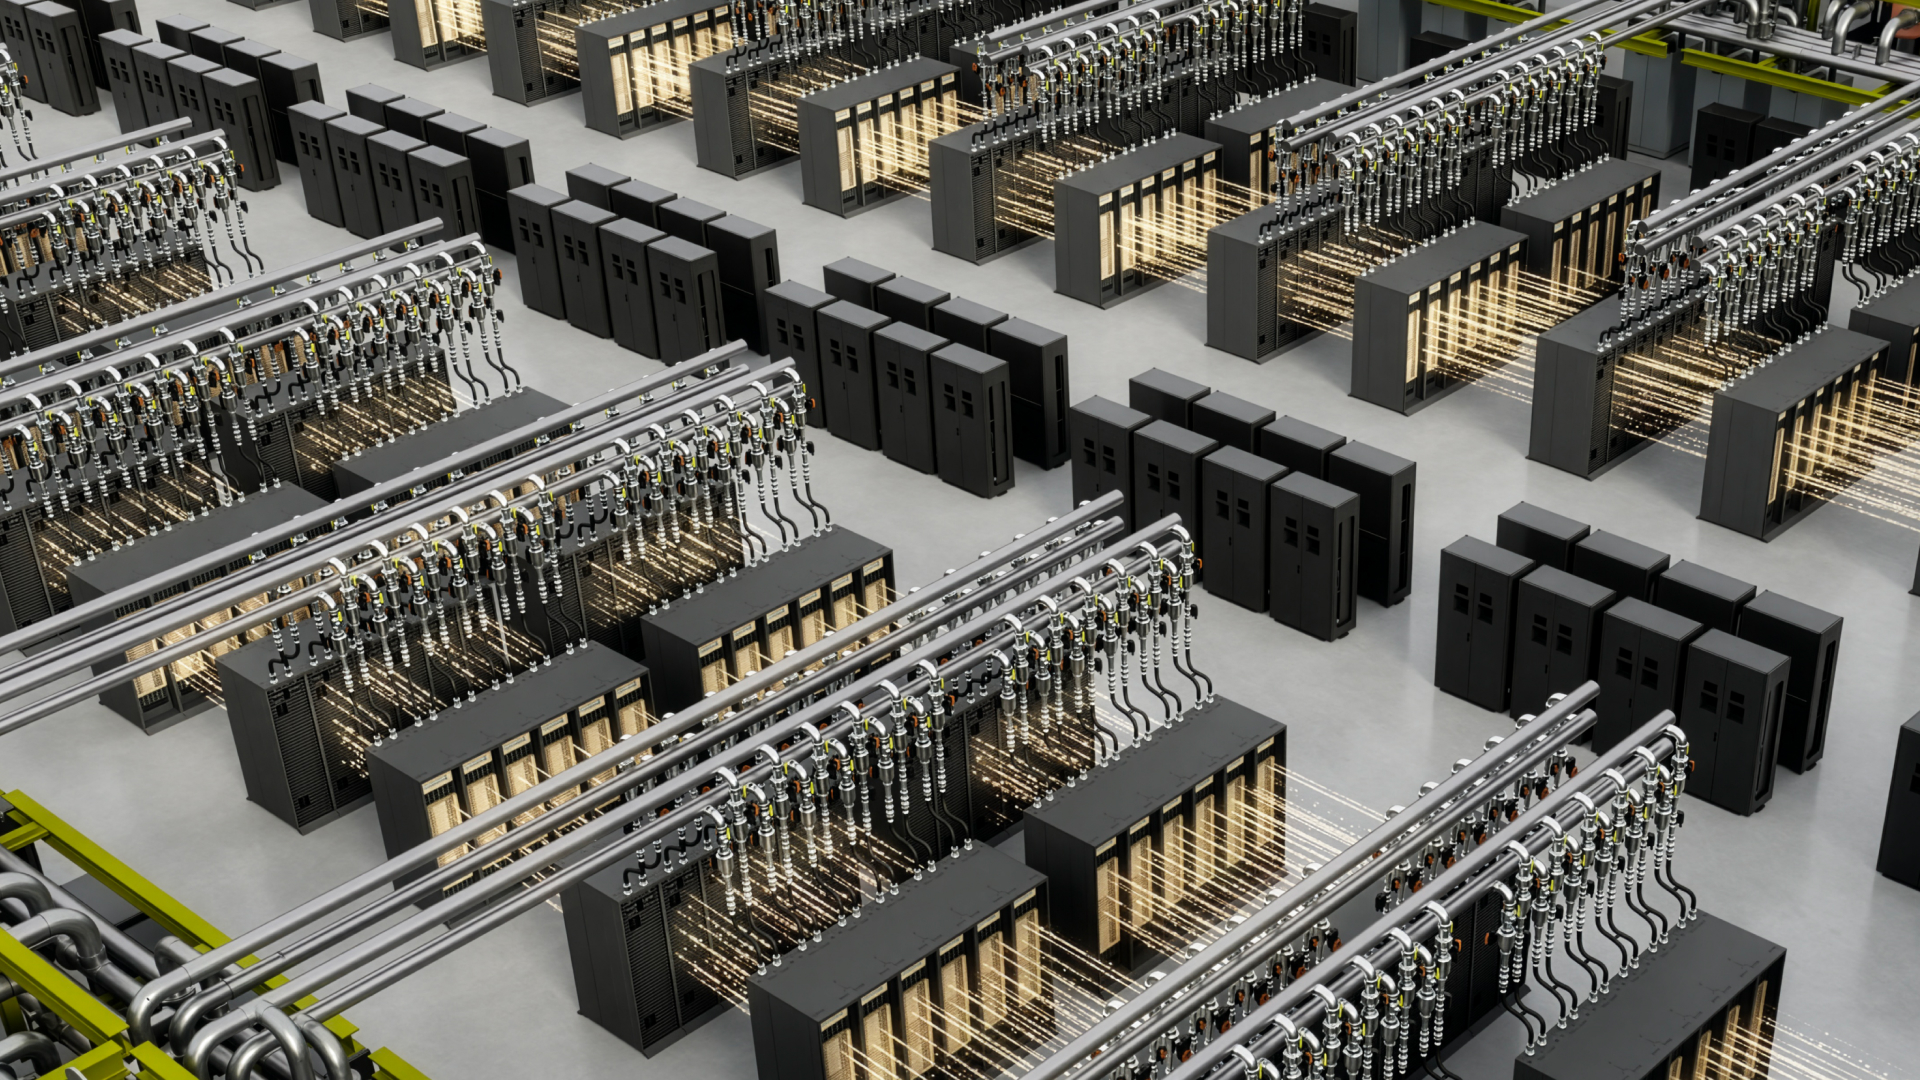
As AI factories grow from megawatts to gigawatts, building them takes more than advanced computing. Open standards are helping the industry scale AI infrastructure faster, more eff…
Microsoft is announcing its third-generation Maia in-house AI chip today, designed to be the "primary AI inference system" for Microsoft's products and services. Maia 300 not only…

IT之家 10 月 12 日消息,根据 HPE(慧与)向 The Next Platform 等外媒分享的演示文稿,这家企业确认其 ProLiant DL585a Gen13 服务器 支持 NVIDIA(英伟达)的 Rubin PCIe GPU 。 ▲ 引自:The Next Platform NVIDIA 的现有 Rubin GPU 属于数据中心级产品,采…
AI 点评 · 英伟达把数据中心级算力做成标准PCIe插卡,企业升级门槛大幅降低。
AI 点评 · 英伟达若收购开源模型公司,意在补齐软件生态短板,强化对AI全栈控制。
Distributed image and video generation in ComfyUI for two NVIDIA DGX Sparks.
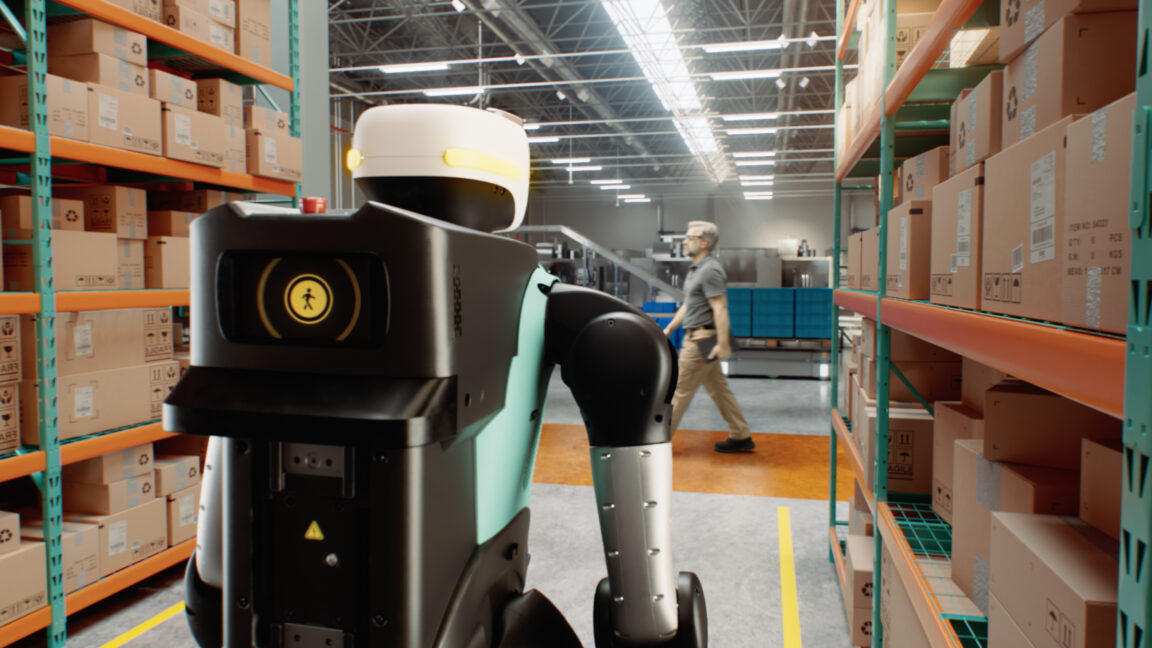
Full-stack safety solution for physical AI is being used by robotics companies.
联想YOGA Pro 15 RTX Spark笔记本电脑,于10月8日9:00正式开启全网盲约。

NVIDIA researchers introduced PivotOPD, an on-policy distillation method that trains multi-turn LLM agents to avoid early pivotal mistakes and recover from them, posting the best a…
Microsoft revealed the specs and price for its Surface Laptop Ultra, AI PCs that run on Nvidia chips that are designed to run AI models and agents.
AI 点评 · 英伟达芯片首次进入微软Surface,AI PC从概念走向本地推理实战,值得关注。
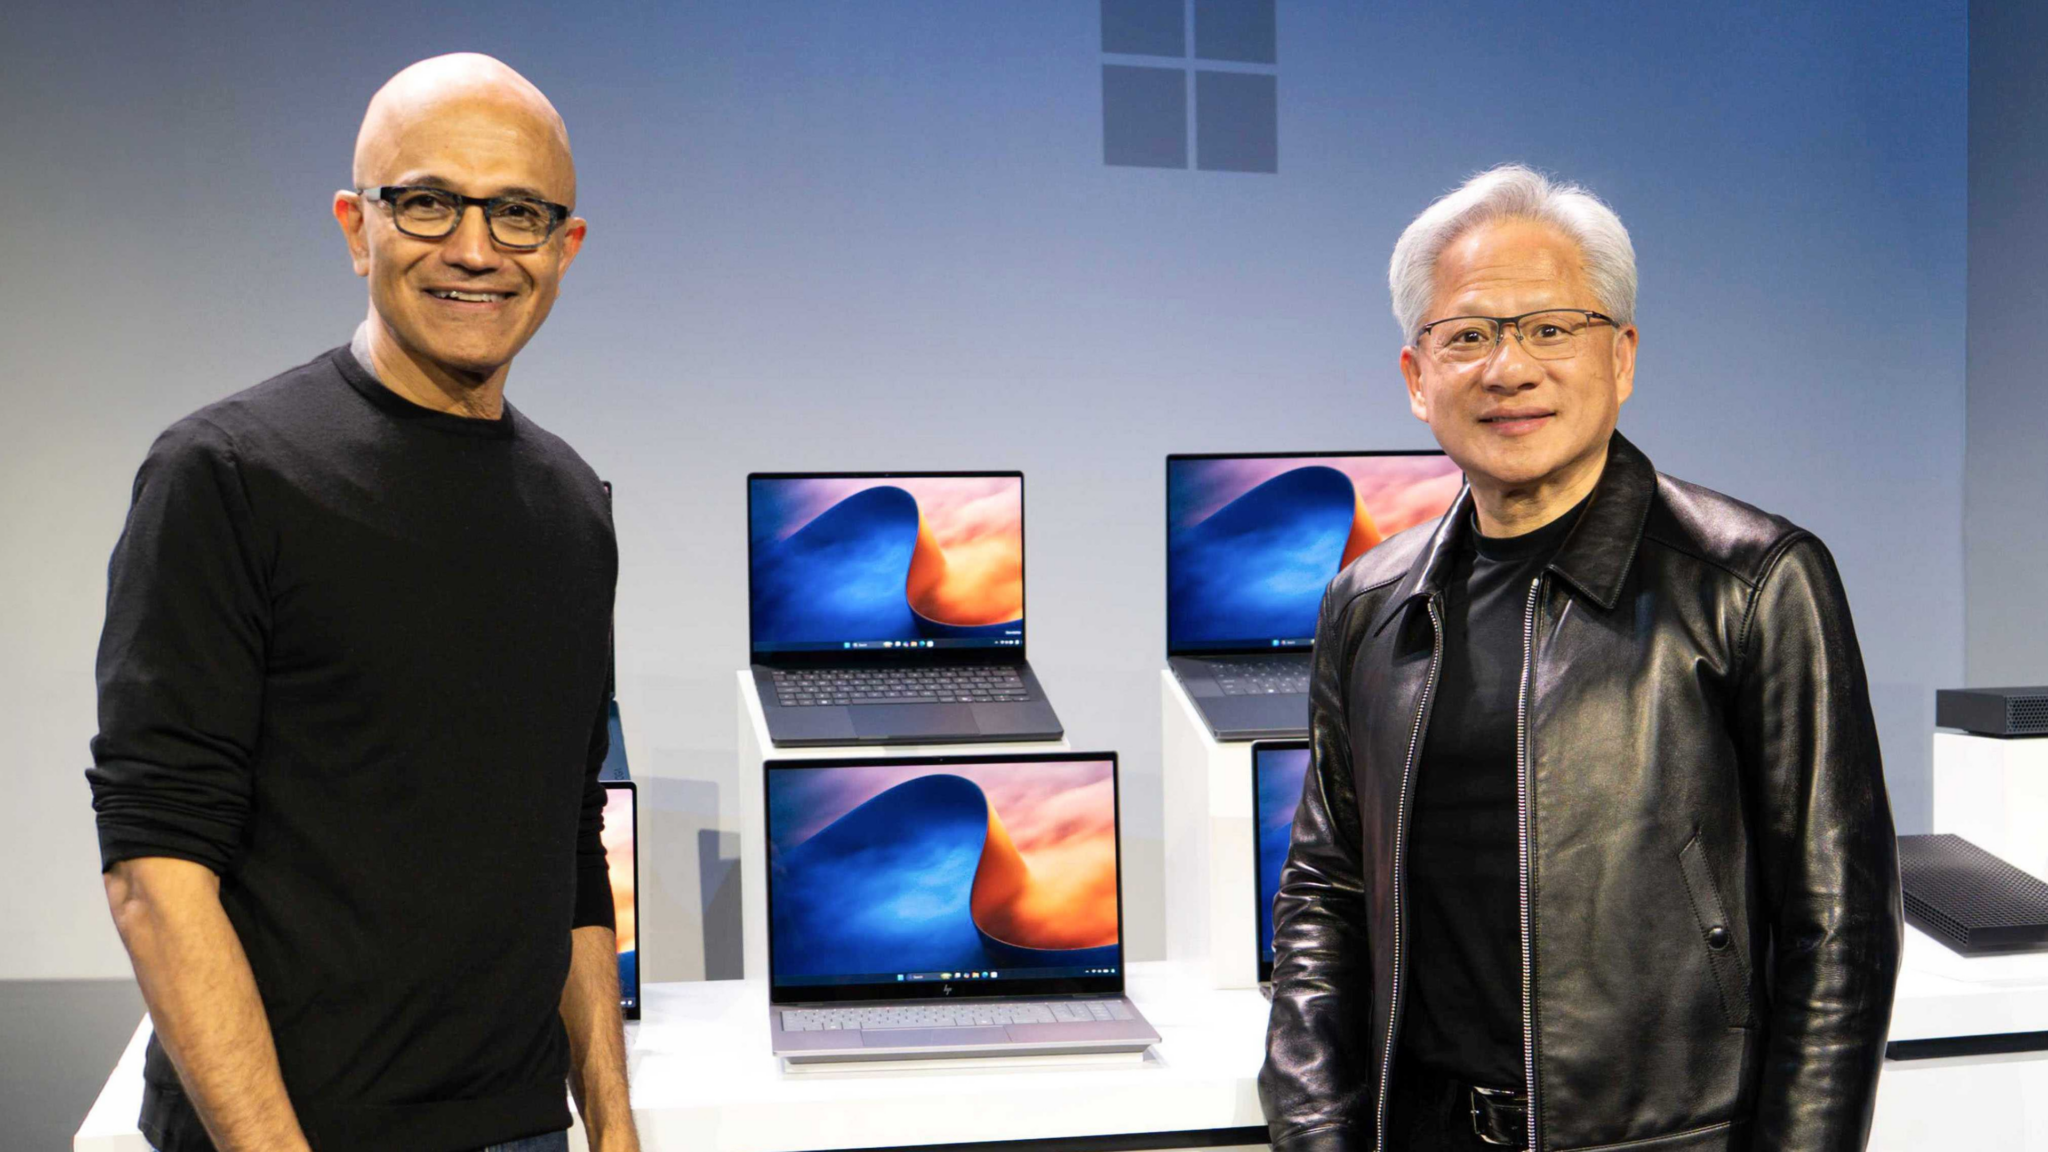
At a Microsoft event in San Francisco on Wednesday, NVIDIA founder and CEO Jensen Huang and Microsoft CEO Satya Nadella outlined how NVIDIA and Microsoft are co-engineering hardwar…
AI 点评 · 英伟达与微软深度整合AI代理与RTX硬件,标志PC从工具转向主动协作平台,或重塑个人计算生态。

Google's AI watermark detector SynthID is now public. Anyone can check whether images, videos, or audio were created by Google's AI or partners like OpenAI and Nvidia. More than 18…
Microsoft's Nvidia-powered Surface RTX Spark Dev Box is available for preorder now and is slated to ship in November for just about $6,000. It's pricier than the DGX Spark mini PC…
From Nvidia and Chime to Obvious Ventures and Anthropic, explore the entire roundtable agenda at TechCrunch Disrupt 2026. Register now to save up to $100 on your pass and get a sec…
Nvidia-backed Lambda is raising up to $4 billion at a $14.5 billion pre-money valuation ahead of a planned 2027 IPO, led by Coatue and Blackstone.
AI 点评 · 英伟达押注的算力新贵冲刺IPO,AI基础设施军备竞赛正烧向资本市场。

IT之家 10 月 6 日消息,综合 CNBC 与《金融时报》报道,Groq 当地时间本周二被告上美国特拉华州衡平法院, 被指控在与 NVIDIA(英伟达)的“类收购”非独家授权交易中牺牲了少数股东的权益 。 原告 Joshua Rubin 和 Benjamin Serebrin 曾是 Groq 的员工,但在与 NVIDIA 的交易前离职。两位员工仍持有 G…
AI 点评 · AI芯片新贵与巨头合作背后的股东博弈,暴露初创退出机制隐患,值得行业警惕。
Discover how to construct an end-to-end streaming robotics learning pipeline using the NVIDIA Cosmos3-DROID dataset without local downloads, leveraging byte-range Parquet reads, be…
Learn how NVIDIA IsaacTeleop turns XR hand tracking and motion controller input into robot commands using a pure Python retargeting engine and NumPy. The post Inside NVIDIA’s Isaac…

The price of anything with memory is skyrocketing thanks to AI. Aging streaming devices are no exception.
AI 点评 · AI抢走内存产能,连七年前的电视盒子都涨价,硬件通胀正蔓延到消费端。
Prime Intellect has launched Prime Inference, an OpenAI-compatible platform for serving frontier open models on NVIDIA Blackwell. Its GLM-5.3 deployment uses Dynamo, vLLM and NVFP4…
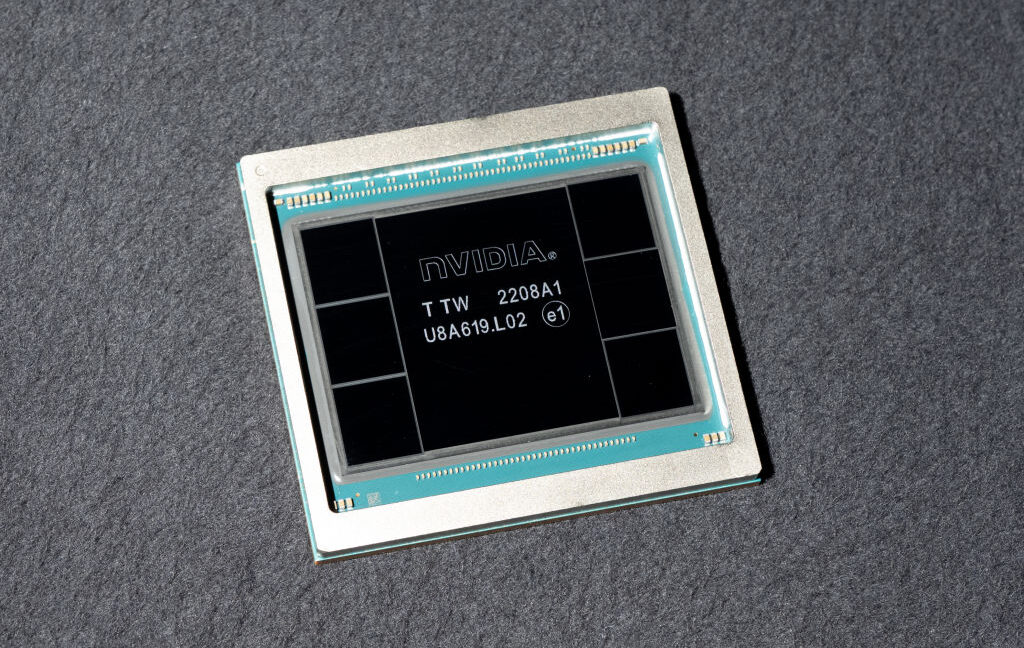
Nvidia’s chip-smuggling problem won’t go away as arrests continue.
AI 点评 · 芯片走私规模惊人,出口管制形同虚设,巨头供应链漏洞正被逐一揭开。
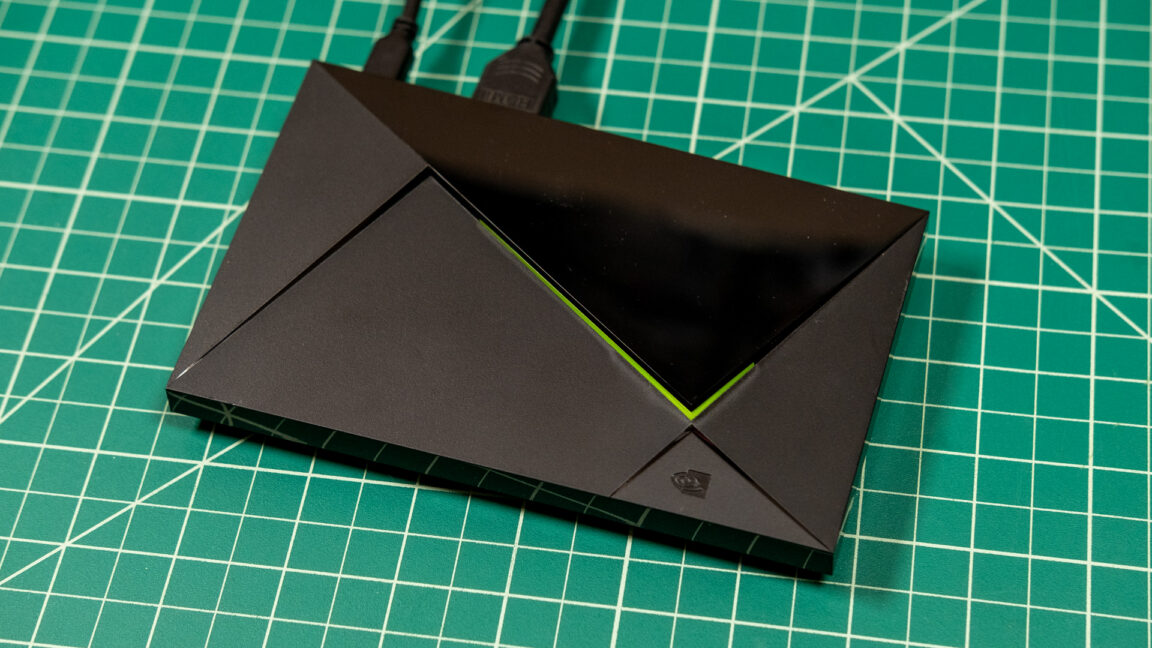
Initially launched in 2019, the Nvidia Shield TV Pro now retails for $299.99.
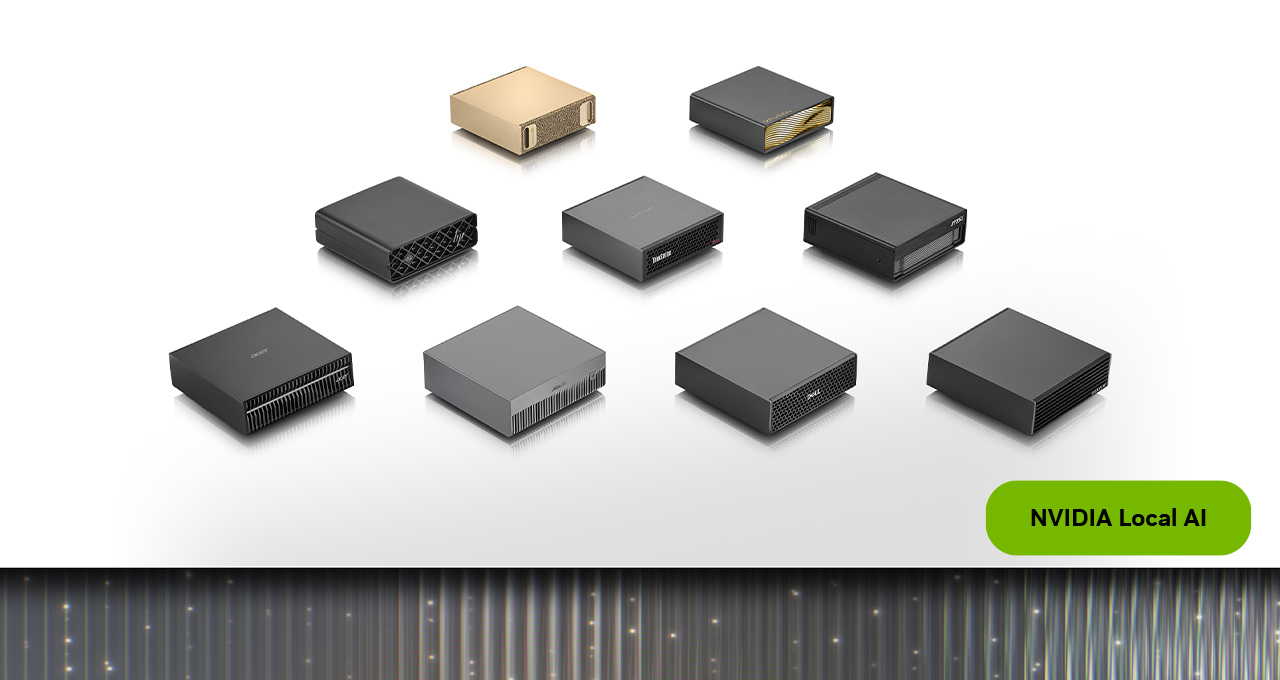
Local AI is becoming more useful by the token. As AI agents move from experiments into everyday development, increasingly capable open models are shrinking to fit on more devices,…
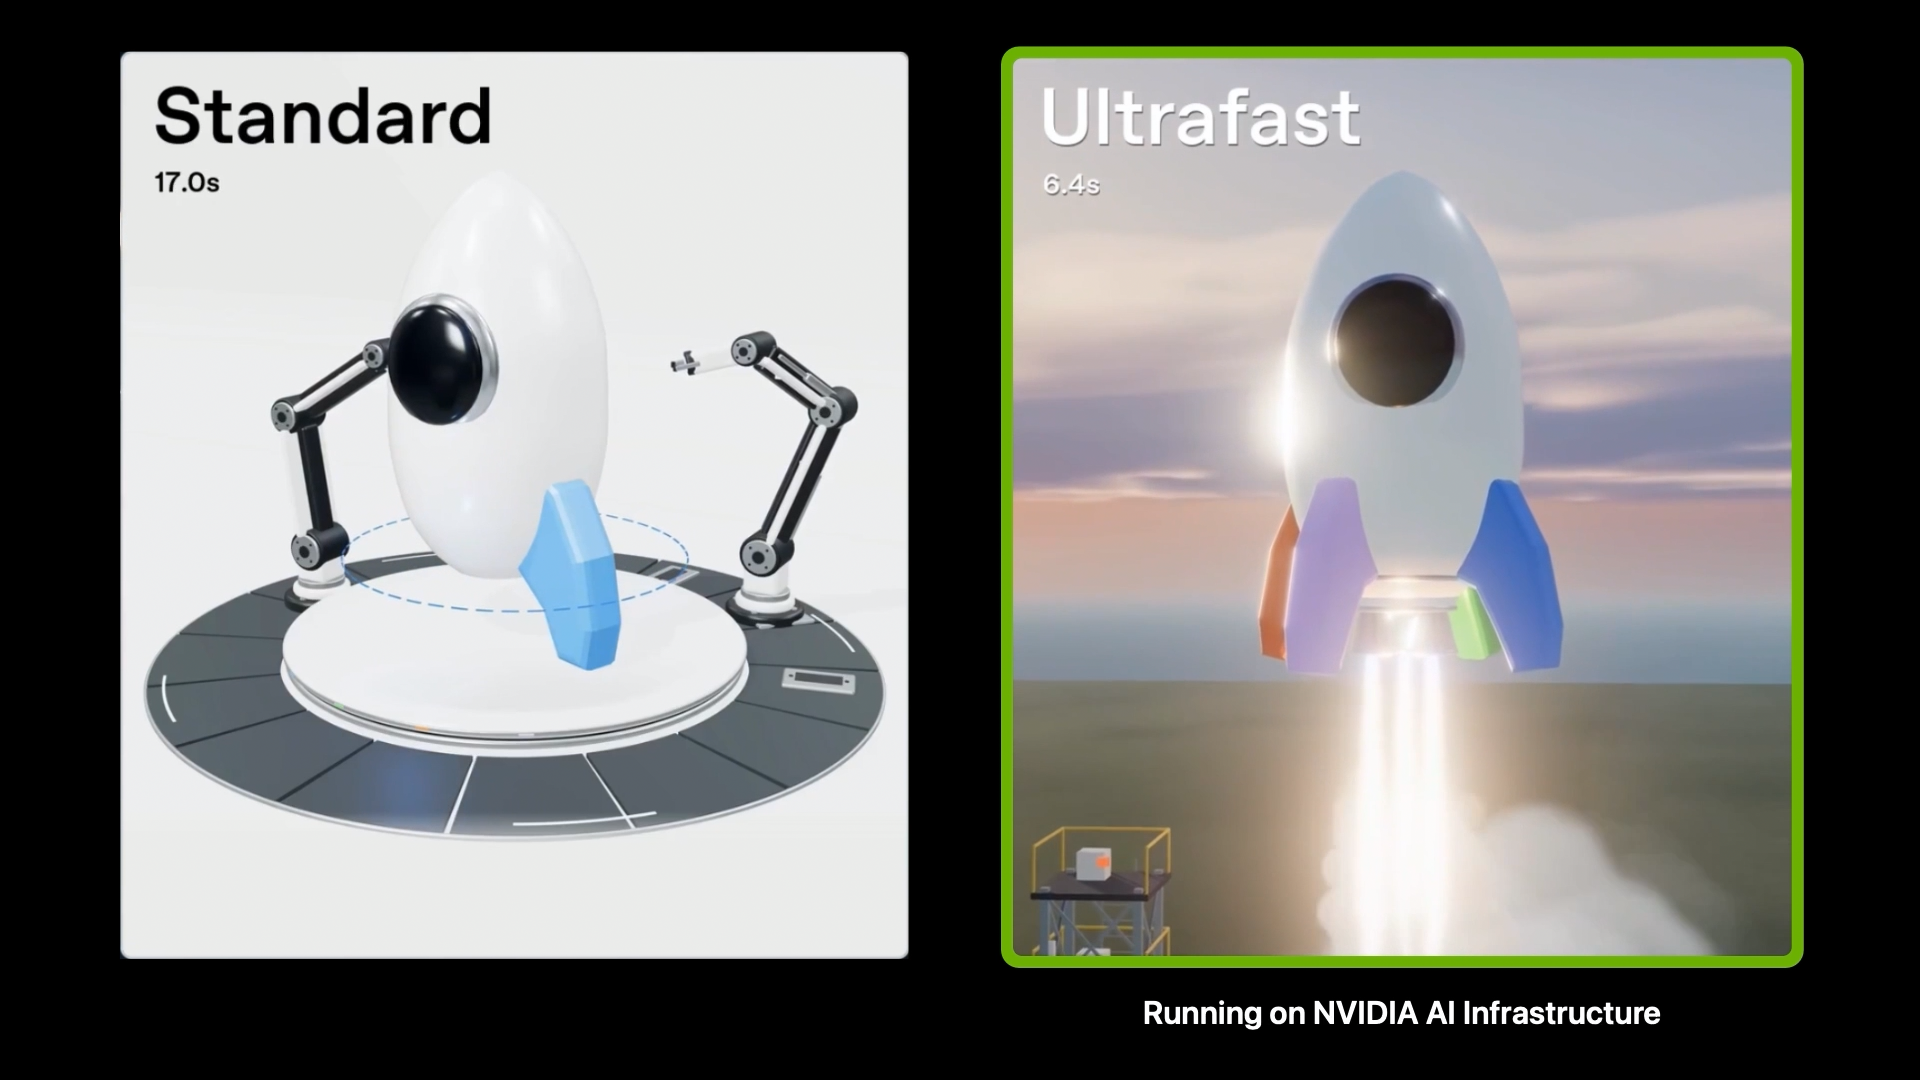
GPT-6 Astra Ultrafast, running on NVIDIA Blackwell GPUs, is available now in the OpenAI API and to eligible ChatGPT Work and Codex users. Accelerated by inference optimizations thr…
AI 点评 · 英伟达与OpenAI深度绑定,算力仍是模型竞赛的胜负手。
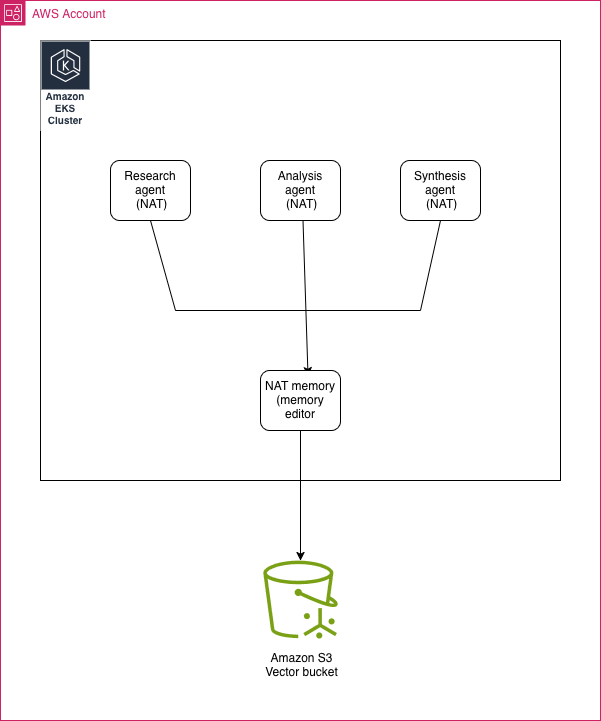
Learn how to use Amazon S3 Vectors as the persistent memory layer within the NVIDIA NeMo Agent Toolkit (NAT), deployed on Amazon Elastic Kubernetes Service (Amazon EKS). This post…
AI 点评 · 智能体长期记忆的工程化落地正从实验走向生产,云厂商与芯片巨头联手补齐这一关键拼图。
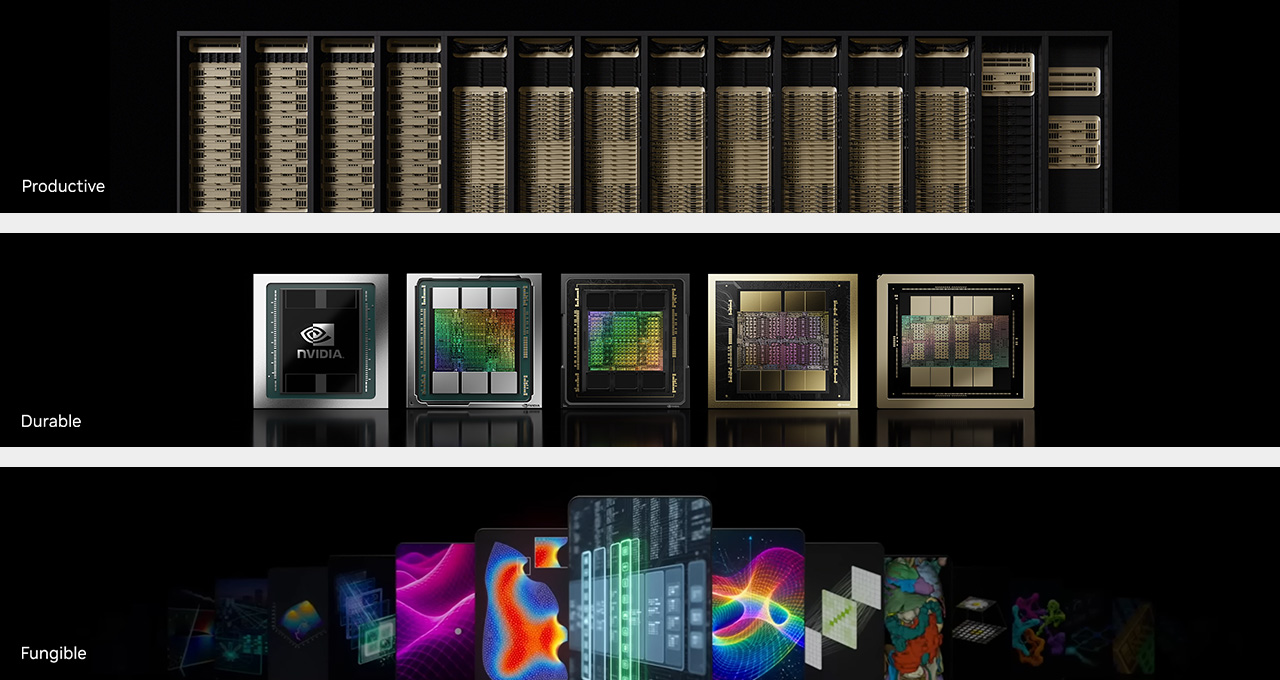
AI factories are built by the megawatt, even by the gigawatt. Each megawatt factory costs roughly $60 million, and AI factory operators will only commit capital on that scale with…
AI 点评 · 每兆瓦六千万美元,算力投入正逼近能源与资本的极限,回报率成为AI工厂成败的关键标尺。

IT之家 10 月 1 日消息,技嘉 (GIGABYTE) 昨日宣布推出 AI TOP 100 B850 台式整机。这一工作站级本地 AI 系统支持 1 张 NVIDIA GeForce RTX 5090 或 2 张 AMD Radeon AI PRO R9700 显卡。 其采用标准台式机架构,基于 AMD 锐龙 9 9950X 处理器 (配套 240mm…
AI 点评 · 桌面级整机塞进工作站级算力,本地跑大模型门槛再降。
Meta classifies its AI data centers as "pilot models" and Nvidia chips as experimental materials to save billions in federal taxes. In 2025 alone, that added up to $3.9 billion. Th…
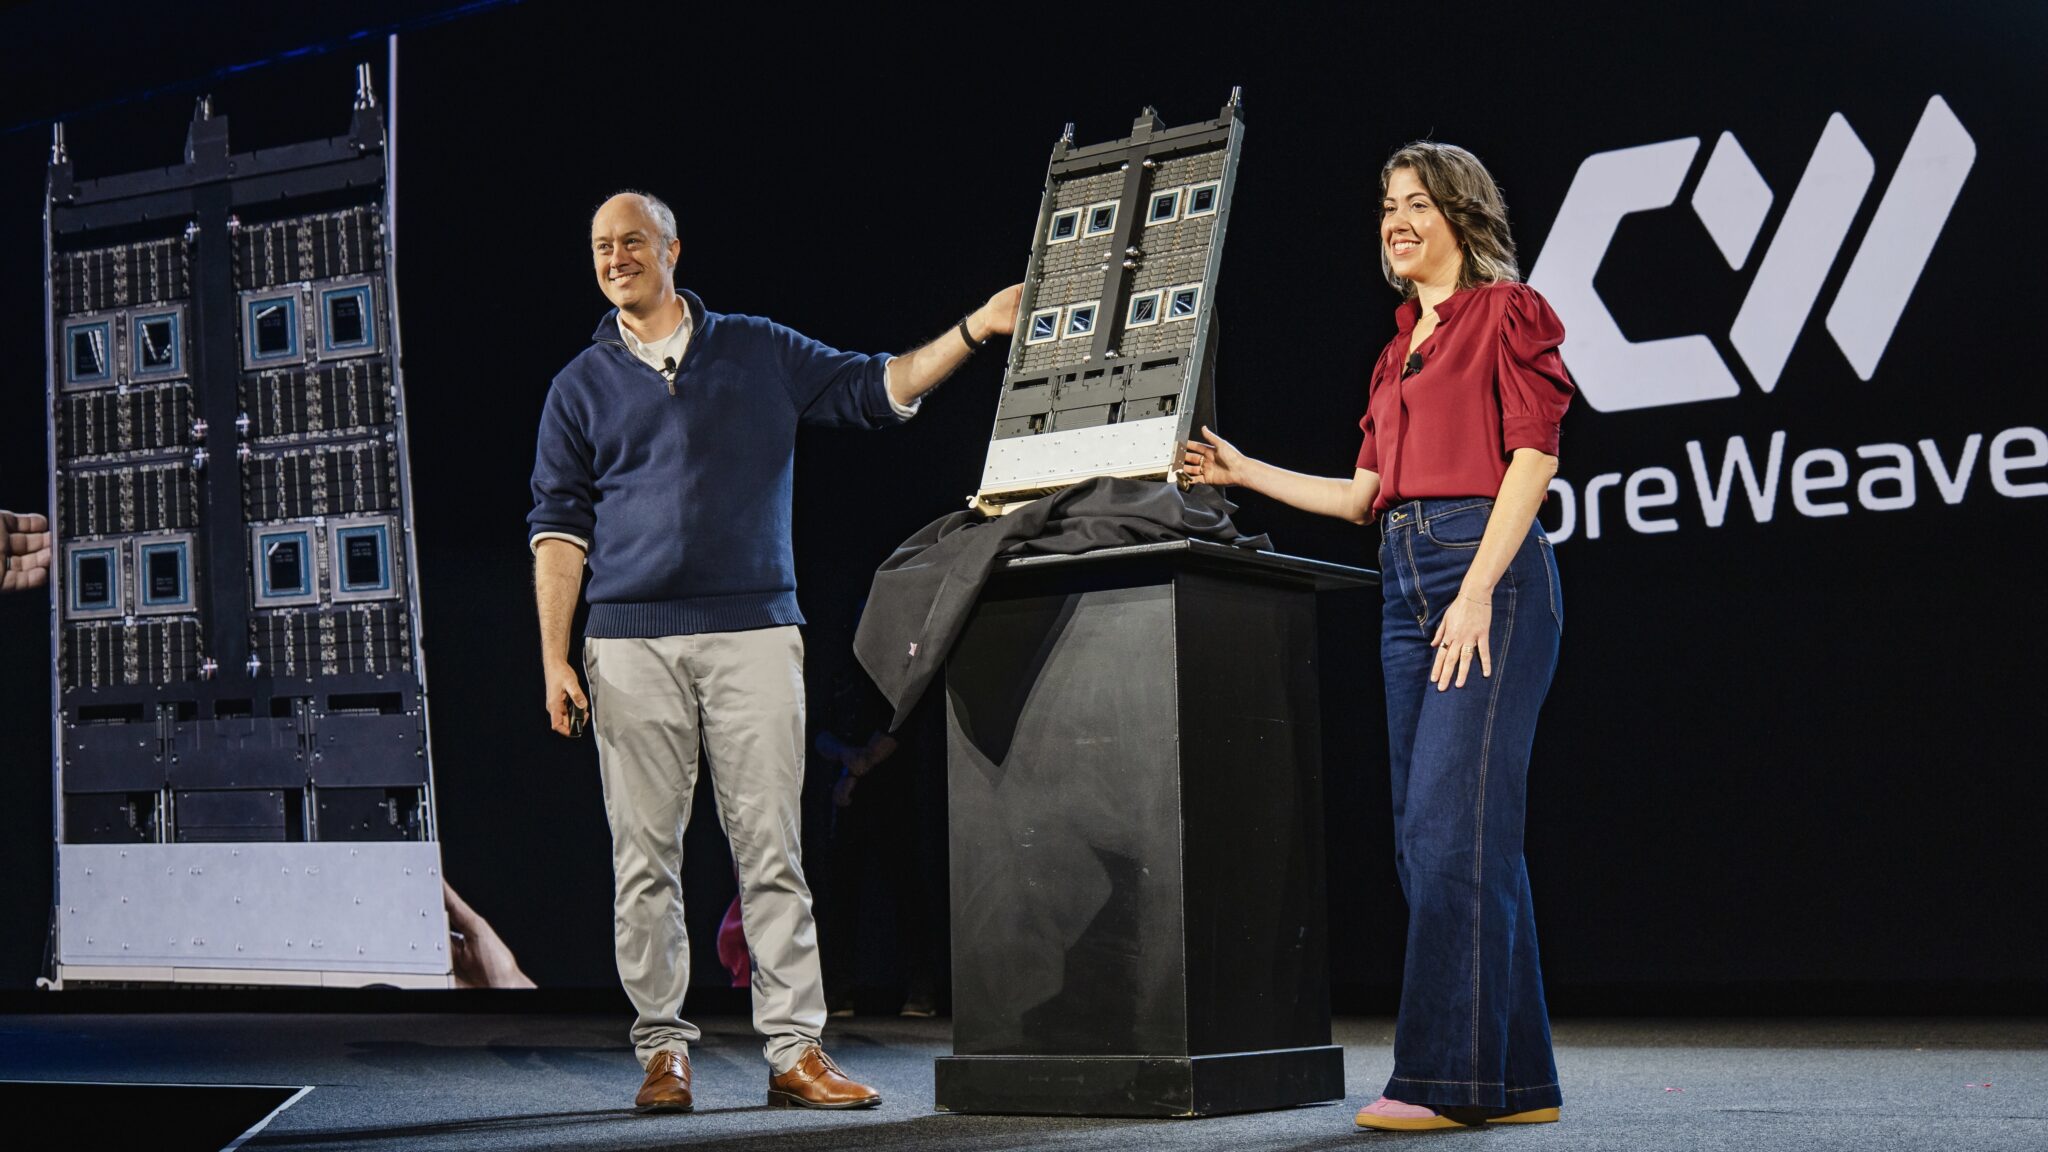
Building on nearly a decade of co-engineering, CoreWeave has built NVIDIA compute, networking and software into a cloud purpose-built for AI that’s still returning on investment ac…
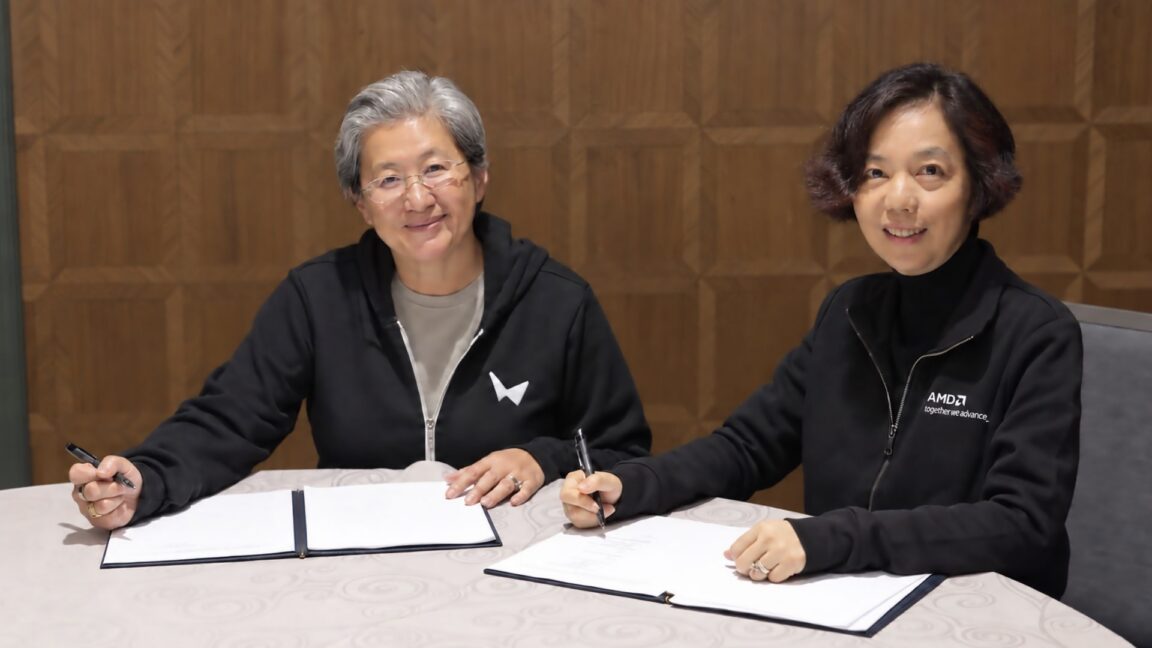
The deal, which is expected to close by year's end, is worth $8.2 billion.
AI 点评 · AMD豪掷82亿美元收购AI新锐,直接叫板英伟达,芯片巨头AI军备竞赛再升级。
Inspired by minGPT for home experiments. Requires CUDA 13.4; build script is Windows only.
AI 点评 · 超小模型训练仅需13秒,让个人实验也能轻松玩转Transformer。
OpenAI isn't a public supporter of Nvidia's Open Agent Safety Platform, but it is privately working with Nvidia, TechCrunch has learned.
AI 点评 · OpenAI私下参与却缺席公开站台,暴露AI安全联盟的信任裂痕,巨头博弈暗流涌动。
AI 点评 · 表格预测迎来新标杆,英伟达用单一模型兼顾精度与效率,有望改变结构化数据建模的选型逻辑。

IT之家 9 月 29 日消息,英伟达(Nvidia)首席执行官黄仁勋(Jensen Huang)表示,AI 模型蒸馏 —— 也就是利用其他模型的输出结果来训练新模型,属于市场竞争行为;然而白宫方面却将该做法定性为盗窃。 IT之家注意到,美国财政部长斯科特 · 贝森特(Scott Bessent)曾在 7 月将蒸馏称作“盗窃”,并威胁要对利用这一手段从美国自…
AI 点评 · 黄仁勋公开为蒸馏正名,与白宫定性正面交锋,折射AI竞争规则未定。
China is reportedly mulling letting ByteDance, Alibaba buy banned Nvidia chips.
AI 点评 · 中国或松绑英伟达芯片采购,牵动美企游说与地缘博弈走向。
Nvidia CEO Jensen Huang on Monday introduced a toolkit of software and hardware products that add independent security layers around AI agents to ensure they stay within their test…

Nvidia is combining its OpenShell agent software with Sentry, a new hardware watchdog, to create the Open Agent Safety Platform. Sentry is supposed to isolate AI agents that break…
Nvidia is launching a new safety platform designed to contain and monitor AI agents, a move that comes in response to a wave of rogue hacking incidents, as reported earlier by Reut…

In the wake of a series of high-profile AI safety incidents, Nvidia is introducing a new software tool that helps keep agents from escaping containment.
Nvidia released Nemotron 3 Diarization, an AI model that identifies which speaker is talking at any given moment in a conversation. The article Nvidia drops a free 100M-parameter m…
AI 点评 · 小模型免费开放说话人分离,语音转写与会议记录的门槛被大幅拉低。
On NVIDIA Blackwell B200, tensor-core throughput outpaces special-function exponential throughput by more than two orders of magnitude, exposing exponential evaluation in fused attention kernels. A pr…

SoL-Pi cuts coding agents' token usage by up to 49 percent with little change in performance by optimizing the control layer between the model and its environment. A research agent…
AI 点评 · 优化模型与环境间的控制层即可省近半token,这条思路比堆算力更值得行业借鉴。

They wanted the silicon. They got the sand.
AI 点评 · 劫匪盯上英伟达芯片,却只搬走二十吨沙子,荒诞背后是芯片荒催生的疯狂黑市。
The funding, which comes from Third Point, Nvidia, and others, will fuel the company's massive AI data center buildout.
AI 点评 · 英伟达押注的欧洲AI云新贵冲刺美股,算力基建军备竞赛再升温。
As Jensen Huang puts it, AI can help fight climate change - but only if it inflicts "an enormous amount of pain and suffering" first. The Nvidia CEO discussed the future of energy…
AI 点评 · 黄仁勋以反讽口吻揭示AI助力气候的前提,暗指技术变革代价高昂,引人深思。
AI 点评 · 英伟达开源仿真框架打通机器人训练全链路,加速具身智能落地值得关注。

Nscale, the Nvidia-backed AI cloud provider, leaves its most important customer, Bytedance, out of the main prospectus for its planned US IPO. The article Nvidia-backed Nscale keep…

Basecamp Research has raised $140 million from investors including Nvidia and Anthropic's Anthology Fund. The London company trains AI models on genetic material from rainforests,…
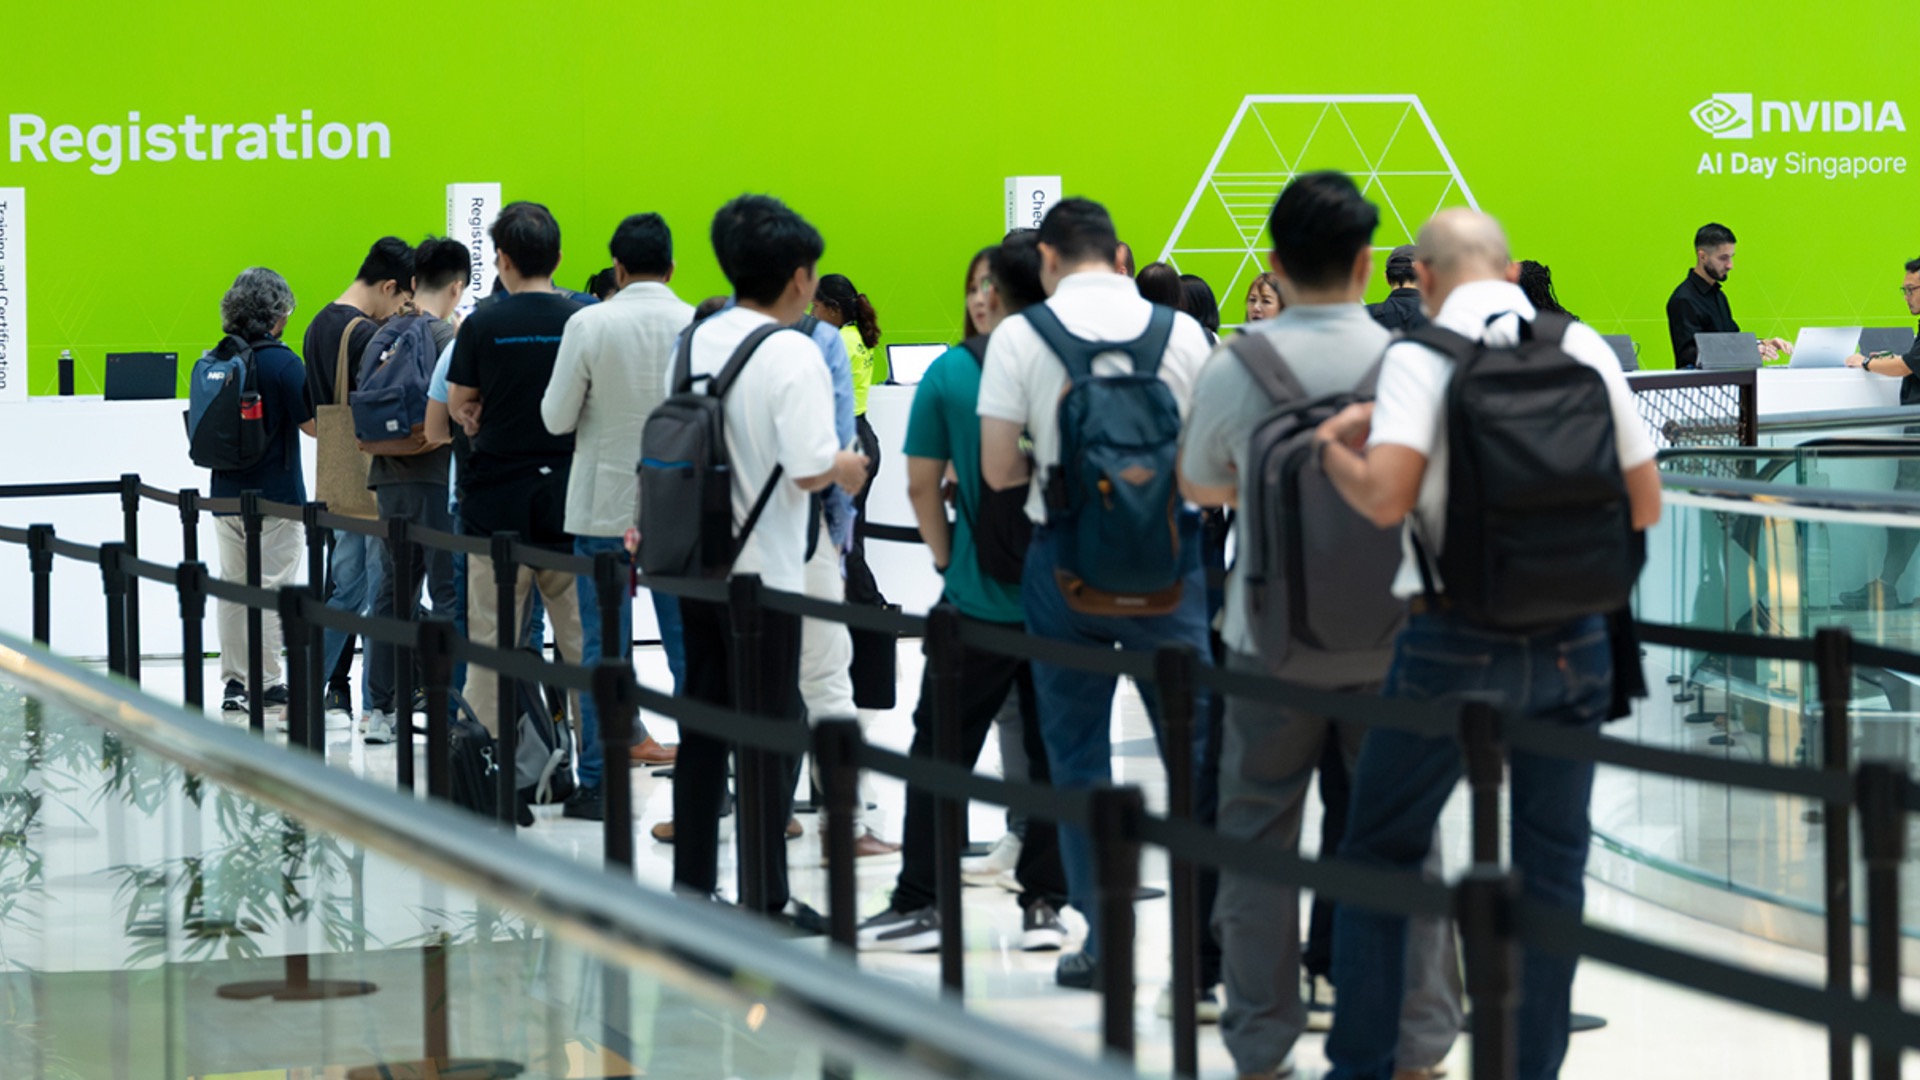
NVIDIA AI Day Singapore, which takes place Sept. 22-23 at the Raffles City Convention Centre, is offering attendees opportunities to explore the hands-on training, expert-led sessi…
At TechCrunch Disrupt 2026, five sessions across the AI Stage and Real World AI Stage cover AI safety, featuring leaders from Anthropic, Nvidia, AWS, Waabi, and more. Register befo…
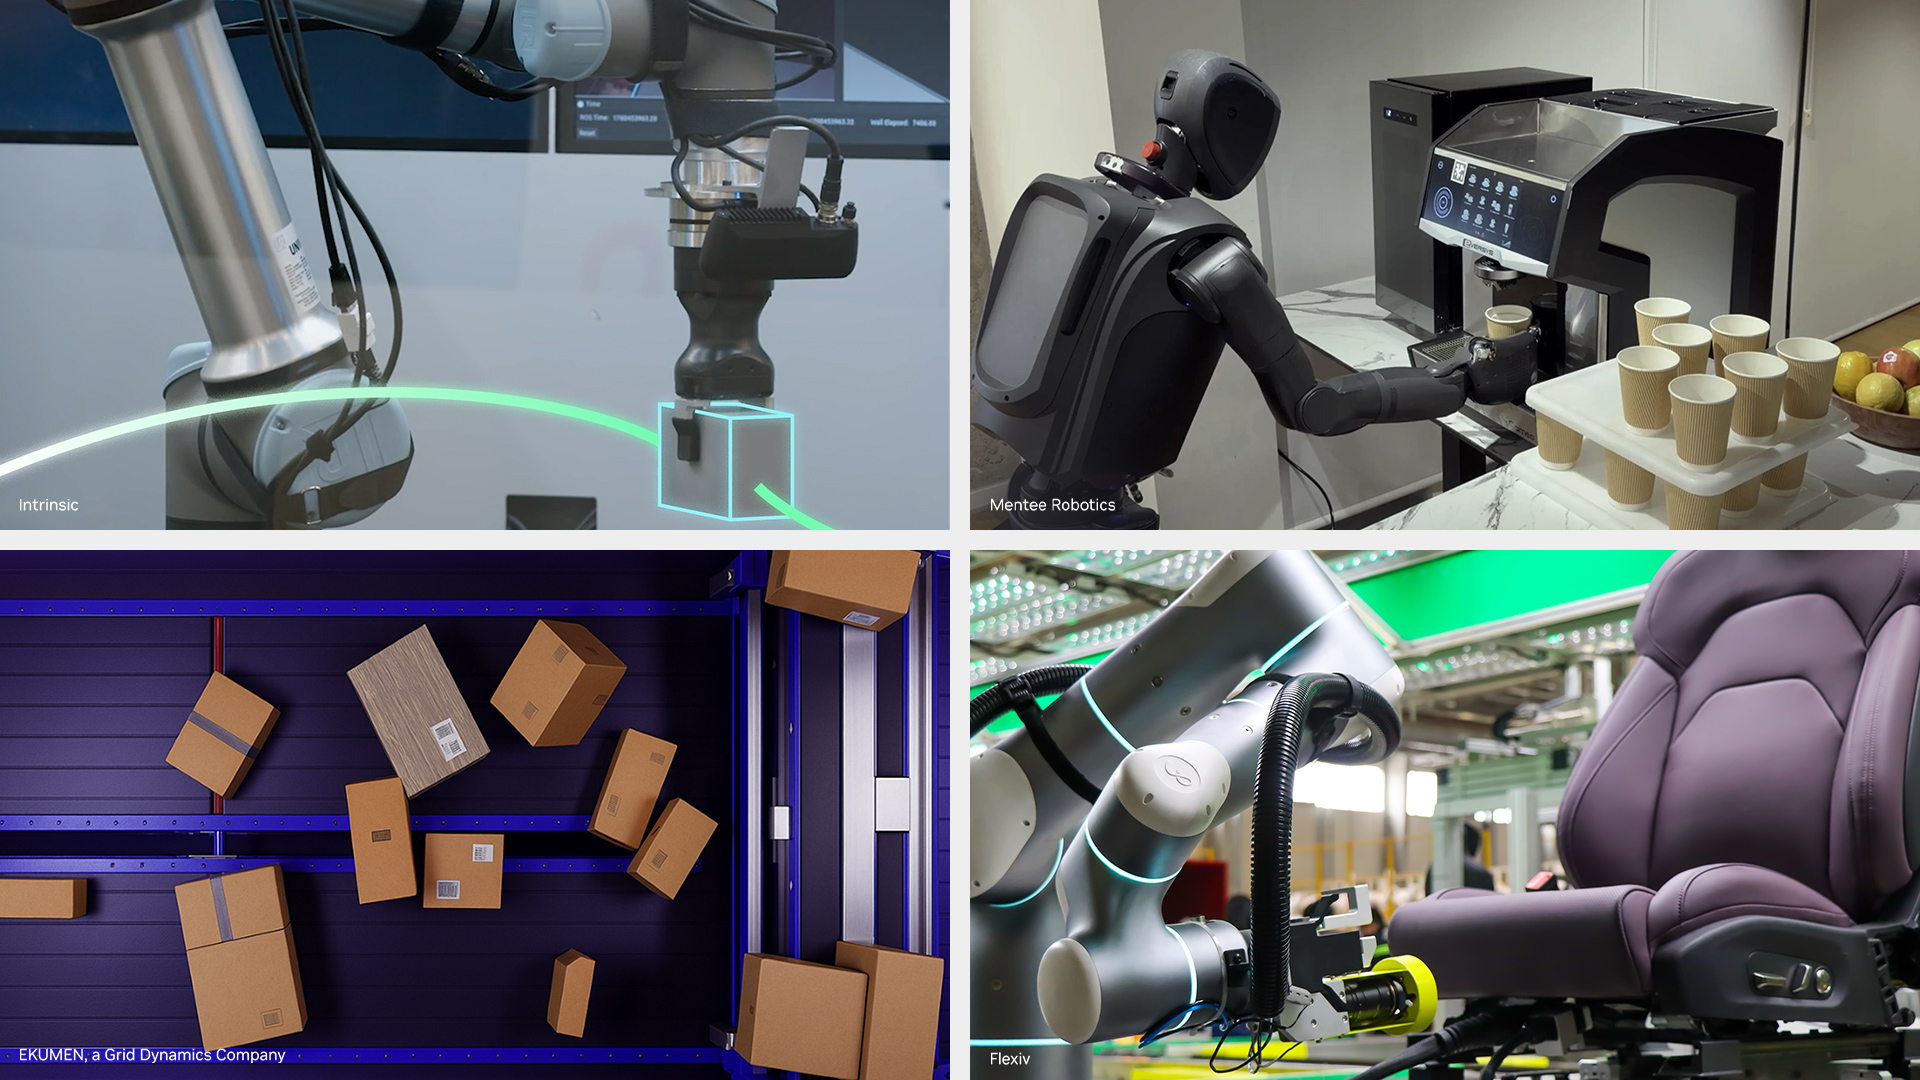
To build and deploy sophisticated robotics applications that can perceive, reason and act in dynamic environments, developers need new physical AI models and tools. The ROS open fr…
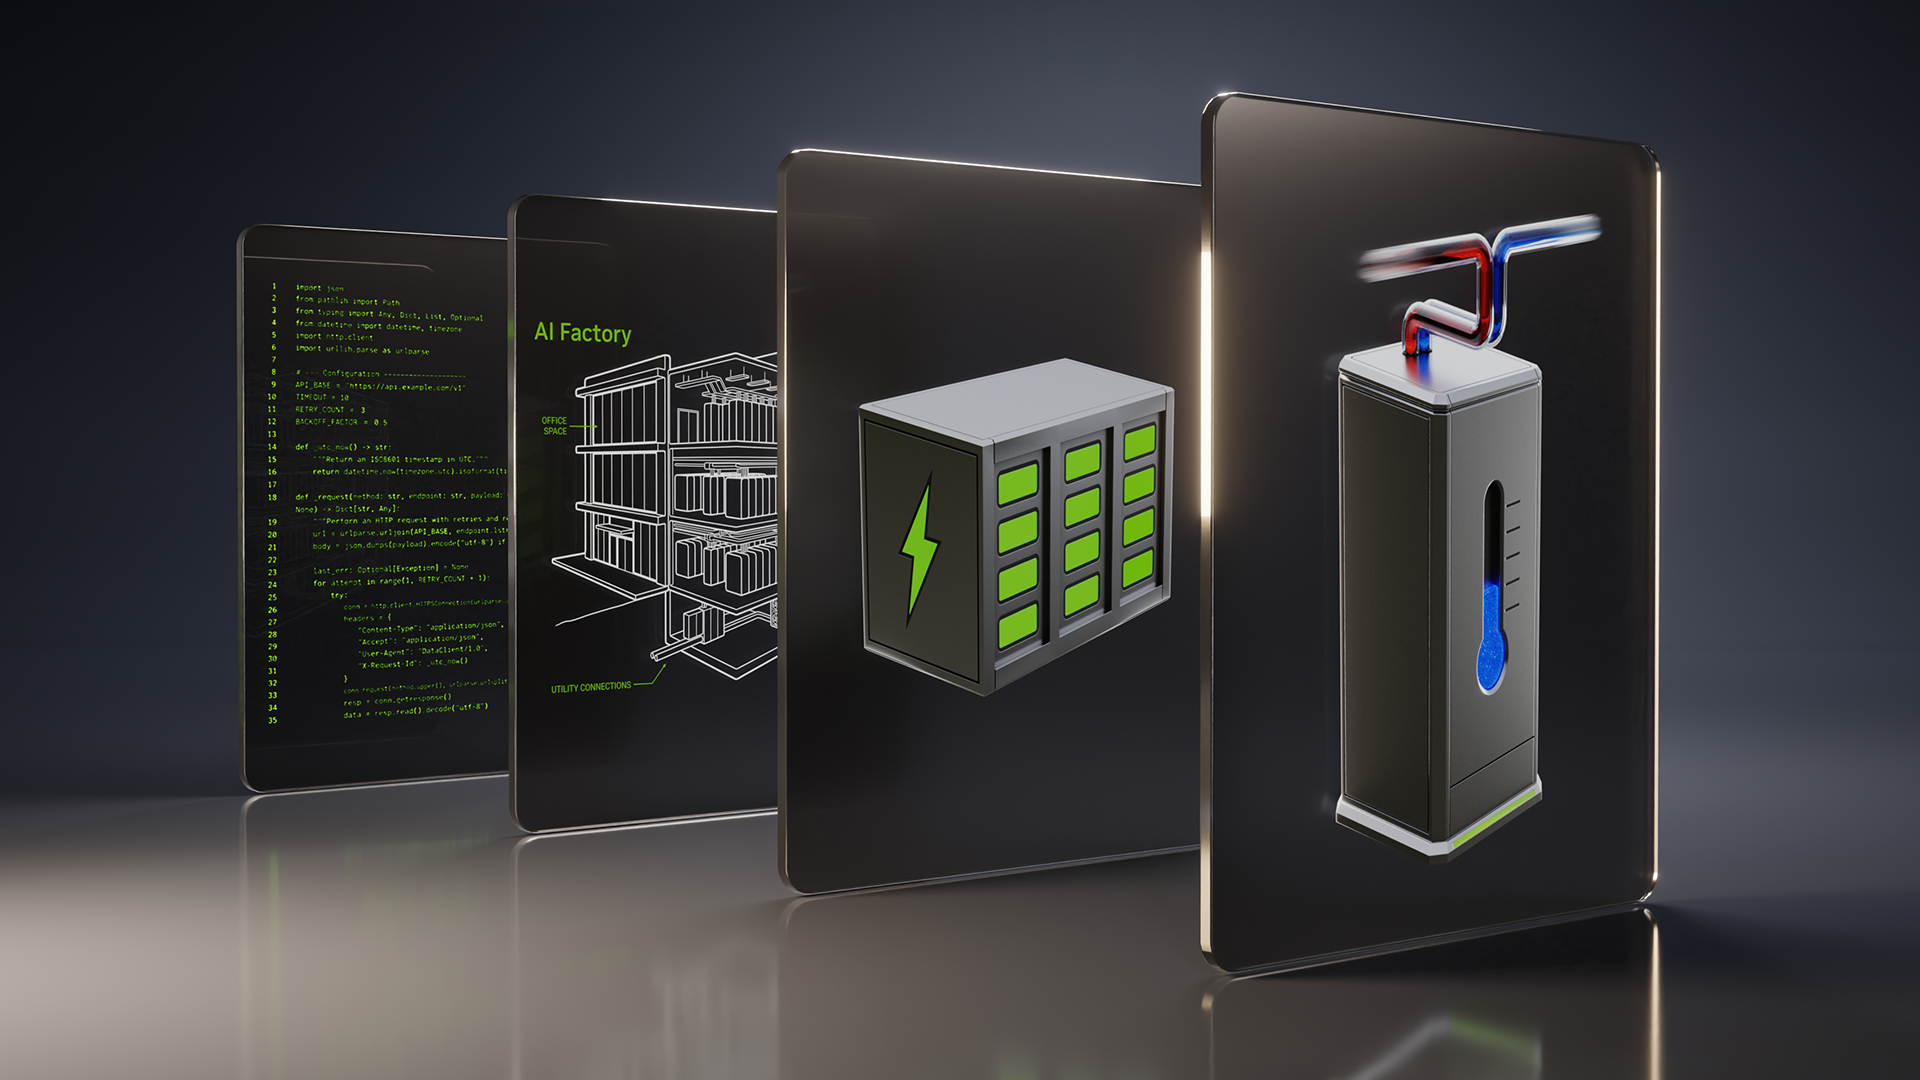
Every AI factory needs power and cooling that fit its computing architecture. As AI infrastructure expands, power, cooling, water, site and grid constraints are shaping what builde…
AI 点评 · 算力扩张的真正瓶颈正从芯片转向供电与散热,英伟达此举意在绑定基础设施生态。
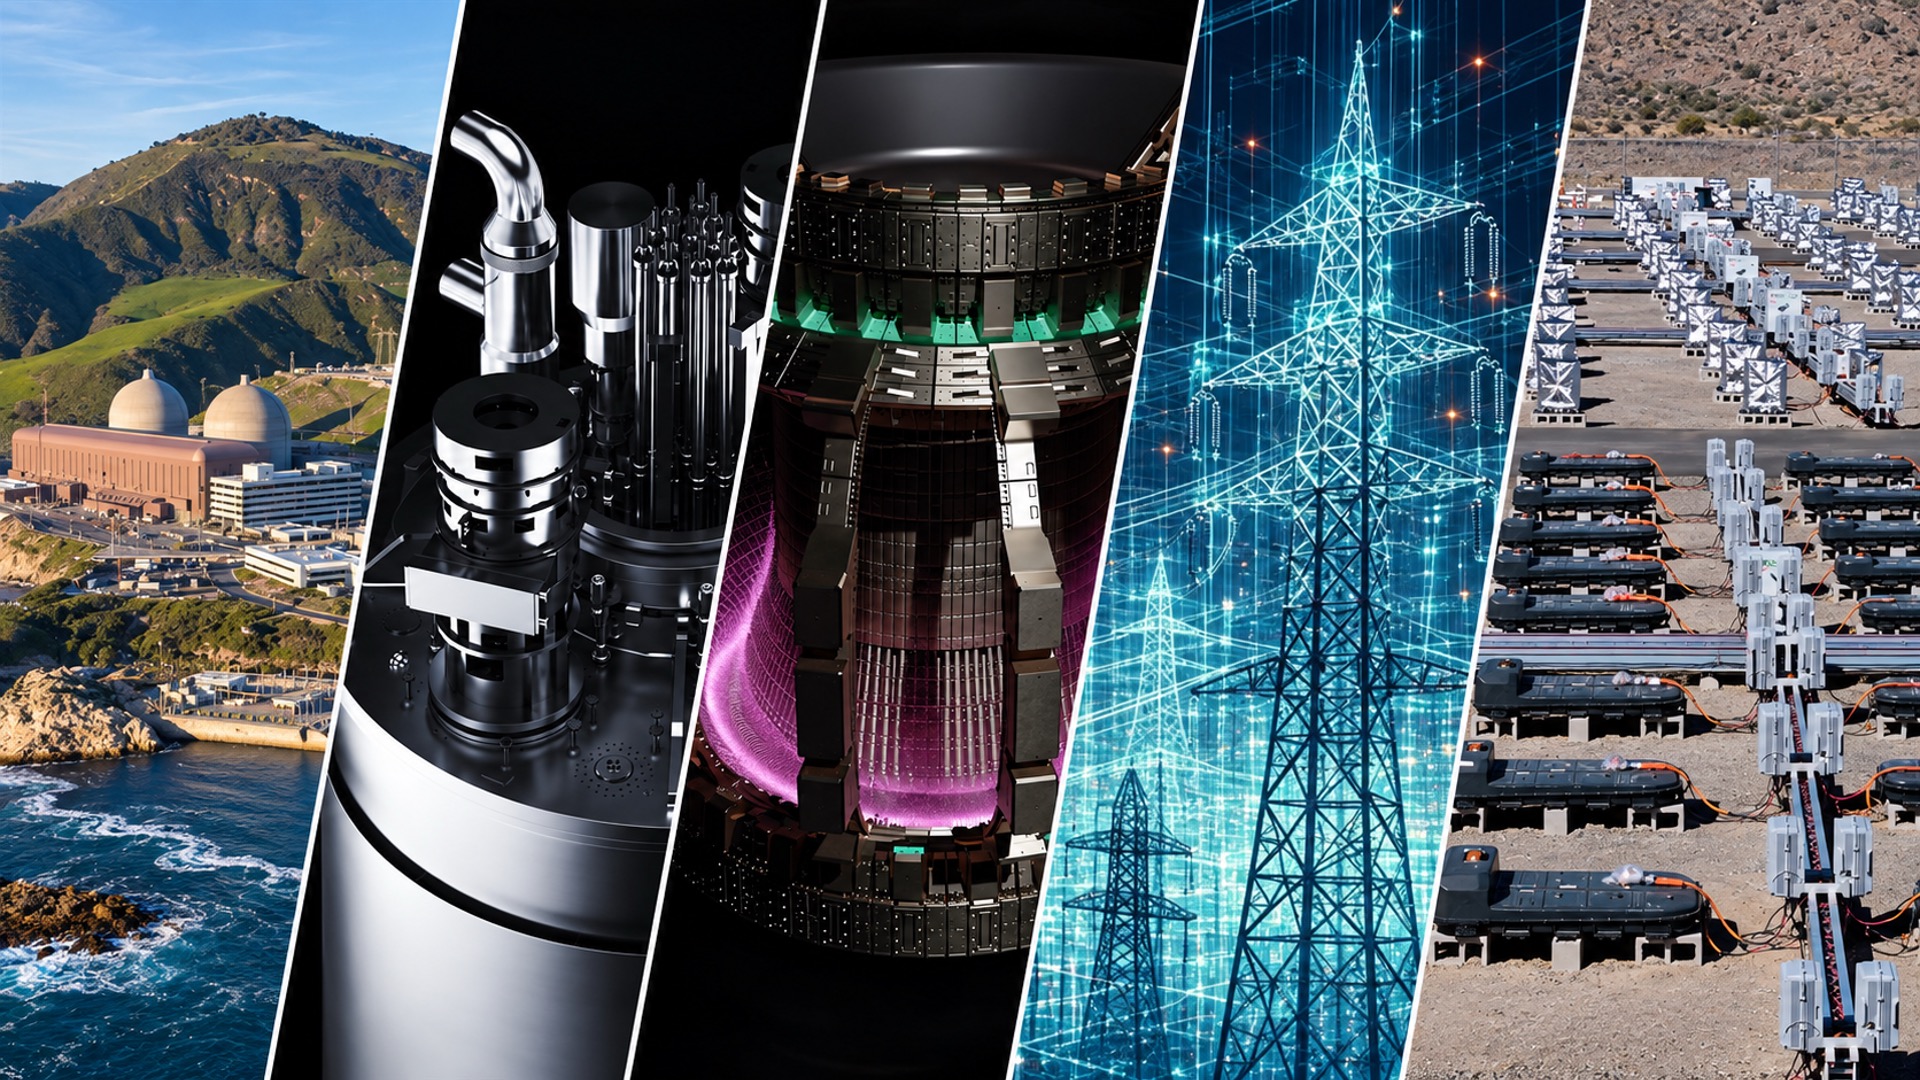
Clean energy isn’t hard to come by, but the pace of large-scale adoption has historically been slow due to bottlenecks — including out-of-date infrastructure, elongated research an…
llama.cpp optimized for NVIDIA Tesla V100 (SM70): large MoE Qwen3.8-Flash-Next with MTP (prefill 3464 tok/s at 200K context, 6x V100-16GB) and Qwen3.8-27B with…
The man who may stand to make the most money from the AI boom seems to think he knows better than anyone else, including researchers who have studied and worked on AI for decades.…
AI 点评 · 黄仁勋的乐观源于利益,却忽视了AI安全研究者的长期警告,这种立场偏差值得警惕。
Nvidia's Nader Khalil and Sydney Sykes discuss one of the decisions shaping next-gen startups on the Builders Stage at TechCrunch Disrupt 2026.

The Dreamforce conference became an unlikely battleground for the CEOs of OpenAI, Anthropic, and Nvidia to debate whether AI development should slow down.
Huawei is accelerating the launch of its next-generation Ascend 960DT AI chip as it pushes to compete with Nvidia and close China’s AI computing gap with the U.S.
A new coalition that includes Google, Nvidia, Anthropic, and Emerald AI wants to find 100 GW of grid capacity for new data centers.

IT之家 9 月 17 日消息,高准确度的爆料者 @Kepler_L2 昨日在 AnandTech 论坛上驳斥了 Moore's Law is Dead 所称“RTX 60 系列瞄准 2027 年上半年”的消息。 他在回复网友时表示:AMD 计划在 2027 年先行推出部分 RDNA 5 产品,代号为“AT2”,具体型号尚未确定。AMD 和 NVIDIA 的…
AI 点评 · 显卡换代周期罕见拉长至三年,玩家恐面临漫长空窗期,厂商或转向AI算力优先。

Integrate NVIDIA Resiliency Extension (NVRx) into PyTorch FSDP training on Amazon EKS to overlap checkpoint I/O with training and recover from GPU faults in seconds. This post cove…
AI 点评 · 大模型训练最怕GPU故障中断,秒级恢复加检查点与训练重叠,直接拉高集群可用性。
According to The Information, Apple is planning to get back into the server game and might just pair up with Nvidia to make it happen. Apple retired its Xserve line in 2011 and has…
System performance, efficient infrastructure scaling and continuous software optimization are key levers that determine AI inference economics. Higher system performance means more…
The robotics industry is still waiting for their breakthrough into day-to-day life. Nvidia's Les Karpas has an answer as to why at TechCrunch Disrupt 2026. Register before Septembe…
AI factories are the infrastructure of the intelligence era. Scaling them responsibly will depend as much on innovation across the grid as inside the data center. Today, Emerald AI…
AI isn't some new form of "alien mind," according to Jensen Huang. It's just hardware and software, so safety can be engineered by each AI product maker.
AI 点评 · 黄仁勋主张行业自管安全,实质是反对监管束缚,这场博弈将决定AI治理走向。
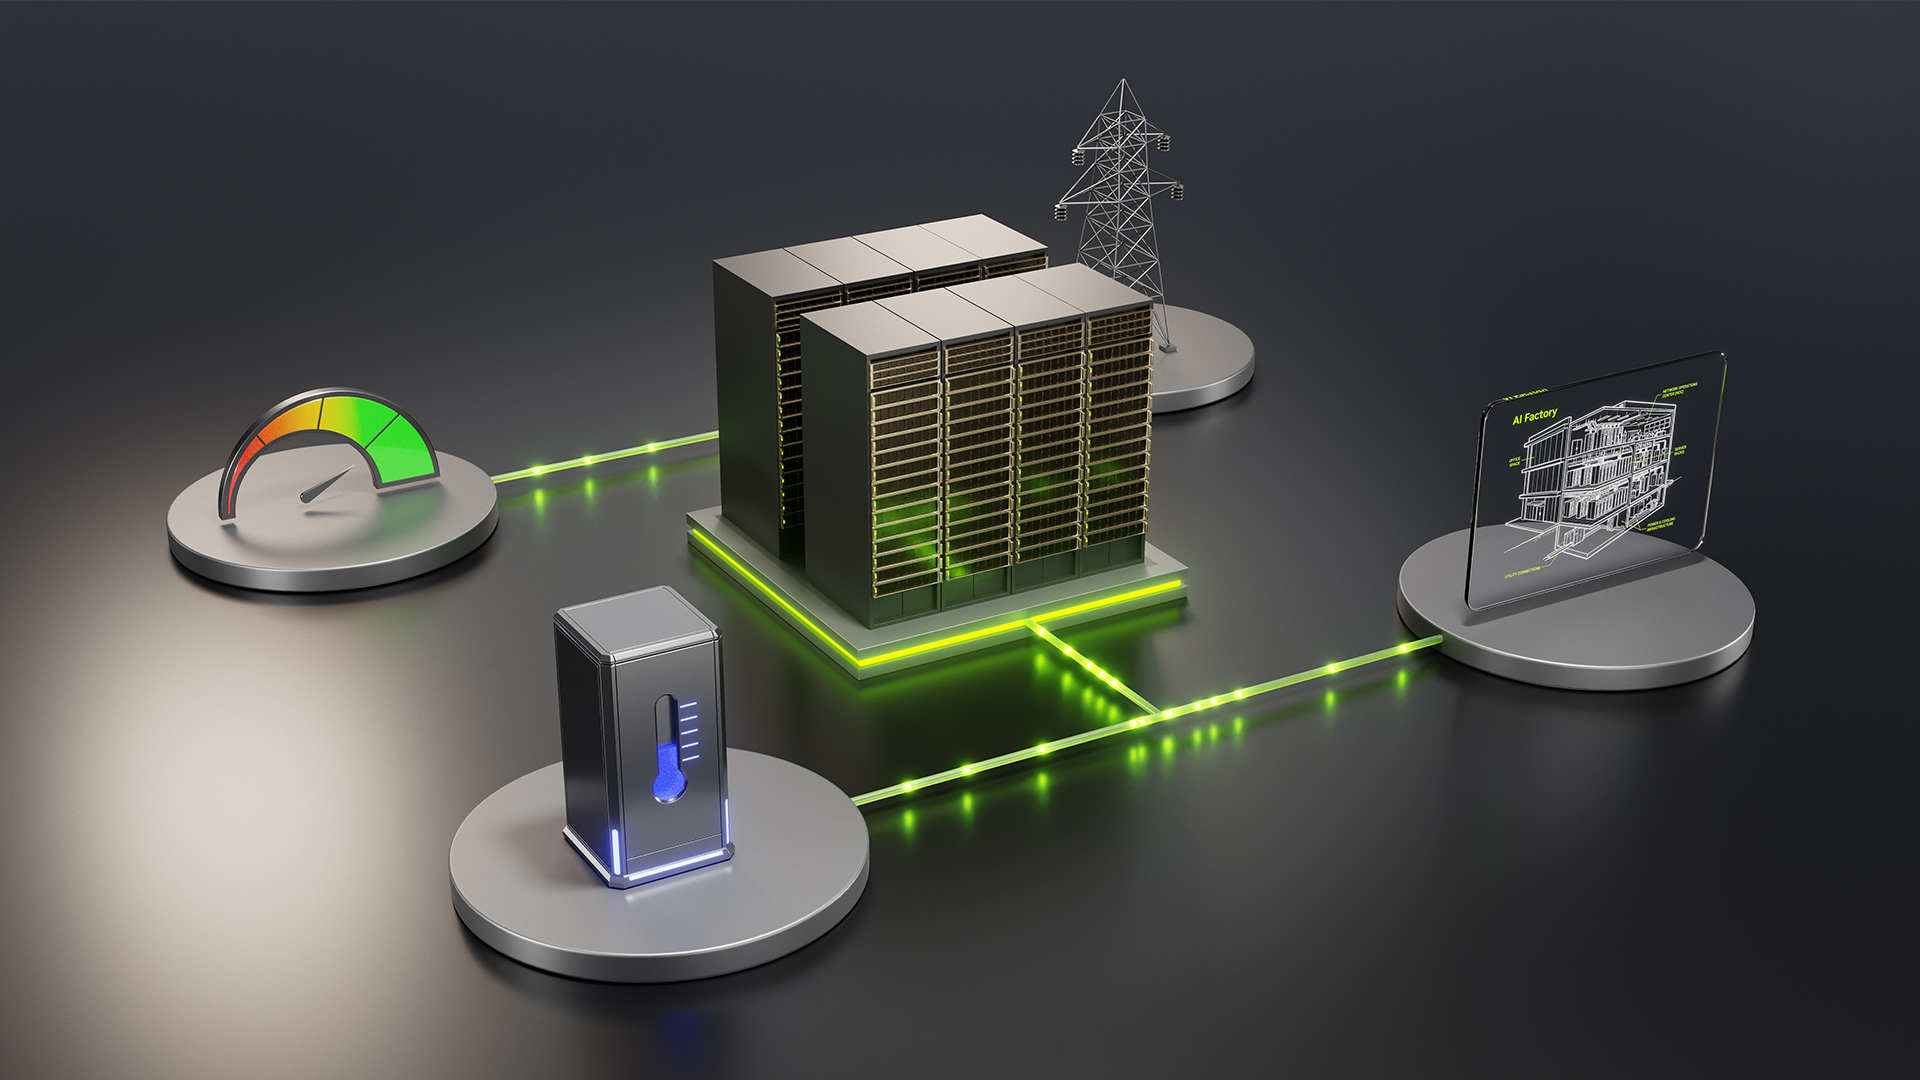
On a sweltering August evening in Silicon Valley, as the sun dropped and air conditioning loads spiked, Silicon Valley Power sent a signal to an AI factory to adjust its power cons…
AI 点评 · 算力竞争正从芯片转向电力调度,AI工厂开始靠需求响应省电,这或成数据中心新标配。
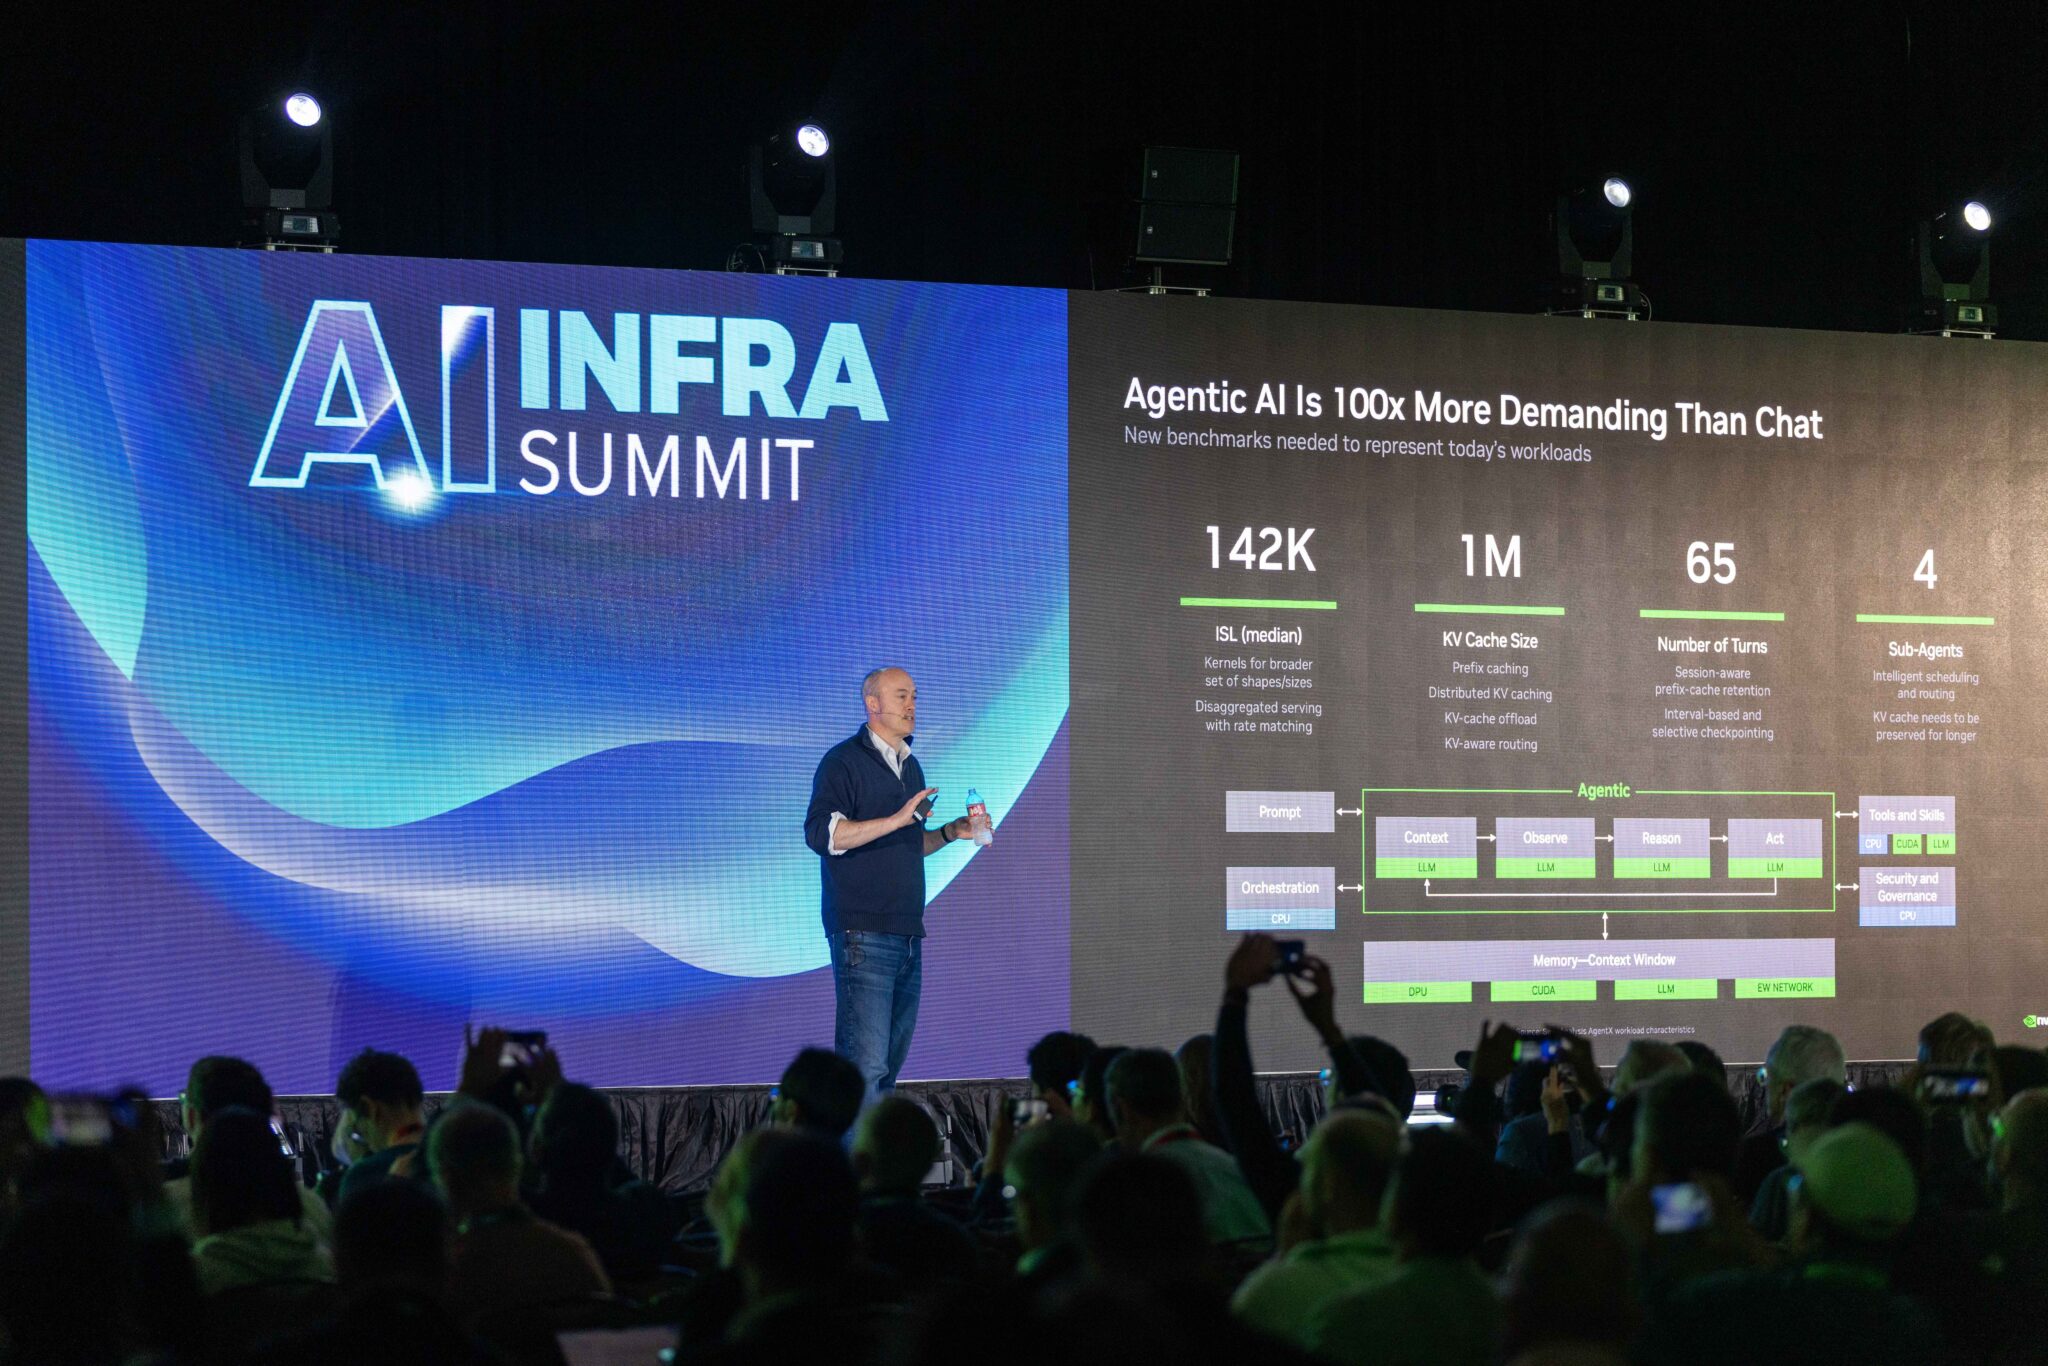
Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, Tuesday spoke on AI factory efficiency at the AI Infra Summit, the Santa Clara Convention Center ev…
AI 点评 · AI工厂竞争焦点正从算力规模转向每瓦token产出,能效成新战场。
Salesforce Koa is built on Nvidia's open-weight Nemotron model and is trained to do sales, marketing, and customer-support tasks.
Though Elon Musk and Sam Altman have supported Dario Amodei's calls to slow the pace of AI development, Jensen Huang seems to feel differently.
AI 点评 · 黄仁勋公开反对放缓AI,凸显行业路线之争,也预示算力扩张将加速。
Nvidia CEO Jensen Huang took a call from President Trump on Monday while onstage at the All-In Podcast's All-In Summit. It's not the first time Huang has taken a call from the pres…
AI 点评 · 黄仁勋当众连线特朗普,把芯片与AI政策博弈搬上舞台,科技巨头与政治权力的暧昧关系再成焦点。
As local models become more capable, AI agents can handle more work directly on a PC while keeping sensitive information on the device. Portable Computer is a local version of the…
This practical tutorial demonstrates how to build and accelerate machine learning workflows using NVIDIA cuML and RAPIDS. It covers GPU environment setup, zero-code scikit-learn ac…
AI 点评 · GPU加速机器学习全流程实战,零代码迁移scikit-learn是最大看点。
https://archive.ph/kt50V
AI 点评 · 英伟达掌控AI算力命脉,其芯片供应与定价权堪比央行调控经济,值得警惕。
Nvidia is in talks to invest up to $10 billion in Anthropic's planned IPO, Reuters reports. At a target valuation of $2 trillion, it would be the largest IPO in history. Most of th…
AI 点评 · 芯片巨头与AI独角兽深度绑定,史上最大IPO预示算力与模型加速合流。
NVIDIA has detailed BioNeMo Inference Runtime (BioIR), a Python library that accelerates biomolecular structure-prediction models on NVIDIA GPUs while staying in plain PyTorch. In…
AI 点评 · 英伟达把生物分子预测推理性能再拉高,GPU加速正成为AI制药基础设施的关键竞争点。
Nvidia has its finger in every pie, and sees another year of plenty in its future, Jensen Huang says. But, he insists, its deals are not circular.
AI 点评 · 英伟达触角遍及全行业,黄仁勋否认循环交易质疑,其增长逻辑能否成立值得关注。
Counterfactual regret minimization (CFR) is one of the few large numerical workloads that still runs faster on CPUs than on GPUs. Each iteration sweeps a game tree with up to billions of states in mil…

Manufacturing floors, warehouses and production lines rarely stay fixed — tasks change, layouts shift and new products arrive, and most robots can’t keep up without significant rep…
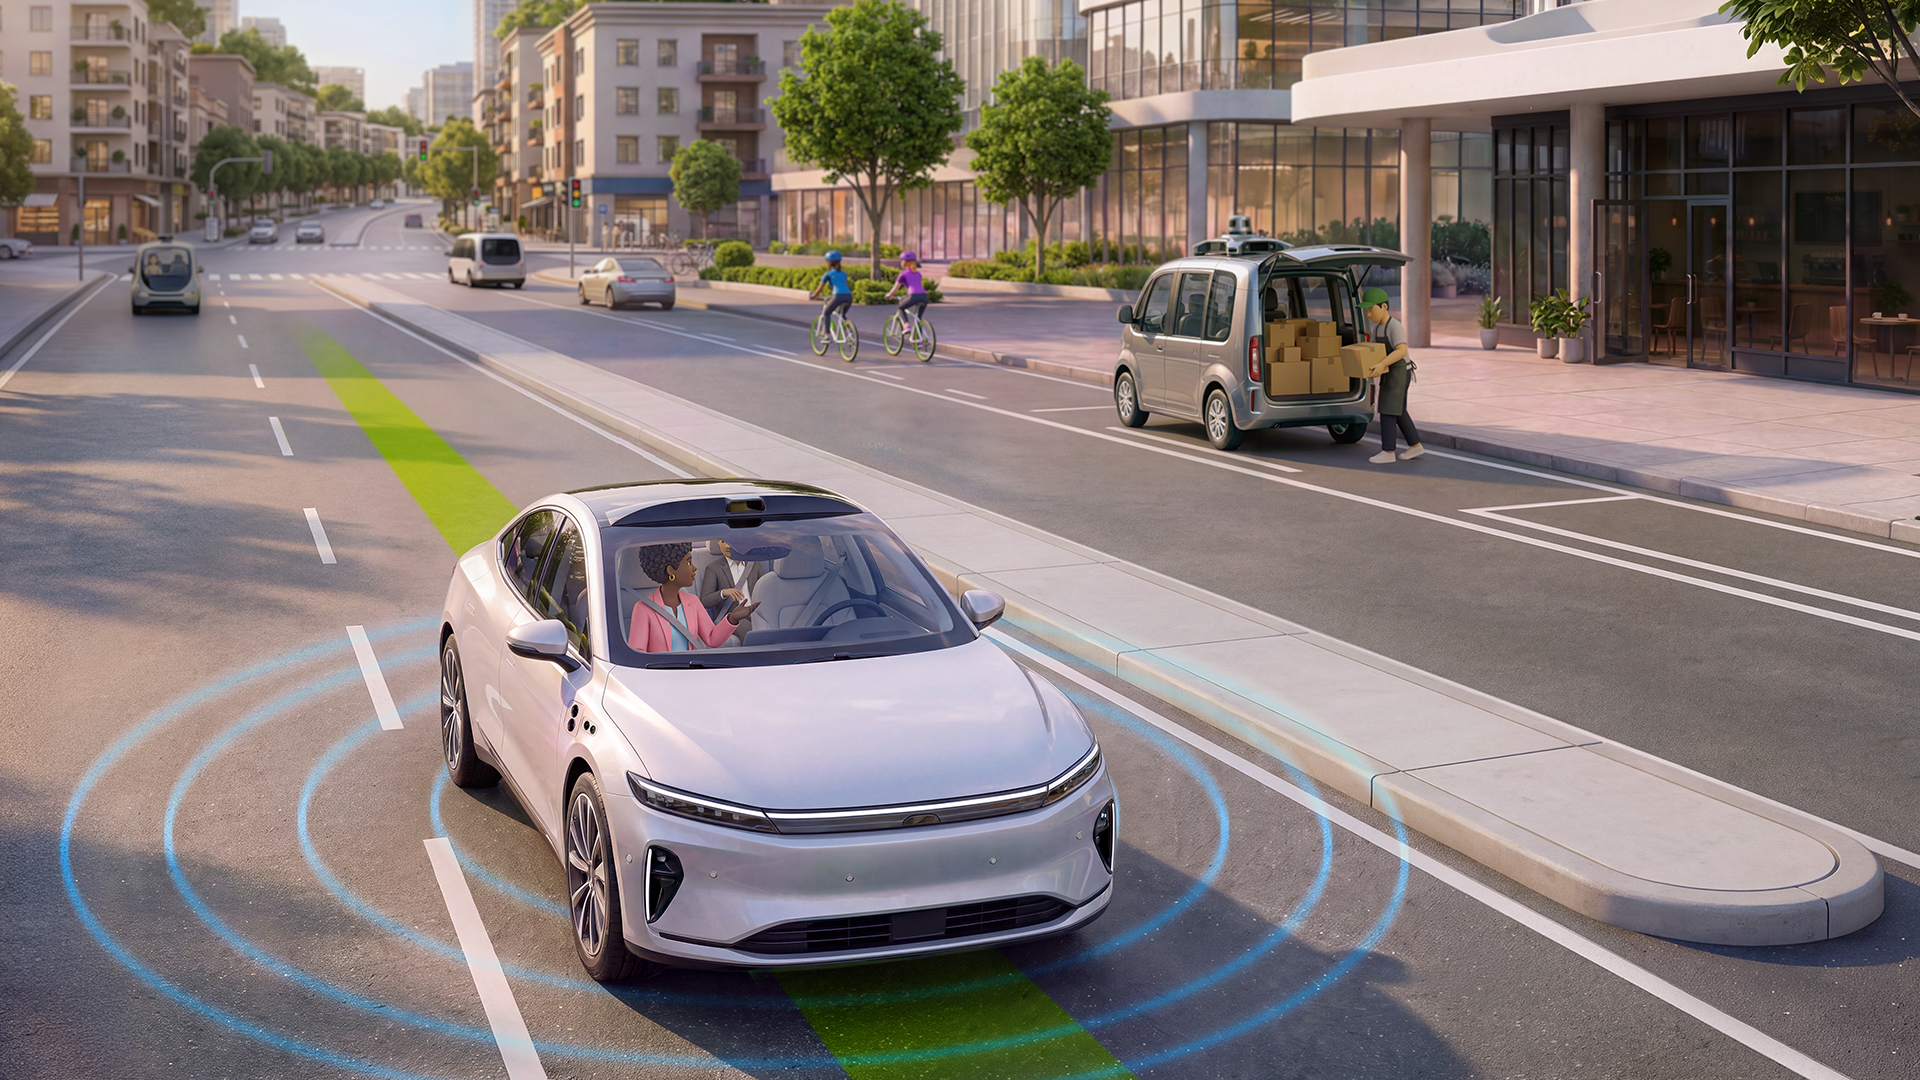
The global robotaxi market — physical AI’s first commercial breakthrough — is projected to reach $400 billion by 2035, with over 6 million commercial vehicles in operation as drive…
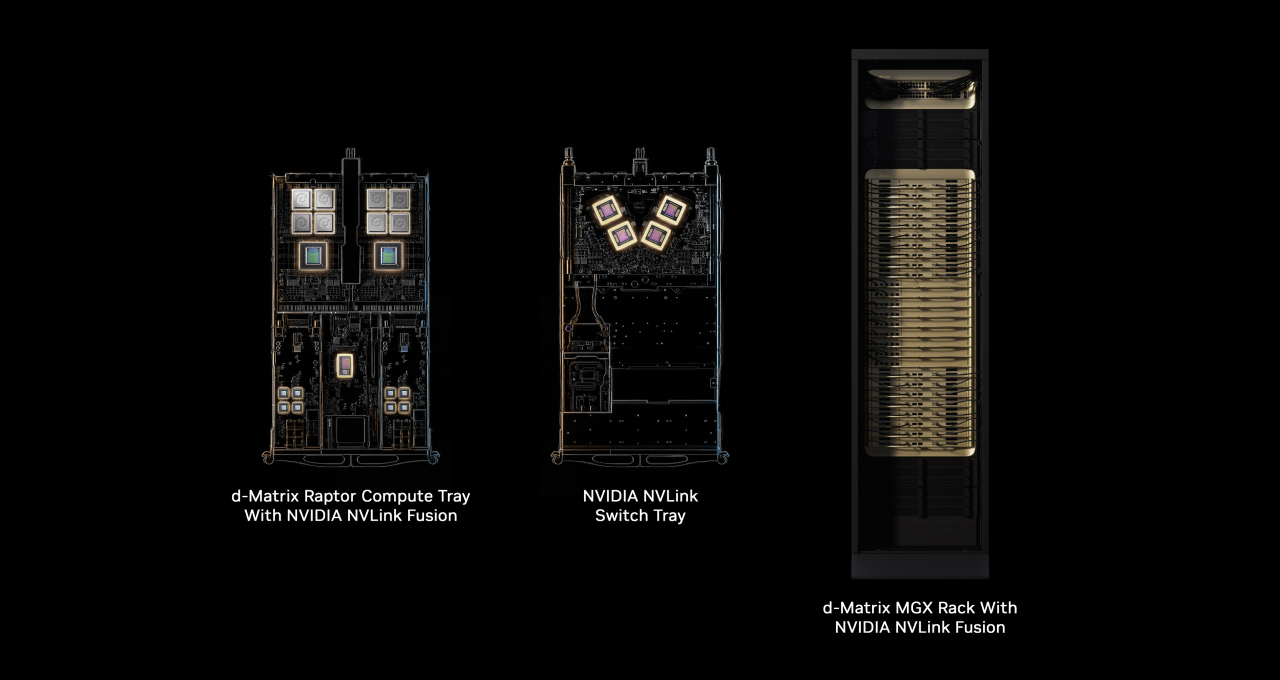
AI inference chipmaker d-Matrix today announced it will use NVLink Fusion to connect its next-generation Raptor XPUs to NVIDIA’s AI infrastructure platform — joining a growing rost…

Nvidia and Palantir want to run supply chains with AI. The article Nvidia and Palantir team up to run supply chains with AI, starting with Nvidia's own million-part operation appea…
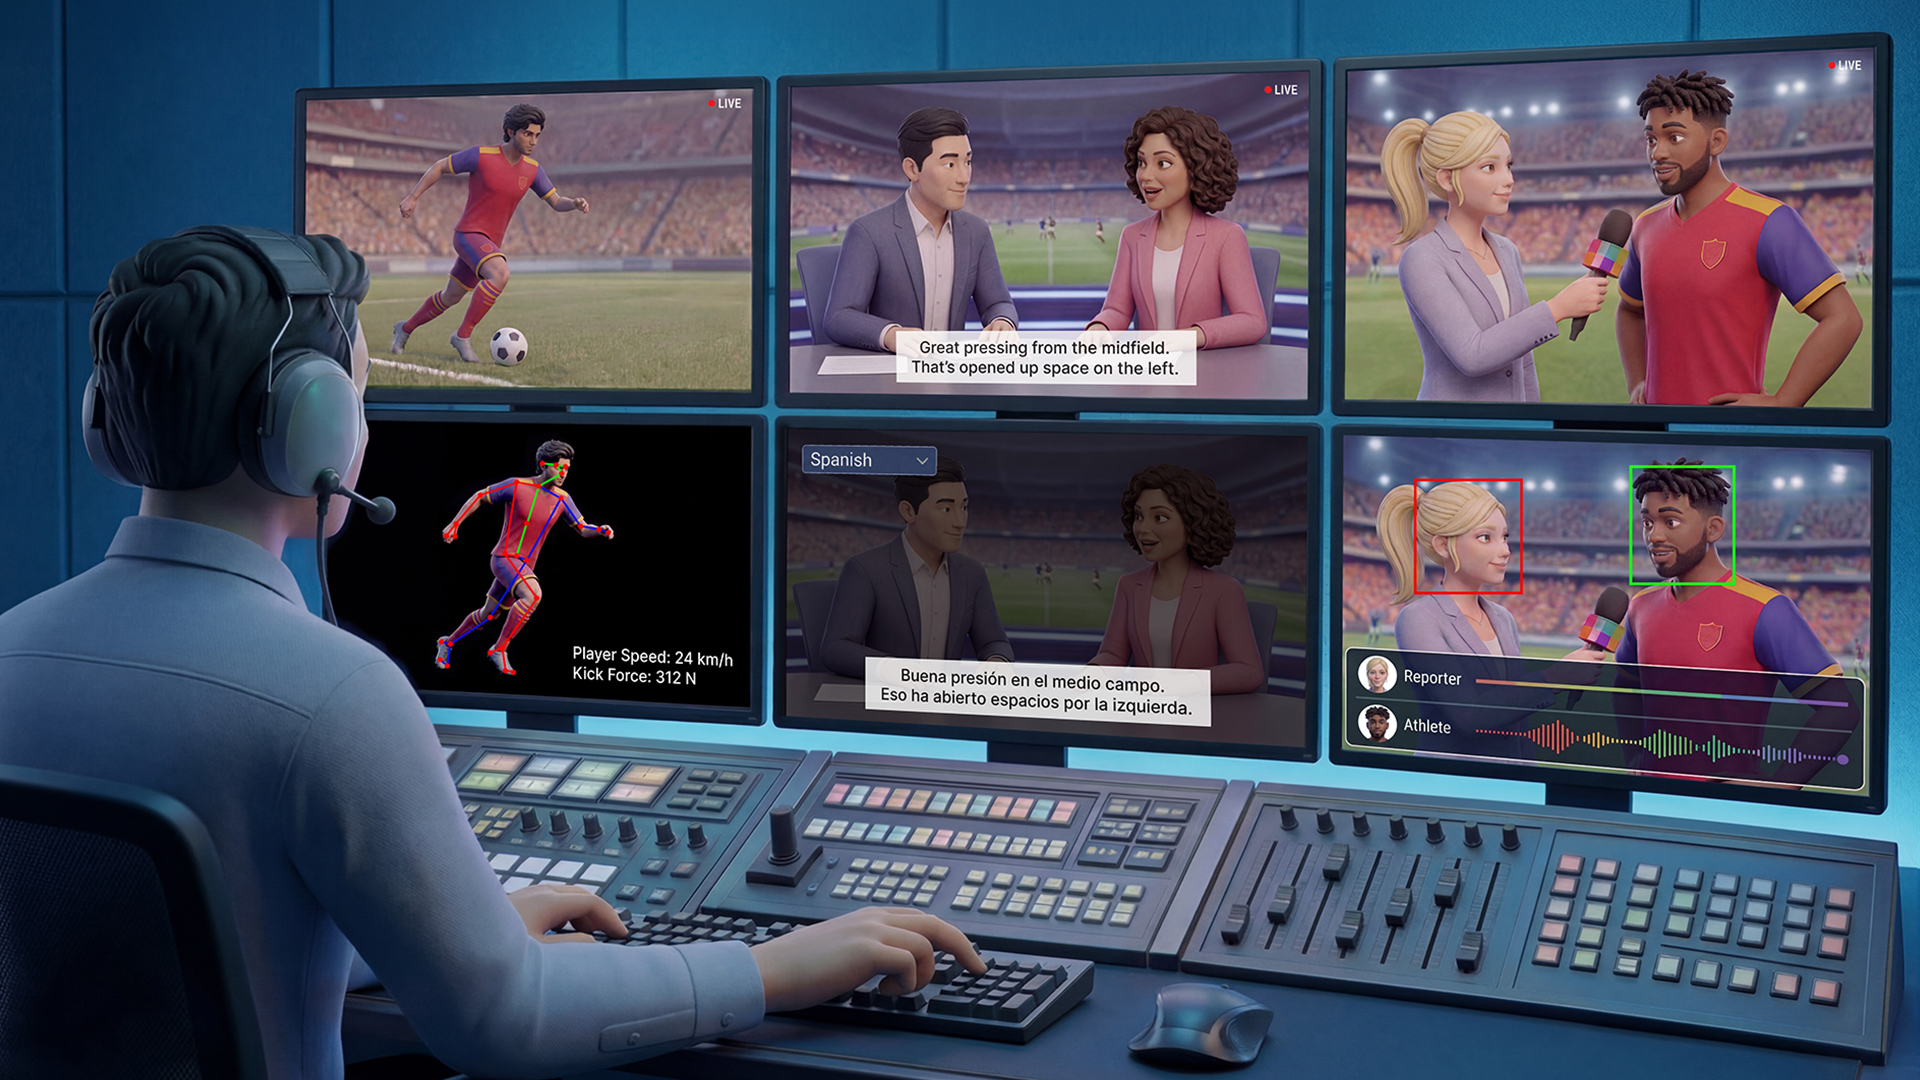
At the IBC conference, running Sept. 11-14 in Amsterdam, the creative, technology and business communities are coming together to turn ideas into action and discuss innovations acr…
We study how model post-training and test-time inference design affect natural-language proof generation for hard olympiad mathematics. Starting from Nemotron 3 Ultra, we train two specialist checkpoi…
NVIDIA has announced CUDA Rust, a push to make Rust a first-class language for GPU kernels. Two open-source NVlabs projects cover the two CUDA programming models: cuda-oxide compil…
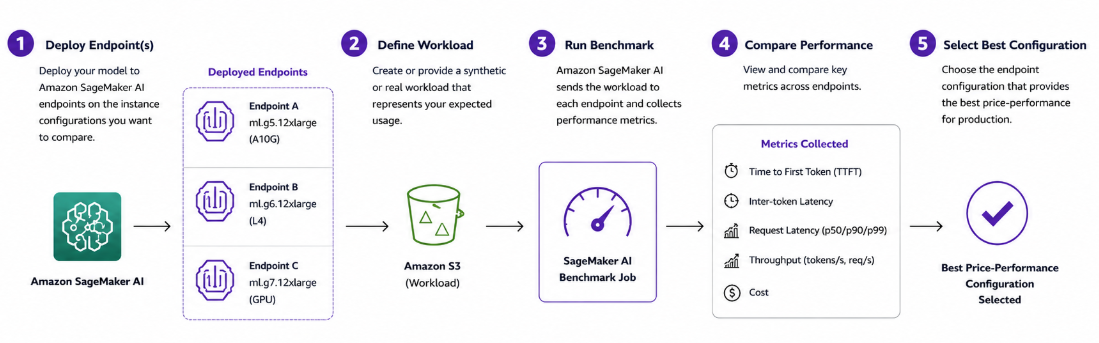
Benchmark two 30B Mixture-of-Experts models, Qwen3-Coder-30B and NVIDIA Nemotron-3-Nano-30B, across G5, G6, G6e, and G7 GPU instances on Amazon SageMaker AI. Compare throughput, la…
We look at NVIDIA Personal AI Router (PAIR), an open source virtual inference router that spreads local AI requests across the machines already on a home network. We cover how PAIR…
AI 点评 · 开源路由打通多设备算力,让本地AI请求自动分流,家庭算力池化迎来新玩法。
AI 点评 · Transformer 生态剧变,关键人物去向牵动开源推理风向。
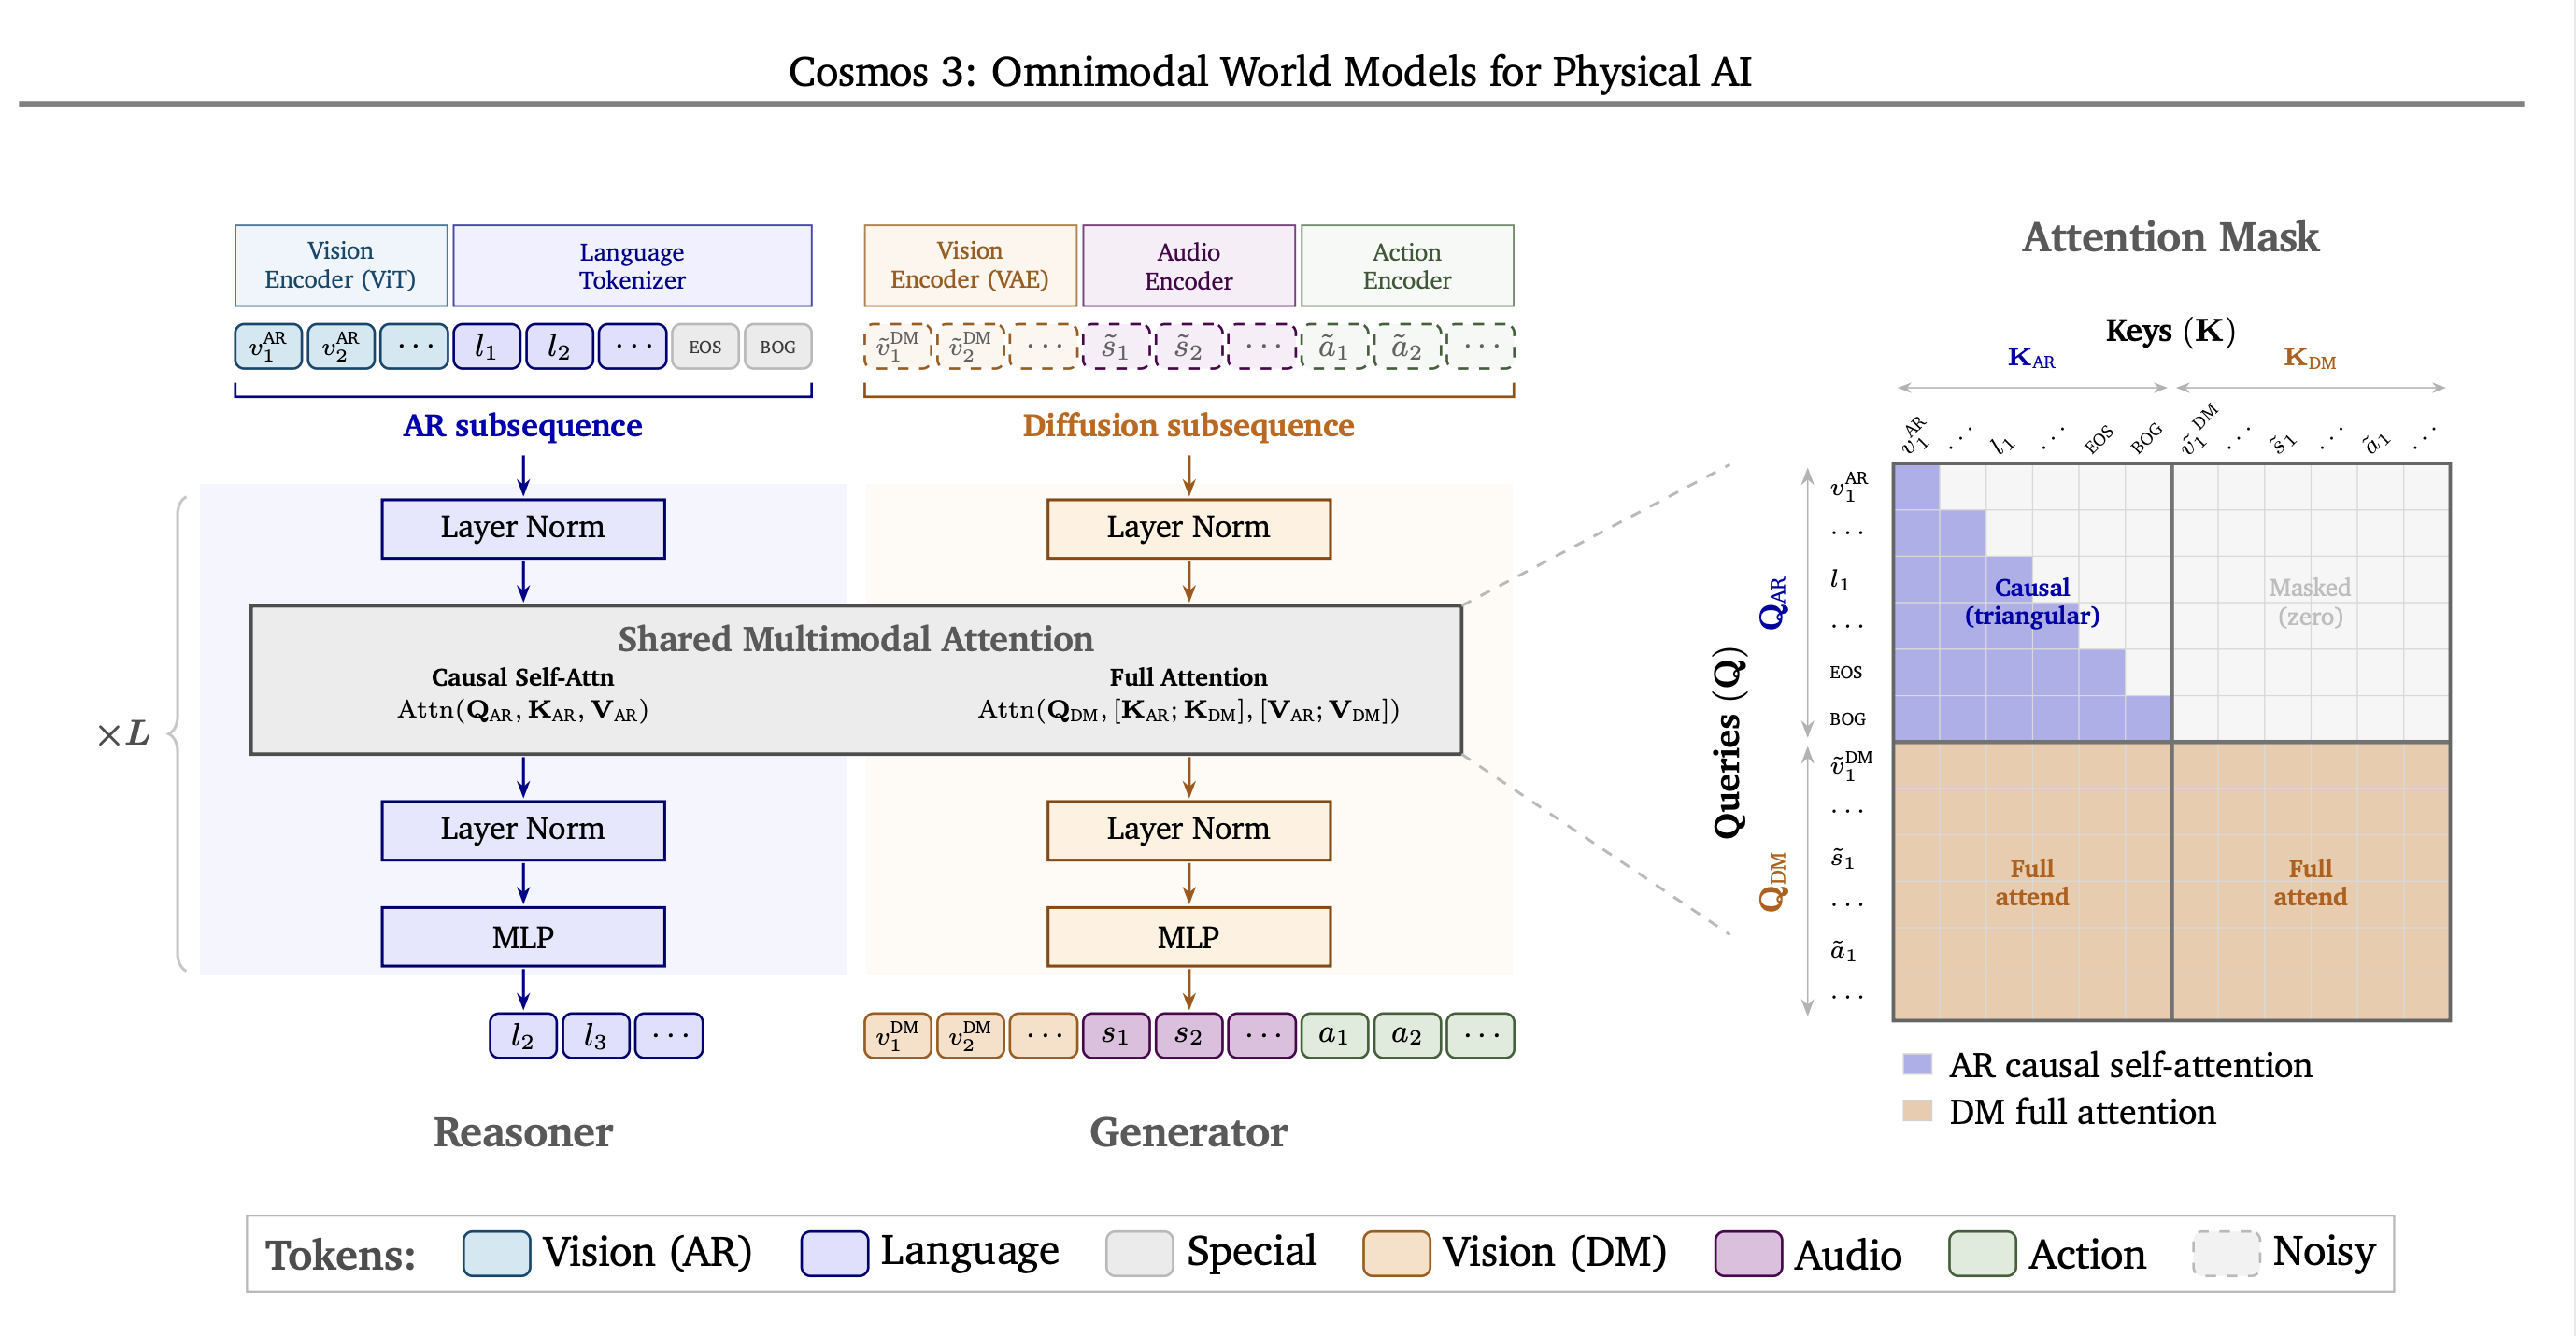
Building a Physical AI system takes a continuous pipeline, not a single training job. This post shows how to run that model factory (synthetic data generation, post-training, and c…
It’s officially the Ternus era at Apple. Tim Cook stepped down as CEO this week, handing the company to former hardware chief John Ternus, whose first memo promised a “huge launch…
Nvidia's PAIR (Personal AI Router) automatically spreads local AI requests across all available devices on a home network, cutting wait times for parallel agent tasks. The article…

IT之家 9 月 4 日消息,根据 NVIDIA(英伟达)官网更新,其面向 Windows on Arm PC 的 RTX Spark N1X 超级芯片处理器在笔记本电脑端提供 2 档配置,而 桌面主机上则仅有“满血”高配 。 可以看到,RTX Spark N1X 面向移动端提供了 5120 核 GPU + 18 核 CPU 的低配, GPU 规模较 614…
AI 点评 · 移动端低配曝光,凸显英伟达细分市场策略,Arm PC竞争再添变数。
Frontier intelligence is going local. At IFA 2026, NVIDIA, Microsoft and its partners are teaming up to provide faster inference and new tools that make agents easier to set up and…
Nvidia is announcing its new Personal AI Router (PAIR), a free tool that syncs up your home computers for tackling local AI inference tasks with tools like Ollama and LM Studio. Le…

Nvidia plans to acquire Hugging Face for about $12.9 billion, securing the central platform for open AI models. More than 18 million developers and 200,000 companies use the hub. C…
Nvidia says Hugging Face will stay open even as the chipmaker takes control of a key AI hub.

At IFA 2026, Nvidia and its partners showed off the first RTX Spark-powered laptops and mini PCs, designed to run AI models right on your computer.

The long-rumored deal will give the chip giant access to—and help it promote—a huge repository of open-source AI models and data sets.
Nvidia said Hugging Face hosts over 3 million models and is used by over 18 million developers.
Nvidia has agreed to buy Hugging Face for $12.93 billion, bringing one of the most popular hosting platforms for open-source AI models, datasets, and tools under the ownership of t…
https://blogs.nvidia.com/blog/nvidia-to-acquire-hugging-face...
I’m excited to announce that NVIDIA has agreed to acquire Hugging Face for $12,930,300,000. Together, we will scale Hugging Face’s platform, strengthen its infrastructure and expan…

Anthropic has signed a $35 billion cloud computing deal with Lambda, an Nvidia-backed cloud provider. The article Anthropic ramps up Claude infrastructure with $35 billion Lambda d…
On our new Real World AI stage, we’ll be focusing on the intersection between the digital and physical, and all the ways we’ll continue to see a blending of the two.
AI 点评 · 虚实融合成AI新战场,Nvidia与机器人同台,看点在于前沿技术如何落地现实场景。
NVIDIA has released Switchyard, an Apache-2.0 Rust proxy and library for LLM traffic. It decodes requests into provider-neutral types, routes them with passthrough, random, LLM-cla…
AI 点评 · 跨厂商LLM流量统一路由,开源Rust实现,填补多API兼容空白。
Stable 4-bit floating-point (FP4) pretraining is difficult because the E2M1 payload represents only a narrow range of magnitudes. NVIDIA's Transformer Engine \nv{} recipe addresses this with current-t…
Nvidia is officially launching DLSS 5 this week, following a divisive announcement in March where we likened the AI upscaling tech to a "real-time generative AI filter for video ga…

IT之家 9 月 1 日消息,英伟达与联发科 8 月 31 日宣布加深长期合作,打造涵盖 AI 基础设施、本地 AI 计算和汽车领域的下一代 AI 计算平台。 作为扩展合作的一部分,联发科将采用 NVIDIA NVLink Fusion 平台,为超大规模企业、云服务提供商和前沿模型开发者提供预验证的路径, 开发定制 XPU 并将其引入 NVIDIA NVLi…
AI 点评 · 芯片巨头跨界结盟,AI、PC、汽车三线并进,生态版图再扩张。
Nvidia invests $3.5 billion into Taiwanese chipmaker MediaTek. The deal shows how Nvidia plans to stay essential to AI infrastructure as Big Tech begins to build its own AI chips.
In this tutorial, we build an ensemble weather forecasting workflow with NVIDIA Earth2Studio. We install the required Earth2Studio components while preserving Colab’s existing CUDA…
AI 点评 · 开源工具链让AI气象预测门槛骤降,批量集成预报实战教程可复现,对研究者和工程团队极具参考价值。
The new generation of data center systems is increasing efficiency with smarter traffic control instead of just more processor cycles.
AI 点评 · 芯片巨头转向系统级优化,智能调度成新战场,算力效率比拼升级。
Neocloud Lambda has raised $1B in private debt to buy Nvidia AI chips and lease them to Microsoft. It's the latest in a string of loans, underscoring the high cost of the AI boom.
AI 点评 · AI算力军备竞赛白热化,千亿融资凸显芯片租赁商业模式的高杠杆与高风险。
Validated GLM-5.3 Flash recipe for 2x NVIDIA RTX PRO 6000 Blackwell 96GB: 262K context, EXL3/TR3, adaptive MTP, tools, and vision.
AI 点评 · 英伟达自证造血能力,AI投资热潮的关键风向标。
Nvidia is nabbing critical infrastructure for open models as interest grows.
AI 点评 · 英伟达揽下开源模型枢纽,AI生态话语权再落一子。
On Nvidia's earnings call Wednesday, CEO Jensen Huang casually announced the company had "achieved AGI," one of the tech industry's ultimate goals some of its biggest players have…

Serving automatic speech recognition (ASR) models at scale is costly when each request uses only a fraction of a GPU. Learn how NVIDIA CUDA Multi-Process Service (MPS) with NVIDIA…
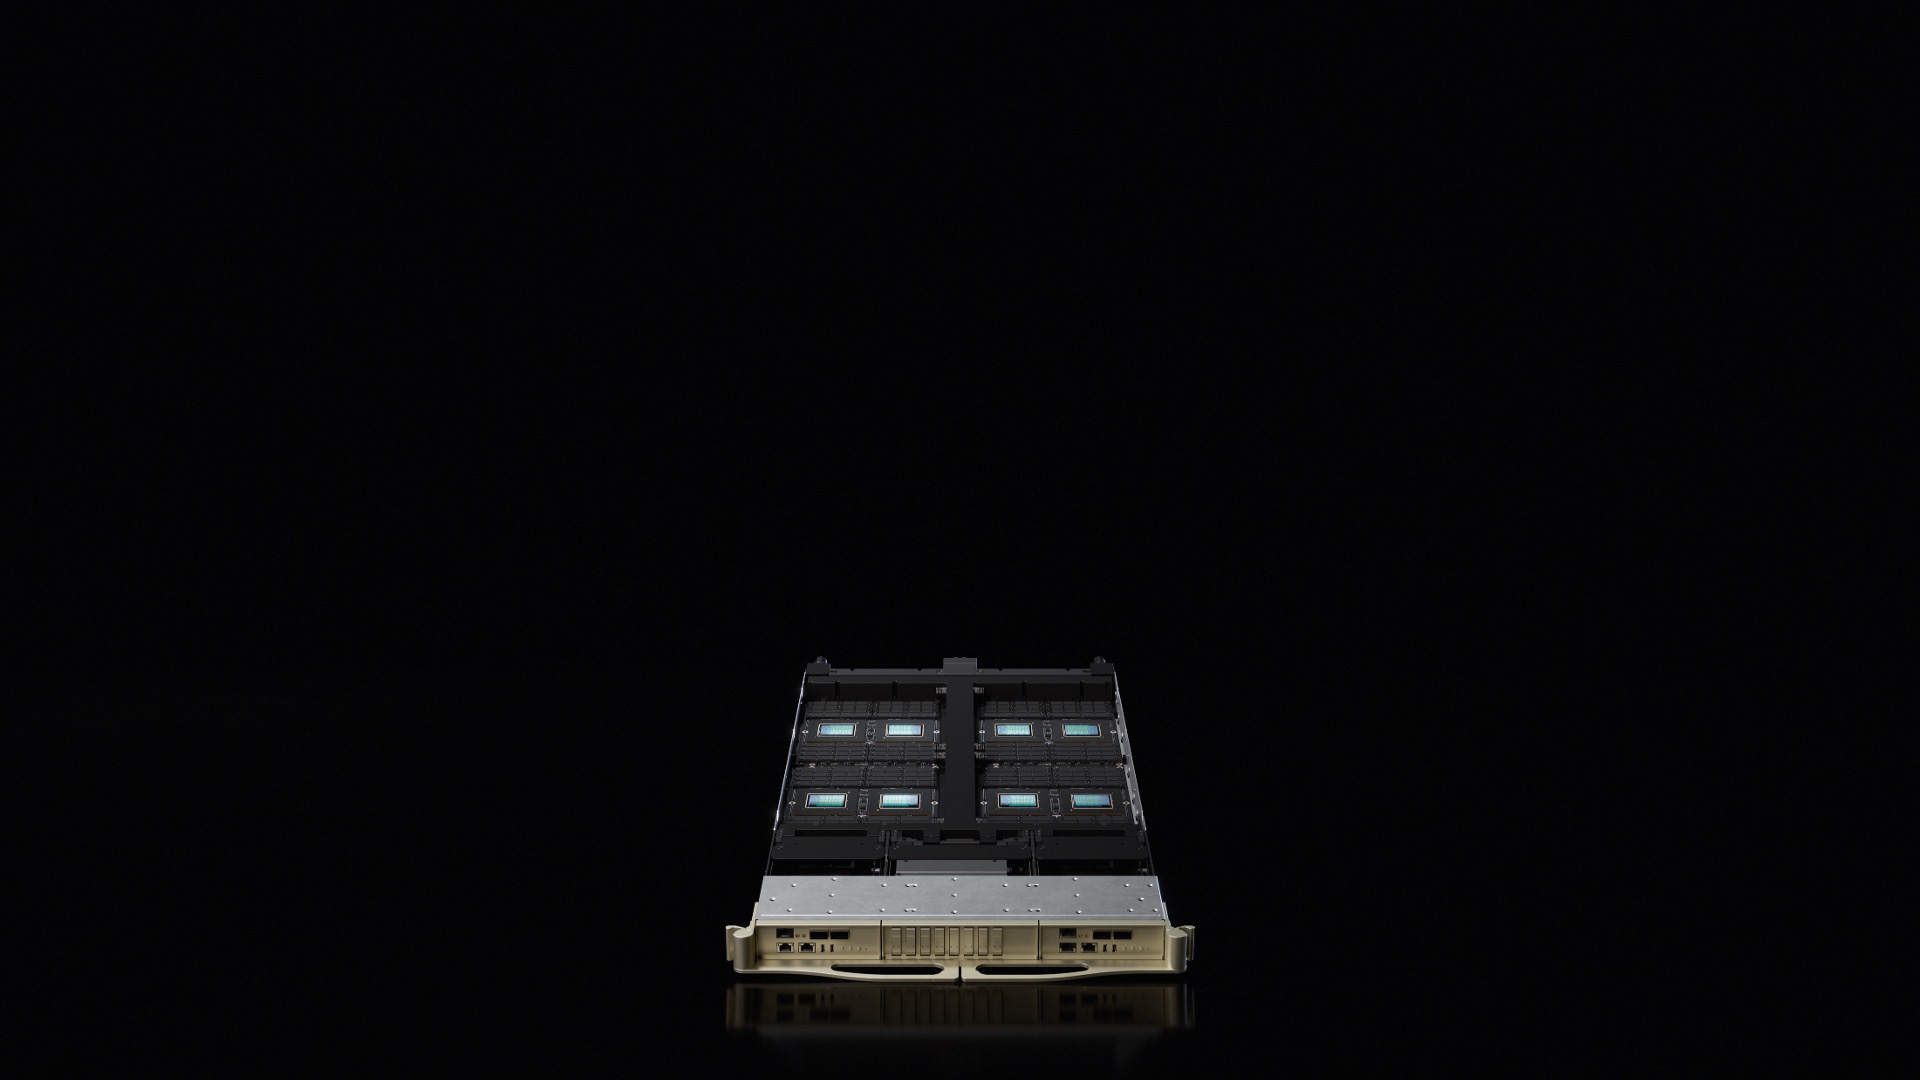
NVIDIA Vice President of Hyperscale and HPC Ian Buck hand-delivers Vera CPU systems across the AI ecosystem as Vera begins shipping at scale.
Z.ai releases GLM-5.3-Flash, an open-source model with 320 billion parameters that lands just three points behind the larger GLM-5.3 on Artificial Analysis's Intelligence Index, at…

Nvidia is buying open-source AI platform Hugging Face for $12.9 billion, about 80 times its $150 million annual revenue. The deal fits Nvidia's push to invest billions in open AI m…
Nvidia has reportedly agreed to buy Hugging Face, the popular open source AI hub, for $12.9 billion in a move that would let Nvidia both protect its chip empire and jump back into…

IT之家 8 月 27 日消息,韩媒 ZDNET Korea 当地时间 26 日援引消息人士报道称,NVIDIA(英伟达)已要求上游 HBM 内存供应商调整 HBM4 内存的供应规划, 提升 8 层堆叠 (8Hi) 产品占比 ,更高堆叠的 12Hi HBM4 比例相应减少。 全球内存市场当前处于供不应求的状态, 降低堆叠高度能以等量的 HBM4 DRAM D…
AI 点评 · 看点在于英伟达调整HBM4堆叠策略,或暗示成本与良率考量,影响内存供应链格局。
Official SGLang x Datawhale course on LLM inference: understand inference, build a mini-sglang from scratch, then read the real SGLang source and land your firs…
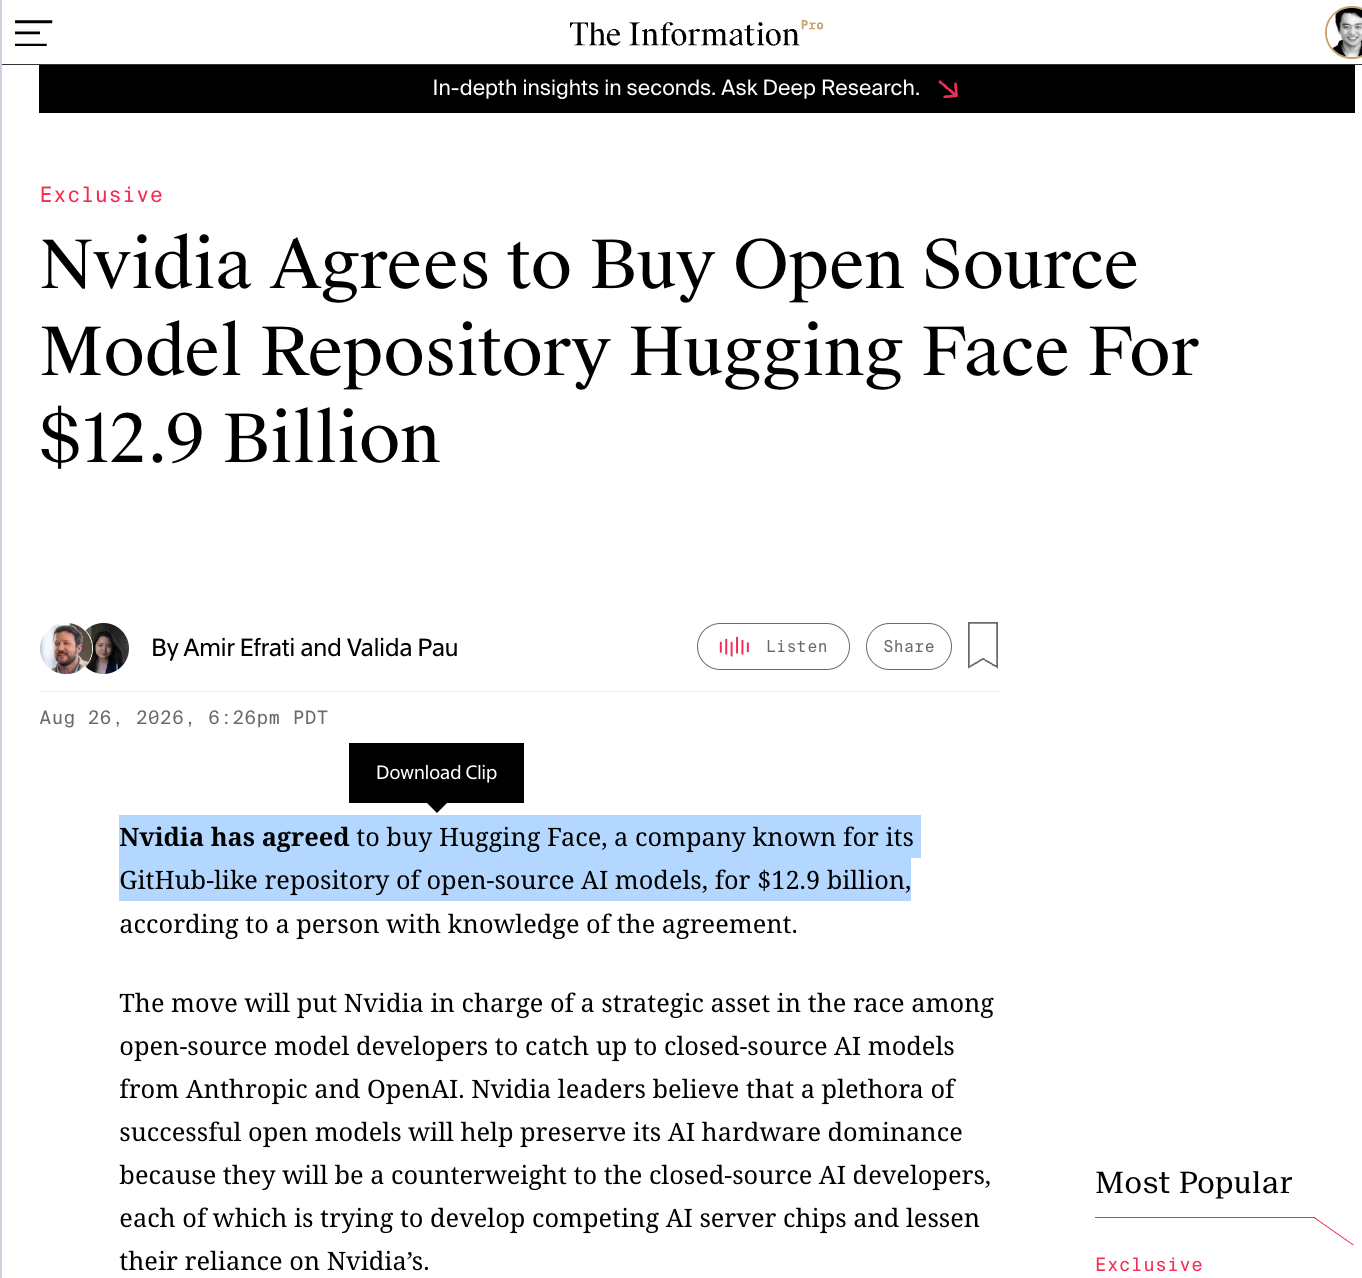
Open Source wins!
AI 点评 · 开源社区迎来巨变,英伟达重金收购HuggingFace,AI生态格局或将重塑。
Amazon is adding another 2 million Nvidia GPU chips to its data centers over the next two years. But this extended partnerships stretches beyond buying more chips.
AI 点评 · 云巨头加码英伟达芯片,凸显AI算力军备竞赛白热化,供应链格局或生变。
Nvidia's predicting it will pull in $108 billion in revenue within just a few months. It wouldn't be the first company to rake in over $100 billion in quarterly revenue - Amazon, A…
AI 点评 · AI巨头单季营收破千亿美元,标志算力需求爆发,或将重塑科技股估值体系。
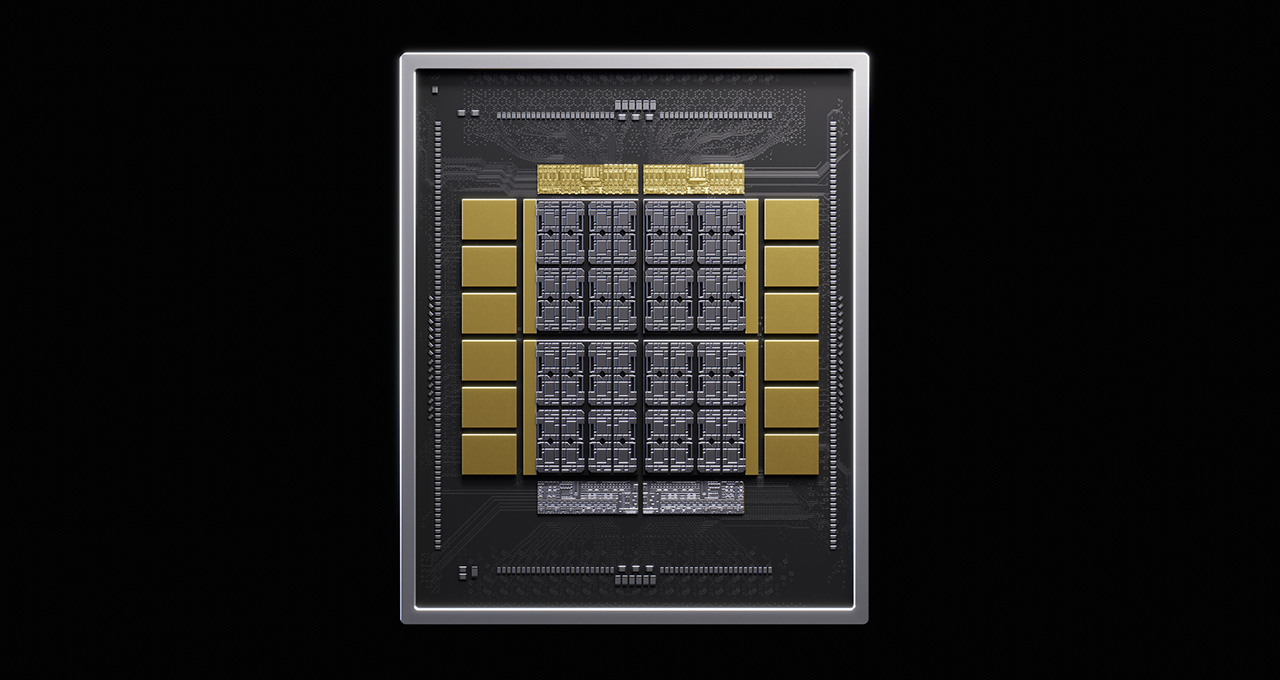
The next wave of AI is placing new demands on infrastructure. As AI agents and trillion-parameter workloads become mainstream, the performance of AI infrastructure depends not only…
AI 点评 · AI算力瓶颈转向内存,NVIDIA自研高带宽存储或重塑硬件格局。
Perplexity releases Portable Computer, packaging local models, harness, sandbox, and connectors into one system running on NVIDIA DGX Spark. The post Perplexity Ships Portable Comp…

OpenAI showed off "Jalapeño," its first in-house inference chip, with benchmarks at the Hot Chips conference. According to SemiAnalysis tests, the chip beats Nvidia's Blackwell and…
AI 点评 · 自研芯片性能反超英伟达,OpenAI硬件话语权大增,AI算力格局或将生变。
https://www.bloomberg.com/news/articles/2026-08-25/openai-cl... , https://archive.ph/yCTrr
AI 点评 · 自研芯片性能对标英伟达,OpenAI硬件自主化提速,或重塑AI算力格局。
Nvidia is moving its Groq 3 LPX inference chip into full production and reports 3,400 tokens per second on Gemma 4 31B, four times faster than Cerebras. But the numbers don't tell…
AI 点评 · 数据亮眼但算法存疑,行业竞争焦点转向推理速度的真实性价比。
Morphological transforms are long-standing tools for shape and mask processing, but the de facto reference implementation in the Python ecosystem, i.e. scipy.ndimage, is CPU-only, single-array, and th…
Nvidia worker indicted after Jensen Huang scolded Supermicro for AI server smuggling.
AI 点评 · 英伟达高管卷入对华AI服务器走私案,凸显巨头涉地缘政治风险,合规警钟再响。

The next era of AI inference won’t be defined by a single breakthrough chip, network or system. It’ll be defined by how every layer of the AI factory works together. That’s why NVI…
AI 点评 · 英伟达量产新一代推理芯片,聚焦AI工厂全栈协同,标志智能体规模化部署进入新阶段。
According to OpenRouter data, agentic AI workloads consume 15x more tokens than a simple chat request. Why? Consider what happens when an AI agent researches a company for an inves…
AI 点评 · 能耗效率提升30倍,直击智能体高消耗痛点,重新定义AI推理性价比标杆。
Nvidia is negotiating an investment in Perplexity at a valuation above $30 billion, more than 50 percent higher than its last funding round, The Information reports. Perplexity's a…
**Agent harnesses** are becoming a key optimization focus, with NVIDIA research showing traditional skill checks poorly predict agent usefulness and proposing a new metric called *…
Nvidia servers with Vera Rubin and Grace Blackwell chips are set to cost about 15 percent more due to an ongoing DRAM shortage from Samsung, SK Hynix, and Micron, Bloomberg reports…
AI 点评 · AI服务器涨价15%,凸显存储芯片瓶颈正成为算力扩张的新关卡。
Nvidia continues to pour money into data center development — just as AI data centers bring lots of money into Nvidia.
AI 点评 · 英伟达重金押注数据中心,AI基建红利循环加速,产业链风向标意义显著。
Nvidia research shows that AI agents can perform well, and not go off the deep end, through fine-tuning, even if the AI model isn't that great at the task.
AI 点评 · 模型平庸也能靠微调出彩,AI应用重心正从算法转向工程控制。

Waymo built its own chip for its robotaxis, cutting its reliance on Nvidia. The article Waymo builds its own chip for its robotaxis, cutting its reliance on Nvidia appeared first o…
Nvidia is paying $6 billion for software that builds AI models from the startup Poolside, and it wants to bring on 109 employees. The article Nvidia is acquiring Poolside's "Model…
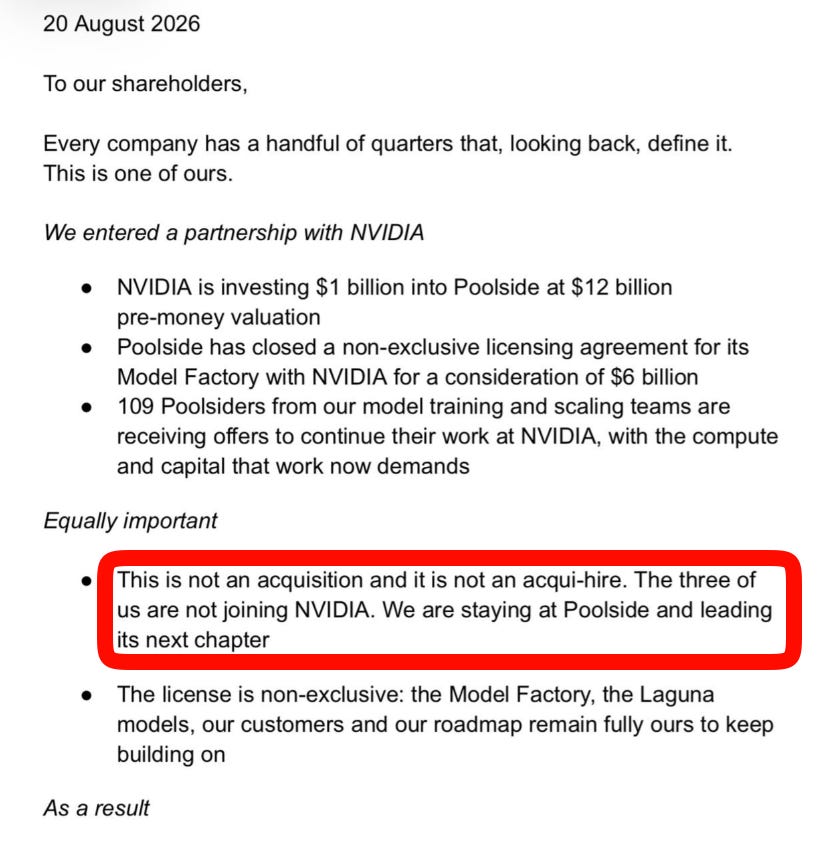
Yes, we’re confused too.
China is letting small batches of Nvidia's H200 chips onto the mainland to help domestic AI firms in the race with the US. The article China lets Nvidia's H200 chips trickle onto t…
April - 1805 Napoleon is master of Europe Only the British fleet stands before him Compute is now an asset class I see it is once again time to talk financial innovation. Apollo, B…
NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an Apache-2.0 project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference…
Take three frontier mixture-of-experts models (Alibaba, OpenAI, NVIDIA; 3.6-4.0B active parameters each) and fine-tune them to reason in a low-resource language. On accuracy benchmarks almost nothing…
NVIDIA teams use ChatGPT Work to reduce manual tasks, connect fast-moving signals, and scale successful workflows globally.
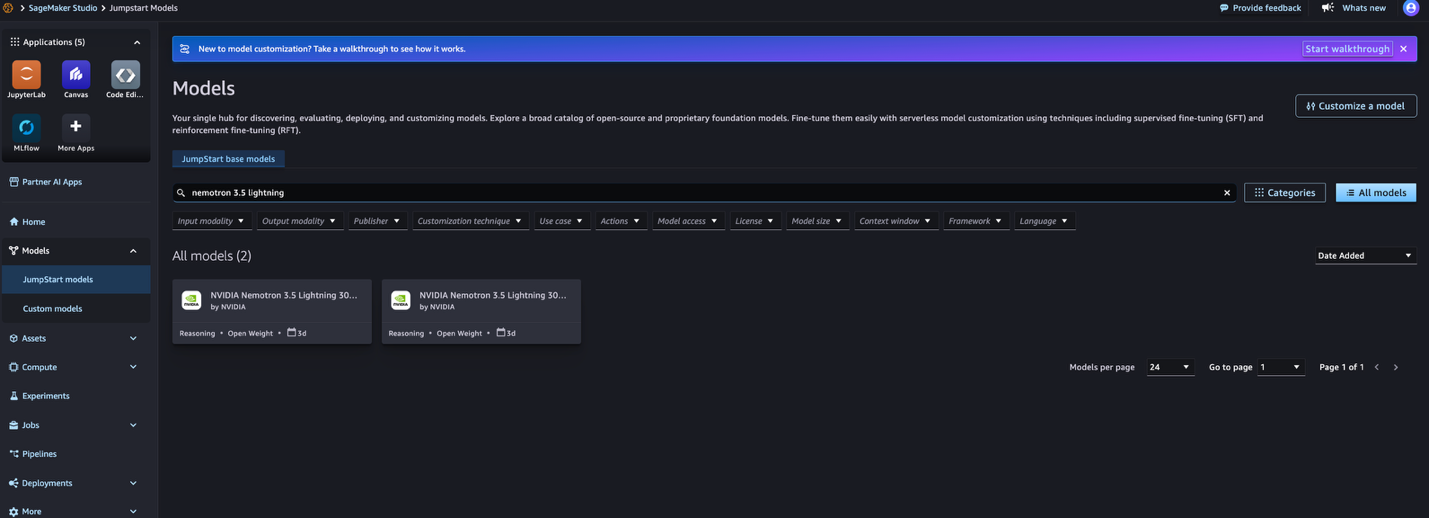
NVIDIA Nemotron 3.5 Lightning, an open model built for high-volume agentic workloads, is now available in Amazon SageMaker JumpStart. This post shows how to deploy the 30B Mixture-…
AI 点评 · 大模型上云提速,30B参数轻量部署,企业智能体落地门槛再降。
Groq raised $350 million at a $3.5 billion valuation as the former AI chipmaker pivots to a neocloud business and expands its Nvidia-powered data center footprint.
AI 点评 · 芯片商转型云服务,估值翻倍印证AI算力需求新风口。
Nvidia's investment in SoftBank's data center developer will guarantee its chips power an OpenAI data center.
AI 点评 · 英伟达押注软银数据中心,锁定OpenAI算力订单,跨界资本绑定凸显AI基建竞争白热化。
Nvidia wants you building your own model, not buying from Anthropic/OpenAI.
AI 点评 · 英伟达推动自建模型,挑战闭源巨头,生态之争再升级。

OpenAI has signed a 20-year lease for an 8-gigawatt data center in Ohio. Nvidia is guaranteeing up to $105 billion for the residual value of the facilities and becomes the exclusiv…
**OpenAI** is advancing its power-and-compute infrastructure with a **4+ GW NVIDIA** capacity commitment and an **8 GW Ohio campus** buildout through **2032**, emphasizing vertical…
Nvidia has cut its guarantee for OpenAI's planned data center in Ohio nearly in half, from $250 billion to just under $120 billion, after investors pushed back on the risk. Meanwhi…
AI 点评 · 英伟达收缩OpenAI押注,恰逢Anthropic数据亮眼,AI投资风向生变。
Tool: CORS Chat I built this today ( with GPT-5.6-Sol xhigh ) to help test Qwen 3.8 27B running in LM Studio on both my M5 MacBook Pro and an NVIDIA DGX Spark. It provides a web UI…
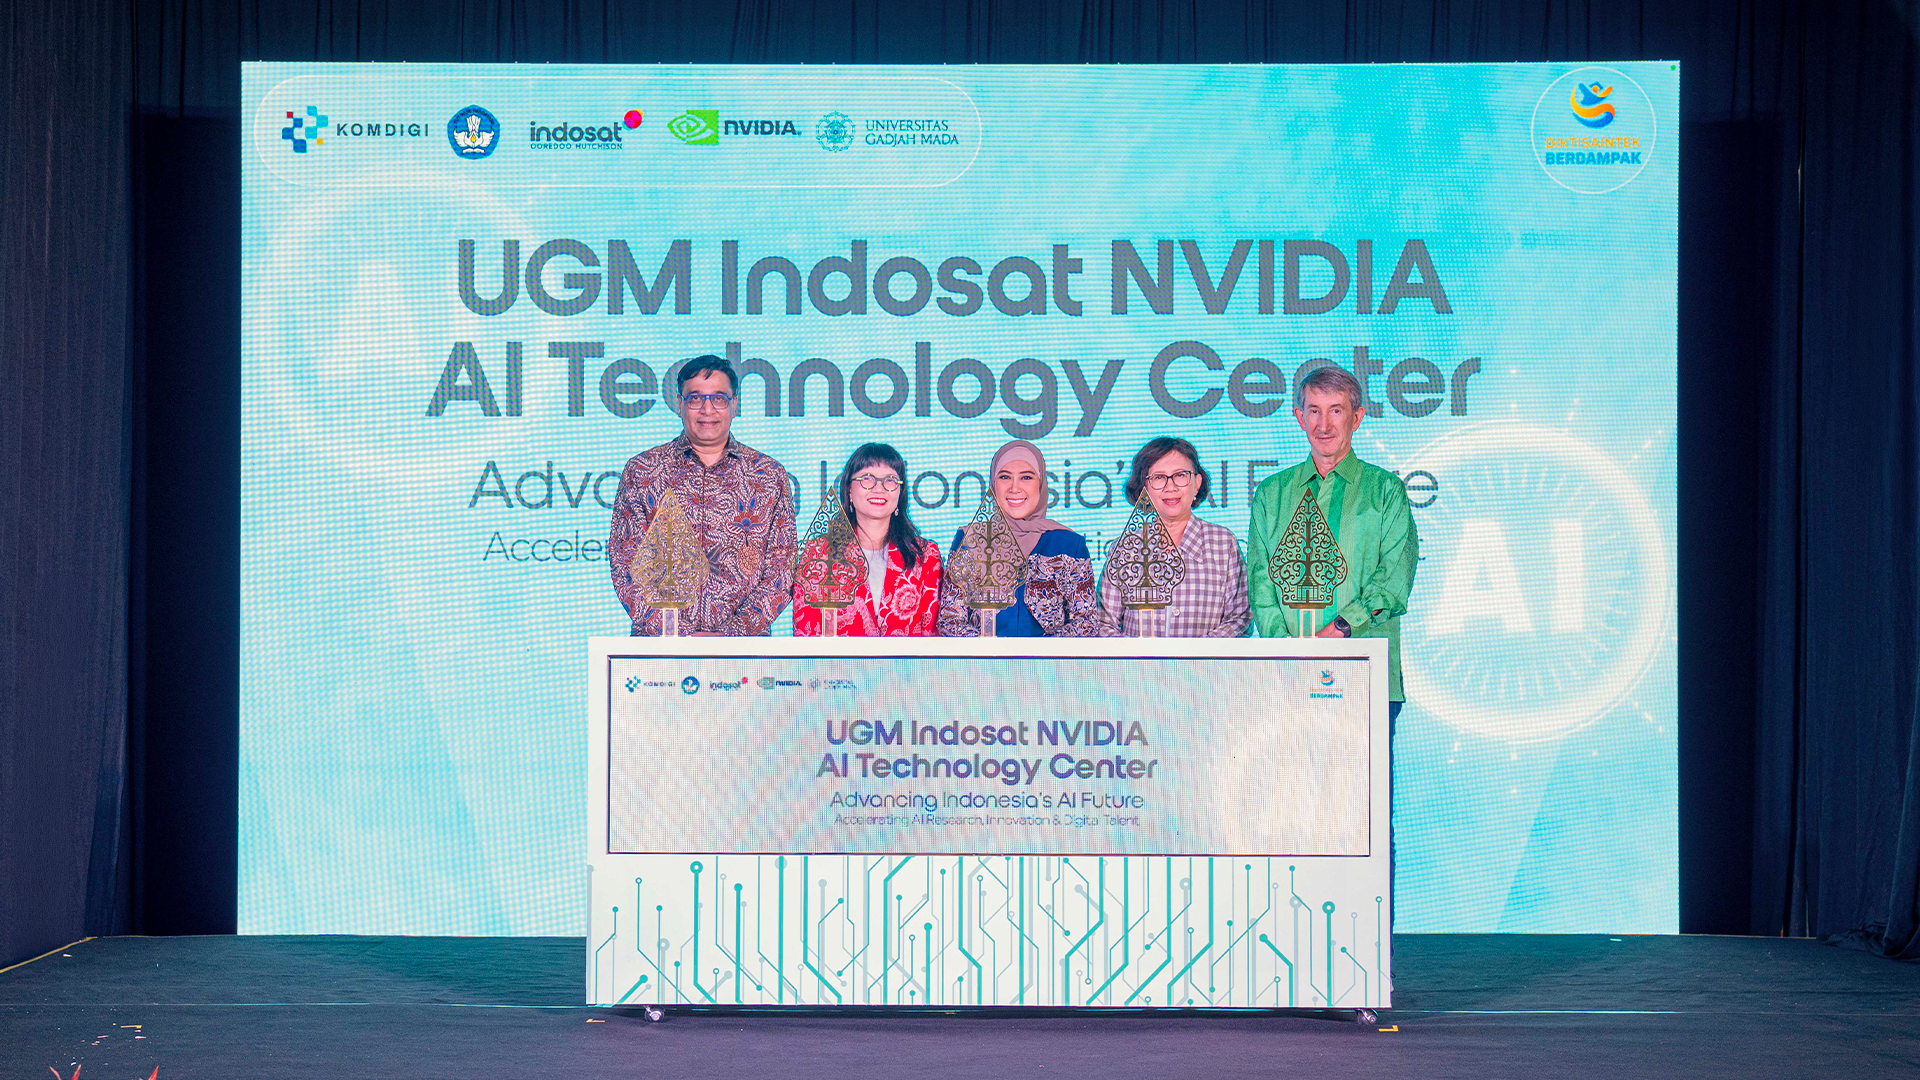
Indonesia is taking charge of its AI future. This week, the Ministry of Communication and Digital Affairs (Komdigi), Indosat Ooredoo Hutchison (Indosat or IOH), NVIDIA and Universi…
AI 点评 · 校企联手建国家级AI中心,东南亚人才竞争升级,中国需警惕生态外溢。
Multi-GPU acceleration for MiniMax H3 video generation on NVIDIA V100 (sm_70). Ulysses sequence parallelism as a drop-in ComfyUI custom node — ~19 min to ~7 min…
Nvidia has a plan to make sure its GPUs won't lose value. It wants to convince a new crop of financiers to keep lending for AI buildouts.
Nvidia is working on Nemotron 4, a new open-weight model designed to rival the world’s best freely available models. The article Nvidia's Nemotron 4 aims for one trillion parameter…
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model. The post NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B…
We announced partnerships with Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs and KKR to establish independent financing platforms designed to mobilize over $500 billion…
LTX-2.5 brings frontier video generation to local NVIDIA hardware: 6.8-second clips, native multishot, day-one ComfyUI, open weights. The post The Video Production Stack Now Fits o…
AI 点评 · 本地开源视频生成首次媲美前沿水平,多镜头与ComfyUI支持将大幅降低创作门槛。
Nvidia's Nemotron 3.5 Lightning is an open-weights model with just 3.6 billion active parameters that matches OpenAI's gpt-oss-120b on the Intelligence Index despite being four tim…
The open source ecosystem is making it easier for AI enthusiasts and developers to build, customize and run increasingly capable agents locally. Throughout August, NVIDIA is celebr…
As AI shifts from chatbots to autonomous agents, open models are serving market demands for full control over where AI runs and how it’s deployed and evolves. Today, NVIDIA is expa…

Nvidia is teaming up with Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs, and KKR to mobilize over $500 billion for AI infrastructure. To win over investors, the chipmake…
AI 点评 · 开源权重加全栈部署控制,让多语言语音代理延迟优化门槛大降。
Run full MiniMax-H3 FL2VA on one RTX A6000: 1344x768 video + stereo audio, 6.16x Turbo, and formal Sol-Attn N=10.
NVIDIA releases NemotronLabs VoiceChat 11B, an open full-duplex speech-to-speech model with 448 ms latency and live tool calling. The post NVIDIA Releases NemotronLabs VoiceChat 11…

The AI industry's hunger for power keeps growing. Nvidia is investing up to $3 billion in Lancium, a power infrastructure developer that already has four gigawatts under contract i…
AI 点评 · 算力军备竞赛延伸至电力赛道,巨头抢滩能源基建成新焦点。
In this tutorial, we build an advanced multimodal retrieval-augmented generation pipeline with NVIDIA NeMo Retriever. We begin by configuring a Python 3.12 environment, installing…
NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt template…
Anthropic and OpenAI are racing to scale up while reducing dependence on Nvidia.
AI 点评 · AI巨头自研芯片,摆脱英伟达依赖,算力军备竞赛升级。
In July, NVIDIA joined more than 200 companies and organizations in signing “Open Weights and American AI Leadership,” an open letter arguing that AI leadership will be measured no…
Modern Greek is absent from NVIDIA's Nemotron retrieval models and from major multilingual retrieval benchmarks, despite being important for retrieval-augmented generation (RAG) in legal, energy, fina…

SpaceX plans to more than 5x its compute capacity by the end of 2027, betting exclusively on Nvidia's Vera Rubin platform. The expansion could require well over a million new GPUs.…
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commerci…
CUDA又危了?
Modern Greek is absent from NVIDIA's Nemotron retrieval models and from major multilingual retrieval benchmarks, despite being important for retrieval-augmented generation (RAG) in legal, energy, fina…
The week-old Open Secure AI Alliance, spearheaded by Nvidia and grown to over 120 companies, already has proposals out for defending against AI agents.
AI 点评 · 英伟达主导百家企业联盟,一周即出AI安全方案,动作之快凸显行业对智能体威胁的紧迫共识。
NVIDIA is participating in the U.S. National Science Foundation’s (NSF) State and Regional Artificial Intelligence Infrastructure Hubs program, an effort launching today to expand…
**Alibaba** launched **Qwen3.8-Max**, enhancing multimodal capabilities and agent ecosystem integration. **NVIDIA** introduced **Alpamayo 2 Super** for autonomous vehicle reasoning…
NVIDIA Sol-Attn for ComfyUI / Triton kernel on SM89 - SM121, with zero-copy MiniMax H3 nodes: memory-efficient attention, scheduled tau with graph preview, and…

Figure 1: CUDA-to-MLX optimization translation map. CUDA optimization knowledge can be translated into architecture-native MLX strategies rather than copied instruction-for-instruc…
Run NVIDIA's tri-modal Nemotron Omni (text+vision+audio) entirely on Apple Silicon — pure MLX runtime, parity-verified against NVIDIA's reference


