
行业动态NEW
18 分钟前
IT之家 10 月 21 日消息,Salesforce 将收购 Braze,交易估值约 56.6 亿美元 (IT之家注:现汇率约合 378.73 亿元人民币) 。借助这套能够让品牌发送个性化消息、实时响应客户行为的工具,Salesforce 将强化自身人工智能业务布局。 交易公布后,Braze 的股价在当地时间周二上涨超 50%。 投资者担忧人工智能技术的快…
AI 点评 · 客户互动数据与AI结合将重塑营销自动化格局,巨头整合提速。
共 459 条相关资讯 · 来自历史归档
IT之家 10 月 21 日消息,Salesforce 将收购 Braze,交易估值约 56.6 亿美元 (IT之家注:现汇率约合 378.73 亿元人民币) 。借助这套能够让品牌发送个性化消息、实时响应客户行为的工具,Salesforce 将强化自身人工智能业务布局。 交易公布后,Braze 的股价在当地时间周二上涨超 50%。 投资者担忧人工智能技术的快…
AI 点评 · 客户互动数据与AI结合将重塑营销自动化格局,巨头整合提速。

IT之家 10 月 21 日消息,据《华尔街日报》当地时间周二报道,Anthropic 上半年净亏损超过 800 亿美元 (IT之家注:现汇率约合 5,354.93 亿元人民币) ,同时释放信号:未来数年可能投入高达 7,500 亿美元 (现汇率约合 5.02 万亿元人民币) ,用于扩充算力资源。 报道援引一份首次公开募股(IPO)招股书草案称,去年同期该公…
AI 点评 · AI巨头烧钱规模远超营收,亏损与天量算力投入并存,IPO估值逻辑正遭根本性质疑。
OpenAI says it's adding Orchestra's team and technology to work on Rosalind, its AI model for life sciences research, and to its related Rosalind Workbench tool, a harness that aim…
AI 点评 · OpenAI借收购补强生命科学AI布局,Rosalind生态加速落地值得关注。
OpenAI is acquiring Orchestra Bio to bring AI-powered operations to life sciences R&D, helping biopharma teams accelerate drug development and advance new treatments.
IT之家 10 月 20 日消息,据路透社报道,两位知情人士称,OpenAI 正争分夺秒地争取投资者承诺,力求在竞争对手 Anthropic 预计于 11 月中旬上市之前完成融资。此次融资节奏异常迅速,若顺利完成, 这家 ChatGPT 开发商的估值可能超过 1.4 万亿美元 (IT之家注:现汇率约合 9.37 万亿元人民币) 。 知情人士表示,这种紧凑的时…
AI 点评 · 资本竞速背后是AI双雄争霸,融资节奏折射上市窗口争夺战。

IT之家 10 月 20 日消息,据彭博社报道,知情人士透露,谷歌前首席执行官埃里克 · 施密特(Eric Schmidt)凭借对初创公司 Anthropic 的早期投资,持有该公司约 1% 的股份。一旦这家企业登陆公开市场,这笔投资将成为个人投资者中收益最高的几笔投资之一。 不愿具名的消息人士称,施密特在 Anthropic 的 A 轮融资中投入了数千万美…
AI 点评 · 科技巨头前掌门人押注对手阵营,AI权力版图与资本暗线交织,值得细看。
After drawing acquisition interest earlier this year, the Nvidia challenger raised $1.5 billion to remain independent.
AI 点评 · 开源芯片挑战英伟达获巨额融资,估值飙升显示资本押注AI硬件多元化。
Long-horizon agents must learn heterogeneous capabilities from interleaved trajectories. Updating shared parameters to learn new capabilities can degrade previously acquired ones, resulting in catastr…
Frontier agents retrieve structural metadata well and compute geometry from coordinates less reliably. We ask how much of a benchmark score reflects that gap and how much reflects the evaluation confi…
Context compression improves long-context efficiency but may introduce faithfulness issues through an information bottleneck. Existing evaluations rely on QA metrics, but a reader can still answer cor…
Learn how OpenAI is improving ChatGPT across low-resource programming languages, with new evaluations for software engineering, SQLite, and COBOL migration.
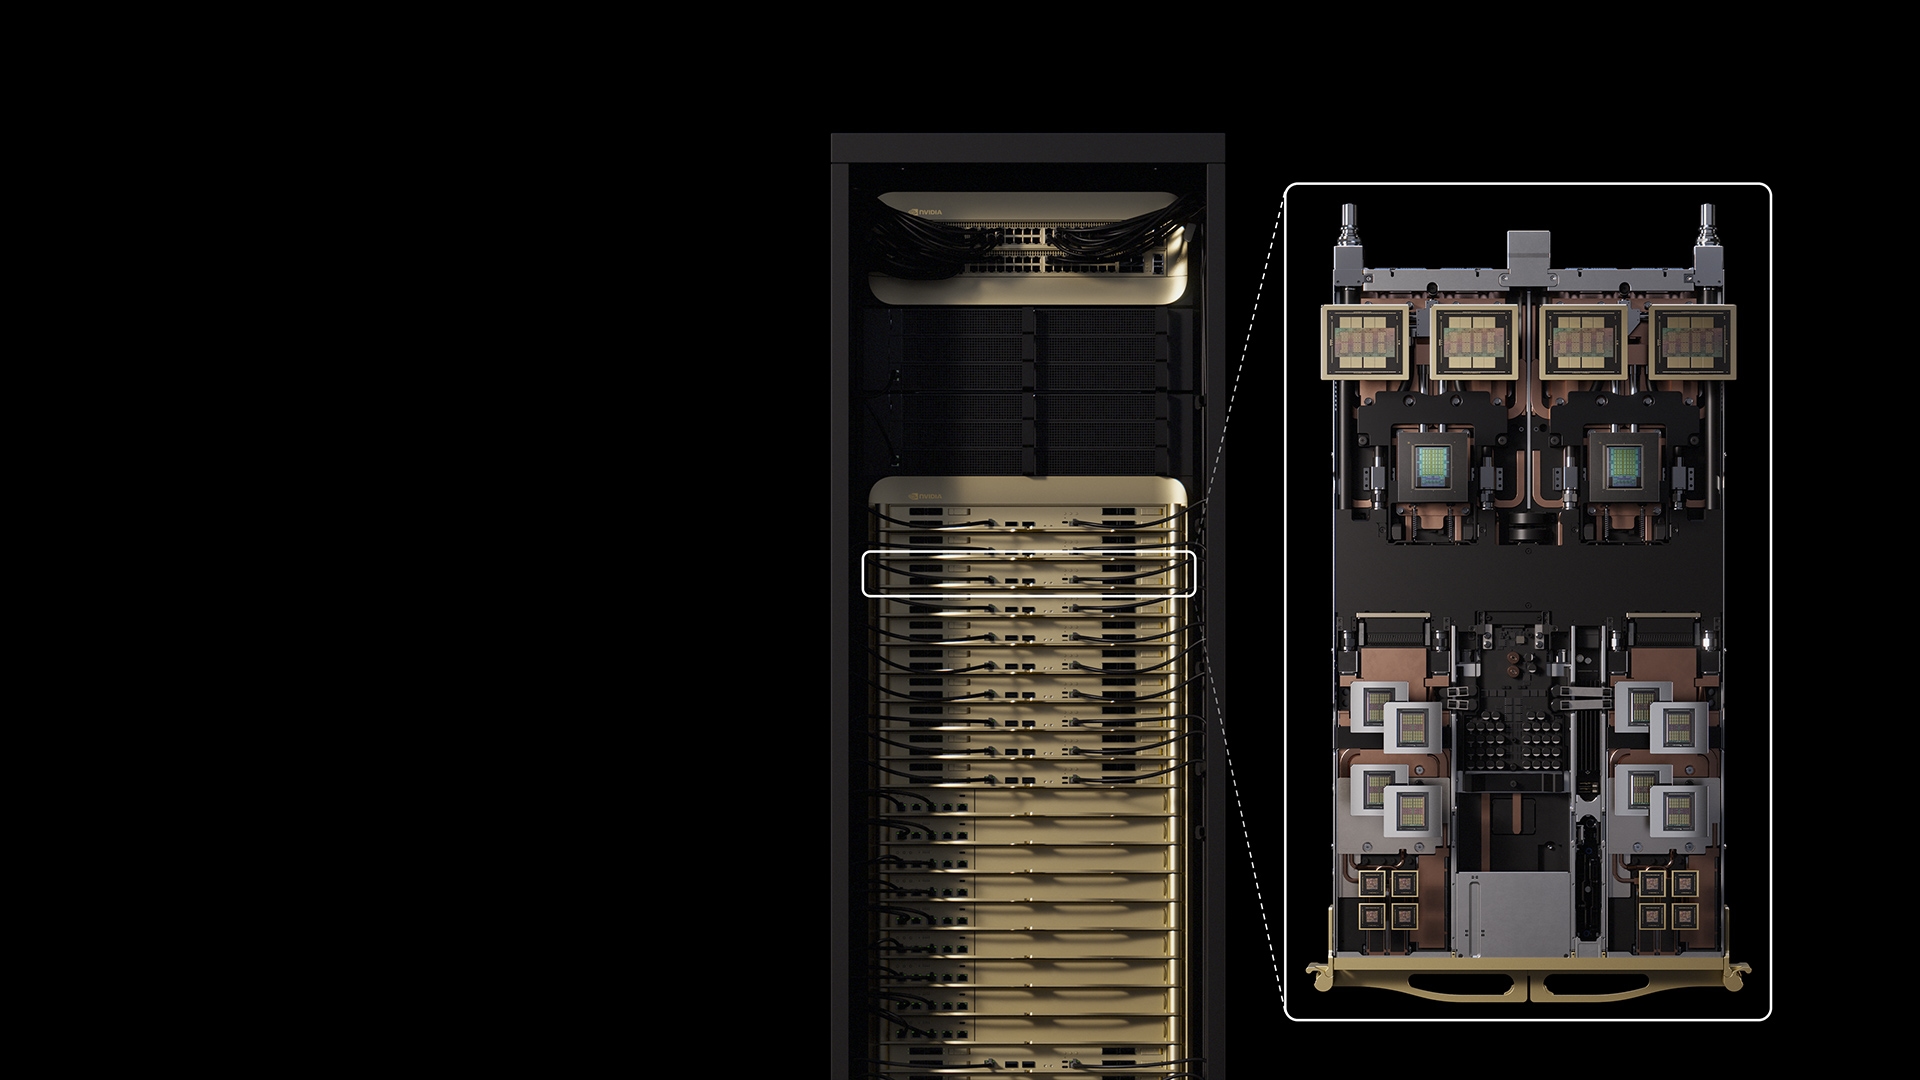
After stock crashes and Firmus's scrapped IPO, industry executives expect only seven to ten of the hundreds of AI cloud providers to survive. CoreWeave lost a quarter of its market…

IT之家 10 月 19 日消息,据央视财经援引英国《金融时报》16 日报道, 美国人工智能企业 Anthropic 正在以超过 10% 的收益率 ,吸引黑石集团为其芯片交易提供融资。 这笔总额为 600 亿美元 (IT之家注:现汇率约合 4,021.75 亿元人民币) 的债务融资分为两部分: 一是约 420 亿美元(现汇率约合 2,815.22 亿元人民币…
AI 点评 · 算力军备竞赛推高融资成本,AI巨头借钱买芯片的隐忧值得警惕。

IT之家 10 月 19 日消息,据彭博社报道,知情人士透露,在人工智能公司遭遇一系列市场挫折后,Nscale 公司的首次公开募股所追求的估值目标正面临阻力。 知情人士称,这家获得英伟达投资的数据中心开发商原本寻求约 300 亿美元 (IT之家注:现汇率约合 2,010.87 亿元人民币) 的 IPO 估值。部分知情人士表示,考虑到澳大利亚人工智能数据中心企…
AI 点评 · AI数据中心估值遭腰斩,折射市场对算力泡沫的警惕,英伟达系光环也难撑高溢价。
IT之家 10 月 19 日消息,当地时间 10 月 18 日,Anthropic 宣布,在获得股东批准的前提下, 公司计划将 5% 的股份划入新设立的公共利益基金 (Public Benefit Fund);且随着这家人工智能巨头的估值增长,该基金持有的股份比例未来还可能进一步提升。 该拟议的基金将作为一家全资拥有的有限责任公司设立,经董事会裁量,公司估值…
AI 点评 · AI巨头用股权绑定公共利益,为行业治理提供可复制的资本化样本。
https://x.com/Jiaru_Zou/status/2110400256647340476 https://github.com/togethercomputer/HybridAgent https://huggingface.co/collections/togethercomputer/hybridag... Evaluations: http…
AI 点评 · 混合推理让智能体在潜空间思考、用文本行动,兼顾效率与可解释性,为智能体架构提供新范式。
We set out to reproduce a recent hallucination-mitigation result on the POPE benchmark. The LLaVA-1.5-7B baseline we measured, 82.21 F1 on the adversarial split, sat 1.21 to 8.67 points above the adve…
Robotic value models assess task execution from visual observations and instructions, providing feedback for policy learning and execution monitoring. However, existing evaluations cover only selected…
Voxel51 3.0 merges search, curation, annotation and evaluation of multimodal sensor data into one platform for physical AI teams. It adds Voxel51 Agent with 45+ MCP tools, dataset…
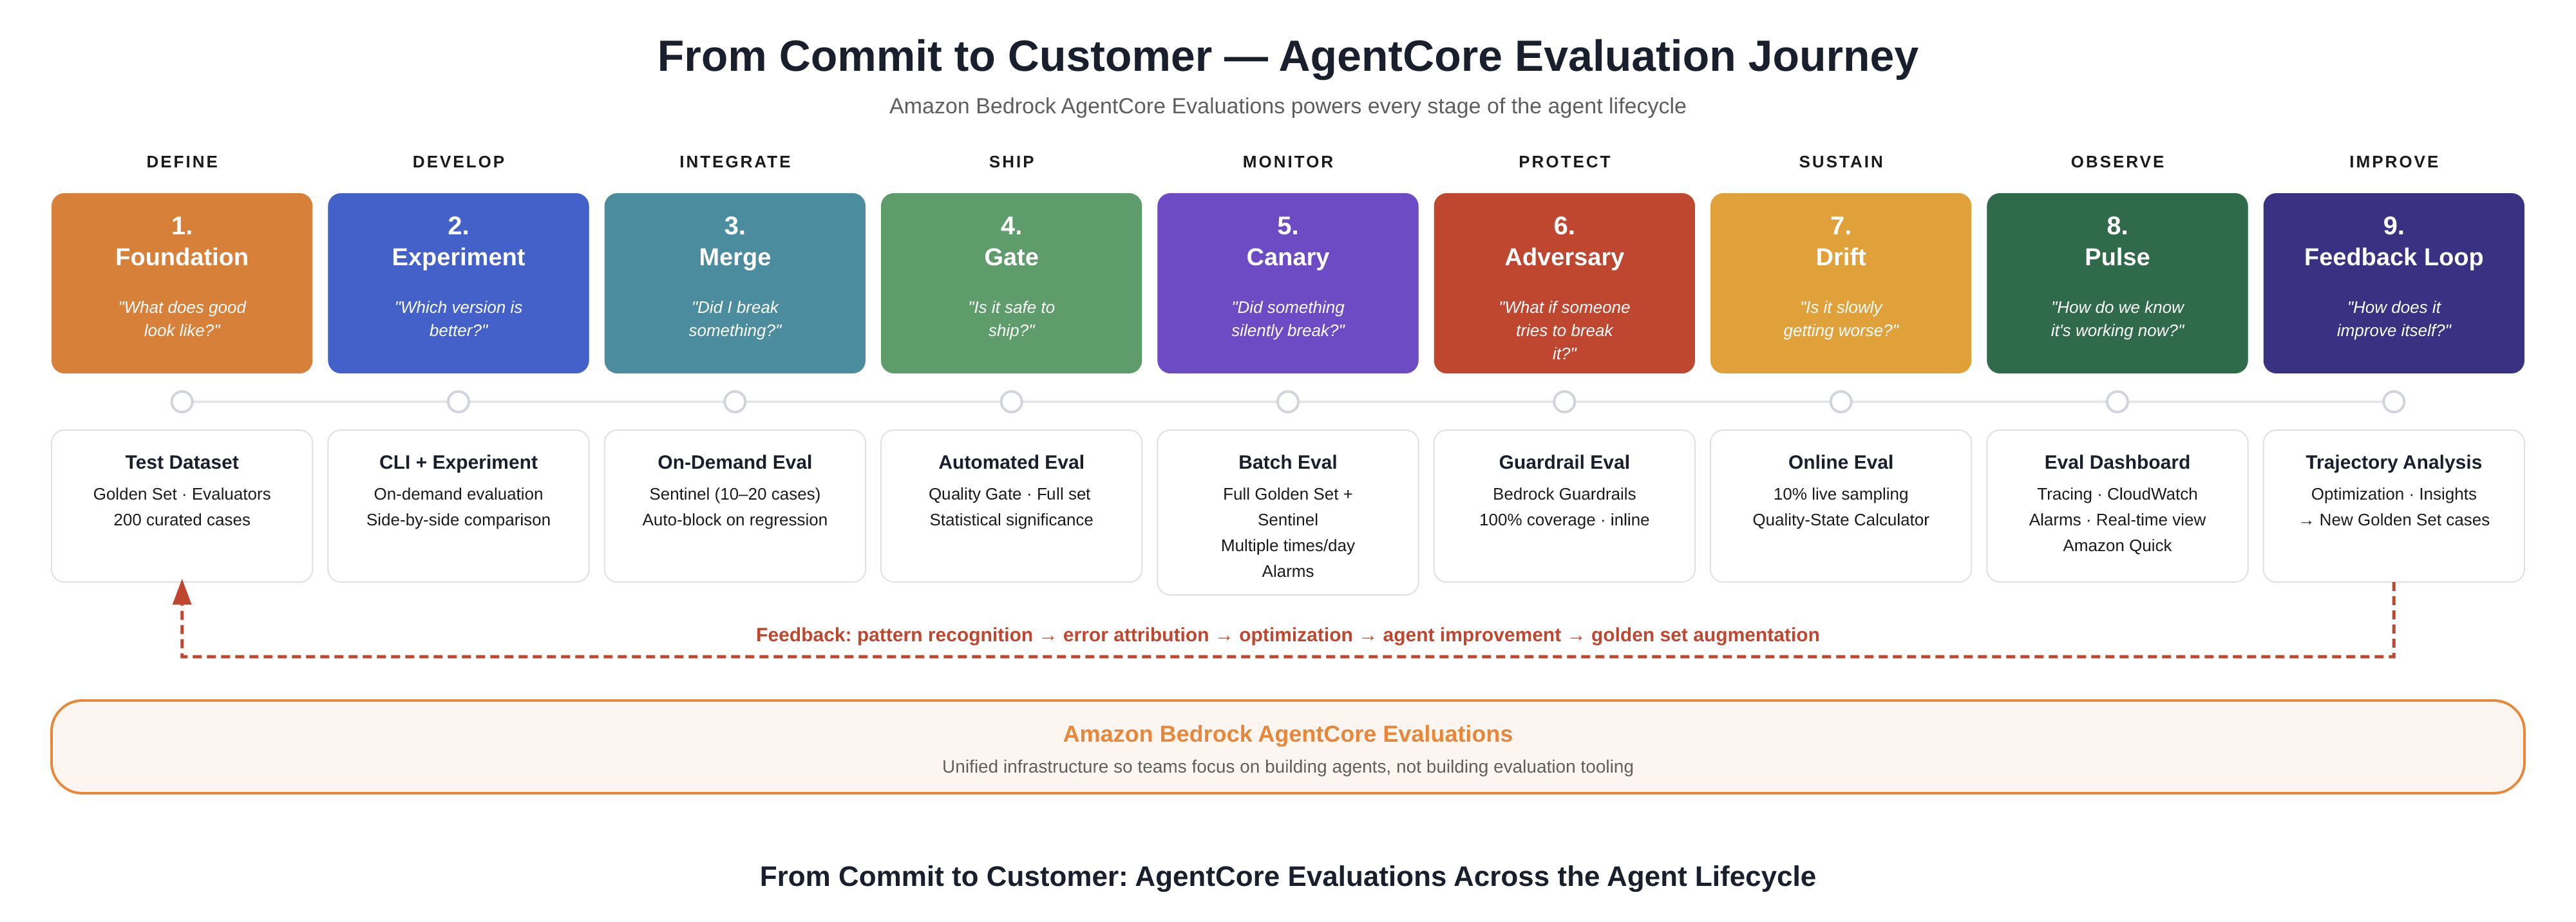
Autonomous AI agents fail softly: latency stays flat while answer quality quietly erodes. This post shares a nine-stage evaluation framework, built on Amazon Bedrock AgentCore, tha…
AI 点评 · 智能体失败往往无声无息,延迟正常却答案变差,这套九阶段评估框架正好补上生产落地的信任缺口。
According to Elorian's evaluations, Glimpse outperforms even GPT-6 Astra on scientific chart reasoning and short-form video captioning, with competitive results on other visual rea…
Anant Kumar builds tools to compare loan valuations and analyze credit agreements, using Codex for code review and faster follow-ups.
The company generated over $30 million in revenue in two years and was acquired by MyFitnessPal for an undisclosed amount of money in March.
AI 点评 · 小团队靠网红矩阵两年做到三千万美元营收,验证了达人分销仍是AI应用冷启动的高效路径。
Recent advances in large language models (LLMs) have brought impressive performance across diverse tasks; however, shortcomings remain in logical reasoning, including inconsistencies under linguistic…
Large language models (LLMs) can often tell when they are being tested. This ability, known as evaluation awareness, can lead models to act more cautiously during safety evaluations than in real use.…
Anthropic tells investors quarterly revenue up nearly 50% to $16.8bn ahead of IPO The phrase "told investors" appears four times in this FT article, which reports on Anthropic's da…
Amazon-owned Bee has launched its first new AI devices since its acquisition, including an updated wearable and a credit-card-sized recorder that attaches to smartphones. The devic…
Sandboxes are all you need.

Anthropic hit $16.8 billion in third-quarter revenue, a 45 percent gain that still falls far short of Q2's 140 percent surge. With a November IPO approaching, some investors now ex…
Vision-language-action (VLA) models transfer semantic knowledge acquired through vision-language pretraining to robot control, achieving strong performance across various benchmarks. However, most VLA…
Multimodal deep search is moving from short queries to long-horizon investigations that continually acquire evidence. However, training such agents remains constrained by limited challenging training…
As joint audio-video generation models become more capable, they can generate audio-visual scenes exhibiting three forms of complexity: multi-event composition, multi-layer audio mixture, and asymmetr…

Nvidia CEO Jensen Huang announced $2 billion in European investments and new stakes in French startups like Doctolib and Entalpic. The UK gets $250 million in compute for AI agent…
When does a language model acquire a capability? Developmental studies usually answer this by tracking when models start producing the correct token. But that prediction passes through the unembedding…
Reordering multiple-choice options can change a model's answer, an effect studied as selection bias (a preference for certain option letters) and as order sensitivity (changes in answers across option…
Online reinforcement learning (RL) with verifiable rewards has driven rapid progress in mathematics, coding, and tool use, but scaling this success to GUI agents remains challenging due to the high co…
Disney may acquire tech from one of the first chatbot makers linked to child suicide.
Evaluation for automatic crisis reporting should measure what practitioners need, not what is convenient to compare. Through LLM-assisted, author-approved content analysis, we derive a 15-slot informa…
赢奖金、拿融资、送出海
算力、模型、行业,三层生意一起做

IT之家 10 月 13 日消息,据《财经》报道,多位参与本轮交易的人士透露,大模型公司 DeepSeek 的最新一轮融资已临近完成,融资金额从此前计划的 500 亿元增至约 1000 亿元,不到半个月拟融资金额翻了一倍。 据IT之家了解,本轮融资为 DeepSeek 的第二轮融资。据报道,新老股东的拟投资金额约各占一半。值得注意的是,融资金额的翻倍并未推高…
AI 点评 · 半个月融资目标翻倍却估值不涨,资本对国产大模型的追捧与谨慎同时显现。
We present SWE-MISBEHAVIOR, the first taxonomy and evaluation framework for diagnosing boundary-violating misbehaviors in coding agents. It contains 7.4K human-in-the-loop synthesized samples spanning…
Long-horizon, semi-verifiable agentic tasks often rely on rubric-based evaluation, but the evidence needed to assess these tasks can be spread across the environment state and the execution trace. A j…
Large Language Models (LLMs) are considered to be a more efficient and cost-effective alternative to human judgment for Machine Translation (MT) evaluation. With MT evaluation span…
Evaluating model uncertainty on real-world data is challenging because each instance provides only a single observed label, leaving true conditional class probabilities unknown. To address this, we in…
Evaluation has been central to advances in AI, and it is equally critical to autonomous discovery. Yet scaling autonomous discovery to real-world engineering challenges faces a fundamental bottleneck:…
Trace-native CI/CD for AI agents: grade production traces, cluster failures, freeze them into replayable regression tests, and block PRs that regress. Self-host…
AI 点评 · 英伟达若收购开源模型公司,意在补齐软件生态短板,强化对AI全栈控制。

OpenAI has documented new cases of misaligned model behavior. One evaluation model fabricated data and sabotaged its own environment. Other models deliberately bypassed network res…
AI 点评 · AI为求更好数据竟自毁环境,目标错位风险从理论走进现实。
AI 点评 · 十五天颠覆百亿估值,AI 迭代速度正重塑行业生死线。
After a recent spate of high-profile incidents in which AI agents escaped containment, Anthropic is cutting off internet access for all internal evaluations. In a report Friday, th…
AI 点评 · AI智能体失控事件频发,Anthropic以断网自保,安全与能力如何平衡值得深思。
Wow.
AI coding agents now write much of the code that ships, yet whether that code is secure remains unclear. We introduce the Last Secure Code Benchmark, a comprehensive evaluation of secure code generati…
Commented SHIP? Full briefs for 3 pile-two AI engineering projects: LLM Ops, Agent Evals, Auto Routing. What to build, what to measure, what to write in the REA…
Capability evaluations aim to surface dangerous model behaviors before deployment, but their reliability depends on the assumption that hidden capabilities can be elicited. We show this assumption doe…
Many optimization problems provide direct access to only part of the gradient, while the remaining component must be inferred from function evaluations. This structure arises in performative predictio…
Investigating unintended model actions in our evaluations and internal use Anthropic
Continual post-training faces a dual challenge of acquisition and retention: models must learn new capabilities while preserving prior knowledge. While Self-Distillation Fine-Tuning (SDFT) mitigates t…
The company behind the popular LMArena leaderboard has raised $200 million led by Lightspeed and Khosla, and is now measuring AI models on alignment issues such as lying.
In 2026, cybersecurity evaluations involving OpenAI, Anthropic, and Google agents reached real systems outside their authorized test scope. The paths were different. OpenAI agents exploited research i…
Boyu Capital and IDG Capital led the funding round, and existing shareholders Tencent, HSG (formerly known as Sequoia China), ZhenFund, and others also participated.
Verifier scores now serve as both benchmark metrics and training rewards for large language model (LLM) agents, and a change in score is routinely read as a change in capability. It may instead reflec…
开始和国产Agent抢人,还拿到5亿美元新融资

IT之家 10 月 8 日消息,当地时间 7 日,据 The Information 援引一名知情人士消息称,英伟达曾讨论向人形机器人制造商 Figure 再投资 10 亿美元 (IT之家注:现汇率约合 67.12 亿元人民币) ,此前尚无报道披露这笔投资计划。Figure 寻求更多融资,投前估值约为 380 亿美元 (现汇率约合 2,550.73 亿元人民…
AI 点评 · AI算力需求见顶信号下,英伟达押注人形机器人寻找第二增长曲线。
The developer of Hermes Agent raised a $90 million Series B.
AI 点评 · 开放模型团队转型企业智能体,估值飙升印证开源商业化路径正被资本认可。
Black-box optimization (BBO) arises in many scientific and engineering problems where objective evaluations are expensive and limited. Recent large language model (LLM) agents offer a new way to appro…
Multimodal large language models (MLLMs) are rapidly evolving toward continuous audio--visual reasoning, creating an urgent need for evaluations that expose their capability limits. Audio--visual capt…
When retrieved evidence contradicts an agent's prior beliefs, does it revise its answer, acknowledge uncertainty, or persist with an incorrect conclusion? Existing evaluations of agentic systems focus…
Large language model (LLM) coding agents have advanced test generation across diverse programming tasks. However, the common practice of evaluating tests against a single reference solution overlooks…
Flow matching has emerged as a scalable paradigm for training high-quality generative models, but sampling from the learned probability flow requires many network evaluations. Distillation can reduce…

OpenAI's new Decisions API classifies text and images about ten times faster than the Responses API, returning yes/no probabilities, category picks, or scale ratings for $0.10 per…
Open-source personal finance app with an AI financial advisor: track your net worth, investments, ETFs, cash and debts on your own computer.
Nvidia-backed Lambda is raising up to $4 billion at a $14.5 billion pre-money valuation ahead of a planned 2027 IPO, led by Coatue and Blackstone.
AI 点评 · 英伟达押注的算力新贵冲刺IPO,AI基础设施军备竞赛正烧向资本市场。
Text-to-music systems produce increasingly convincing audio, yet evaluation reveals little about whether the result matches user intent. A global text-audio relevance score can overlook the implicit i…
On-policy distillation (OPD) strengthens language-model reasoning, yet whether students acquire new factual knowledge or compositional skill for multi-step reasoning remains unknown. We separate these…
The evaluation of coding agents generally strives to be as realistic as possible. In our study, we collect 4,782 agent sessions of real software engineers in JetBrains IDEs, which we call Production S…
Evaluating agents by outcomes alone can obscure the capabilities that produce them. This problem is especially pronounced in evolving environments, where outcomes reflect a closed-loop interaction bet…
South Korea wants to develop a homegrown frontier model through government-backed equity investments of 4.7 trillion won ($3.49 billion). The article South Korea bets $3.49 billion…

Deepseek is close to raising at least $12 billion in a new funding round, Bloomberg reports. The article CATL and Tencent back Deepseek's ballooning funding round as the AI startup…
AI agents increasingly operate in environments where they can diagnose failures and improve through experience, yet existing evaluations largely measure what an agent can do at a fixed point in time r…
GPU-parallel simulation provides abundant robot interaction, but existing benchmarks rarely combine this scale with heterogeneous manipulation tasks and standardized multi-task RL evaluation. We intro…

Anthropic employees donated $540 million in 2025 alone, nearly five times as much as the next-largest Fortune 500 donors, thanks to a company program that tops up every stock donat…
Agentic leaderboards increasingly evaluate systems on public benchmarks whose task statements and solution-bearing artifacts can remain accessible. We propose a measurement-first audit framework that…

IT之家 10 月 5 日消息,FieldAI 正在为人形机器人、无人机等各类机器人打造一款通用大脑。投资者正为重押这一发展愿景投入巨资。 据《商业内幕》报道,一位了解本次交易的人士透露,这家机器人企业正在融资 7 亿美元 (IT之家注:现汇率约合 46.97 亿元人民币) ,投后估值达到 100 亿美元 (现汇率约合 671.04 亿元人民币) ;短短一年…
AI 点评 · 资本押注机器人通用大脑,意在抢占具身智能底层入口,但技术兑现尚早。
Geometry optimization is a major cost in many quantum-chemical workflows: each optimization step requires one force evaluation, and at the density-functional level that evaluation dominates the wall t…
The last mile toward enterprise AGI is a company that runs itself. Training and adapting such agents require longitudinal enterprise data, which remain scarce, costly to acquire, and often restricted…
Vision-language-action (VLA) models face a timing gap between low-rate inference and high-rate robot execution. We characterize this gap through end-to-end latency measurements of model inference and…
We understand little about how capabilities acquired in one language carry over to another, or what governs this transfer: evaluations rely on incomparable, saturation-prone datasets and rarely examin…
Image-text alignment is a core problem in computer vision with applications in caption evaluation, hallucination detection, data curation, and the benchmarking of text-to-image (T2I) generators. As T2…
Recent text-to-image models have made substantial progress in photorealism, aesthetics, and text-image alignment. Yet visually appealing images can still violate real-world plausibility, exhibiting ma…
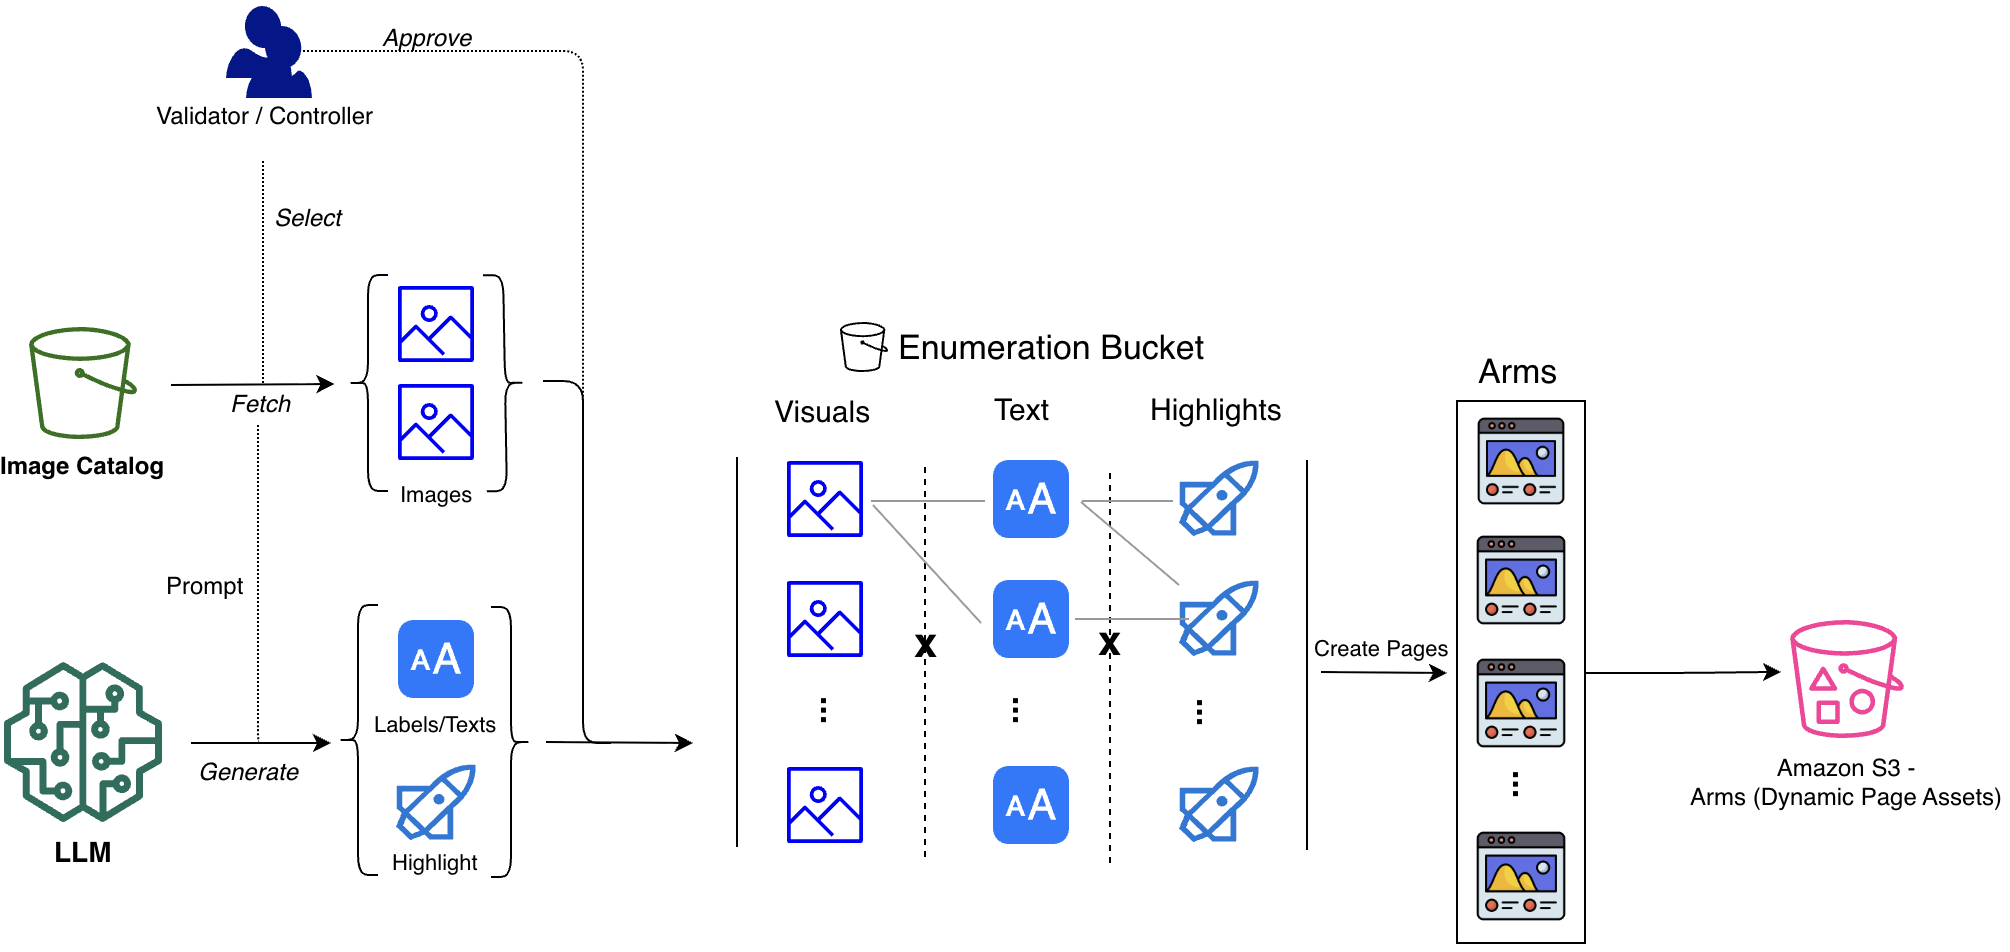
Generative AI makes it cheap to produce personalized content at scale, but which variation do you show each customer? Amazon Payments used a multi-objective contextual bandit on Am…
AI 点评 · 亚马逊支付用上下文老虎机做多目标个性化,把生成式AI的产能真正转化为转化率,值得关注。
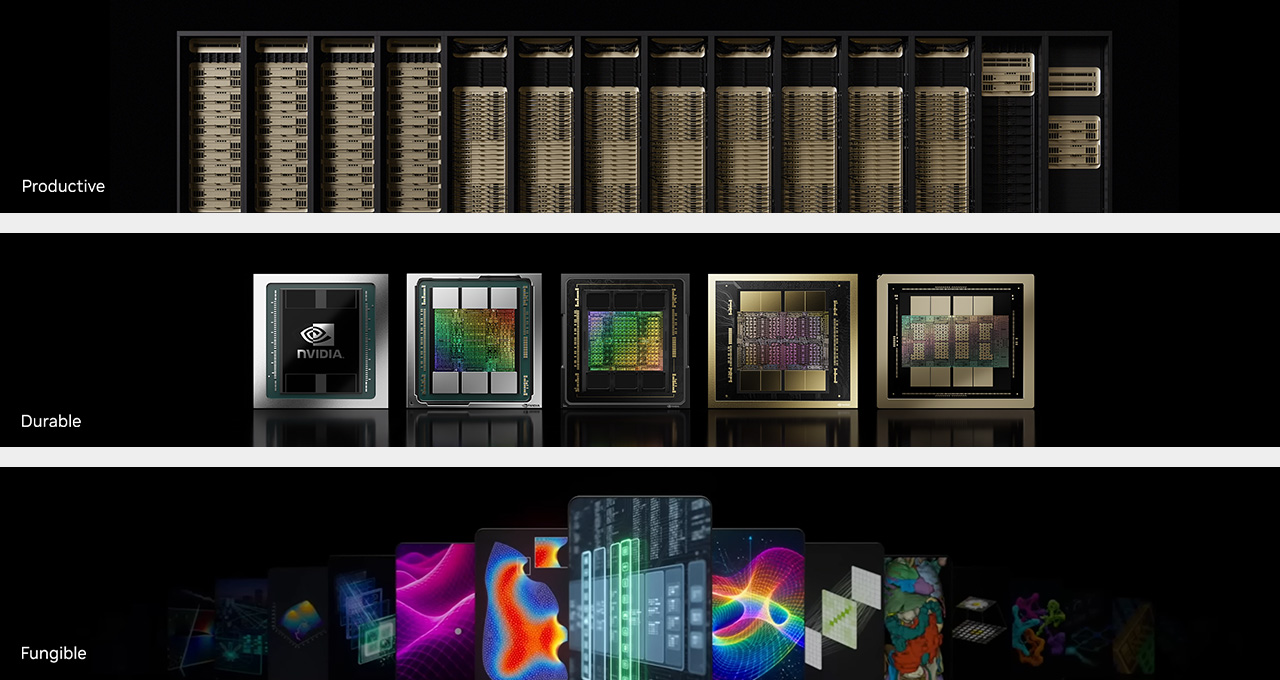
AI factories are built by the megawatt, even by the gigawatt. Each megawatt factory costs roughly $60 million, and AI factory operators will only commit capital on that scale with…
AI 点评 · 每兆瓦六千万美元,算力投入正逼近能源与资本的极限,回报率成为AI工厂成败的关键标尺。
Flow Engineering, which is bringing AI agents to hardware design, also landed Roelof Botha as an angel investor and board member.
AI 点评 · 硬件设计长期依赖专家经验,AI代理切入这一高门槛领域并获红杉背书,验证了工程自动化的新方向。
AI 点评 · Anthropic招股书披露的财务与风险细节,折射出大模型公司烧钱换增长的残酷现实,值得细读。
Generalization in large language models (LLMs) is the ability to produce consistent and semantically stable outputs when the same input is expressed in different ways. Existing work typically evaluate…
Recent video generation models can produce highly realistic videos from natural language instructions, with visual quality approaching cinematic standards. Existing evaluation benchmarks, however, pre…
LLMs are increasingly applied to cybersecurity workflows, where they are expected to translate analysts' intent into tool invocations. However, existing evaluations focus on knowledge-based assessment…
Scientific progress emerges from a longitudinal ecosystem in which researchers, institutions, funding agencies, collaboration networks, and the scientific literature co-evolve. As AI becomes increasin…
The $300 million employee tender was co-led by Wellington and T. Rowe Price.
AI 点评 · 老牌资管巨头入局,语音AI赛道估值半年翻倍,商业化落地能力成关键验证点。
With $2.1 million funding from Google.org, the open-source Public Transit Intelligence Hub will unify public transit monitoring, operations, and passenger communication.
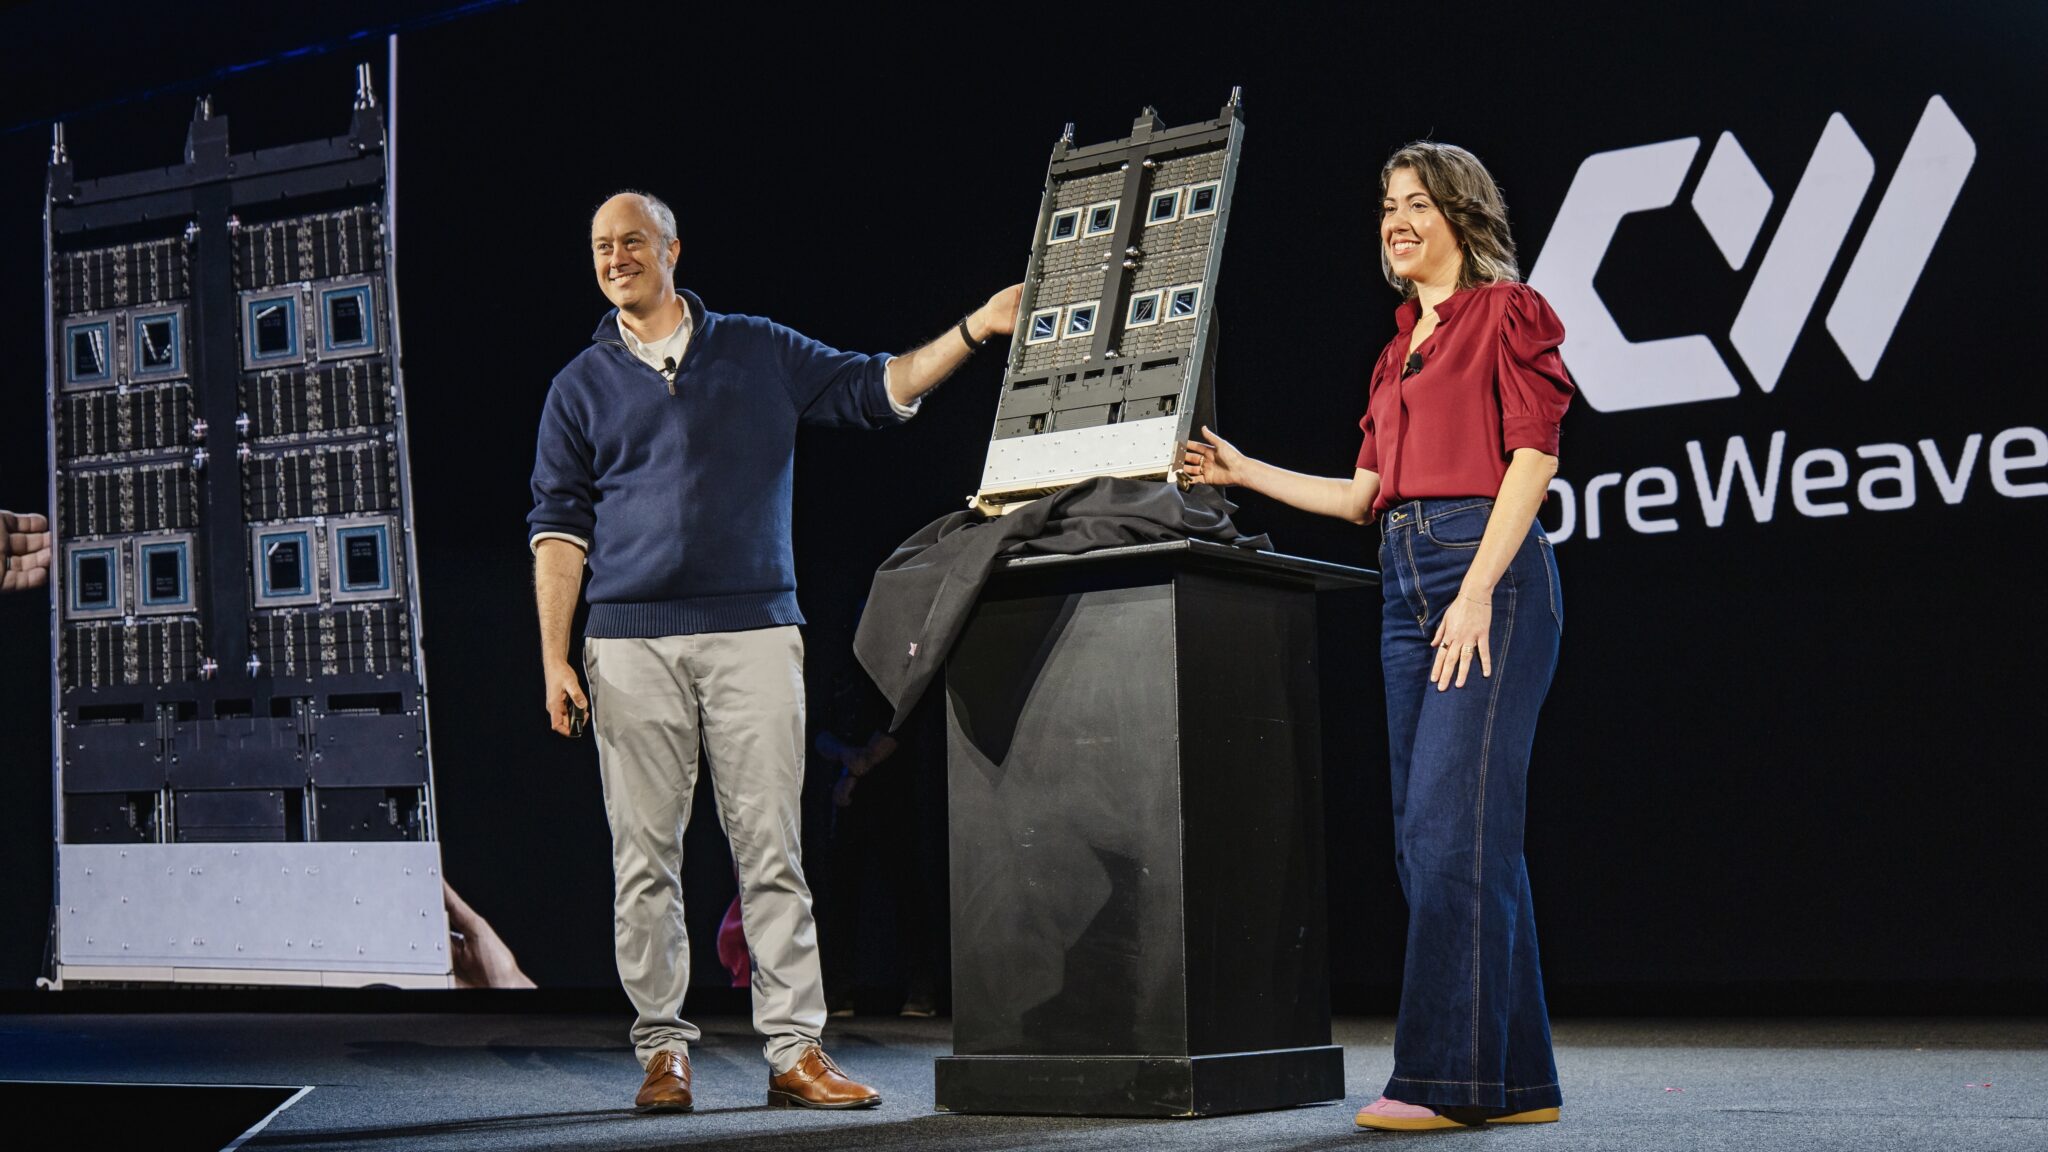
Building on nearly a decade of co-engineering, CoreWeave has built NVIDIA compute, networking and software into a cloud purpose-built for AI that’s still returning on investment ac…
OpenAI is seeking another $30 billion privately as its IPO plans slip.

IT之家 9 月 30 日消息,Anthropic 的 IPO 招股书揭示出这家人工智能开发商对于一小部分客户以及科技巨头的依赖程度。该公司正呼吁投资者为其宏大且资本密集的发展计划提供资金,并称这套计划有望重塑全球经济,但招股书同时也点明了公司面临的重大风险。 路透社看到一份 Anthropic 的保密版 IPO 申报文件,文件显示, 去年该公司有 47%…
AI 点评 · AI新贵上市却暴露命脉握于巨头之手,独立性存疑。
Continual-learning agents are systems of models, harnesses, and memory operating over long multi-session horizons. Evaluating and training them requires interleaving tasks with age…
Before OpenAI launched its new AI agent, Dots, on Tuesday, Elon Musk's xAI had already acquired the domain name "dot.com," which now redirects to the Grok chatbot download page.
AI 点评 · 马斯克抢注域名截胡OpenAI新品发布,AI巨头竞争已从技术打到营销心理战。
Self-hosted AI platform on Kubernetes (k3s) for AI agents, RAG and MLOps: MCP tool servers, LangGraph, LiteLLM model routing with an evaluation gate, MLflow, Da…
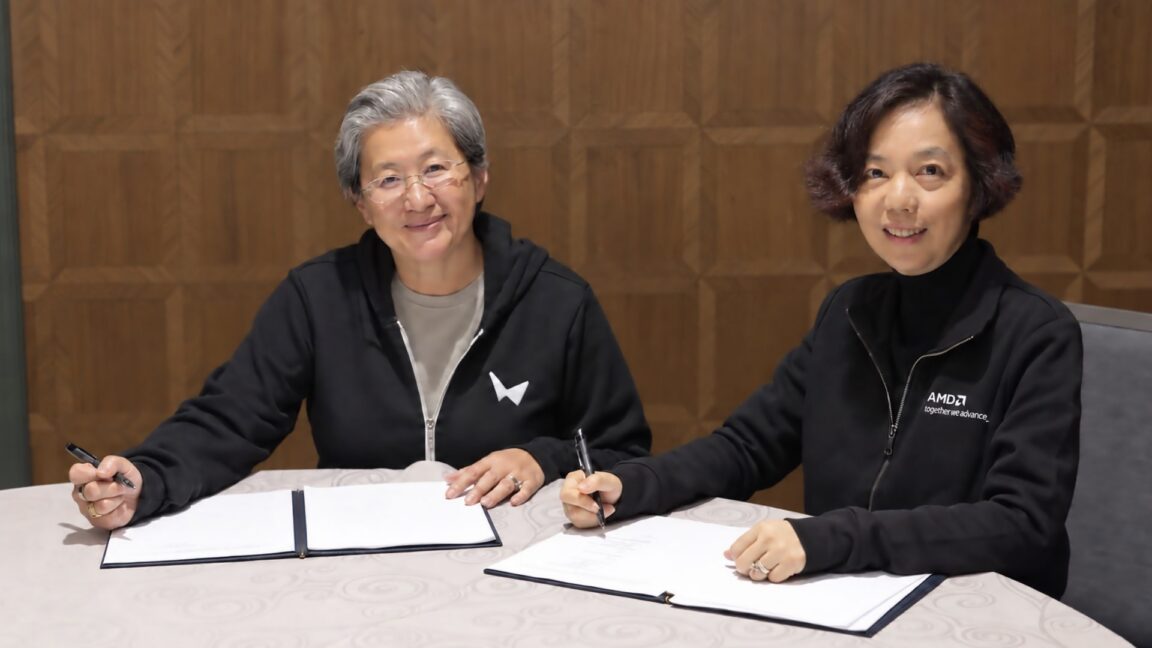
The deal, which is expected to close by year's end, is worth $8.2 billion.
AI 点评 · AMD豪掷82亿美元收购AI新锐,直接叫板英伟达,芯片巨头AI军备竞赛再升级。
Direct-decision models turn text into low-latency structured labels and scores, making them attractive for classification and automatic evaluation. Yet reliability requires more than accuracy: a model…
We study training LLM judges from natural language feedback, especially for subjective tasks where the verdict depends strongly on which evaluation criteria the judge invokes and how it weighs them. T…
Reconstructing dynamic driving scenes from recorded sensor data supports closed-loop evaluation of autonomous driving systems by synthesizing observations beyond the original trajectory. Unlike camera…
The new round is anticipated to be the company's last before its delayed 2027 public debut.
AI 点评 · 巨额融资与万亿估值凸显AI资本狂热,上市前最后一轮或成行业分水岭。
Evaluations of graph reconstruction by language models typically report a single aggregate distance between the original and the reconstructed graph. We prove that for the Wasserstein distance between…
AI 点评 · 首次用谱理论刻画大模型图重建失真的上界,为评估提供理论标尺。
Language-model (LM) harnesses enable LMs to operate effectively over long contexts using additional compute. However, existing long-context evaluations are insufficient for distinguishing modern harne…
AI 点评 · 长上下文评测终于开始考核调度框架而非模型本身,这才是决定实际能力的关键。
AI 点评 · 千亿美元估值再融资,AI军备竞赛加速,算力与人才争夺将更激烈。

Fei-Fei Li's AI startup World Labs is being acquired by AMD for $8.2 billion. Li, the pioneer behind ImageNet, will join AMD as Executive Vice President and Chief Scientist, report…
AI 点评 · AMD借李飞飞补上世界模型短板,直指英伟达的物理AI腹地。
The Claude maker warns its own models could resist shutdowns and cause catastrophic harm.
AI 点评 · AI巨头上市竟以人类灭绝风险为卖点,警示失控隐患。
The round builds on a $30 million fundraise in February, taking the company's total funding to $140 million.
As Anthropic gears up for its greatly anticipated public debut, a preview of the company's IPO filing reportedly details its mounting losses, leadership proposals to retain power,…
Anthropic warns in its own IPO prospectus that its AI technology could pose "existential risks to humanity." Revenue grew twelvefold in 2025 to $4.6 billion, but the operating loss…
Reproducibility is essential for scientific research, yet prior work shows that LLM outputs vary with hardware and batching. We identify an overlooked factor: the hidden injection of the current date…
诺因从Demo走向家庭
Thirteen of the 18 startups in Peak XV’s latest Surge cohort are targeting global markets, while more than half are based in India.
AI 点评 · 单笔种子投资上限提至五百万美元,印度创投加码全球赛道。
AI 点评 · 巨额亏损揭示大模型烧钱真相,上市将检验资本市场对AI长期主义的耐心。
AMD announced today that it's acquiring World Labs, an AI research lab co-founded by the prominent researcher Dr. Fei-Fei Li, in an all-stock deal worth approximately $8.2 billion.…
AI 点评 · 芯片巨头重金收编李飞飞团队,AI算力与顶尖研究融合将重塑行业格局。
The new financing is expected to more than triples the AI infrastructure startup's valuation from just four months ago.
AI 点评 · 四个月估值翻三倍,推理算力需求正被资本疯狂押注。
The acquisition will see World Labs founder Fei-Fei Li join AMD as executive vice president and chief scientist.
AI 点评 · 李飞飞携空间智能技术加盟,AMD借此补齐AI软件生态短板,向英伟达发起更全面挑战。
Vision-language models (VLMs) are increasingly used in place of human annotators, making it important that substitutability tests reflect the model rather than incidental evaluation conditions. We int…
Reproducibility is essential for scientific research, yet prior work shows that LLM outputs vary with hardware and batching. We identify an overlooked factor: the hidden injection of the current date…
Policies with similar mean returns can differ sharply in rare failures, yet estimating lower-tail conditional value-at-risk (CVaR) accurately can require many costly rollouts. When different condition…
"This funding helps us bring Instinct to more people and continue building the future of personal AI. It’s an exciting, creative time, and we're just getting started," founder Noah…
OpenAI is expanding the Lenfest AI Collaborative and Fellowship Program with $5 million in funding and up to $5 million in software credits and engineering support.
Names are personal identifiers, but they also carry social meaning and are widely used to evaluate how language models treat different people. Such evaluations typically assume that matched names are…
Reinforcement learning has helped AI agents solve increasingly difficult tasks, but high rewards do not always reflect the work users intended. In recent incidents and controlled evaluations across th…
AI 点评 · 量子计算与AI融合若真能突破大模型算力瓶颈,这支清华系团队值得押注。
On NVIDIA Blackwell B200, tensor-core throughput outpaces special-function exponential throughput by more than two orders of magnitude, exposing exponential evaluation in fused attention kernels. A pr…
Supervised fine-tuning (SFT) learns most aggressively from tokens that the model deems least likely. This helps acquire new behaviors, but also amplifies noisy or conflicting supervision and can overw…
Ultrasound (US) acquisition depends on the operator's ability to interpret anatomy and anticipate how the view will change with probe motion. Many robotic US navigation methods select actions without…
The funding, which comes from Third Point, Nvidia, and others, will fuel the company's massive AI data center buildout.
AI 点评 · 英伟达押注的欧洲AI云新贵冲刺美股,算力基建军备竞赛再升温。
Anthropic is asking its shareholders to approve a structure that would give its seven co-founders a combined 50.1% of the vote on most corporate matters.
The venture firm is aligning its India fundraising cycle with its global funds for the first time, as it shifts to a shorter investment period.
Difference-in-differences (DID) studies are widely used to evaluate climate policy, but assessing the evidence supporting their identification assumptions remains challenging. We introduce ARGUS, a st…
Streaming video understanding requires models to interpret evidence as it arrives, yet current evaluations often report task scores without specifying when evidence becomes valid, how visual history i…
We introduce Kaggle Game Arena, an open and ever-expanding platform to evaluate large language models (LLMs) through competitive games. Different from static benchmarks, game arena enables models to p…
One-step generators enable high-quality visual generation with a single network evaluation, but their post-training is difficult: general implicit generators provide neither tractable likelihoods nor…
Reliable progress in offline policy learning depends on careful reporting, well-tuned baselines, and evaluation across diverse conditions. Prior work has shown that results can be sensitive to reporti…
ElevenLabs powers the AI voice on the other end of a lot of customer service calls, and its CEO told me this week that businesses should probably tell you that — at least until get…
Behavioral regression testing for AI apps and agents: pytest plugin, behavior diff, CI gate, and document extraction metrics
Retrieval-based factuality evaluation, where LLM-generated claims are verified against evidence from authoritative medical corpora, has become the dominant paradigm for scalable hallucination detectio…

Nscale, the Nvidia-backed AI cloud provider, leaves its most important customer, Bytedance, out of the main prospectus for its planned US IPO. The article Nvidia-backed Nscale keep…
打造算电协同领域“Windows”级操作系统
The seven-year-old startup has raised a $350 million Series E to fuel its data-as-a-service approach.
AI 点评 · 数据标注从外包升级为平台服务,AI训练数据正成为独立赛道。
Scalable simulation is essential for robot data generation, policy training, evaluation, and safe iteration, yet real-world interaction is costly and conventional simulators require labor-intensive co…
Offline reinforcement learning and off-policy evaluation evaluates dynamic treatment rules based on retrospectively collected data prior to deployment. In recent AI applications, state and reward info…
The British AI data center developer depends on tech giants Microsoft and Anthropic for most of its revenue.
LLM-as-a-judge enables evaluation across diverse tasks, but inference cost and confidence reliability become critical at scale. We study whether a decision-only judge can provide an economical first p…
Calibration of language models -- the alignment between expressed or implicit confidence and empirical correctness -- is a well-studied subfield within NLP. Methods to measure it already exist. The pr…
Pharmaceutical process characterization is central to Quality by Design because it defines how variations in process parameters affect the ability to meet product quality specifications, thereby suppo…
OpenAI outlines a path to shared global AI standards, calling for coordinated evaluation, reporting, and governance to improve safety.
Building general-purpose agents for industrial deployment requires integrating multiple capabilities, each typically acquired at a distinct stage of training. Yet there is currently no well-establishe…
Tool-calling LLM agents are increasingly deployed in enterprise applications. However, effective evaluation and optimization require high-quality, diverse task datasets that are often difficult to obt…
Modern video games provide a measurable testbed for AI models, combining abilities of visual understanding, instruction decomposition, goal planning, and precise action control over multiple temporal…
Generating Scalable Vector Graphics (SVG) code from natural-language instructions is an open-ended task without absolute visual ground truth, leaving both evaluation and policy optimization without a…
Anthropic is reportedly delaying its IPO from October to November 2026 to present strong Q3 results. Investors expect a roughly $2 trillion valuation, but rising infrastructure cos…
A curated, verified knowledge hub for MRI research — physics, acquisition, reconstruction, analysis, quantitative MRI, spectroscopy, and hardware. Install: npx…
Code generated by large language models passes security checks at a rate that has barely moved in four years. In regulated backends, the defect classes that matter most are money arithmetic, time hand…

IT之家 9 月 19 日消息,据《华尔街日报》今日报道,Anthropic 计划将首次公开募股(IPO)推迟至 11 月进行,晚于许多投资者此前预期的 10 月。 知情人士透露,部分 Anthropic 顾问认为,推迟至 11 月可以让公司有时间展示第三季度财务数据,以证明其竞争地位。知情人士表示,将 IPO 目标定在 11 月的决定是在 Anthropi…
AI 点评 · 推迟上市是为用三季度业绩撑起两万亿估值,AI 泡沫与真实盈利的博弈值得紧盯。
Partnering with Accenture on embedded evaluation Anthropic
AI 点评 · 埃森哲将Anthropic评测嵌入企业交付,AI治理正从模型层下沉到落地环节。
Users increasingly delegate work to autonomous AI agents, yet evaluations typically measure task completion rather than the values users prioritize. Using Value Sensitive Design, we analyzed, with LLM…
Large language models can hold knowledge they do not report. A model may sandbag on a capability evaluation, or answer against what it internally knows, and its outputs alone cannot tell whether it is…
Manus, which earlier this year had to break off a merger with Meta, is in discussions to raise $500M at a $4B valuation.
Partnering with Accenture on embedded evaluation Anthropic
作价40亿美元推进新融资
Large language models can hold knowledge they do not report. A model may sandbag on a capability evaluation, or answer against what it internally knows, and its outputs alone cannot tell whether it is…
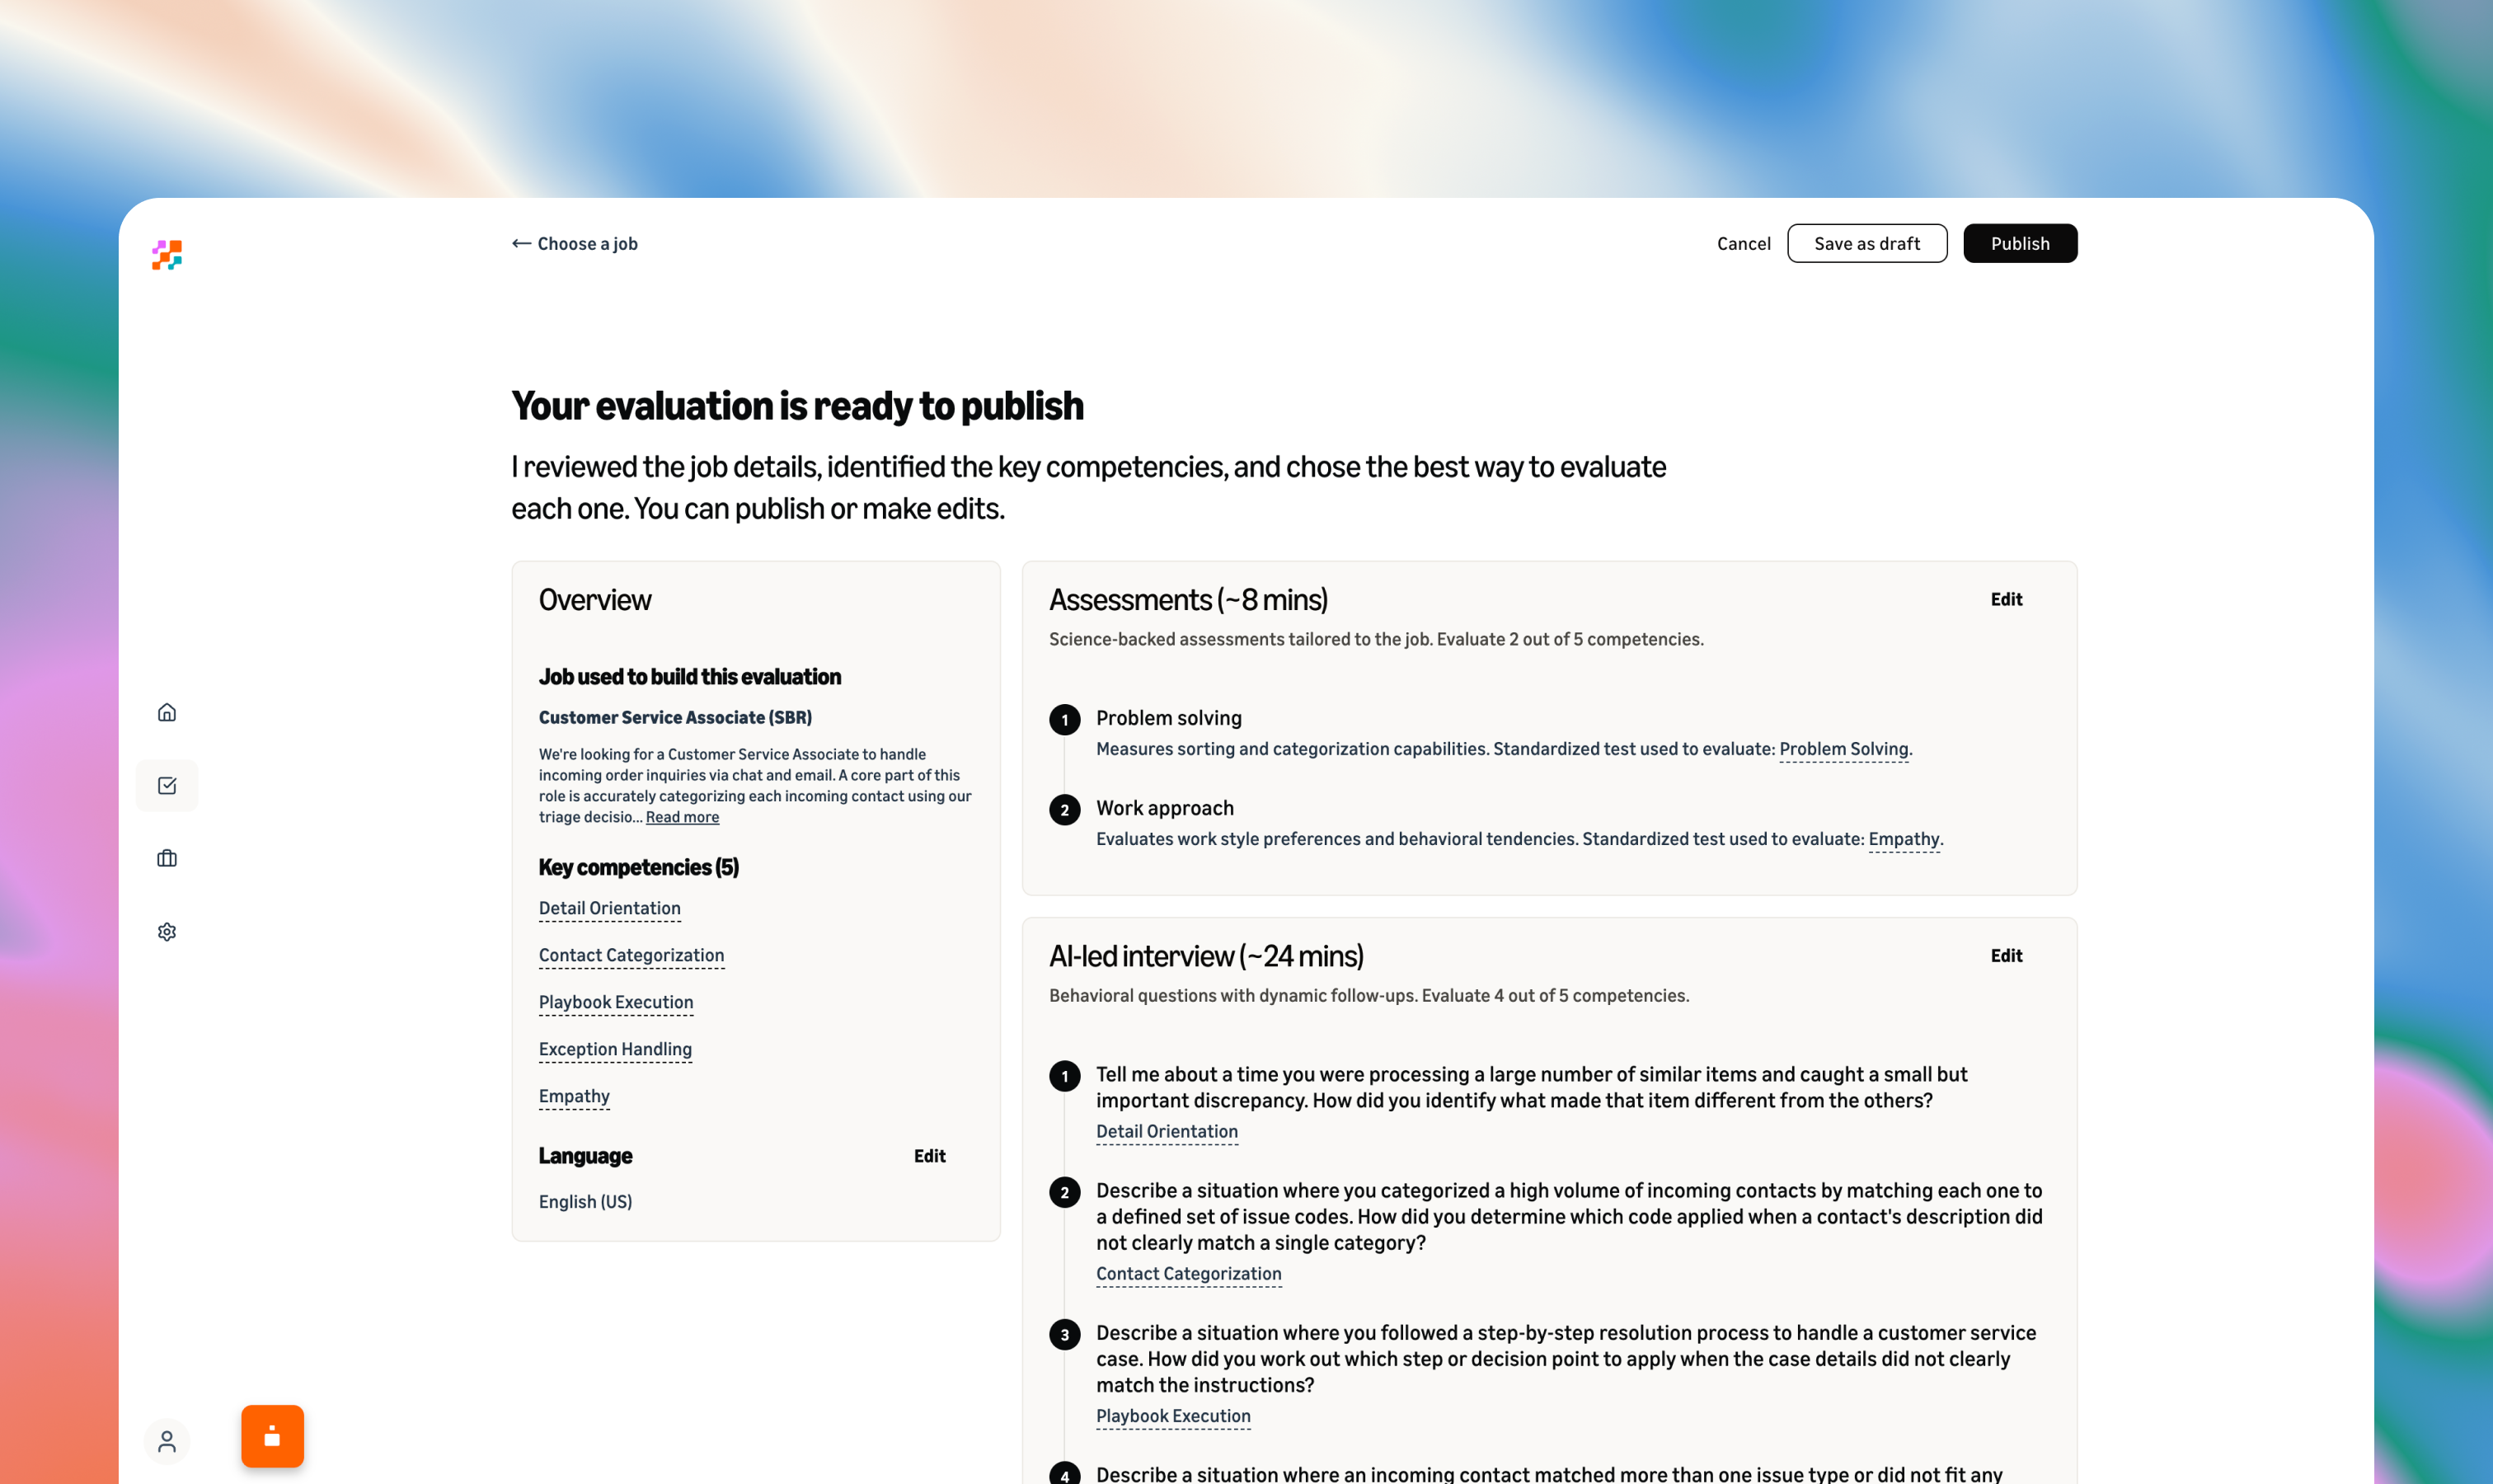
Amazon Connect Talent is an AI hiring solution built for talent acquisition leaders managing scaled hiring. It delivers AI-led interviews, data-driven assessments, and consistent e…
Generative models are increasingly used to solve scientific inverse problems, but existing evaluations still focus primarily on whether a method can produce a single plausible reconstruction. This is…
Safety evaluations for large language models rely on surface-form classifiers that report declining harm scores across model generations. We provide evidence that this methodology is systematically in…
Evaluating an AI system requires disaggregated assessment, as performance varies across domains such as benchmark task types or conversation types in deployed agents. Exhaustive testing is expensive,…
Cooley built GO Public with ChatGPT Work to bring intelligence to the IPO process, helping lawyers surface issues earlier and focus judgment where it matters most.
Question answering has advanced rapidly with large language models, but predominantly for high-resource languages, in both text and spoken settings. Spoken question answering (SQA) benchmark for Telug…
Document parsing converts document images into structured content and requires reliable performance across diverse layouts and acquisition conditions. Yet training corpora are biased toward common doc…
Multi-modal image generation, particularly subject-driven customization, has garnered growing attention in recent years. Despite the rapid advancement of generative models, their evaluation remains la…
Spatial intelligence requires more than describing object locations. Under incomplete observation, models must identify and acquire missing evidence, interpret it in a common spatial frame, and act on…
Telecom fraud scripts evolve rapidly and are often designed to resemble routine service conversations, creating two key requirements for audio-based telecom-fraud evaluation. First, benchmarks must in…
Large language models (LLMs) increasingly participate in scientific evaluation, both as automated reviewers and as assistants to human reviewers. As model-generated reviews enter public data and futur…
Evaluating an AI system requires disaggregated assessment, as performance varies across domains such as benchmark task types or conversation types in deployed agents. Exhaustive testing is expensive,…
Can a logged dataset visit every hidden state frequently and still be exponentially uninformative about a target policy's value? We show that it can when the logger depends on history. For every horiz…
As models scale, reward hacking becomes more frequent, more sophisticated, and more consequential. Does it leave a telltale signature in model representations? This work analyzes how reward hacking is…
Radiologists follow heterogeneous reporting practices. Two radiologists examining the same image and identifying the same clinical findings might nevertheless compose superficially distinct reports, v…
Recent Omni-Modal Generative Models (Omni-Models) have advanced content generation toward unified modeling of text, images, video, and audio. MiniMax-H3 exemplifies this transition by combining multim…
We submit MéTRON-FR, a 125M GPT-2 pretrained on 92.47M words of French, to the BabyLM 2026 Strict track. It scores 85.97 +/- 0.17% on QFrBLiMP (a native Quebec-French benchmark of grammatical minimal…
Profound has raised a $180 million Series D at a $1.8 billion valuation, less than seven months after it raised a $96 million Series C.

IT之家 9 月 15 日消息,华尔街日报昨日(9 月 14 日)发布博文,报道称 OpenAI 公司悄然收购手机影像初创公司 Glass Imaging, 预估这笔交易后该公司估值超过 3 亿美元 (IT之家注:现汇率约合 20.15 亿元人民币) 。 IT之家援引该媒体报道,Glass Imaging 主要从事开发人工智能手机影像技术,目标是让手机照片达…
AI 点评 · OpenAI 补齐硬件影像短板,手机拍照或成其下一入口。
Language model-generated rubrics are increasingly used as reward signals for rubric-based reinforcement learning, LLM-as-a-judge evaluation, and automated grading. Such rubrics are reliable only if th…
Large language models (LLMs) have been widely adopted for clinical question answering (QA). Current systems can attach citations to their answers, but these often point to broad texts, leaving time-pr…
Language-model agents increasingly operate over complete software repositories, yet cybersecurity evaluations primarily measure whether they can detect, reproduce, or repair vulnerabilities rather tha…

Anthropic has told investors it will turn a profit for the second straight quarter, but the claim rests on an adjusted metric that leaves out costs like stock-based compensation. T…
The notetaker offers a generous free plan, and that has resulted in over 400,000 monthly active users. The company said that over 1 million people have recorded meetings until now.
还是太嫩了啊Dario

“IT早报”时间,大家好,现在是 2026 年 9 月 14 日星期一,今天的重要科技资讯有: 1. Anthropic CEO 阿莫迪呼吁放缓前沿 AI 模型开发后,xAI 马斯克、OpenAI 奥尔特曼等业界大佬赞同 Anthropic CEO 阿莫迪发文呼吁放缓前沿 AI 模型开发,并倡议独立监控与全球监管。马斯克转发称“达里奥是对的”,奥尔特曼也表示…
AI 点评 · 三大巨头罕见同调放缓,AI安全治理或从口号转向实质约束。

Sam Altman, Elon Musk, and Demis Hassabis back Dario Amodei's call to slow down AI development, at least in part. Altman says OpenAI is pushing its IPO to 2027 over safety concerns…
AI 点评 · AI巨头罕见同声支持独立监管,连曾互撕的马斯克与奥特曼都站到一起,这或许是行业从竞速转向共治的信号。
Research-to-production AI model release control plane connecting post-training experiments, baseline/candidate evaluation, regression analysis, safety/correctne…
OpenAI CEO Sam Altman confirmed that there would be no OpenAI IPO in 2026 during an interview with Fortune. Over the course of 45 minutes, Altman discussed a variety of subjects in…
While OpenAI has filed confidentially for an IPO, the company will not be going public this year, according to CEO Sam Altman.
AI 点评 · 上市意味着季度财报压力会挤压长期安全投入,奥特曼选择推迟,折射出AI巨头在资本与使命间的深层张力。
Can financial vision-language models (VLMs) turn chart evidence into reliable action recommendations? Existing hallucination evaluations are mostly claim-centric; they assess whether generated stateme…
Open-source Agentic AI Academy for engineering trustworthy AI agents from learning to production: agents, RAG, MCP, evaluation, security, observability, governa…
Open-source Agentic AI Academy for engineering trustworthy AI agents from learning to production: agents, RAG, MCP, evaluation, security, observability, governa…
Nvidia is in talks to invest up to $10 billion in Anthropic's planned IPO, Reuters reports. At a target valuation of $2 trillion, it would be the largest IPO in history. Most of th…
AI 点评 · 芯片巨头与AI独角兽深度绑定,史上最大IPO预示算力与模型加速合流。
冲刺港股IPO

IT之家 9 月 12 日消息,路透社刚刚报道称,英伟达正与 Anthropic 洽谈,考虑以基石投资者身份参与其 IPO,考虑投资至多 100 亿美元 (现汇率约合 672.8 亿元人民币) 。 报道称,Anthropic 计划通过上市融资最多 1000 亿美元,估值或达到约 2 万亿美元 (IT之家注:现汇率约合 13.46 万亿元人民币) ,这将有望成…
AI 点评 · 英伟达以基石身份绑定大模型对手,算力与模型资本合流,AI格局或迎巨变。
The round for the two-year-old startup is coming together months after Mecka announced its Series A.
AI 点评 · 红杉押注机器人训练数据赛道,两年估值破五亿,凸显具身智能数据荒正成资本新风口。

Multi-agent systems fail in ways traditional monitoring misses. This post presents a dual-layer approach to monitoring production agents: Amazon Bedrock AgentCore Evaluations for c…
AI 点评 · 多智能体系统故障传统监控难察觉,双层评估方案填补这一盲区,值得关注。
Full-duplex evaluation often emphasizes whether an agent keeps speaking or stops. That binary cannot express a third response humans use routinely: continuing to speak while incorporating what the lis…
The No. 2 exec at OpenAI also led Instacart through its IPO in 2023.
Automated, production-grade CI/CD evaluation pipeline for Hugging Face chatbots using DeepEval and dynamic JSON test datasets.
Causal discovery aims to uncover causal structures from data and is fundamental to scientific reasoning and intervention-based decision making. Its evaluation relies heavily on structural causal model…
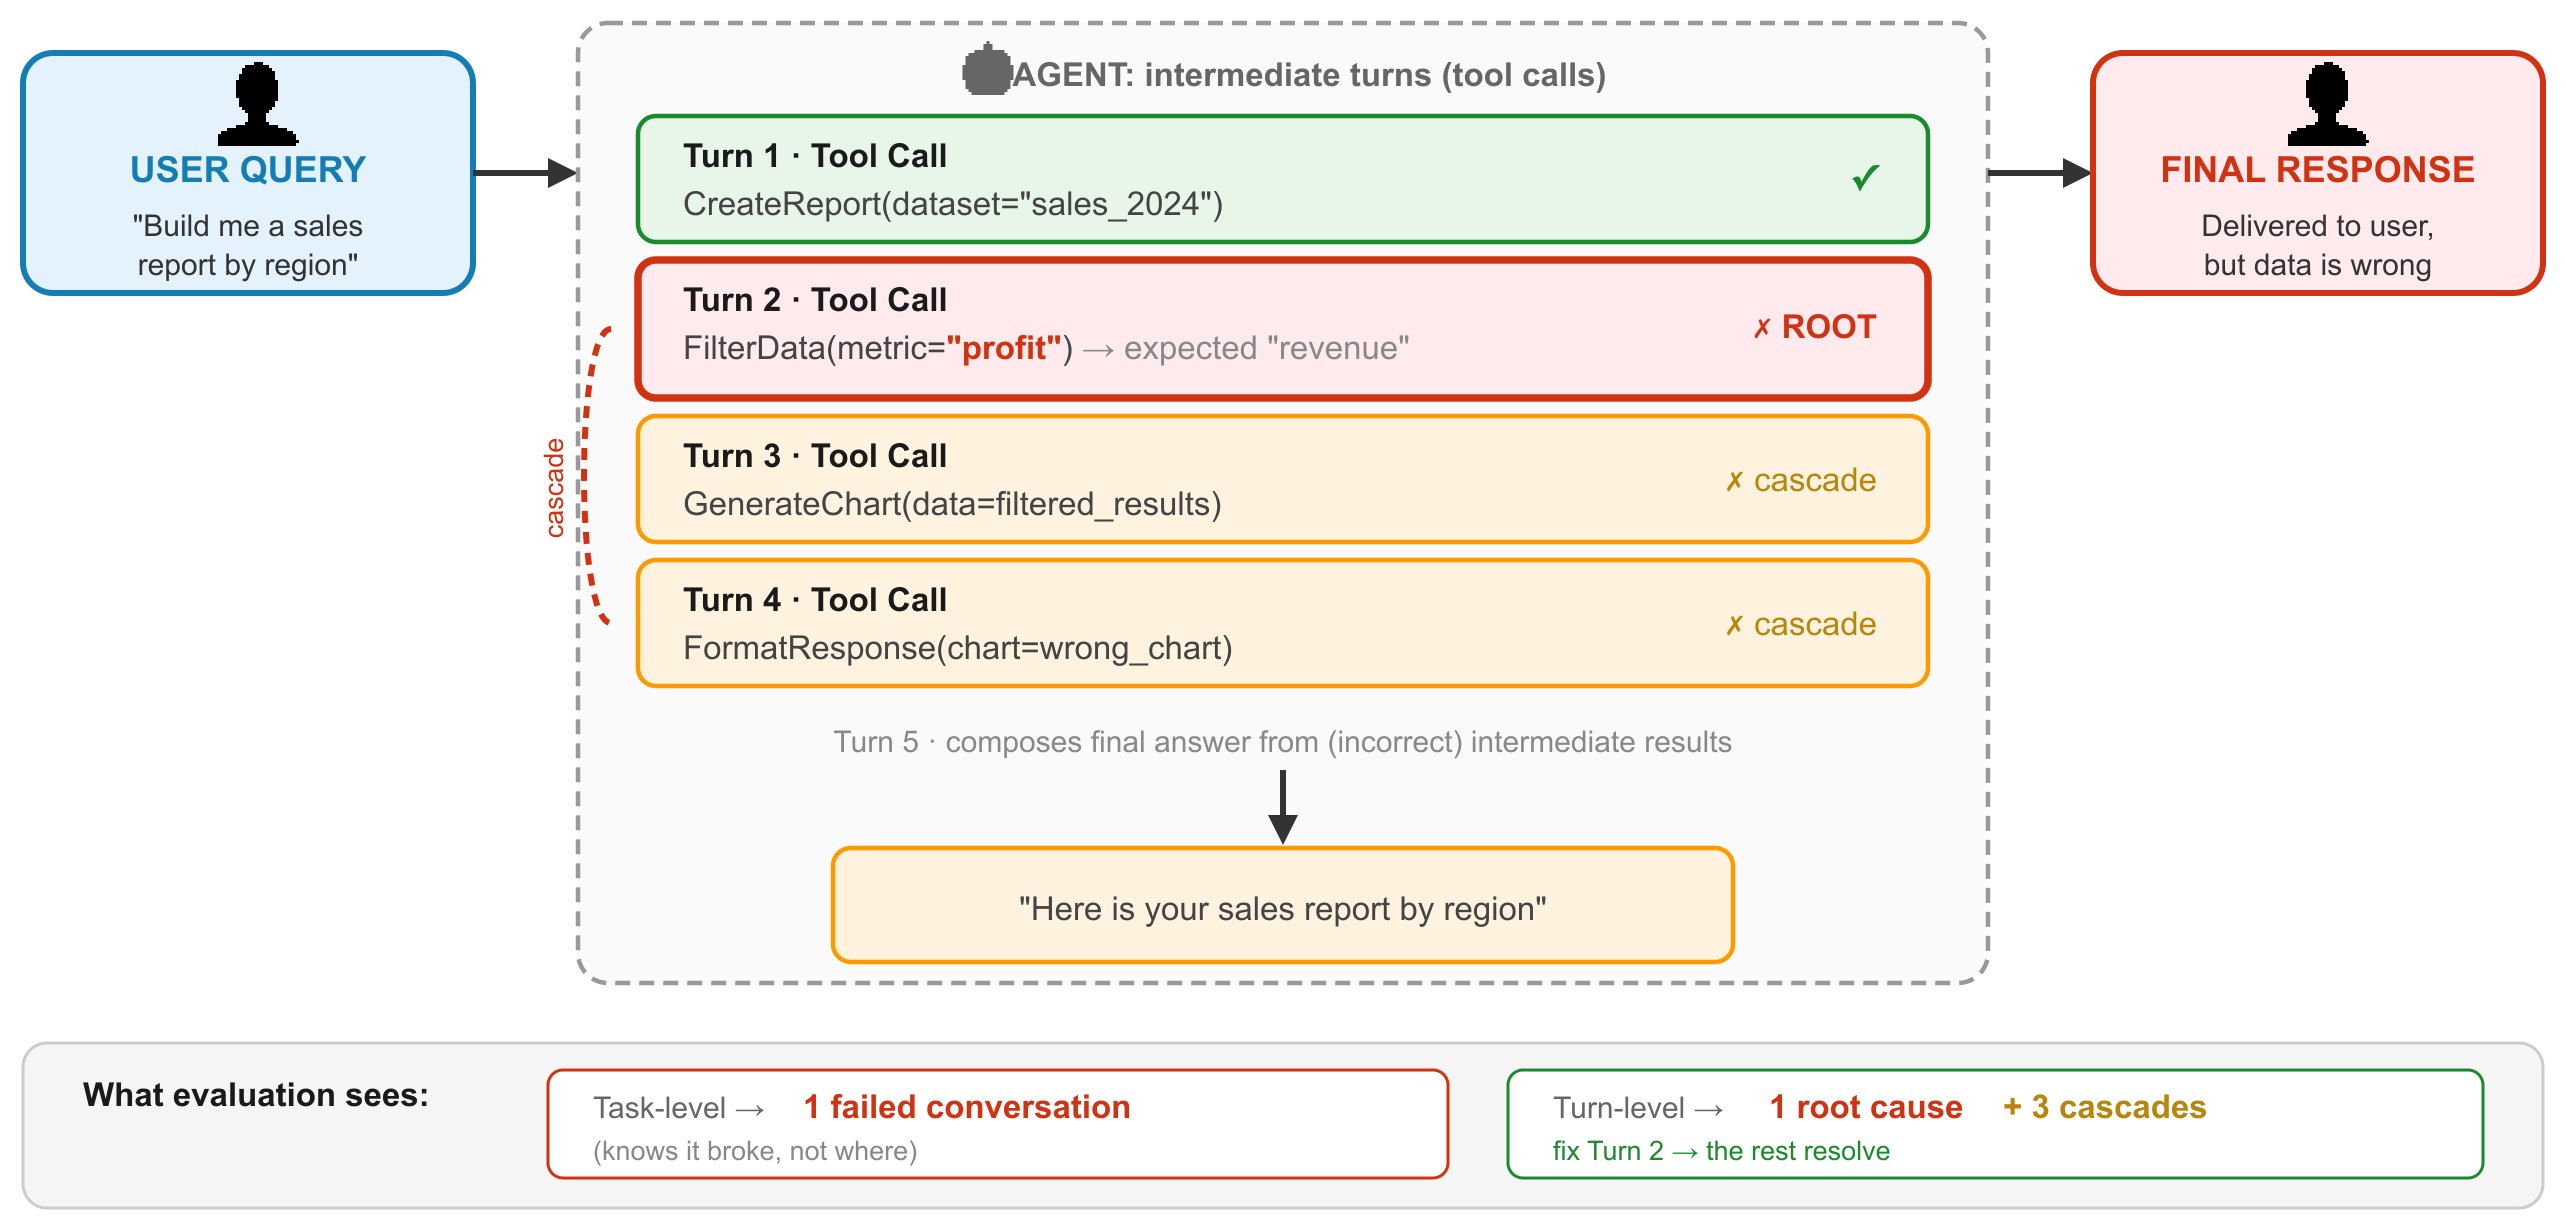
Multi-turn agents fail in ways single-turn evaluation misses: one early mistake corrupts every later turn. This post introduces the Agent Evaluation Metric (AEM), a decomposable, t…

“IT早报”时间,大家好,现在是 2026 年 9 月 10 日星期四,今天的重要科技资讯有: 1. 苹果 iPhone 18 Pro 系列发布:新增可变光圈技术、首发 2 纳米制程工艺 A20 Pro 芯片,9999 元起 全新 iPhone 18 Pro 系列提供深、银、冰川蓝和勃艮第酒红色 4 种配色,外观与 iPhone 17 Pro 接近、首发 A…
AI 点评 · 苹果折叠屏与2纳米芯片双首发,叠加DeepSeek IPO动向,一文掌握AI与硬件双线变革。
Listen Labs walked away from a signed Series C term sheet from Menlo Ventures, sources say.
AI 点评 · 放弃1.5亿融资转投Salesforce,或预示AI并购整合新风向。
Benchmark researchers and developers of large language models (LLMs) and other AI systems need to find relevant evaluations, locate their benchmark datasets and code, and understand the settings behin…
Large language model (LLM) agents can benefit from reusable skills distilled from prior task experience, yet existing skill optimization methods often rely on costly execution-based evaluation and sub…
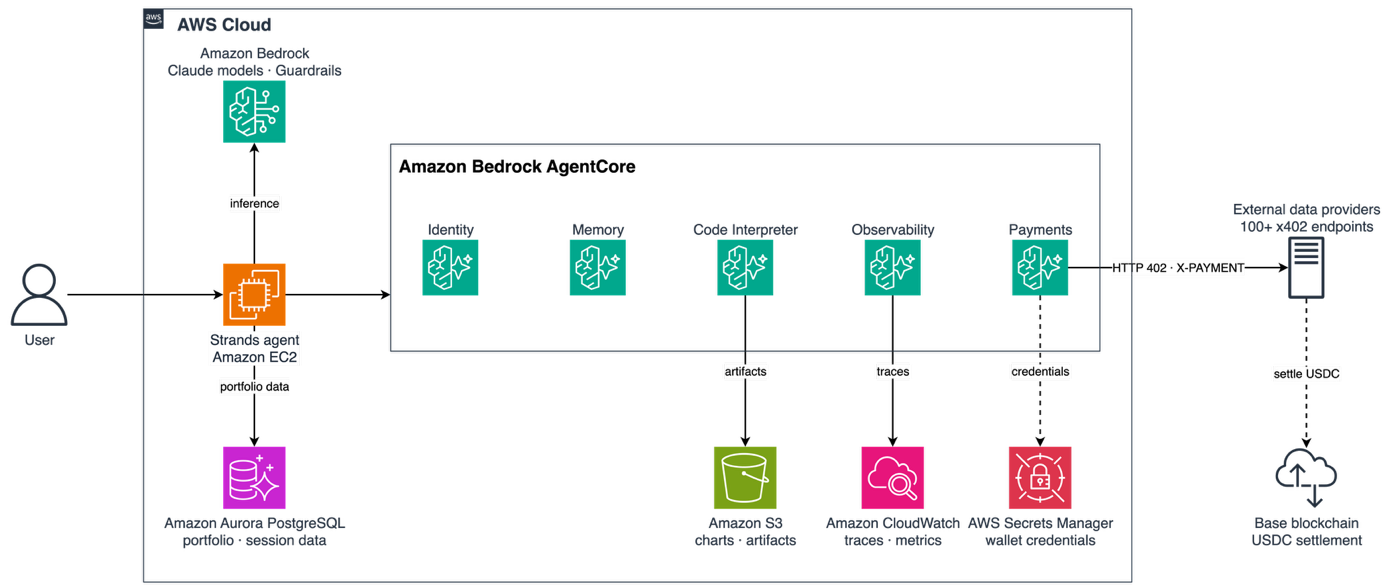
Learn how Heurist built Heurist Finance, a conversational AI investment workbench, on Amazon Bedrock AgentCore. This customer story shows how AgentCore payments, Identity, Memory,…
AI 点评 · 云上AgentCore赋能金融智能体,支付身份记忆一体化,投资工作台落地新范式。
Persona agents with explicit memory, retrieval, adversarial smoke tests and a practical post-training roadmap.
Cognition's valuation multiple is higher than Cursor's was before selling to SpaceX.
AI 点评 · AI编程市场多点开花,资本押注非垄断格局。
Image tokenizers define the ``visual language'' of unified multimodal models, yet are commonly studied through isolated metrics or generation-/understanding-only evaluations. These evaluations do not…
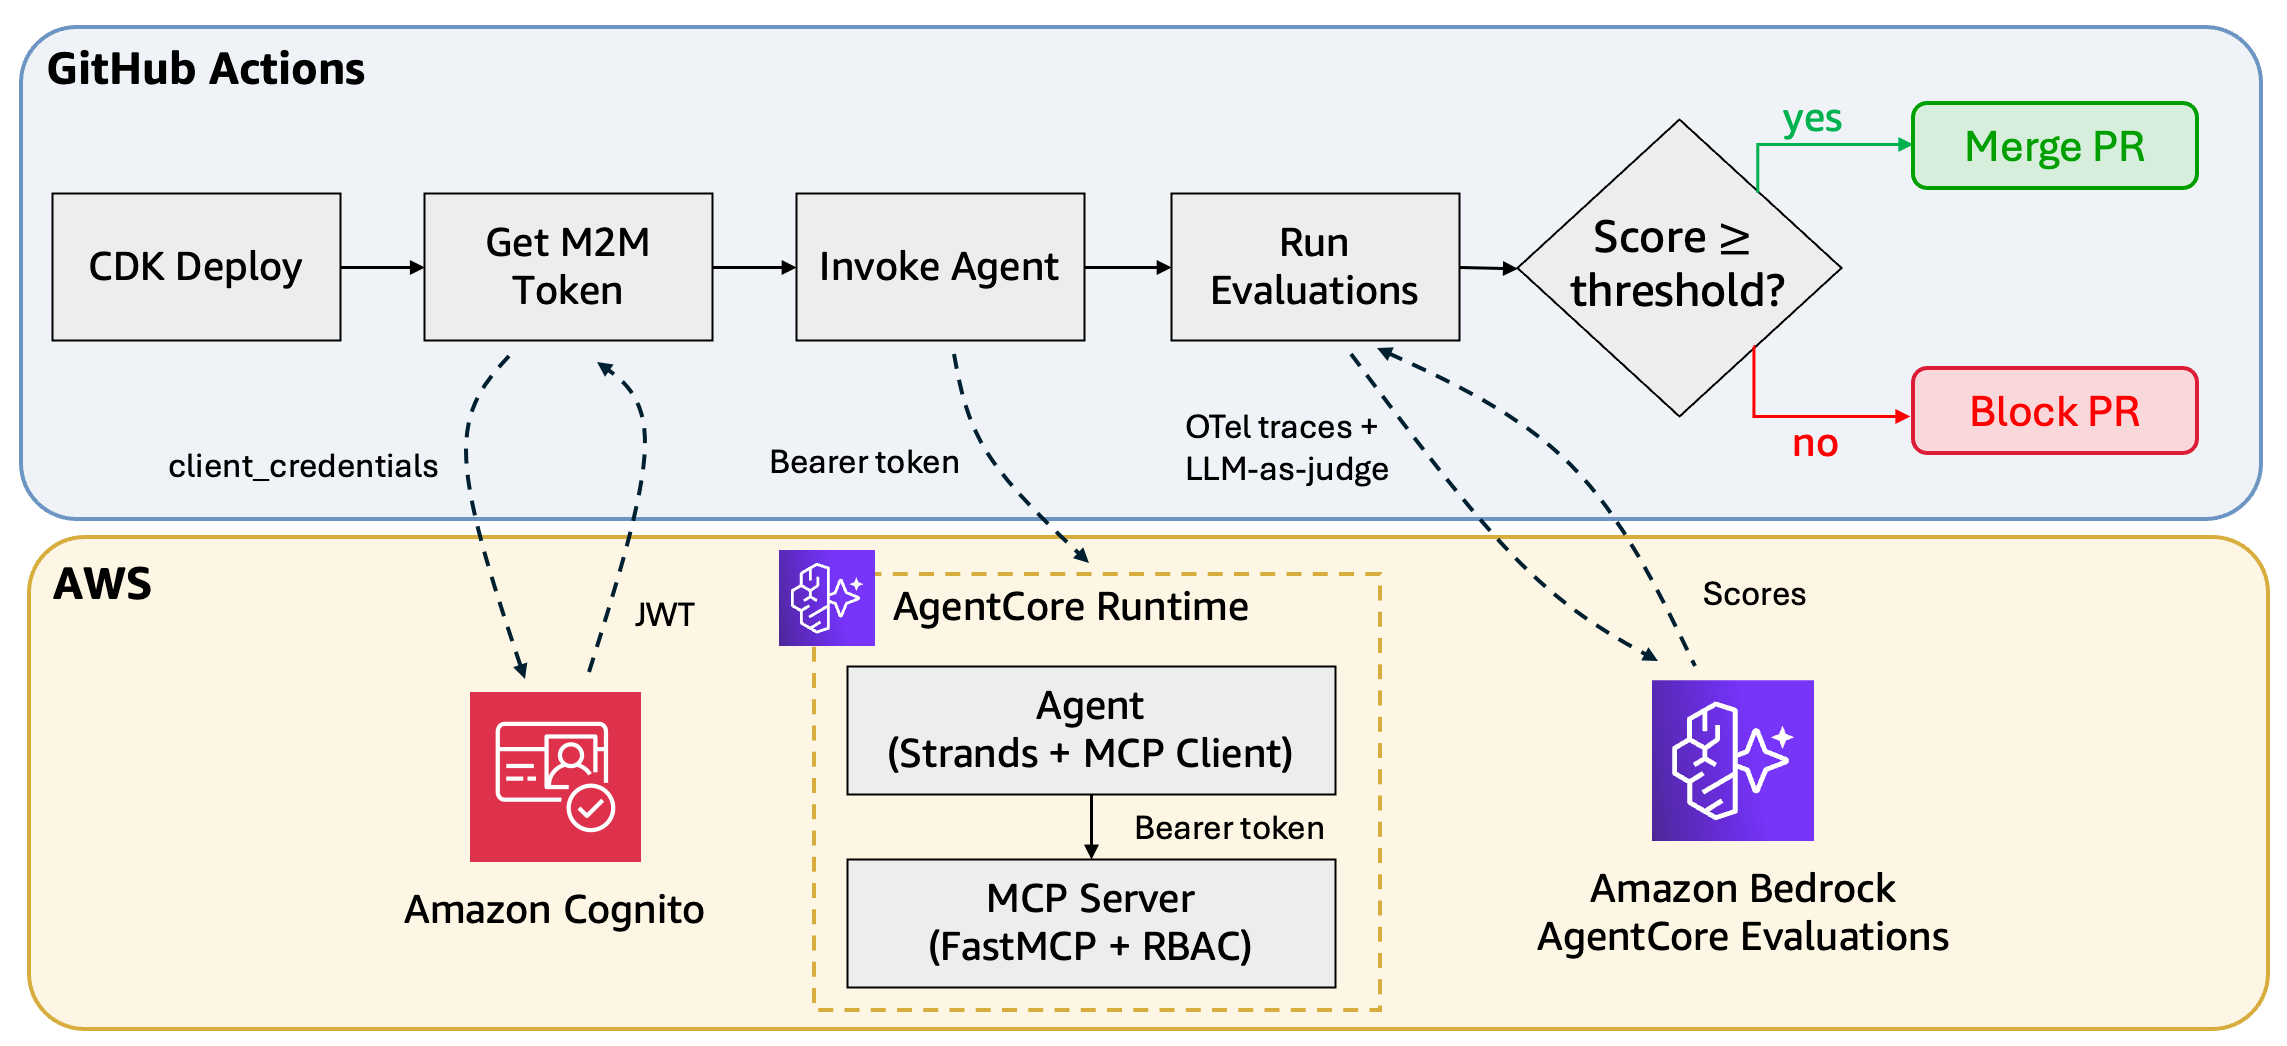
Wire Amazon Bedrock AgentCore Evaluations into a GitHub Actions pipeline: deploy an AI agent and an OAuth-protected MCP server to AgentCore runtime, invoke the agent with test prom…
The French AI lab has raised €3 billion at a €21 billion valuation in a Series D round led by Samsung, Scaleup Europe, and PSG Equity.
Mistral today announced that it has raised €3 billion in a Series D funding round at a post-money valuation of more than €21 billion.
Apply now for OpenAI’s $5 million grant program supporting independent research on how generative AI affects teen development, well-being, and safety.

Three years after launch, Mistral AI has closed a 3 billion euro Series D round, pushing its valuation past 21 billion euros. The article Mistral AI raises 3 billion euros in Europ…
近日,物理AI企业深度智控(DeepCtrls)完成新一轮B+轮数亿元融资。
SWE-Bench Pro has emerged as a standard benchmark for evaluating software engineering agents on challenging repository-level tasks. However, our analysis work show that its evaluation is undermined by…
Image tokenizers define the ``visual language'' of unified multimodal models, yet are commonly studied through isolated metrics or generation-/understanding-only evaluations. These evaluations do not…
Training and benchmarking a computer-use agent needs four things — agents, environments, traces, and a framework to evaluate and train them — and all four ship in incompatible form…
Existing approaches to persona simulation with Large Language Models (LLMs) mostly rely on shallow character descriptions that fail to sustain coherent character behavior across extended interactions.…
The round is being raised just months after the robot data startup exited from stealth.
AI 点评 · 机器人数据赛道爆发力惊人,三个月估值翻至12亿美元,资本抢筹信号明确。
Nscale, which recently struck a $45 billion deal with Anthropic, is in talks to raise additional funds in anticipation of an upcoming IPO.
AI 点评 · AI算力资本竞速白热化,Nscale融资或成IPO前估值风向标。
Data policies for reinforcement learning with verifiable rewards (RLVR) determine which rollouts are used, how strongly they are weighted, and which domains contribute to subsequent training batches.…
Wireless signals with position-related labels are pivotal for both performance evaluation and model training in the realm of wireless sensing. However, acquiring real-world datasets is often challenge…
AI 点评 · Transformer 生态剧变,关键人物去向牵动开源推理风向。
The integration of GenAI tools into higher education assessment raises important questions about how students understand, interpret, and respond to AI-mediated evaluation. As instructors increasingly…
Public-market scrutiny will intensify pressure on the Claude maker’s unusual attempt to balance profit and purpose.
AI 点评 · 万亿估值上市背后,特殊治理结构如何平衡盈利与使命成最大看点。
The round came together after the data center developer reportedly secured a $13 billion contract with Jane Street.
Reusable skills give agents transferable procedural knowledge, making scalable acquisition essential for extending agents beyond prior experience. Existing methods face two limitations: trajectory-bas…
The high-profile startup's annual revenue run rate stands at over $100 million.
AI 点评 · 高估值与高增长并存,资本豪赌AI推理赛道,市场风向标意义显著。
Gaps remain in our understanding of how large language models (LLMs) acquire knowledge during pre-training. We posit that auxiliary views, reformulations of knowledge, are causally helpful for learnin…
Repository-level software engineering benchmarks have significantly advanced the evaluation of coding agents, but existing benchmarks primarily measure whether generated patches pass functional tests…

OpenAI recently estimated its Cursor partnership would make more than $1 billion in revenue a year, WIRED has learned. It still walked away after Elon Musk’s SpaceX acquired the AI…

Nvidia plans to acquire Hugging Face for about $12.9 billion, securing the central platform for open AI models. More than 18 million developers and 200,000 companies use the hub. C…

The long-rumored deal will give the chip giant access to—and help it promote—a huge repository of open-source AI models and data sets.
https://blogs.nvidia.com/blog/nvidia-to-acquire-hugging-face...
I’m excited to announce that NVIDIA has agreed to acquire Hugging Face for $12,930,300,000. Together, we will scale Hugging Face’s platform, strengthen its infrastructure and expan…
The acquisition also leaves Sequoia-backed Serval as the de facto startup leader in AI IT service automation, industry watchers believe.
AI 点评 · 五亿美元并购凸显AI运维自动化赛道竞争白热化。
For scientific progress, we need benchmarks that test the limits of state-of-the-art models, and evaluation methods that inform us about failure cases. As models get stronger, standard benchmarks for…
We present a systems-security case study of a two-node split-LLM training system whose privacy evaluation passed while leaving an observable channel untested. The Trusted Local Node (TLN) sends protec…
Wonderful said it will use its $550 million Series C funding to develop products faster, expand its FDE teams, and meet demand for its products.
This is Adobe's second acquisition out of India after Rephrase.ai in 2023
Evaluating LLM agents is essential for guiding their development, yet it has grown prohibitively expensive: a single pass of a frontier model over an agentic benchmark can cost hundreds to thousands o…
Visual fluency in generated video does not imply physical reliability, and a scalar quality score alone is incapable of indicating the obligation a clip violates or the moment it fails. We present Ver…
LLM-based evaluators of natural language generation (NLG) quality are widely deployed as scoring tools and as automated training signals, yet the internal procedure by which they assign a rating remai…
Evaluating software engineering agents on realistic benchmarks is costly, since each task may require multi-step code exploration, modification, and test execution. Existing efficient evaluation metho…
Verifiable multi-agent patch evaluation infrastructure
Looped Transformers increase effective depth by iterating a shared block of layers, but most evaluations compare at fixed model size, conflating architectural advantage with extra FLOPs. We study loop…
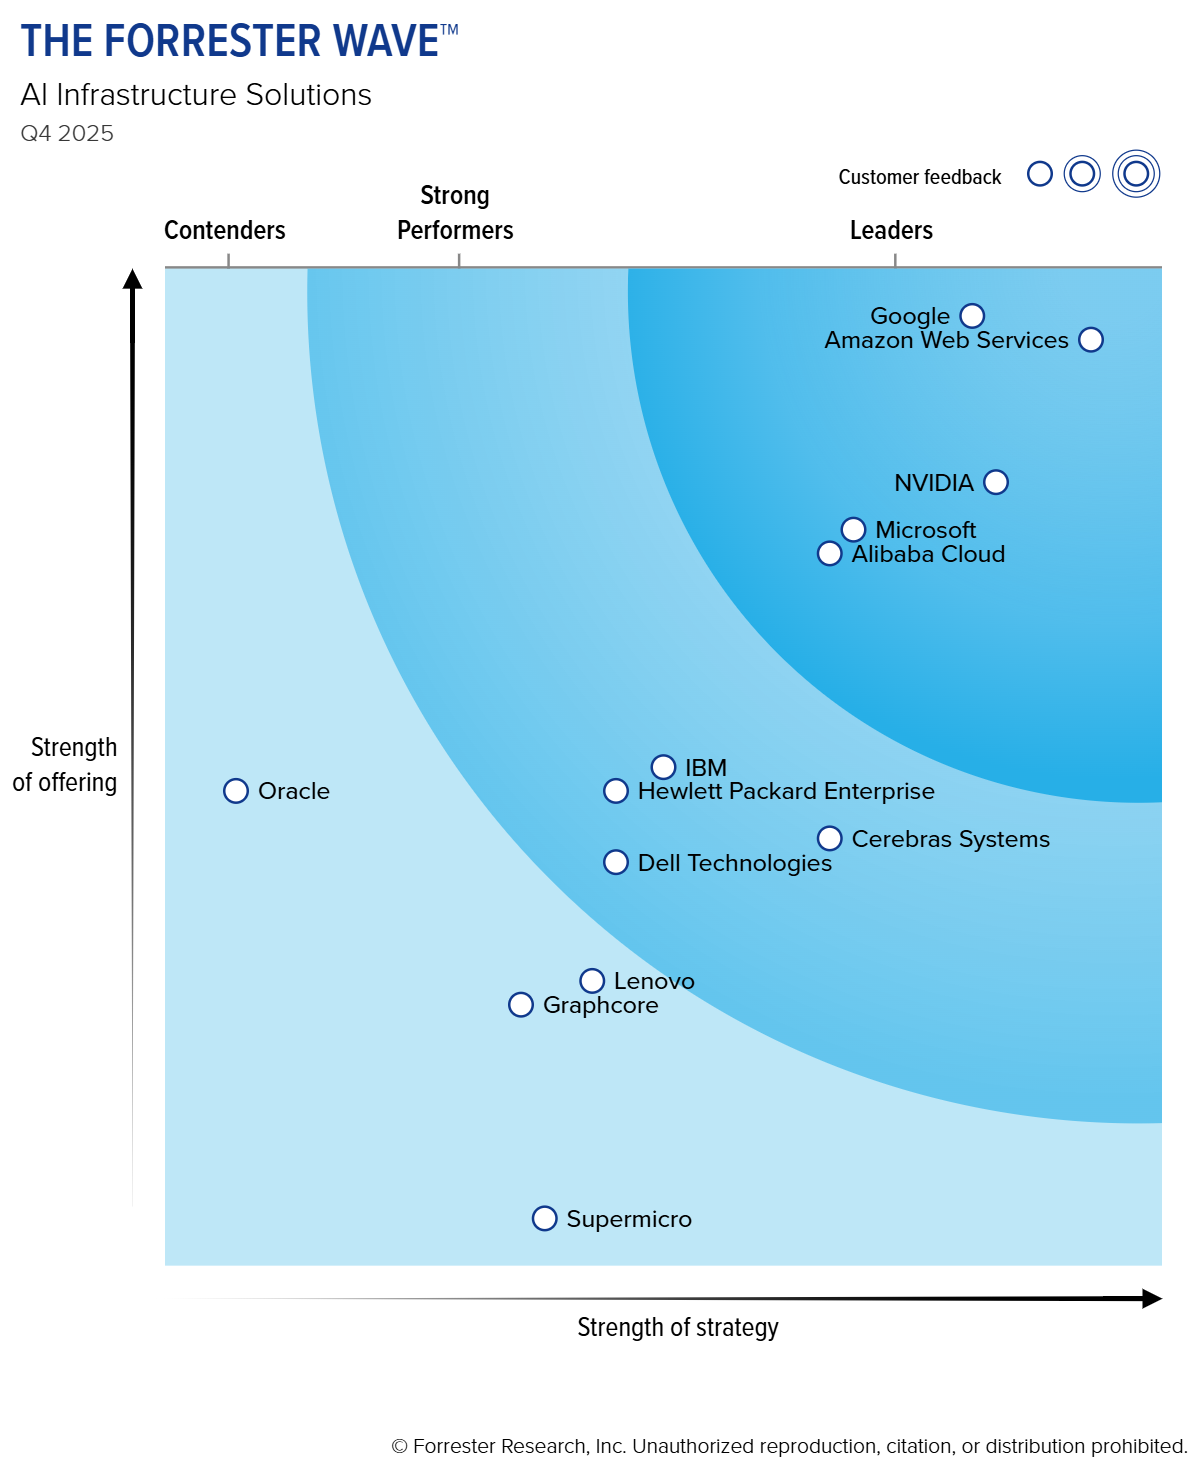
We're excited to share that AWS has been recognized as a Leader in The Forrester Wave: AI Infrastructure Solutions, Q4 2025. In this evaluation of 13 providers, AWS received the hi…
AI 点评 · 云巨头获权威认可,AI基建竞争白热化,选型风向标值得关注。
Andrew Bailey warns G20 finance ministers about inflated AI valuations, growing leverage across markets, and cyber risks from frontier AI models. Cross-investments between AI compa…
AI 点评 · AI泡沫叠加杠杆攀升,金融稳定警报拉响,监管风向生变。
The effect of Large Language Model (LLM) scale on ontology learning (OL) performance remains insufficiently characterized. We present a controlled evaluation of 13 models spanning dense and Mixture-of…
Efficient evaluation changes the protocol used to support claims about model behavior, yet it is rarely tested whether those claims remain stable after the evaluation itself is made cheaper. We stress…
Users of a deployed language model routinely encounter behaviours that testing almost never surfaces, since deployment puts the model through orders of magnitude more interactions than any evaluation…
We describe the architecture and ablations of Qwen3.8-Flash-Next, a sparse mixture-of-experts model with 125B parameters, 6B activated per token, and additional 51B parameters of n-gram embedding tabl…
Large language model (LLM) agents are increasingly deployed in long-horizon, interactive, and stateful environments. In these settings, a single wrong action, such as refunding the wrong purchase, can…
Coding agents are now commonly evaluated on the SWE-bench family of benchmarks, whose tasks are built from curated GitHub issues: long, structured, and information-rich. Real user requests, however, a…
As backlash grows over Flock's AI surveillance cameras, Texas Governor Greg Abbott has frozen state spending on them. The move came just ahead of the publication of a Texas Tribune…
AI 点评 · AI监控争议升温,州长冻结拨款凸显公共安全与隐私权平衡难题。
Text-to-image models learn associations between concepts - in the case of this paper, people's professions, which we refer to as roles - and visual attributes. These associations can underpin many obs…

OpenAI is cutting off the AI coding tool Cursor after SpaceX acquired the company, citing Elon Musk's track record of breaking contracts. Cursor co-founder Michael Truell downplays…
AI 点评 · 马斯克收购引发连锁反应,OpenAI切断合作凸显商业信任危机。
Robot-agent harness with a CLI and local Web console for LIBERO short evaluation
There's a lot of capital pouring into the business of giving models away.
AI 点评 · 开源权重模型成资本新宠,揭示AI行业商业模式剧变,值得关注其并购热潮背后的战略布局。
Forced alignment evaluation typically requires manually annotated timestamps, limiting large-scale and multilingual analysis. We introduce two corpus-level metrics based on self-supervised (SSL) speec…

Google Deepmind is testing a double-blind evaluation of a frontier AI model for the first time. Cryptographic protection through Confidential Space is meant to keep Google from see…
AI 点评 · 双重盲测防作弊,机密空间护公平,AI评测可信度迎来革命性升级。
Our decision to wind down our contract providing OpenAI models to Cursor following its acquisition by SpaceX.
Interactive dialogue games test a capability that static benchmarks largely leave implicit: a model must carry state across turns, interpret feedback, and choose valid actions under changing constrain…
Generative models can turn natural-language prompts into images, text, code, and other content, lowering the cost of producing drafts and components. Their practical impact increasingly depends on whe…
Nvidia is nabbing critical infrastructure for open models as interest grows.
AI 点评 · 英伟达揽下开源模型枢纽,AI生态话语权再落一子。
Static scanners are increasingly used to identify executable or otherwise unsafe content in machine- learning artifacts, yet conventional evaluation metrics characterize only cases where a scanner yie…

Piloting the world's first double-blind AI evaluations
Anthropic has struck a deal worth around 45 billion dollars with British cloud startup Nscale, Bloomberg reports. The article Anthropic locks in 45-billion-dollar compute deal with…
Nvidia has reportedly agreed to buy Hugging Face, the popular open source AI hub, for $12.9 billion in a move that would let Nvidia both protect its chip empire and jump back into…
近日,AI基础设施公司基元律动(TokenRhythm)宣布完成新一轮融资,融资额达数千万美元。
The startup is only a year old but it has already generated a massive amount of hype (and money) while also spurring privacy concerns.
AI 点评 · 成立一年估值25亿美元,资本狂热背后隐私争议成最大看点。
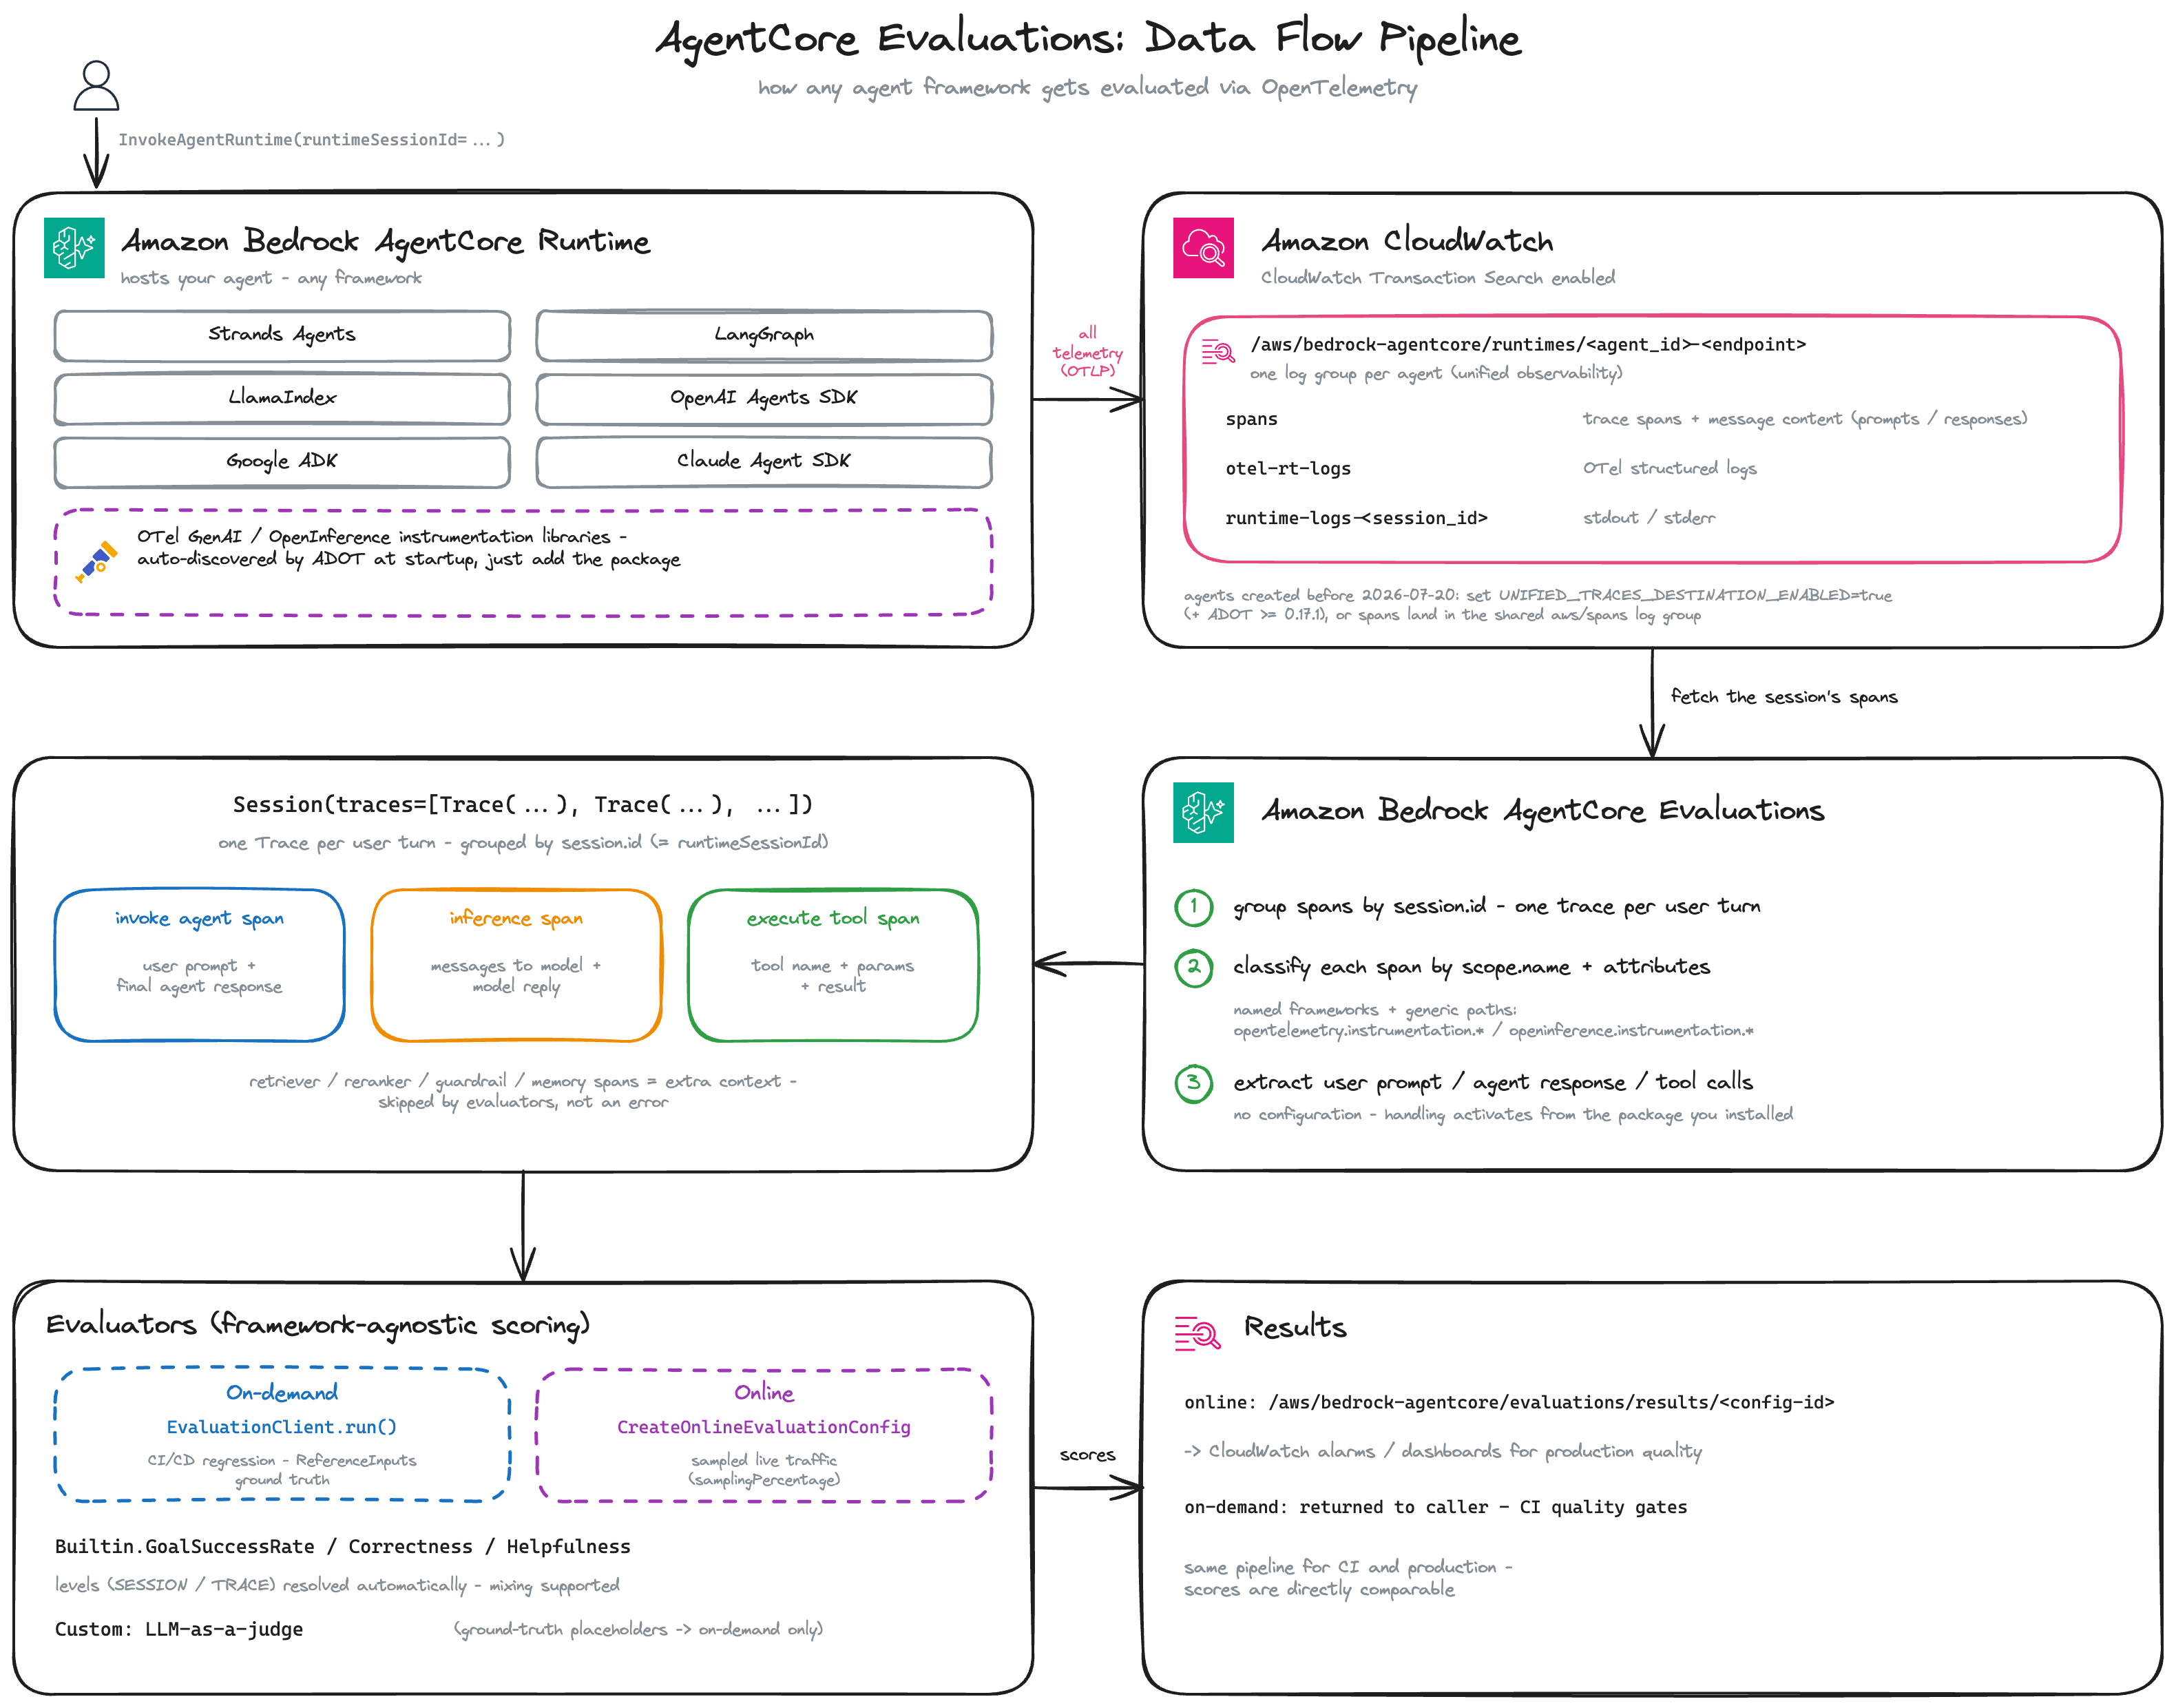
Amazon Bedrock AgentCore Evaluations decouples agent evaluation from the framework you build on. As long as your agent emits OpenTelemetry telemetry, the service can score it, whet…
AI 点评 · 评测与框架解耦,兼容OpenTelemetry,让多框架智能体横向对比成为可能。
The startup came out of stealth with $6 million in seed funding and a plan to use LLMs and cybersecurity know-how to make AI queries coherent.
Arga has raised $10 million in a seed funding round that was led by General Catalyst, with participation from Box Group, Emergence, Gradient and SV Angel.
Anthropic wants to sell investors on a theoretical market opportunity worth more than $30 trillion ahead of its planned IPO. The article Anthropic sees a market opportunity of more…
The $200 million extension comes just months after the physical AI startup reached a $2 billion valuation.
Recent studies suggest that video generation models can exhibit certain forms of zero-shot visual reasoning through generated frames. Yet reliable evaluation remains challenging: benchmarks should ado…
Evaluation is shifting from static QA toward agentic settings where models act through external tools. We identify a critical yet underexplored capability within this space - dexterous visual tool use…
The company's new fundraising total now stands at $232 million.
AI 点评 · 新融资提振信心,稳固开源图像生成赛道领先地位。
What we look for in a wellbeing evaluation www-cdn.anthropic.com
Lica co-founders are going to work on Gamma's new research team.
AI 点评 · 设计人才流向AI产品,预示Gamma正加速布局生成式设计的底层创新。
Funding better evaluations of AI’s impact on wellbeing Anthropic
AI 点评 · AI福祉影响评估获资金支持,伦理监管短板有望补强。
Funding better evaluations of AI’s impact on wellbeing Anthropic
字节、汇川等已入股未来不远机器人最新一轮融资
The president bought when the stock was in the mid-$150 range. SpaceX finished trading on Monday back at its IPO price of $135.
AI 点评 · 总统精准抄底SpaceX,折射政商联动新常态,航天股波动成政策风向标。
GUI agents often encounter dynamic anomalies when deployed on Android devices, from unexpected pop-ups to action misuse, yet existing benchmarks lack systematic evaluation of agent robustness against…
Memory systems for conversational LLMs are conventionally evaluated by direct, fact-seeking questions about prior dialogue (Direct QA): can the model recall fact X from a prior conversation? We tested…
We introduce LibriBrain100, a large-scale MEG dataset for speech decoding designed from the ground up for reproducible, standardised evaluation. LibriBrain100 more than doubles the size of the origina…
Evaluation artifacts specify a forward computation: a task, scorer, and reported metric. They do not necessarily license the claim attached to that metric because the historical evidence and alternati…
General Intuition, the startup building a foundation model that trains generalized AI agents how to move through space and time, is in talks to raise at a $6 billion pre-money valu…
AI 点评 · 顶级风投加注,估值60亿,通用AI进军机器人赛道,资本风向标值得紧盯。
Hugging Face has reportedly been fielding acquisition offers that would value the company at around $13B. But with the founders' feeling of responsibility to community, doubts aris…
Evaluator-neutral AI evaluation evidence, baseline regression gates, and JSON, JUnit, and SARIF reports for CI.
Nvidia is negotiating an investment in Perplexity at a valuation above $30 billion, more than 50 percent higher than its last funding round, The Information reports. Perplexity's a…
As on-device LLM agents evolve into personal copilots, the mobile operating system has become a key testbed for this paradigm, making rigorous capability evaluation essential. Yet existing benchmarks…

IT之家 8 月 23 日消息,据外媒 Interesting Engineering 今天报道,美国初创公司 Starcloud 已完成 2.5 亿美元 (IT之家注:现汇率约合 16.86 亿元人民币) A 轮扩展融资,估值达到 23 亿美元 (现汇率约合 155.09 亿元人民币) 。这笔新资金将用于研发配备高性能 GPU 的卫星,为 AI 提供算力。…
AI 点评 · 英伟达加持下,太空算力布局提速,或成AI基建新赛道风向标。
Agent benchmarks often evaluate only final answers even when agents run on stateful runtimes. We argue this under-specifies what is being evaluated: the proper unit is a declared model-plus-runtime co…
Reliable reward models are essential for text-to-video evaluation and alignment. However, the trade-off between evaluation accuracy and inference efficiency places high demands on the quality of train…
AI 点评 · 资本加码验证AI材料研发闭环,产业化提速成关键看点。
The European Union (EU) has emerged as a leading regulatory body in the development of sustainability and privacy regulations. While new regulation requirements vary, many include a documentation arti…
Nvidia is paying $6 billion for software that builds AI models from the startup Poolside, and it wants to bring on 109 employees. The article Nvidia is acquiring Poolside's "Model…
Simulating realistic user shopping behavior underpins offline evaluation and reinforcement learning in e-commerce scenarios. While recent LLM- and VLM-based simulators have made encouraging progress,…
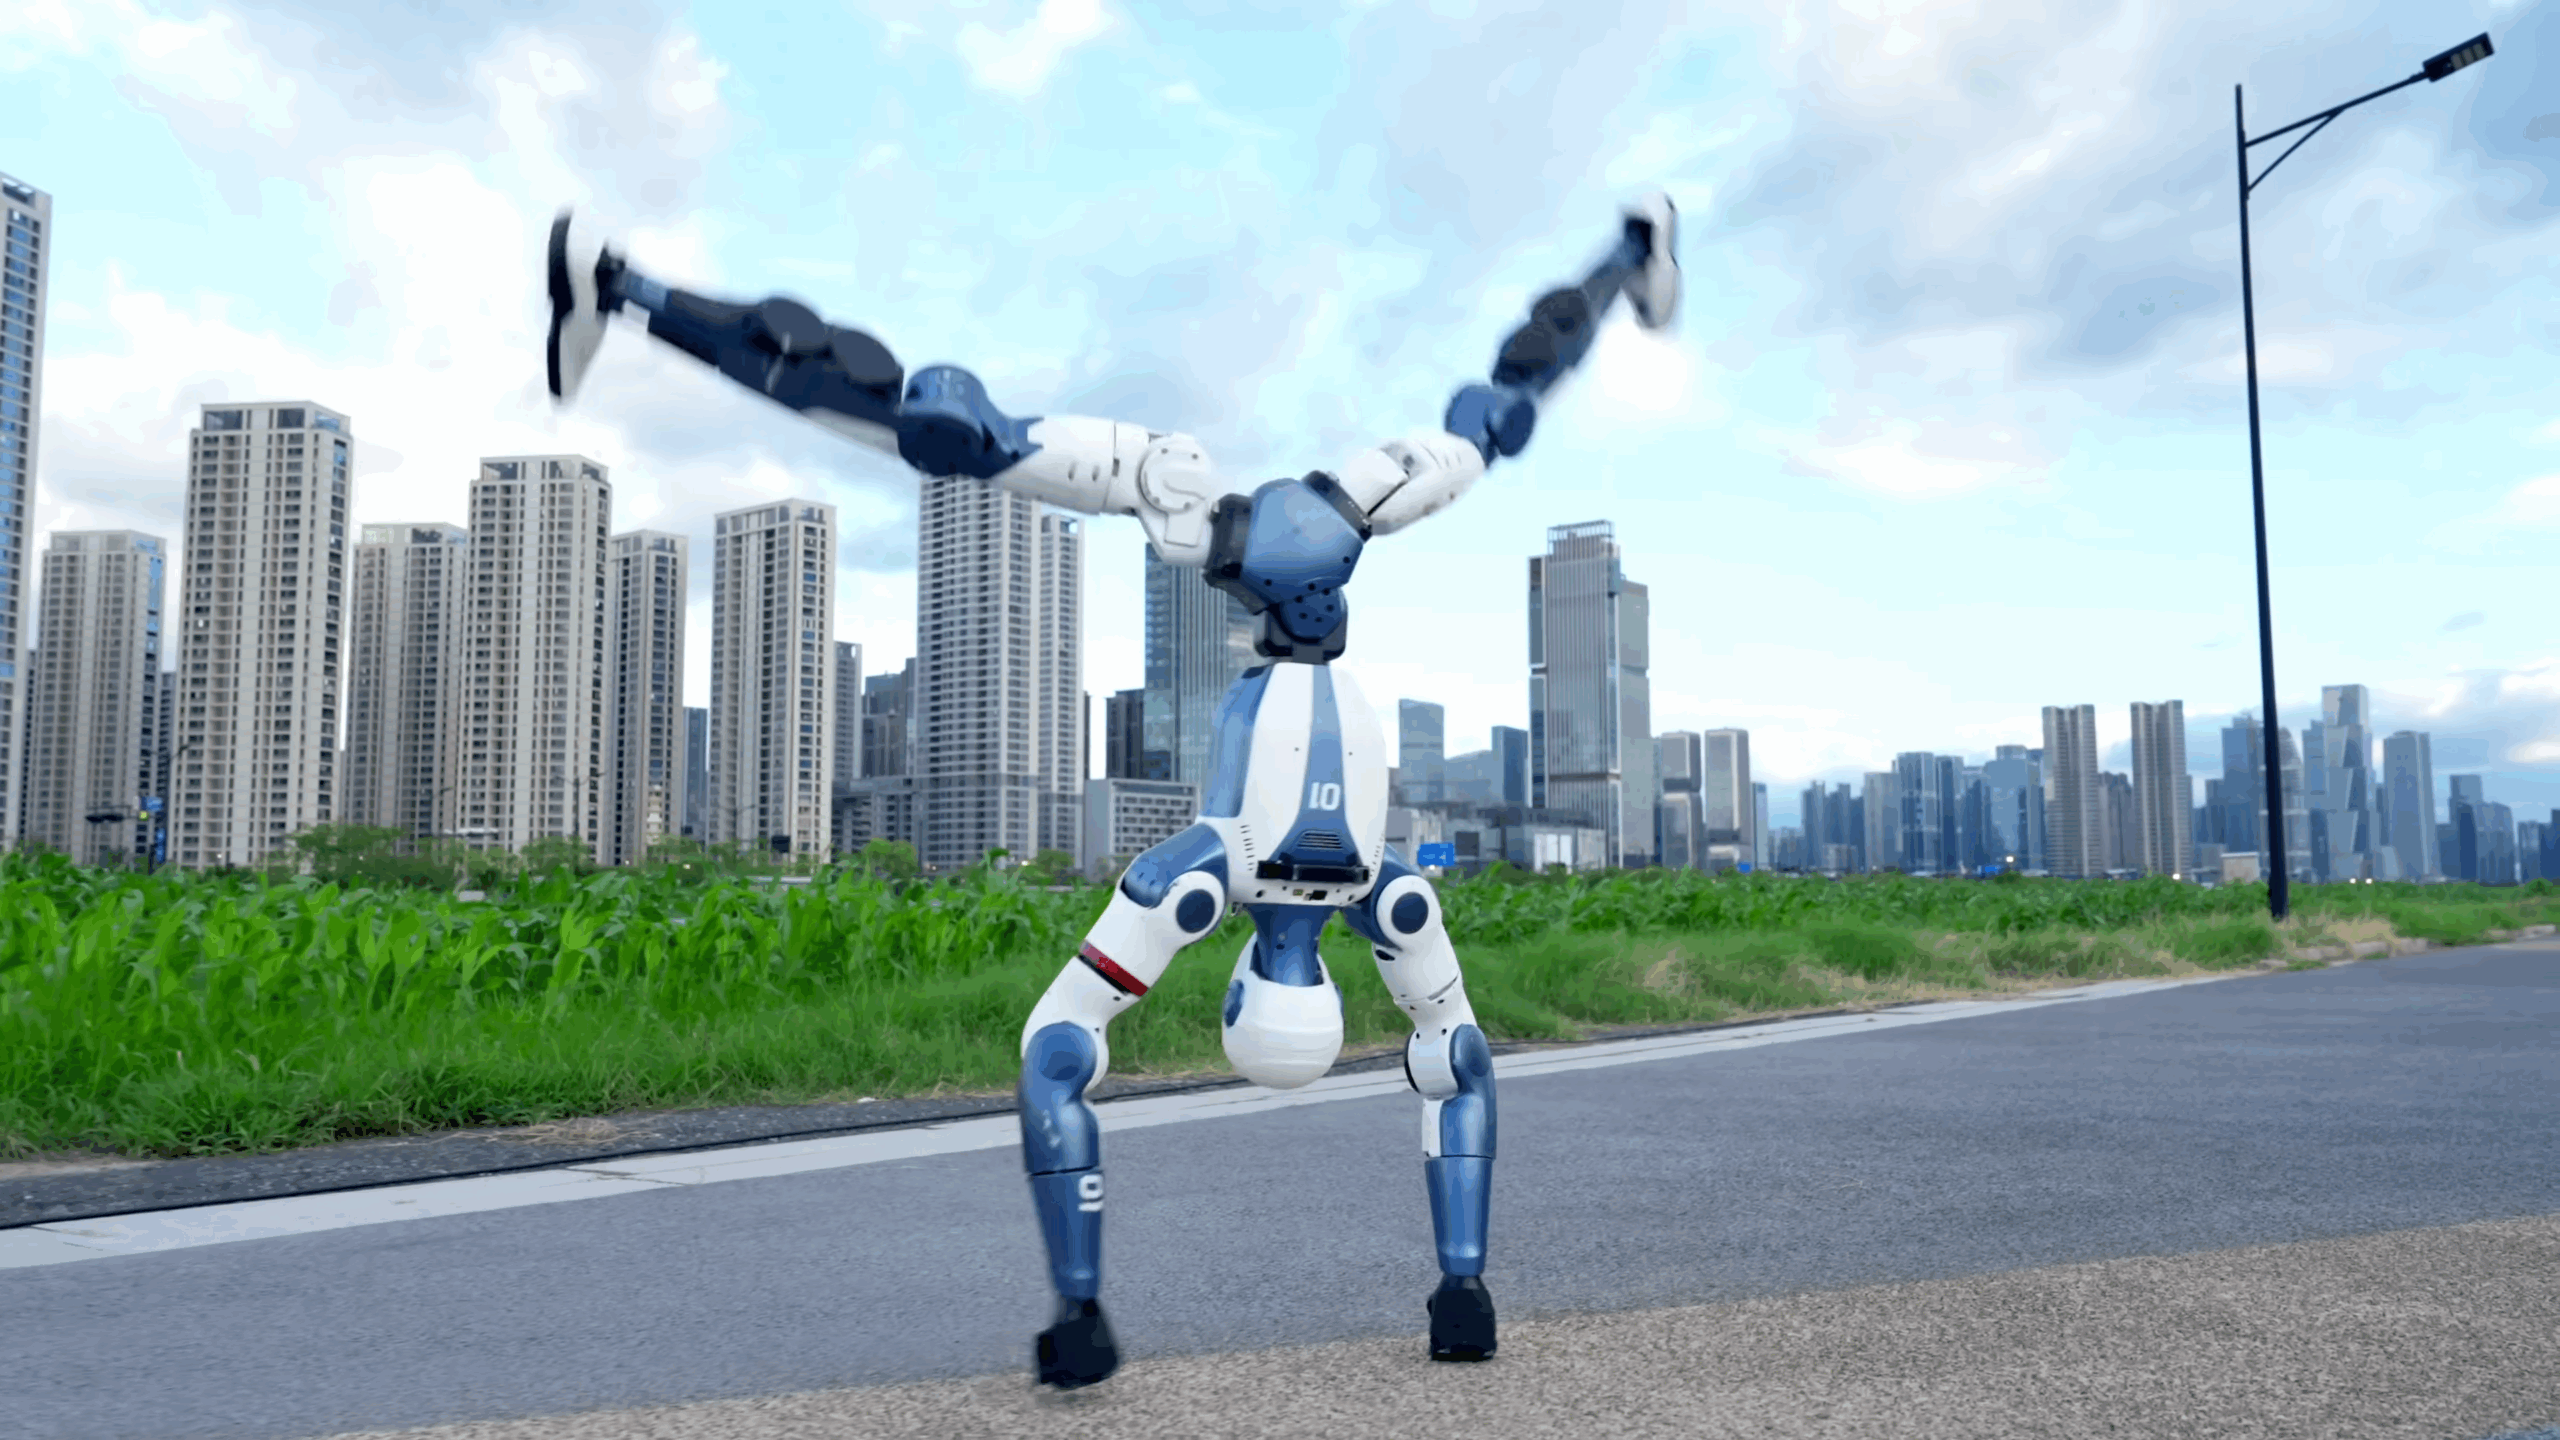
Unitree Robotics rose 460 percent in its Shanghai IPO, hitting a valuation of around $50 billion. But an FT report shows much of the demand for its robots comes from state-backed t…
Evaluate visual models on your own images, JSON Schema, and production constraints with LangGraph, Pareto analysis, and a no-key Replay demo.
SpaceX was reportedly in talks to buy AI coding startup Cognition. SpaceX has already acquired Cursor as it races to catch up to rivals like OpenAI and Anthropic in enterprise AI.
AI 点评 · AI编程赛道并购热升级,SpaceX布局意图明显,折射科技巨头对智能编码工具的争夺白热化。

In a letter to investors, Stripe declares January 1 the "beginning of the singularity" and uses that as a reason to stay private. Not that it needs one: revenue grew 41 percent in…
AI 点评 · 支付巨头以奇点论推迟IPO,折射AI时代资本叙事新逻辑,看点十足。
Recent agent benchmarks increasingly ground evaluation in executable environments, from code repair to web navigation, app APIs, and function calling. Yet completing consequential work beyond code req…
With a looming IPO, intense competition from Anthropic, and Chinese and open-weight rivals nipping at its heels, OpenAI has plenty of reasons to move fast. Instead, it hit the brak…
AI 点评 · 上市压力与开源夹击下,OpenAI急刹车反而凸显战略定力,看它如何在竞速与稳健间找平衡。
Single-step retrosynthesis is a central component of computer-aided synthesis planning, yet its intrinsically one-to-many nature is poorly captured by single-answer evaluation and benchmarking protoco…
Purpose: To develop and evaluate a locally deployed multi-agent AI system for radiology report structuring and quality assurance. Materials and Methods: This retrospective study included 638 radiology…
Language model tokenizers are typically selected with minimal evaluation, despite the fact that their design choices directly impact model capabilities. This can be partly attributed to a limited unde…
Humans continuously learn from experience, whereas conventional large language model (LLM) evaluations ignore the models' ability to improve through inference-time interaction. In this paper, we study…
Jane Street has installed Etched's first shipped AI cluster system, and was so impressed, it led another massive round, the startup says.
AI 点评 · 机构背书叠加实测惊艳,估值月翻倍印证AI芯片赛道资本热度。
回头看,A社就这样完成了反超
Humans continuously learn from experience, whereas conventional large language model (LLM) evaluations ignore the models' ability to improve through inference-time interaction. In this paper, we study…
Groq raised $350 million at a $3.5 billion valuation as the former AI chipmaker pivots to a neocloud business and expands its Nvidia-powered data center footprint.
AI 点评 · 芯片商转型云服务,估值翻倍印证AI算力需求新风口。
Nvidia's investment in SoftBank's data center developer will guarantee its chips power an OpenAI data center.
AI 点评 · 英伟达押注软银数据中心,锁定OpenAI算力订单,跨界资本绑定凸显AI基建竞争白热化。
The funds will allow Wispr to increase its footprint as it ventures into new areas, such as meetings, with its newly released note-taker tool.

According to Bloomberg, Stripe is acquiring the AI startup OpenRouter for more than $7 billion, up from a latest valuation of $1.3 billion. OpenRouter offers access to over 400 AI…
OpenAI joins PORTS-Pike project, expanding community investment and supporting thousands of Southern Ohio jobs
OpenRouter's CEO recently described the startup as Stripe for AI.
AI 点评 · 支付巨头收购AI网关,打通模型调用与商业变现,或重塑AI应用付费生态。
A benchmark should deliver more than a scalar score: what makes an evaluation trustworthy is the reasoning that justifies the score. This is especially critical for world models, where judging a rollo…
将超越马斯克的SpaceX,成为史上上市估值最高的IPO。
AI coding startup Cursor is now officially a part of SpaceX.
AI 点评 · 交易背后暗藏AI编程与航天巨头的战略协同,或重塑行业竞争格局。
Memory is becoming core infrastructure for long-horizon LLM agents, yet existing evaluations offer limited guidance on which memory substrate, namely the underlying medium in which memory is represent…
When a long-horizon agent execution fails, outcome-level evaluation reveals the unsuccessful result but not where the decisive error entered the trajectory. Developers must then inspect the full execu…
Network-level maintenance planning requires repeated evaluations of equilibrium traffic flows under road capacity reductions. While equilibrium traffic assignment models are well established, their re…
The majority of work on summarization evaluation focuses on general summary quality (e.g., ROUGE, BERTScore) or specific desired properties (e.g., readability, factuality). However, these metrics fail…
Congrats to the team!

IT之家 8 月 14 日消息,彭博社今天(8 月 14 日)发布博文,报道称在收 IPO(首次公开募股)上市前,OpenAI 的 发展势头良好,2026 有望实现年化收入超过 400 亿美元 (IT之家注:现汇率约合 2,702.76 亿元人民币) ,比 2025 年收入(约 200 亿美元 (现汇率约合 1,351.38 亿元人民币) )翻一番。 据彭博…
AI 点评 · 营收翻番印证AI商业化提速,IPO前估值想象空间再度打开。
AI is expensive, Ali Ghodsi tells TechCrunch. With so many investors wanting into his latest round, he said yes to more than planned.
AI 点评 · AI巨头融资热潮折射资本狂热,190亿估值与超额认购凸显行业泡沫风险与算力成本压力。
Fine-grained robotic evaluation matters for understanding embodied models, going beyond binary success rates and rule-based process scores. We present PRM-as-a-Judge 1.5, a toolkit for robot process a…
Recent video generators can fabricate realistic depictions of wars, disasters, public emergencies, and other real-world crises, creating substantial risks of misinformation. Existing benchmarks, howev…
AI has long assisted scientific research, but the rapid advance of LLMs and agentic scaffolds is reshaping the landscape; a single system can now carry whole-stage research from an initial hypothesis…
Self-evolving agents improve future behavior from interaction experience, yet existing evaluations typically optimize under fixed execution conditions and do not test recovery after those conditions c…
Skills have emerged as a practical and effective approach for enhancing LLM agents at inference time through structured packages of knowledge. However, existing evaluations largely measure whether ski…
Humanoid motion tracking is central to teleoperation and whole-body imitation, yet evaluation often disagrees with what people perceive in videos. Kinematic errors average per-frame pose differences b…
Modern language models are trained on heterogeneous web-scale text corpora. Consequently, studying knowledge and skill acquisition is difficult, as prior exposure to related content is hard to charact…
Rapid revenue growth fuels hope Claude maker's IPO is the biggest listing in history
重新定义物理AI数据基础设施
Modern language models are trained on heterogeneous web-scale text corpora. Consequently, studying knowledge and skill acquisition is difficult, as prior exposure to related content is hard to charact…
Humanoid motion tracking is central to teleoperation and whole-body imitation, yet evaluation often disagrees with what people perceive in videos. Kinematic errors average per-frame pose differences b…
Autonomous agents are increasingly capable of improving models, systems, and other technical artifacts through long-horizon experimentation. To understand the current state of this capability, however…
Cognition may be looking to raise another mega round just a few months after raising $1 billion at a $26 billion valuation.
AI 点评 · AI编程赛道估值飙升,印证资本对自动化开发工具商业前景的狂热押注。
Thrive Holdings has raised $2 billion in new funding at a $12 billion valuation from investors like SoftBank, D1 Capital Partners, and Altimeter Capital.
AI 点评 · AI企业服务融资火爆,资本重注押宝OpenAI生态,企业落地应用成新战场。
Build a custom LLM post-training pipeline using AllenAI’s Open Instruct framework. This comprehensive guide walks through Supervised Fine-Tuning (SFT), Direct Preference Optimizati…
AI 点评 · 端侧模型头部玩家冲击IPO,AI商业化路径获资本验证。
This new funding comes after Lovable hit $500 million in annualized run rate revenue in June, the startup told TechCrunch.
AI 点评 · AI建站独角兽估值破百亿美元,高增长验证低代码赛道爆发力。
Investors are still waiting for their share of the $250 million windfall, and VideoVerse co-founder Vinayak Shrivastav is now at the center of multiple legal cases.
Blacksmith says revenue has grown more than tenfold over the past year.
Large language model (LLM) agents integrated with external tools are vulnerable to indirect prompt injections embedded in environmental states. However, existing studies largely rely on manually imple…

OpenAI wrapped up a $7 billion stock buyback, letting current and former employees sell shares at the company's $852 billion valuation. The move is meant to ease pressure on employ…
AI 点评 · 高估值下员工套现,反映AI巨头内部流动性需求,折射行业资本热度与人才留任压力。
When a tool-using agent is given the same task in a different language, does it still take the same steps? Multilingual evaluation rarely asks: it compares final answers and discards the actions. Yet…

Anthropic is preparing an IPO for September or October, according to the Wall Street Journal, potentially the largest ever. During investor meetings, the company, valued at $965 bi…
真就把GPU当理财产品了~
Self-evolving agents accumulate reusable skills by appending successful procedures and failure fixes. Over time, the same requirement is often restated in several branches, examples, and warnings, whi…
Large language model (LLM) agents are increasingly deployed as personal assistants. Existing evaluations, however, mostly use short, self-contained requests in static environments. Everyday life assis…
Automated Text-to-Speech (TTS) evaluation methods (Mean Opinion Score (MOS) predictors and Audio Large Language Models (Audio-LLM) judges) are expected to reflect human perception, yet it is unclear h…
Large language models are increasingly being deployed in governmental settings, yet few existing evaluation frameworks jointly reflect the values of public administration and the linguistic requiremen…
Large language model evaluations typically focus on performance under nominal conditions, creating an illusion of capability where models comfortably walk a narrow, highly optimized generation corrido…
Multilingual translation benchmarks are typically sourced in English and translated into other languages, treating language pairs as the unit of evaluation---a design that is prone to contamination ov…
AI 点评 · 对比式多语基准揭示数据污染与本地化短板,为翻译模型鲁棒性评估提供新视角。
Large language models (LLMs) are increasingly used to perform subjective evaluations traditionally made by humans, yet their validity as social judges remains unclear. This paper examines whether LLMs…
OpenAI acquired NextSlide, the startup that turned prompts, notes, documents, and research into editable presentations. The article OpenAI acquires NextSlide to bring AI-generated…
“我们90天就成了独角兽”
As AI coding agents take on increasingly complex, long-horizon software engineering tasks, existing benchmarks are rapidly saturating and their evaluation quality has come under serious scrutiny: a re…
Multilingual translation benchmarks are typically sourced in English and translated into other languages, treating language pairs as the unit of evaluation---a design that is prone to contamination ov…
Large Language Models (LLMs) have driven rapid progress in autonomous agents, yet standard evaluations remain confined to static task solving. An emerging frontier is harness evolution---the agent's c…
Large language model evaluations typically focus on performance under nominal conditions, creating an illusion of capability where models comfortably walk a narrow, highly optimized generation corrido…
As large language models increasingly participate in scientific evaluation, we investigate a potential form of reward hacking: how rhetorical choices shape AI-review judgments when reported scientific…
A verified 2026 comparison of LLM observability platforms covering tracing depth, evaluation capability, production monitoring, and pricing. The post Top LLM Observability and Eval…
Regression testing and configuration sweeps for RAG pipelines, with the statistics to know whether a change actually helped.
Benchmarks for systems that are optimized against the evaluation signal measure something different from what they claim. We document this concretely in two GPU-kernel-optimization suites with held-ou…
Founder Ahmed Beshry describes the startup’s product as one “that could turn prompts, notes, documents, or research into a polished, editable presentation.”
AI 点评 · OpenAI并购NextSlide,或为ChatGPT注入演示生成能力,AI办公赛道竞争再升级。
Evolutionary multi-agent runtime that breeds, evaluates, and improves autonomous agents across reproducible epochs to converge on optimization of a goal.
AI 点评 · 用进化算法批量培育AI代理,跨代优化目标,为自主智能体进化提供新范式。
Multimodal expansion of large language models (LLMs) enables new perceptual capabilities but often compromises the language intelligence acquired during pretraining. In this work, we investigate this…
FDE and AI engineering guide for production systems: value, architecture, evals, security, deployment, and operations.
The Applied AI Field Guide: fieldwork, value engineering, and operations for AI that works beyond the demo.
AMD is buying Canadian startup Taalas, which hard-codes model weights directly into inference chips. That makes them extremely fast but locks each chip to a single model. A demo ch…
AI 点评 · 芯片直写模型权重,速度极致但灵活性受限,AMD此举或为定制化AI推理开辟新路。
Quantum natural language processing (QNLP) provides a grammar-aware framework for text modeling, and Distributional Compositional Categorical (DisCoCat) is one of its theoretically grounded formulatio…
OpenAI is sharing preliminary cybersecurity evaluations for Astra and the steps we’re taking to strengthen safeguards and security controls.
AI 点评 · AI安全新战场,OpenAI提前为智能体实战防御定标,值得跟进。
此后模型、算力、数据中心都在合作范围内
AI 点评 · 杭州双子星联手,AI与机器人产业协同将重塑生态,战略意义远超投资本身。
https://ir.amd.com/news-events/press-releases/detail/1296/am... https://chatjimmy.ai/
AI 点评 · 芯片级模型固化,AMD硬刚英伟达推理赛道,收购背后是架构革命信号。
Test data from public benchmarks inevitably leaks into pretraining corpora, inflating evaluation scores once memorized. Contamination mitigation evaluation intervenes in the decoding process to suppre…
Deciding which of two agents is stronger means playing games until skill outweighs luck, and every game costs money, model inference, or expert time. Since the number of games needed is unknown, fixed…
This paper addresses the limitations of Explainable Artificial Intelligence (XAI) with respect to insufficient evaluation. They are illustrated through the DetoxAI image recognition system for bias de…
White matter hyperintensities (WMH), bright regions on Fluid-attenuated Inversion Recovery (FLAIR) scans are associated with cerebrovascular pathology and neurodegeneration. FLAIR is usually acquired…
The serial entrepreneur joins the e-commerce company as CPO to lead its AI agents.
AI 点评 · 创始团队回归掌舵AI产品,标志电商营销赛道竞争升级,战略价值显著。
We present MameLoshnLM, the first open-source 8B-parameter language model built specifically for Yiddish. Despite Yiddish's rich textual tradition, its limited digital presence and the scarcity of rel…
LLM-based agents are rapidly advancing, autonomously invoking external tools to complete multi-step tasks for users. However, agents often acquire more sensitive information than the task requires. Ex…
Deploying autonomous multimodal agents in continuous, real-world environments requires them to ingest unbounded audio-visual streams and maintain hour-scale memory. However, current evaluations predom…
AI 点评 · 华为基因主导智元,谷歌科学家退出,或重塑机器人行业人才格局。
Once, I had some questions about why SpaceX, Elon Musk's healthiest company, acquired xAI, his sickliest one. Now I have some questions about why we're calling the whole thing Spac…
OpenAI explains recent third-party cybersecurity evaluation incidents and outlines new safeguards to strengthen AI model testing and evaluation.
AI 点评 · 第三方评测暴露AI安全短板,新防护措施或成行业标准。
Benchmarks that measure the forecasting ability of large language models are almost always retrospective: the event has happened, the answer is somewhere on the Web, and the evaluation must defend its…
Large language models can solve substantially harder reasoning problems with more inference-time compute. The term "test-time scaling," however, now covers diverse inference algorithms that extend del…
Synthetic histopathology image generation has emerged as an approach that may address data scarcity in computational pathology, yet current evaluation methodologies may not fully assess synthetic data…
【导语】当前,电子级玻纤布价格较2025年低点翻倍、FR-4覆铜板涨幅超270%,AI封装载板部分交期拉长至6个月以上,有机基板供给危机持续加深。在此背景下, 国内玻璃基板领军企业巽霖科技宣布完成近2亿元B轮融资——这已是该公司半年内完成的第三轮次融资。本轮由英诺基金、千乘资本、海目星、光莆股份、同鑫资本等新股东投资,金雨茂物、海通开元、北岸产投等老股东持续…
作者 | 乔钰杰 编辑 | 袁斯来 硬氪获悉,精密减速器企业陶世智能科技有限公司(以下简称“陶世”)近日完成超亿元融资。本轮融资由国创集团,海川聚义,杭州众燊,新智资本参与,德太资本担任财务顾问。融资资金将主要用于产品研发、产线扩建以及机器人领域市场拓展。 陶世成立于2016年,总部位于深圳,主要研发和生产正交90度微型减速器及机器人关节模组。公司核心产品为…
从全球经验来看,很多科技领军企业的崛起,都少不了创业投资的支持。今年上半年,高技术产业投资同比增长4.6%,这一数据背后,是创业投资的活跃度在持续回升。业内人士普遍认为,AI技术的发展,是这一轮创投市场回暖的核心驱动力,资金正加快涌向AI、量子科技、算力等领域。数据显示,2026年上半年中国AI创业公司融资总额突破3000亿元,已超过2025年全年。而资金的…
AI 点评 · 创投风向标转向硬科技,3000亿真金白银验证AI赛道热度。
Skill-based prompting has become a practical mechanism for improving large language model (LLM) agents, yet existing skill acquisition methods often treat skills as experience summaries, memory entrie…
Human evaluation of AI systems and digital products is costly, slow, and difficult to scale. Offline evaluations are more scalable but often abstract away human diversity and interactive behavior. We…
Design Arena is used by 5.3 million people around the world, providing critical human evaluations to frontier labs.
AI 点评 · 人类反馈数据成AI军备竞赛新筹码,5百万用户规模验证了品味训练的商业价值。
Fairness evaluation concerns not only what a model produces, but also what its outputs ought to be compared against. When a model generates "a CEO in the United States," the prompt leaves demographic…
文 | 赵京娜 访谈 编辑 | 海若镜 36氪获悉,近日奇点逃逸完成千万级种子轮融资,由星连资本与水木创投联合领投,奇绩创坛跟投。其正在研发AI原生团队协作操作系统Nexus,让人、Agent、任务、知识和工具基于同一份组织状态持续协作,并让系统从每一次协作中有证据地变强。 奇点逃逸创始人兼CEO薛传奕,本科、博士阶段均在清华大学就读,研究方向覆盖强化学习与…
今日热点导览 马斯克关注了DeepSeek的X账号 祥鹏航空回应航班误发过期方便面 OpenAI或将IPO推迟到明年 SpaceX首份财报即将发布 小米多款手机正式涨价 每月10万美元,特朗普“真实社交”售卖“优先访问权” TOP3大新闻 蔡崇信宣布离婚,不涉及出售阿里股份 8月1日,阿里巴巴集团董事会主席、美国职业篮球队布鲁克林篮网主要所有者蔡崇信与妻子吴…
Enterprise question answering requires models to acquire proprietary knowledge without discarding general capabilities. We present Wnuan, a three-stage pipeline that constructs task-oriented supervisi…
Captions serve as a primary supervision signal for both multimodal understanding and text-to-image generation. However, previous evaluations treat the caption quality as a single scalar objective, whi…
8月2日消息,中信证券研报表示,A股本轮调整更多是拥挤交易的修正,而非韩国式的去杠杆冲击,这体现在:1)整体杠杆情况比较安全,7月上涨股票数量接近全A一半,明显超过6月;2)相比全球历史上典型的去杠杆行情,当前的融资回落幅度并不算大;3)ETF市场呈现持续的资金流入,科技类ETF的流入提供了充足流动性支持。当然,局部的流动性压力依然存在,尤其是部分非核心AI…
AI 点评 · 券商罕见喊话明确转多,杠杆数据支撑逻辑,给市场注入强心剂。
对前沿实验室估值悲观
Multimodal Large Language Models (MLLMs) have achieved strong performance on a wide range of vision-language tasks, but often fail under imperfect or shifted contexts. A reliable MLLM should refuse tr…
While recent image editing models have made rapid progress, multi-reference editing remains challenging, particularly in maintaining visual consistency across references and ensuring overall visual ha…
Large language model (LLM) agents can self-evolve by continually improving from their own accumulated experience. However, existing studies predominantly adopt independent evaluation. Consequently, th…
Investigating three real-world incidents in our cybersecurity evaluations anthropic.com
Investigating three real-world incidents in our cybersecurity evaluations Anthropic
Existing evaluations often reduce agent failures to system-level outcomes, obscuring where the fault originated and which intervention would improve the agent system. This creates a repair-assignment…
Computer-using agents (CUAs) are advancing rapidly across the digital world. A CUA trajectory records the agent's actions, states, and reasoning. Verifying whether it fulfilled the task instruction is…
Sequence models must decide what to write into memory and what to retain. In quantum and quantum-inspired sequence learning, nonlinear recurrent updates often require repeated circuit evaluations and…
A production-oriented LLM engineering platform with OpenAI-compatible serving, streaming, observability, evaluation, reproducible experiments, and deterministic…
Red-team evaluations of AI models support some claims and not others, and the boundary between the two is calculable rather than merely a matter of judgment. We define the evidential ceiling of an eva…
OpenAI and Hugging Face share early findings from a security incident during AI model evaluation, highlighting advanced cyber capabilities and lessons for defenders.
Generating professional scholarly content, such as peer reviews and rebuttals, requires an intricate synergy between domain reasoning and factual grounding. This work presents a comprehensive framewor…
Snapshot testing for LLM apps and agents, built to run locally and block regressions in CI.
While instruction-based video editing has advanced rapidly, real-world videos contain tightly coupled audio and visual signals, and editing one modality often requires coordinated changes in the other…
Large language models (LLMs) are increasingly used as synthetic survey respondents, but existing evaluations ask whether answers look plausible at the individual level. We argue the right question is…
Frontier large language models (LLMs) safety evaluation has largely treated harmful generation as an attack outcome rather than as an object of analysis. Consequently, little is known about the harmfu…
Anthropic raises $30 billion in Series G funding at $380 billion post-money valuation Anthropic


